Databricks-Certified-Professional-Data-Engineer Latest Exam Duration & Exam Databricks-Certified-Professional-Data-Engineer Answers
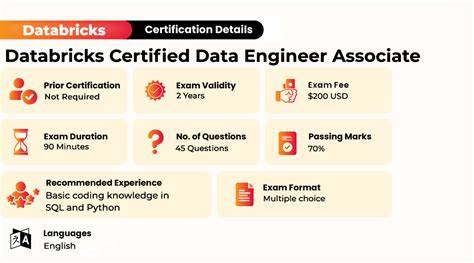
Actualtests4sure's study material is available in three different formats. The reason we have introduced three formats of the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice material is to meet the learning needs of every student. Some candidates prefer Databricks-Certified-Professional-Data-Engineer practice exams and some want real Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) questions due to a shortage of time. At Actualtests4sure, we meet the needs of both types of aspirants. We have Databricks-Certified-Professional-Data-Engineer PDF format, a web-based practice exam, and Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) desktop practice test software.
Databricks Certified Professional Data Engineer exam is a rigorous and comprehensive assessment of a candidate's skills in designing, building, and maintaining data pipelines on the Databricks platform. Databricks-Certified-Professional-Data-Engineer exam covers a wide range of topics, including data storage and retrieval, data processing, data transformation, and data visualization. Candidates are tested on their ability to design and implement scalable and reliable data architectures, as well as their proficiency in troubleshooting and optimizing data pipelines.
Databricks Certified Professional Data Engineer certification exam is a hands-on exam that requires candidates to demonstrate their skills in building data pipelines and workflows using Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of a set of performance-based tasks that require candidates to design, implement, and manage data solutions in a Databricks environment. Candidates are given a set of data engineering scenarios and must use Databricks to build solutions that meet the requirements of each scenario.
>> Databricks-Certified-Professional-Data-Engineer Latest Exam Duration <<
Free PDF 2026 Databricks Useful Databricks-Certified-Professional-Data-Engineer Latest Exam Duration
If you are looking to advance in the fast-paced and technological world, Databricks is here to help you achieve this aim. Databricks provides you with the excellent Databricks Certified Professional Data Engineer Exam practice exam, which will make your dream come true of passing the Databricks Databricks-Certified-Professional-Data-Engineer Certification Exam.
Databricks Certified Professional Data Engineer exam is a certification program offered by Databricks, a unified data analytics platform that provides a collaborative workspace for data science teams. Databricks Certified Professional Data Engineer Exam certification program is designed for data professionals who want to demonstrate their knowledge and skills in building reliable, scalable, and performant data pipelines using Databricks.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q46-Q51):
NEW QUESTION # 46
A data engineer has created a new cluster using shared access mode with default configurations. The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
- A. CAN ATTACH TO
- B. CAN RESTART
- C. CAN MANAGE
- D. CAN VIEW
Answer: D
Explanation:
Databricks provides different permission levels to control access to clusters. The correct minimal permission required for viewing driver logs is CAN VIEW.
Databricks Cluster Permission Levels:
* CAN ATTACH TO:
* Allows users to attach notebooks to a cluster but does not allow them to view logs.
* Not sufficient for viewing driver logs.
* CAN MANAGE:
* Grants full control over the cluster, including starting, stopping, and editing configurations.
* Too broad for this requirement.
* CAN VIEW (Correct Answer):
* Allows users to view cluster details, logs, and status but not modify any configurations.
* Minimal required permission for viewing logs.
* CAN RESTART:
* Grants permission to restart the cluster, but does not include log access.
* Not sufficient for viewing logs.
Conclusion:
The minimal permission needed to allow the development team to view driver logs is CAN VIEW.
References:
Databricks Cluster Permissions Documentation
NEW QUESTION # 47
The data engineering team maintains the following code:

Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- B. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 48
Which statement describes Delta Lake Auto Compaction?
- A. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 49
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
- A. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- B. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name DataEngineer_cluster
Answer: B
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
NEW QUESTION # 50
You are asked to create a model to predict the total number of monthly subscribers for a specific magazine.
You are provided with 1 year's worth of subscription and payment data, user demographic data, and 10 years
worth of content of the magazine (articles and pictures). Which algorithm is the most appropriate for building
a predictive model for subscribers?
- A. TF-IDF
- B. Decision trees
- C. Logistic regression
- D. Linear regression
Answer: D
NEW QUESTION # 51
......
Exam Databricks-Certified-Professional-Data-Engineer Answers: https://www.actualtests4sure.com/Databricks-Certified-Professional-Data-Engineer-test-questions.html
- Databricks-Certified-Professional-Data-Engineer Training Solutions 🏡 New Soft Databricks-Certified-Professional-Data-Engineer Simulations 🦏 Databricks-Certified-Professional-Data-Engineer Labs 😘 Search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ and obtain a free download on ➤ www.prepawayexam.com ⮘ 🍙New Soft Databricks-Certified-Professional-Data-Engineer Simulations
- Online Databricks-Certified-Professional-Data-Engineer Bootcamps 🥃 Databricks-Certified-Professional-Data-Engineer Top Questions 🍪 New Soft Databricks-Certified-Professional-Data-Engineer Simulations 😲 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download exam materials for free through 「 www.pdfvce.com 」 🦍Databricks-Certified-Professional-Data-Engineer Certification Exam Dumps
- Databricks Databricks-Certified-Professional-Data-Engineer Practice Test Software Gives an Exact Impression of the Real Exam 🦯 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and obtain a free download on ▛ www.examdiscuss.com ▟ 🏦New Soft Databricks-Certified-Professional-Data-Engineer Simulations
- HOT Databricks-Certified-Professional-Data-Engineer Latest Exam Duration - High-quality Databricks Databricks Certified Professional Data Engineer Exam - Exam Databricks-Certified-Professional-Data-Engineer Answers 👣 Easily obtain free download of ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ by searching on ⏩ www.pdfvce.com ⏪ 🕞Latest Test Databricks-Certified-Professional-Data-Engineer Discount
- 100% Pass 2026 Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam –The Best Latest Exam Duration ⌛ Open ⇛ www.prep4sures.top ⇚ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to download exam materials for free 👑Exam Databricks-Certified-Professional-Data-Engineer Discount
- Databricks-Certified-Professional-Data-Engineer Test Free ✨ Databricks-Certified-Professional-Data-Engineer Certification Exam Dumps 🚌 Databricks-Certified-Professional-Data-Engineer Valid Braindumps Ebook 🆒 Copy URL ▛ www.pdfvce.com ▟ open and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free ➿Latest Test Databricks-Certified-Professional-Data-Engineer Discount
- Pass Guaranteed Quiz 2026 Professional Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Latest Exam Duration 🥝 Enter [ www.validtorrent.com ] and search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ to download for free 🎎Databricks-Certified-Professional-Data-Engineer Valid Braindumps Ebook
- New Soft Databricks-Certified-Professional-Data-Engineer Simulations 🌞 Databricks-Certified-Professional-Data-Engineer Labs ⛰ Exam Databricks-Certified-Professional-Data-Engineer Discount 🆖 Search for ( Databricks-Certified-Professional-Data-Engineer ) and download it for free on ➤ www.pdfvce.com ⮘ website 🦗Databricks-Certified-Professional-Data-Engineer Labs
- Free PDF 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam –Efficient Latest Exam Duration 🖖 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and obtain a free download on ✔ www.prep4sures.top ️✔️ ☝Databricks-Certified-Professional-Data-Engineer Training Solutions
- Exam Databricks-Certified-Professional-Data-Engineer Testking 🍤 Databricks-Certified-Professional-Data-Engineer Top Questions 🛃 Databricks-Certified-Professional-Data-Engineer Labs 📧 Easily obtain free download of 「 Databricks-Certified-Professional-Data-Engineer 」 by searching on ➠ www.pdfvce.com 🠰 😭Exam Databricks-Certified-Professional-Data-Engineer Testking
- Databricks-Certified-Professional-Data-Engineer Training Solutions 🔁 Databricks-Certified-Professional-Data-Engineer Labs 🎽 Reliable Databricks-Certified-Professional-Data-Engineer Dumps Ppt 🛑 Open ⇛ www.vceengine.com ⇚ enter ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and obtain a free download 🥰Databricks-Certified-Professional-Data-Engineer Book Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, youemerge.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes