If you don't work hard to improve your strength, you can't get the chance you want. Without chance, you will not be able to obtain your desired status and salary. This society is such a reality. It is also fair. Every year, many people purchase our Certified-Data-Engineer-Professional study materials. With the help of our Certified-Data-Engineer-Professional Exam Braindumps, they successfully passed the exam and got the certification, and became more and more successful than before. So if you buy our Certified-Data-Engineer-Professional practice questions, you will have a brighter future!
| Section | Weight | Objectives |
|---|---|---|
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
>> New Databricks Certified-Data-Engineer-Professional Test Dumps <<
Our Certified-Data-Engineer-Professional question torrent not only have reasonable price but also can support practice perfectly, as well as in the update to facilitate instant upgrade for the users in the first place, compared with other education platform on the market, the Certified-Data-Engineer-Professional Exam Question can be said to have high quality performance. We can sure that you will never regret to download and learn our Certified-Data-Engineer-Professional study material, and you will pass the Certified-Data-Engineer-Professional exam at your first try.
NEW QUESTION # 117
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.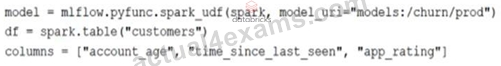
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
Answer: B
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 118
Which Python variable contains a list of directories to be searched when trying to locate required modules?
Answer: E
Explanation:
sys. path is a built-in variable within the sys module. It contains a list of directories that the interpreter will search in for the required module.
NEW QUESTION # 119
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
Answer: B
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
NEW QUESTION # 120
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: E
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 121
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: E
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 122
......
Candidates who crack the Certified-Data-Engineer-Professional examination of the Databricks Certified-Data-Engineer-Professional certification validate their worth in the sector of information technology. The Databricks Certified-Data-Engineer-Professional credential is evidence of their talent. Reputed firms hire these talented people for high-paying jobs. To get the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification, it is essential to clear the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) test. For this task, you need to update Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) preparation material to get success.
Reliable Certified-Data-Engineer-Professional Source: https://www.actual4exams.com/Certified-Data-Engineer-Professional-valid-dump.html