참고: ExamPassdump에서 Google Drive로 공유하는 무료, 최신 SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1DhyRFRhfgcR0NkGeYACbtMNkUw6xys50
IT인증시험문제는 수시로 변경됩니다. 이 점을 해결하기 위해ExamPassdump의Snowflake인증 SPS-C01덤프도 시험변경에 따라 업데이트하도록 최선을 다하고 있습니다.시험문제 변경에 초점을 맞추어 업데이트를 진행한후 업데이트된Snowflake인증 SPS-C01덤프를 1년간 무료로 업데이트서비스를 드립니다.
| Section | Objectives |
|---|---|
| Topic 1: Data Engineering with Snowpark | - Pipeline development
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 4: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 5: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 6: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
ExamPassdump의 Snowflake인증 SPS-C01덤프는 최근 유행인 PDF버전과 소프트웨어버전 두가지 버전으로 제공됩니다.PDF버전을 먼저 공부하고 소프트웨어번으로 PDF버전의 내용을 얼마나 기억하였는지 테스트할수 있습니다. 두 버전을 모두 구입하시면 시험에서 고득점으로 패스가능합니다.
질문 # 237
You are working with a Snowpark DataFrame that contains product information including 'product_name' and 'description'. You need to create a new column named 'search_terms' that contains the first three words from the 'description' column, converted to lowercase. If the description has fewer than three words, the 'search_terms' column should contain all the words available. The words should be separated by a space. What is the MOST efficient way to achieve this using Snowpark?





정답:B
설명:
Using a UDF (Option C) is a valid approach, but generally less efficient than leveraging built-in functions or existing Snowflake functions, especially for large datasets, because it involves serialization and deserialization between Python and Snowflake. Option A is not dynamic and will error on strings with fewer than three words. Option D will only correctly return the words if there are exactly three, otherwise it won 't match. E will just return the lowercased string and Snowflake UDF defined in SQL. Snowflake UDFs overhead, and are preferable for performance It is also less efficient than a UDF/Stored proc as it involves calling the Regex. Option is incorrect. Option B (UDF) is the most efficient, assuming GET FIRST THREE_WORDS is a are optimized for execution within the Snowflake environment, minimizing data transfer compared to Python UDFs in Snowpark.
질문 # 238
Consider the following Snowpark Python code snippet:
정답:D
설명:
Snowpark's lazy evaluation allows the query optimizer to combine multiple filter operations into a single scan, improving efficiency. The code will execute successfully because Snowpark does not require explicit materialization of intermediate DataFrames. Null values are allowed in Snowpark DataFrames.
질문 # 239
You have a Snowpark DataFrame named 'employee_df with columns 'employee_id', 'department', and 'salary'. You want to calculate the average salary for each department and add it as a new column named 'avg_department_salary' to the original DataFrame. Additionally, you want to sort the resulting DataFrame by department and then by salary in descending order. Which of the following Snowpark code snippets correctly implements this requirement?





정답:D,E
설명:
Option D and E are correct. Both implement the window function correctly to add the average salary per department as a new column and then sort the DataFrame as required. Option E is very close and just has the window partition defined with 'col('department')'. Option A is correct but uses sort. Option B is incorrect because it does not include the original columns other than department when grouping so will loose important data, and attempts to sort on a column that no longer exists.Option C uses 'avg('salary')' instead of avg(col('salary'))
질문 # 240
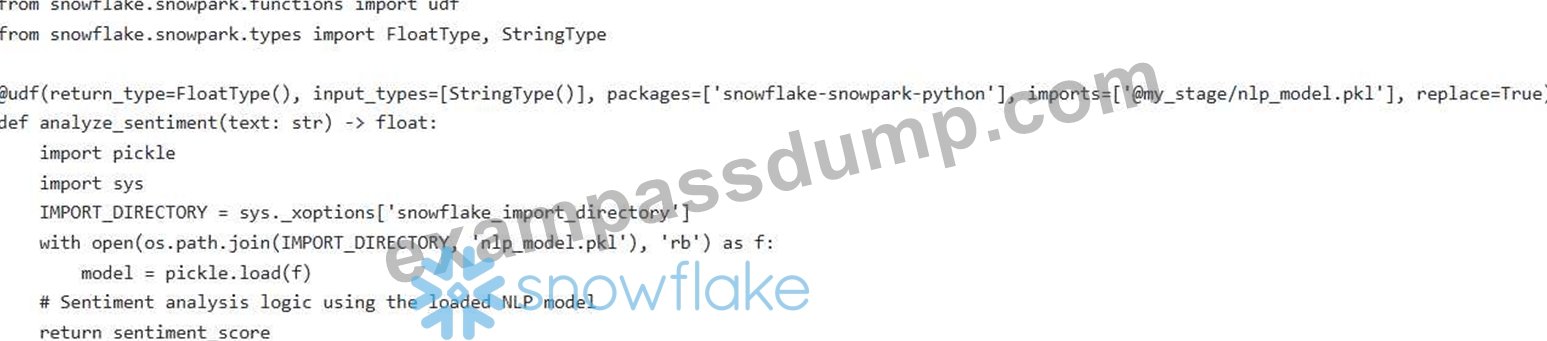
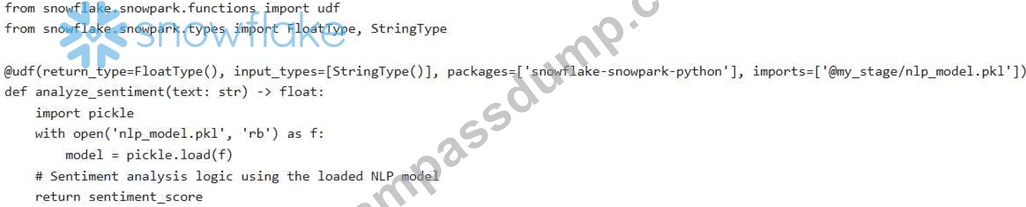
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?


정답:A
설명:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
질문 # 241
You are developing a Snowpark application that involves creating a set of stored procedures and UDFs to process data'. To ensure proper version control and dependency management, you decide to package your Python code into a single Python Wheel file and deploy it to Snowflake. Which of the following methods are valid for deploying and utilizing this Python Wheel file within Snowflake, considering best practices for maintainability and security? (Select TWO)
정답:B,D
설명:
Options D and E are the correct answers. Creating a Conda environment file and deploying it to Snowflake (Option D) allows for explicit version control and dependency management, ensuring consistent execution across environments. You need to upload the environment.yml which contains the packages and custom wheel you need to add. Using 'snowflake-cli' to push wheel as a package (Option E) is the approach for using custom packages. These are the recommended approaches. Uploading wheel files to internal or external stages and referencing them using the 'USING' clause (Options A and B) might work, but it lacks the structured dependency management provided by Conda environments. Snowsight cannot be used to directly upload wheels for environment setup (Option C).
질문 # 242
......
ExamPassdump의 Snowflake SPS-C01덤프는 Snowflake SPS-C01시험문제변경에 따라 주기적으로 업데이트를 진행하여 덤프가 항상 가장 최신버전이도록 업데이트를 진행하고 있습니다.구매한 Snowflake SPS-C01덤프가 업데이트되면 저희측에서 자동으로 구매시 사용한 메일주소에 업데이트된 최신버전을 발송해드리는데 해당 덤프의 구매시간이 1년미만인 분들은 업데이트서비스를 받을수 있습니다.
SPS-C01인기덤프자료: https://www.exampassdump.com/SPS-C01_valid-braindumps.html
그 외, ExamPassdump SPS-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1DhyRFRhfgcR0NkGeYACbtMNkUw6xys50