In contemporary society, information is very important to the development of the individual and of society (AI-500 practice test), and information technology gives considerable power to those able to access and use it. Therefore, we should dare to explore, and be happy to accept new things. In terms of preparing for exams, we really should not be restricted to paper material, there are so many advantages of our electronic AI-500 Study Guide, such as High pass rate, Fast delivery and free renewal for a year to name but a few. I can assure you that you will pass the exam as well as getting the related certification as easy as rolling off a log.
| Section | Weight | Objectives |
|---|---|---|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
Take a look at our Free Microsoft AI-500 Exam Questions and Answers to check how perfect they are for your exam preparation. Once you buy it, you will be able to get free updates for Microsoft AI-500l exam questions for up to 12 months. We also ensure that our support team and the core team of AI-500 provide services to resolve all your issues. There is a high probability that you will be successful in the Microsoft AI-500 exam on the first attempt after buying our prep material.
NEW QUESTION # 22
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.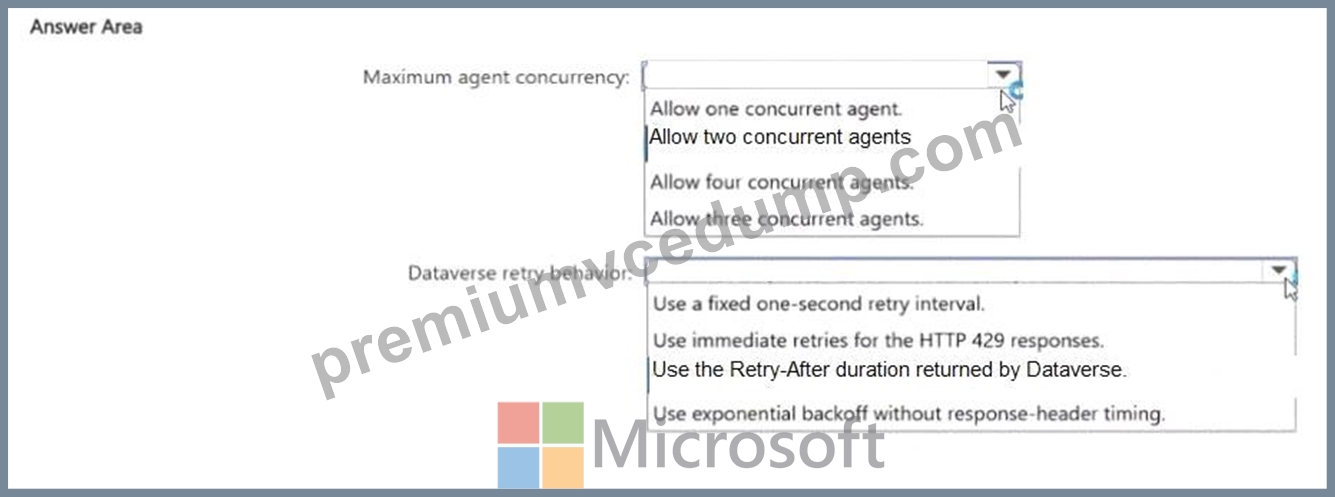
Answer:
Explanation: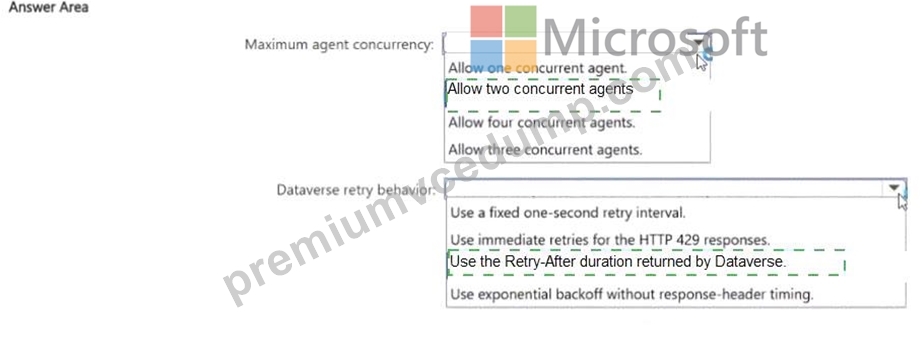
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits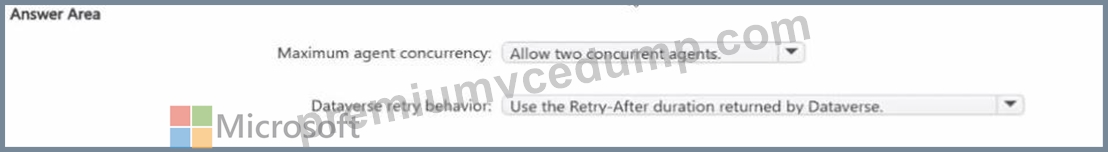
NEW QUESTION # 23
You have a Microsoft Foundry multi-agent solution. The solution includes a parent agent that can call an Azure logic app and delegate to two subagents.
You need to implement a review process for flagged interactions. The solution must meet the following requirements;
* Identify requests that call third-party services.
* Moderate the prompts, steps, and tool calls.
* Include a governance review.
What should you do?
Answer: C
Explanation:
The review process must cover the full sensitive interaction, including third-party calls, prompts, intermediate steps, and tool actions, and it must feed a governance review process. A centralized sensitive-use intake combined with guardrails and tracing provides the required evidence, while human reviewers must be able to approve, edit, or reject flagged interactions rather than reviewing only the final message. Content Safety alone does not provide full process governance over tool use. Routing only subagent findings or requiring approval only for the final response misses earlier third-party actions. CI/CD evaluation is important for release quality but does not control individual flagged production interactions. The source duplicated the label C for the final option; that final option should be labeled D. With that label correction, D is the best answer. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - governance, guardrails, tracing, and HITL
NEW QUESTION # 24
You have a Microsoft Foundry agent that handles customer support chats. The agent has two tools named get_contract_terms and calculate_refund.
On turns where refunds must be calculated, the agent inconsistently calls the tools.
You need to reliably force refund-estimate turns to call calculate_refund.
Which request configuration should you use?
Answer: B
Explanation:
The requirement is to force one specific tool, `calculate_refund`, whenever the application determines that a refund estimate is required. A named function in `tool_choice` removes ambiguity by directing the model to invoke that exact function. `tool_choice: " auto " ` allows the model to decide whether to call a tool and which tool to use. `tool_choice: " required " ` forces some tool call but does not guarantee that `calculate_refund` is selected when multiple tools are available. A natural-language instruction remains probabilistic and is not equivalent to an API-level enforcement setting. Microsoft ' s function-calling API documents named tool choice as the deterministic way to force a specific function. Therefore A is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure OpenAI - Function calling and tool choice
NEW QUESTION # 25
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.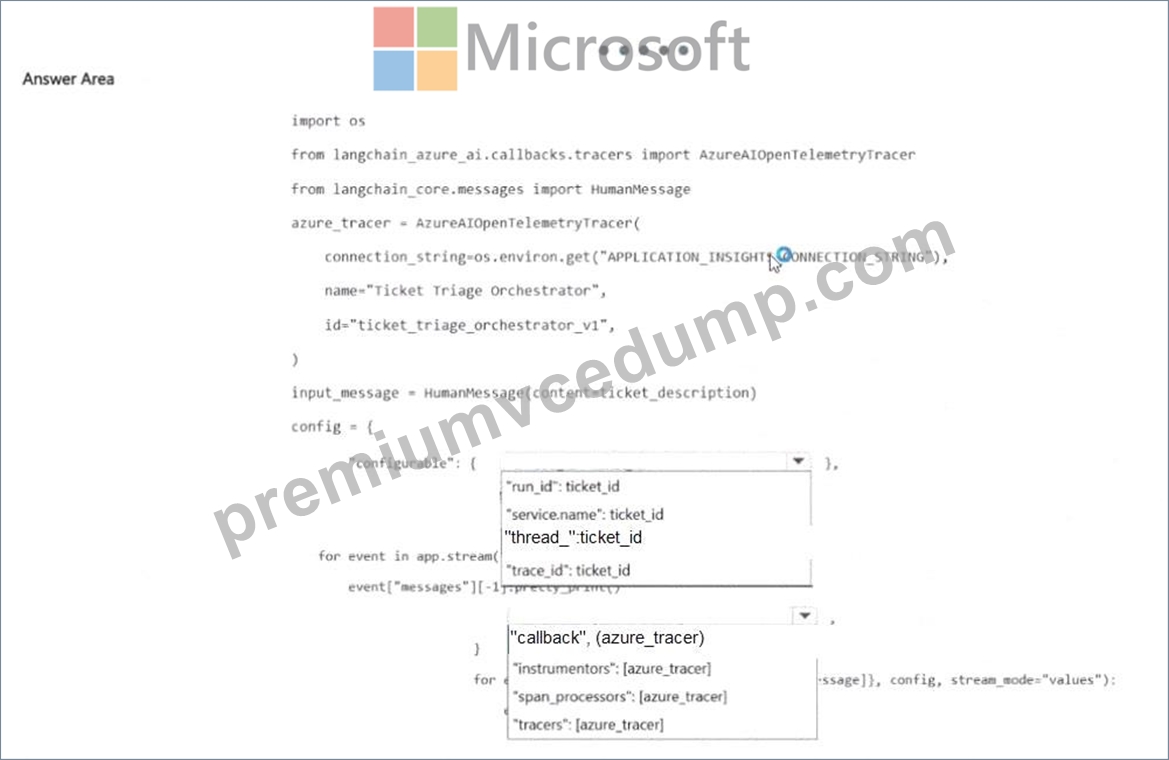
Answer:
Explanation: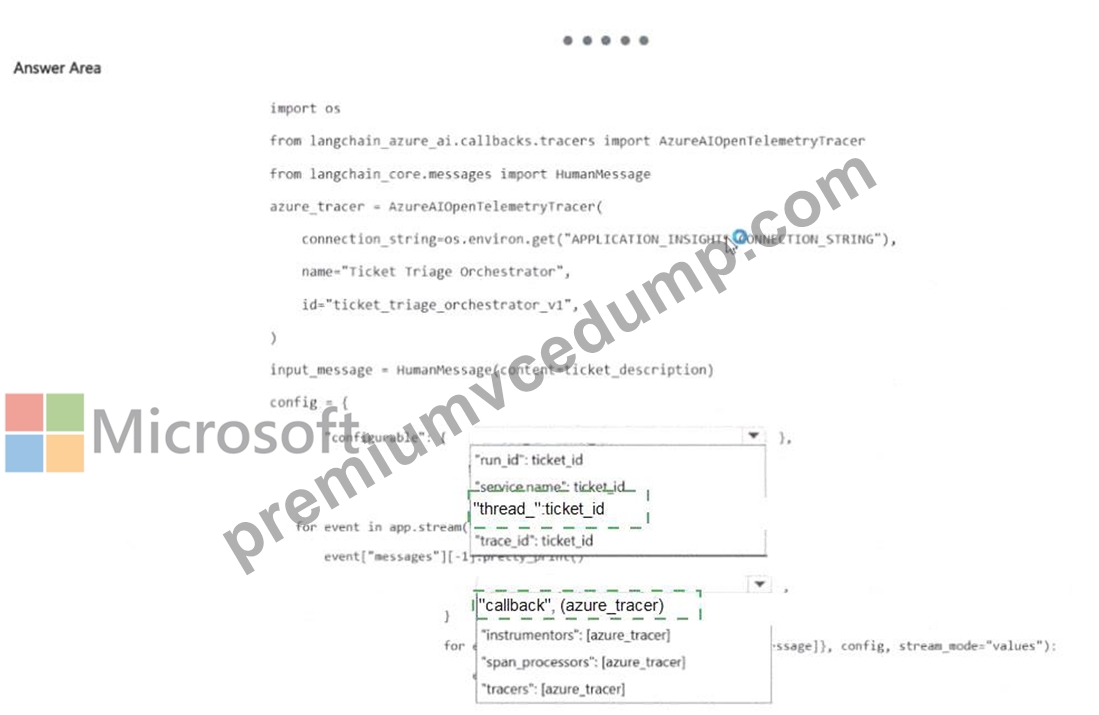
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents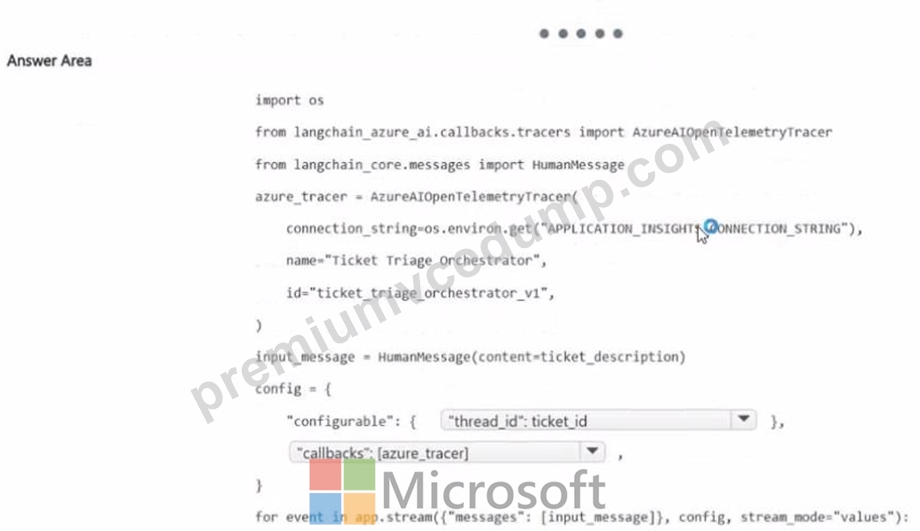
NEW QUESTION # 26
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.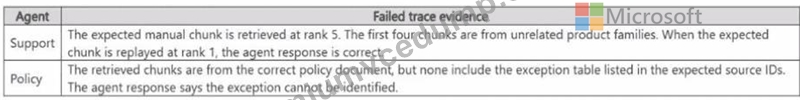
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.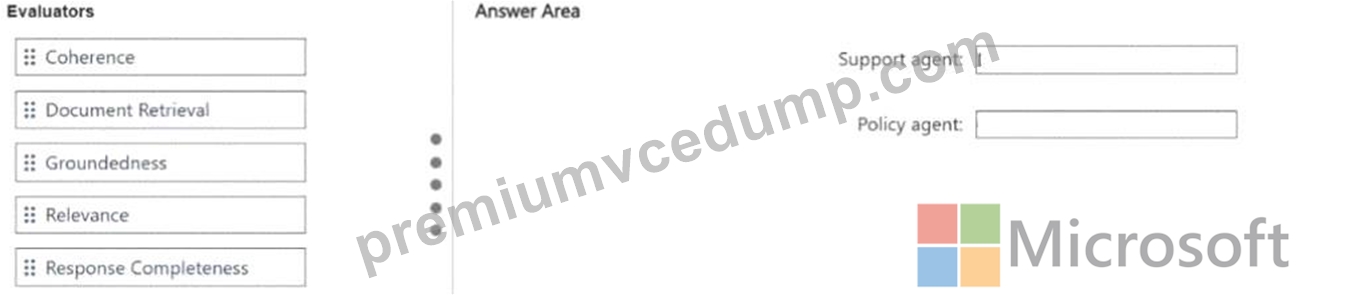
Answer:
Explanation: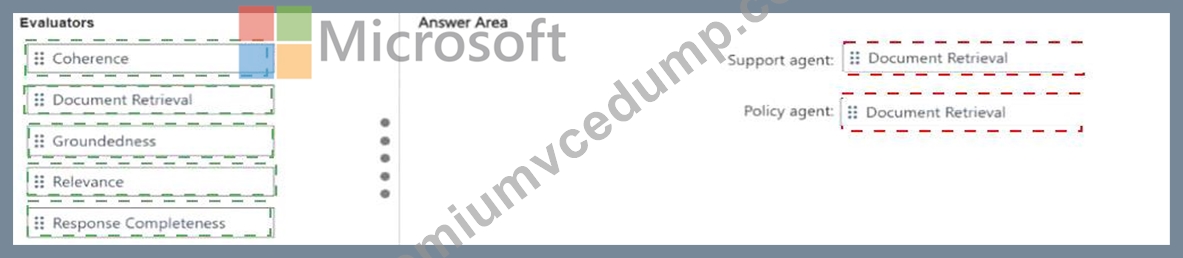
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 27
......
Probably you’ve never imagined that preparing for your upcoming AI-500 Exam could be easy. The good news is that our AI-500 exam braindumps can help you pass the exam and achieve the certification withe the least time and efforts. The excellent AI-500 learning questions are the product created by those professionals who have extensive experience of designing exam study material. Just remind you that we have engaged in the career for over ten years and we have became the leader in this field.
Practical AI-500 Information: https://www.premiumvcedump.com/Microsoft/valid-AI-500-premium-vce-exam-dumps.html