요즘 같은 인재가 많아지는 사회에도 많은 업계에서는 아직도 관련인재가 부족하다고 합니다.it업계에서도 이러한 상황입니다.Microsoft DP-800시험은 it인증을 받을 수 있는 좋은 시험입니다. 그리고ITDumpsKR는Microsoft DP-800덤프를 제공하는 사이트입니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement AI capabilities in database solutions | 25-30% | - Integrate AI models and services
|
| Topic 2: Design and develop database solutions | 35-40% | - Develop database solutions
|
| Topic 3: Secure, optimize, and deploy database solutions | 35-40% | - Secure database solutions
|
Microsoft업계에 종사하시는 분들은 DP-800인증시험을 통한 자격증취득의 중요성을 알고 계실것입니다. ITDumpsKR에서 제공해드리는 인증시험대비 고품질 덤프자료는 제일 착한 가격으로 여러분께 다가갑니다. ITDumpsKR덤프는 DP-800인증시험에 대비하여 제작된것으로서 높은 적중율을 자랑하고 있습니다.덤프를 구입하시면 일년무료 업데이트서비스, 시험불합격시 덤프비용환불 등 퍼펙트한 서비스도 받을수 있습니다.
질문 # 71
Drag and Drop Question
You have an Azure SQL database that stores sales data and contains tables named Sales and Products. Sales contains three columns named SalesDate, ProductKey, and TotalSale, Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales, filter on SalesDate or ProductKey, and use SUM() to aggregate TotalSale.
Products is relatively small and is used primarily for point lookups and joins to Sales.
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.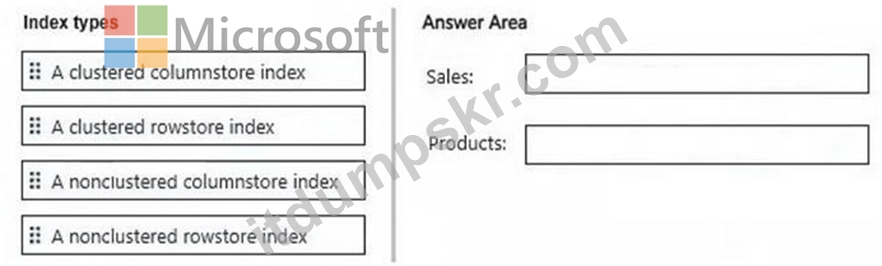
정답:
설명: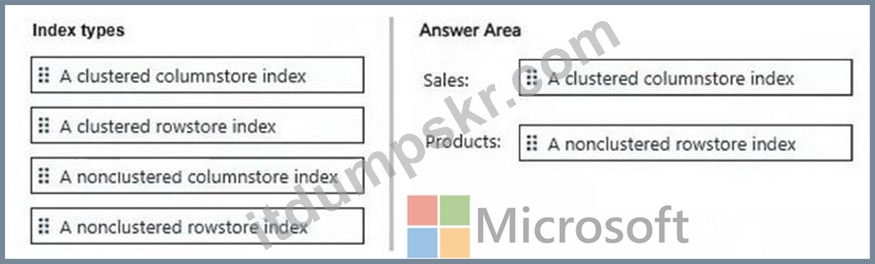
질문 # 72
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.GetCustomerOrders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
정답:A
설명:
We have encountered plan regression. This often happens after maintenance (like updating statistics) because the query optimizer generates a new execution plan that it thinks is better based on the new data distribution, but it ends up being less efficient in practice.
Since you've already identified the Plan ID for the faster plan and the Query ID from Query Store, you can force the "good" plan immediately using:
EXEC sp_query_store_force_plan @query_id = [YourQueryID], @plan_id = [YourFastPlanID]; Use code with caution.
This tells Azure SQL to ignore the new, slower plan and stick to the one that worked, providing an almost instant fix for your API's performance without requiring a code deployment.
Reference:
https://daxsws.com/blog/real-world-dynamics-365-performance-tuning-scenarios-and-fixes
질문 # 73
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
정답:D
설명:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
질문 # 74
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
정답:A
설명:
Microsoft documents that DriftReport creates an XML report showing changes that have been made to the registered database since it was last registered . That is the action intended to detect whether the production schema has diverged from the expected model baseline in your deployment workflow.
This is different from DeployReport , which shows the changes that would be made by a publish action . In other words:
* DriftReport answers: Has the deployed database drifted from the registered state/model?
* DeployReport answers: What changes would be applied if I published now?
The other options are not the right fit:
* Extract creates a DACPAC from an existing database, not a drift analysis report.
* Script generates a deployment script, not a schema-drift report.
So to generate a report that shows whether production has diverged from the model in source control , add:
SqlPackage.exe /Action:DriftReport
질문 # 75
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1 DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1 .
A company policy prohibits sharing customer Personally Identifiable Information (Pll), secrets, and query result sets with any Al service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to sales .Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
정답:B
설명:
The correct answer is D because the policy explicitly prohibits sharing customer PII, secrets, and query result sets with any AI service. The safe way to use GitHub Copilot Chat here is to provide only schema- level information such as table names, column names, relationships, and the required procedure behavior, without sharing actual table contents or result sets. That lets Copilot help generate and review the Transact- SQL while avoiding disclosure of customer data. This is consistent with Microsoft and GitHub guidance that content provided in prompts is what the AI can use, so avoiding real data in the prompt is the appropriate control.
The other options violate the requirement:
* A pastes real rows containing email addresses, which is direct PII disclosure.
* B shares actual query result sets, which the policy forbids.
* C provides the connection string so Copilot can validate against the database, which is inappropriate because it exposes connection details and could enable access beyond schema-only assistance.
So the correct approach is to ask Copilot to generate the stored procedure using only the schema and requirements, not real customer data.
질문 # 76
......
Microsoft인증 DP-800시험을 등록했는데 마땅한 공부자료가 없어 고민중이시라면ITDumpsKR의Microsoft인증 DP-800덤프를 추천해드립니다. ITDumpsKR의Microsoft인증 DP-800덤프는 거의 모든 시험문제를 커버하고 있어 시험패스율이 100%입니다. ITDumpsKR제품을 선택하시면 어려운 시험공부도 한결 가벼워집니다.
DP-800시험패스 인증덤프공부: https://www.itdumpskr.com/DP-800-exam.html