According to the statistic about candidates, we find that some of them take part in the Microsoft exam for the first time. Considering the inexperience of most candidates, we provide some free trail for our customers to have a basic knowledge of the AI-200 exam guide and get the hang of how to achieve the AI-200 Exam Certification in their first attempt. You can download a small part of PDF demo, which is in a form of questions and answers relevant to your coming AI-200 exam; and then you may have a decision about whether you are content with it. Our AI-200 exam questions are worthy to buy.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
A certificate means a lot for people who want to enter a better company and have a satisfactory salary. AI-200 exam dumps of us will help you to get a certificate as well as improve your ability in the processing of learning. AI-200 study materials of us are high-quality and accurate. We also pass guarantee and money back guarantee if you fail to pass the exam. We offer you free demo to have a try. If you have any questions about the AI-200 Exam Dumps, just contact us.
NEW QUESTION # 143
You are implementing a Retrieval-Augmented Generation (RAG) system by using the native vector search capabilities of Azure Cosmos DB for NoSQL API.
You have a container named Documents that stores technical articles. Each article includes a property named embedding.
You must ensure that the system can perform efficient similarity searches between user queries and the stored articles.
You need to configure the database resources to support semantic retrieval.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.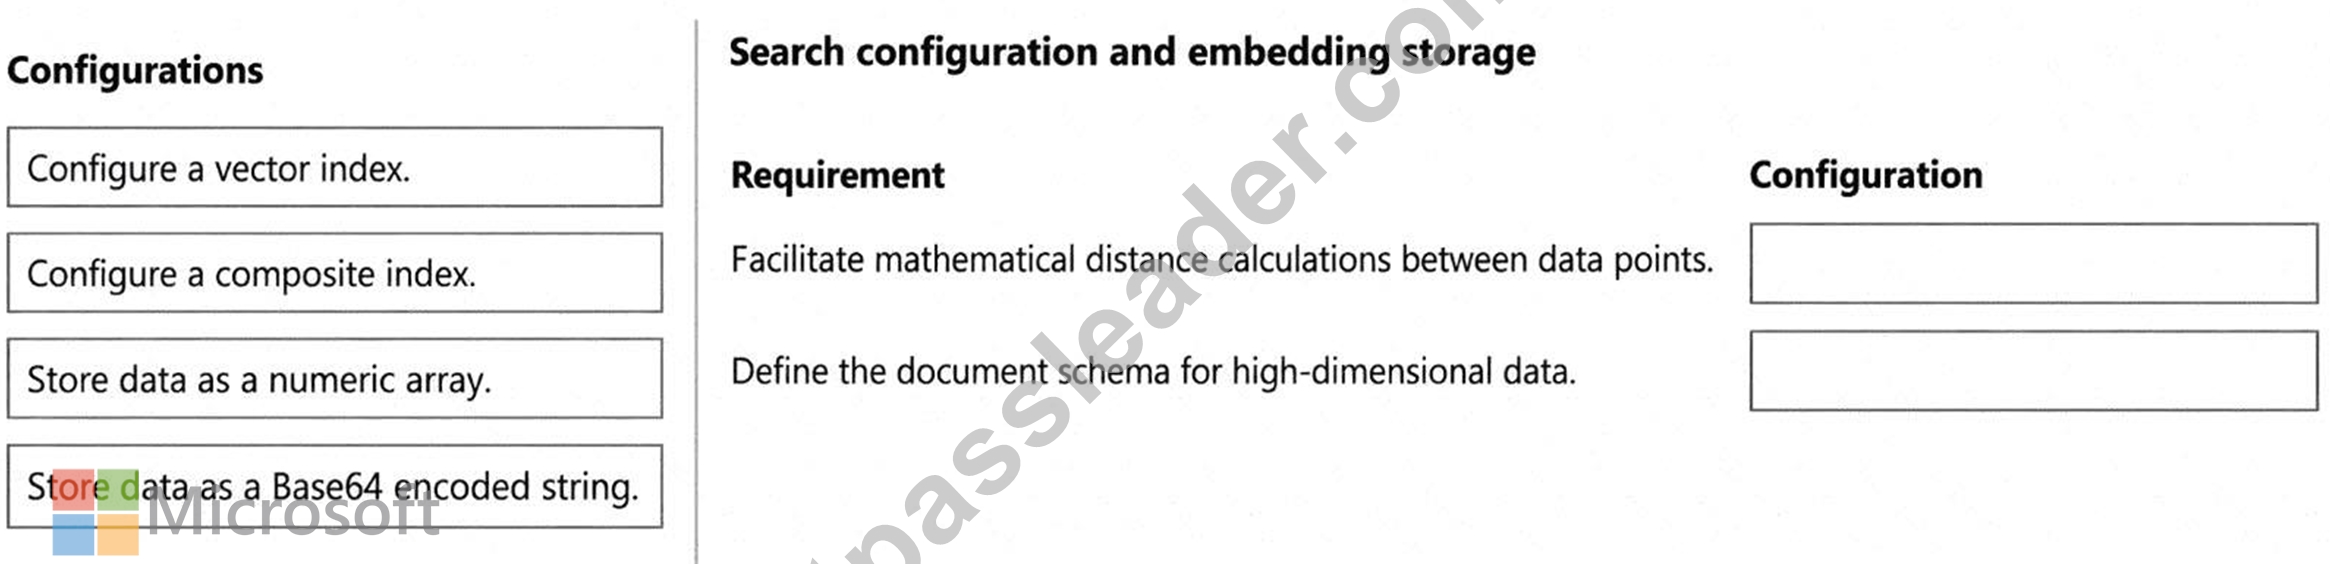
Answer:
Explanation: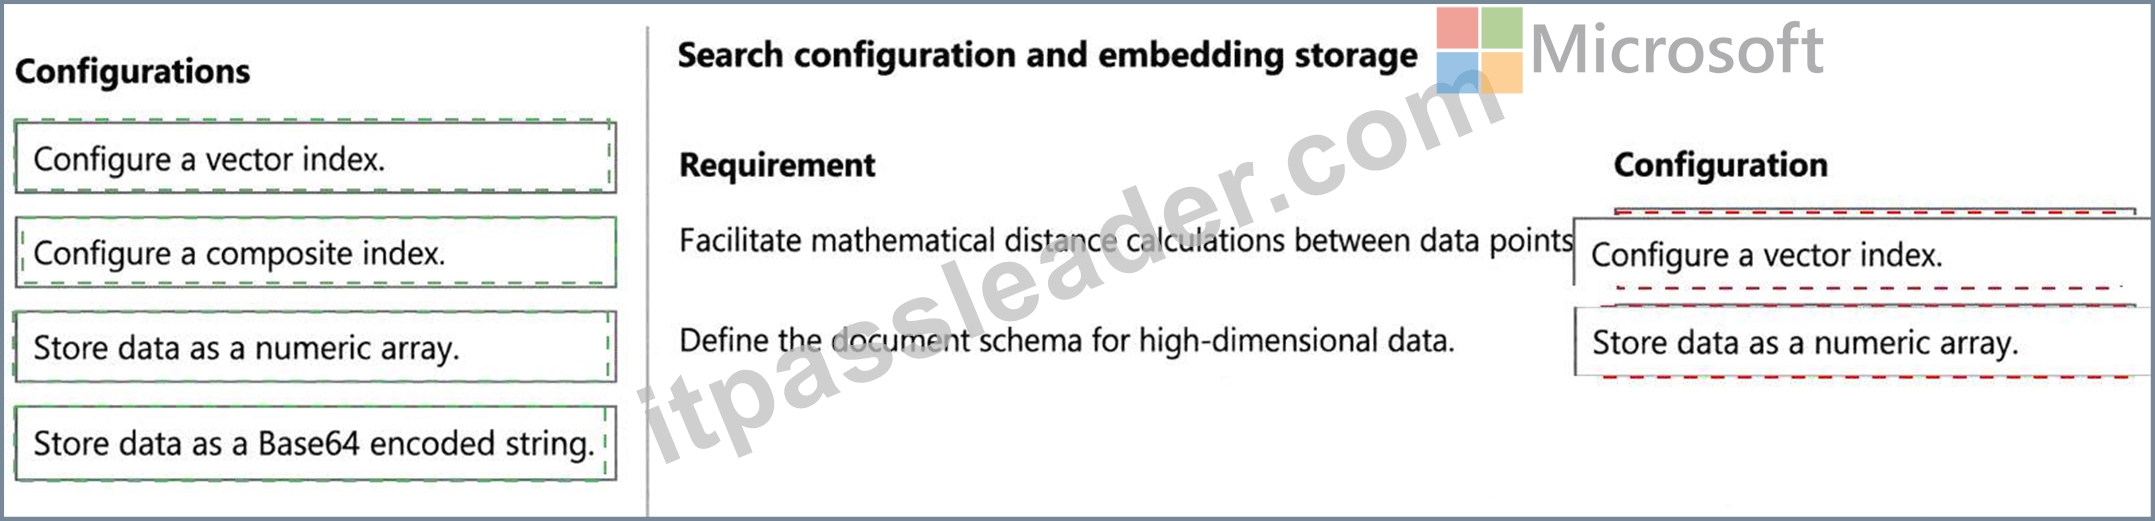
Explanation:
* Facilitate mathematical distance calculations between data points: Configure a vector index.
* Define the document schema for high-dimensional data: Store data as a numeric array.
Azure Cosmos DB for NoSQL supports native vector search by storing embeddings directly in JSON documents and defining a vector embedding policy plus a vector index on the embedding path. Microsoft documents that vector search compares a query vector with stored vectors by calculating similarity or distance through the VectorDistance() system function. A vector index materially improves this process by reducing search latency, increasing throughput, and lowering RU consumption compared with an unindexed vector scan.
The embedding property itself must be stored as an array of numeric values . Microsoft examples show embedding properties such as " contentVector " : [2, -1, 4, ...] and define the associated vector policy with attributes including path, data type, dimensions, and distance function. This representation is required because embeddings are high-dimensional numerical vectors generated by an embedding model.
A composite index optimizes queries involving multiple scalar properties but does not provide vector- distance indexing. A Base64-encoded string cannot be used directly for native vector similarity calculations because Cosmos DB expects the vector field to contain numeric values matching the configured dimensionality.
Study Guide references: Azure Cosmos DB for NoSQL # vector embedding policies; vector indexes; VectorDistance(); numeric embedding arrays; native vector search.
NEW QUESTION # 144
Drag and Drop Question
You are deploying an Azure Function app that retrieves secrets from Key Vault by using a managed identity.
The deployment must ensure that identity and secret configuration are in place before the function code is deployed.
You need to deploy the function app securely.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.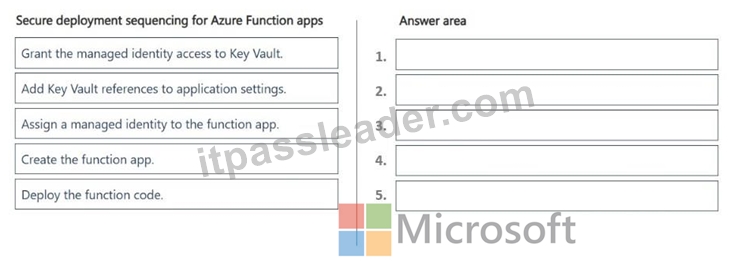
Answer:
Explanation: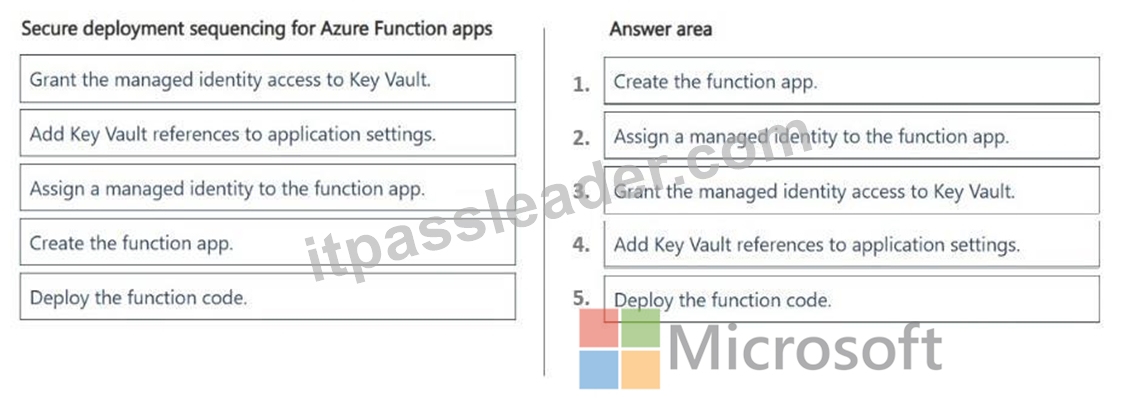
Explanation:
Step 1: Create the function app
You must first provision the underlying Azure Functions infrastructure before you can bind an identity or configuration settings to it.
Step 2: Assign a managed identity to the function app
Turning on the managed identity (such as a system-assigned identity) creates a distinct security principal in Microsoft Entra ID for the resource.
Step 3: Grant access to Key Vault
Use the managed identity's principal ID to create an access policy or RBAC role assignment in Key Vault, allowing the app to read secrets.
Step 4: Add Key Vault references to application settings.
Configure the Function App's application settings to point to the Key Vault secret URIs (@Microsoft.KeyVault(...)), which can now be securely resolved by the identity.
Step 5: Deploy the function code
Finally, deploy the application code. This ensures that when the code initializes and executes, all environment variables and secrets are already active and accessible, preventing application startup failures.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 145
Drag and Drop Question
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data.
The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account.
The application must perform the following tasks:
- Initialize the connection by using the account endpoint and key.
- Define shared throughput.
- Perform create, read, update, and delete (CRUD) operations on items
stored in a container.
You need to implement the SDK components required for the application to access and manage data in Azure Cosmos DB for NoSQL.
Which SDK components should you use? To answer, move the appropriate components to the correct requirements. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.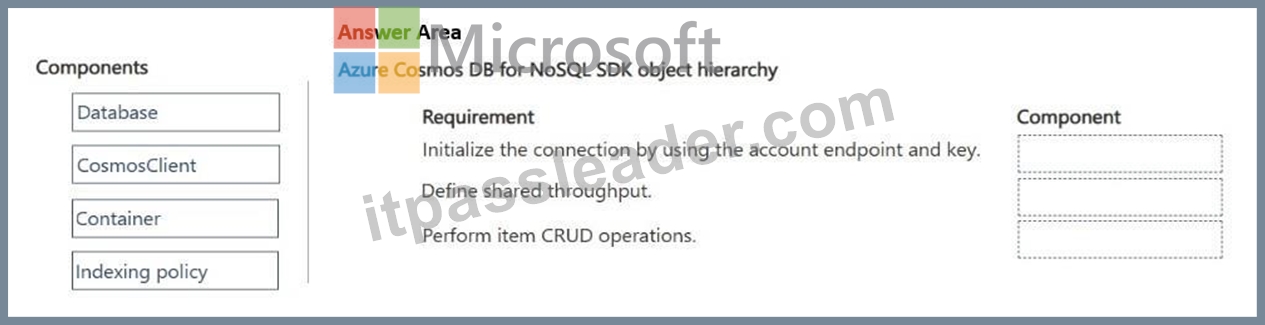
Answer:
Explanation: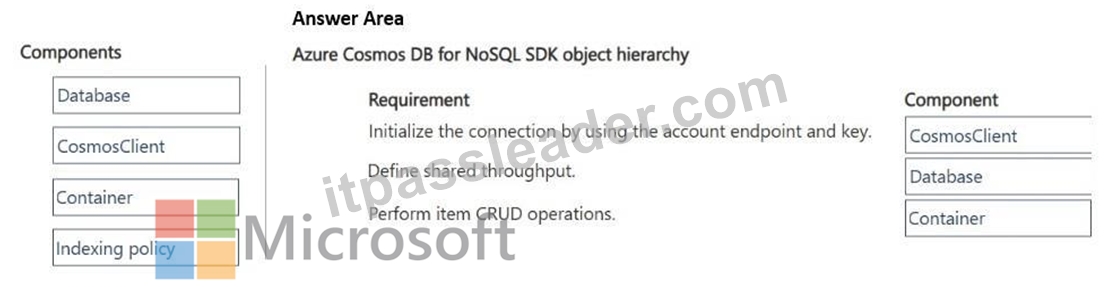
Explanation:
Box 1: CosmosClient
To initialize the connection to an Azure Cosmos DB for NoSQL account using the account endpoint and key, you must use the CosmosClient class.
Box 2: Database
The database SDK component should be used to define shared throughput.
In Azure Cosmos DB, shared throughput (provisioned Request Units per second or RU/s) is configured at the database level. When throughput is provisioned on a database, that capacity is shared among all the containers created within that specific database.
Box 3: Container
To perform item create, read, update, and delete (CRUD) operations, you should use the Container SDK component In the Azure Cosmos DB for NoSQL SDK for .NET, individual JSON documents (items) live inside a container. The Container class exposes the specific methods required to execute CRUD operations on these items.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/how-to-dotnet-get-started
NEW QUESTION # 146
You plan to develop an Azure Functions app with an HTTP trigger.
The app must support the following functionality:
Event-driven scaling -
Ability to use custom Linux images for function execution
You need to identify the app ' s hosting plan and the maximum amount of time that the app function can take to respond to incoming requests.
Which configuration setting values should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.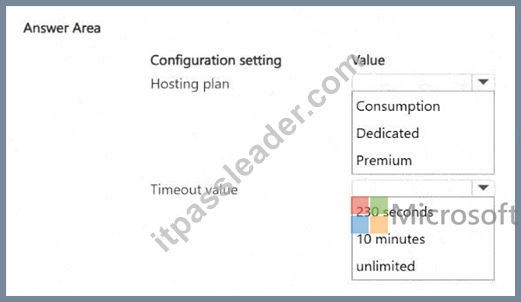
Answer:
Explanation: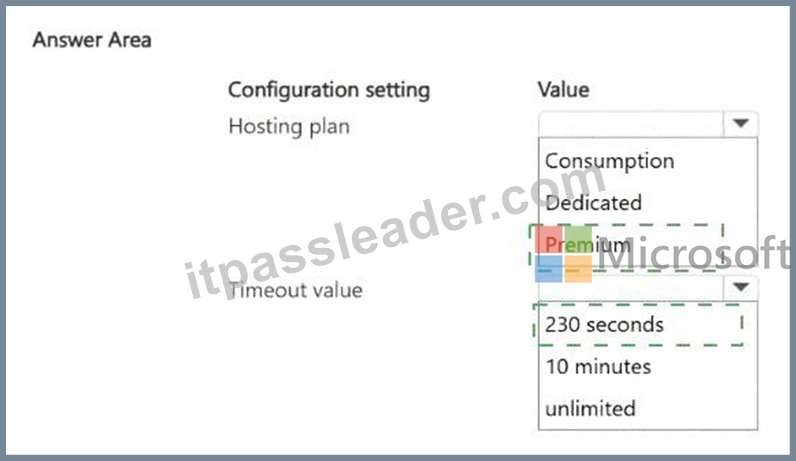
Explanation:
* Hosting plan: Premium
* Timeout value: 230 seconds
The correct hosting option is the Azure Functions Premium plan . Microsoft documents that the Premium plan supports event-driven scaling , where Azure Functions dynamically adds or removes host instances based on incoming trigger activity. It also supports Linux container deployments , which is required when the function app must execute from a custom Linux container image. A Dedicated App Service plan can host Linux containers, but it does not provide native Functions event-driven scaling. The legacy Consumption plan supports event-driven scaling but does not satisfy the custom Linux container requirement in this question.
For an HTTP-triggered function , the maximum time available to return an HTTP response is 230 seconds .
This limit applies even though a Premium-plan function can have a much longer or effectively unbounded execution timeout. Microsoft explains that the 230-second response limit results from the Azure Load Balancer ' s default idle timeout. If processing continues beyond this point, the function can continue executing, but the client will receive a timeout and the function cannot return its eventual response over that original HTTP connection.
Therefore, Premium + 230 seconds is the required combination.
Study Guide references: Azure Functions hosting options; Premium plan; Linux container support; event- driven scaling; HTTP-trigger timeout behavior.
NEW QUESTION # 147
You are developing a Retrieval-Augmented Generation (RAG) solution for a company. AI responses and embedding vectors are cached in Redis. The solution must meet the following requirements.
* AI responses must expire exactly 24 hours after they are cached
* Cached embeddings must always reflect the current source data.
You need to configure Redis to meet the requirements.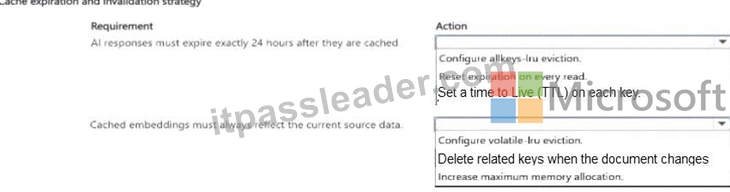
Answer:
Explanation: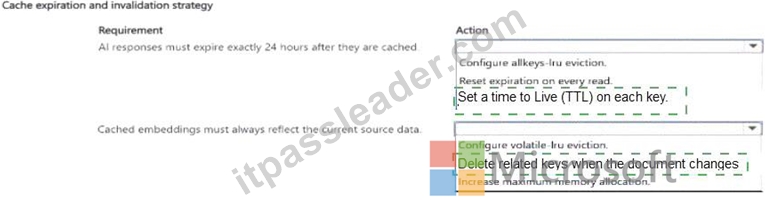
Explanation: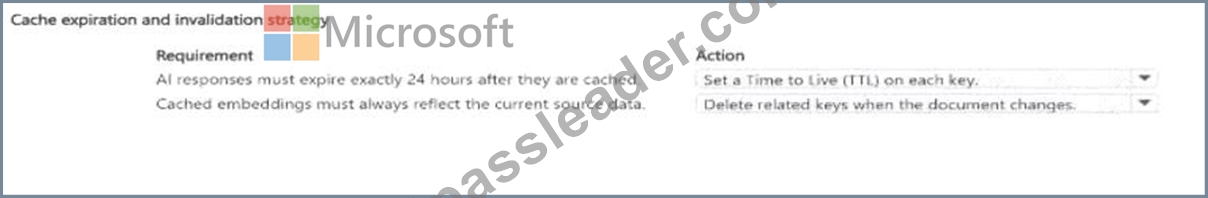
I response expiry: set a 24-hour TTL on each key. Embedding freshness: delete related cache keys when the source document changes.
Detailed Explanation: A fixed TTL encodes the requirement that an AI response must expire after a defined period rather than survive indefinitely or have its lifetime extended on every read. Embedding freshness is a separate consistency requirement: when the authoritative document changes, any cached representation derived from the old document must be invalidated immediately. Memory eviction policies are capacity- management mechanisms and cannot guarantee a precise 24-hour lifetime or source-data consistency.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Managed Redis documentation
NEW QUESTION # 148
......
ITPassLeader provide all candidates with AI-200 test torrent that is compiled by experts who have good knowledge of AI-200 exam, and they are very professional in compile AI-200 study materials. Not only that, our team checks the update every day, in order to keep the latest information of AI-200 our test torrent. Once we have latest version, we will send it to your mailbox as soon as possible. It must be best platform to provide you with best AI-200 study material for your exam.
New AI-200 Test Experience: https://www.itpassleader.com/Microsoft/AI-200-dumps-pass-exam.html