
What's more, part of that TestKingFree MLA-C01 dumps now are free: https://drive.google.com/open?id=1Ug8f4NNK-dM_g_V9wlMD6zZeTMyB5rYR
Our excellent Amazon MLA-C01 practice materials beckon exam candidates around the world with their attractive characters. Our experts made significant contribution to their excellence. So we can say bluntly that our MLA-C01 Actual Exam is the best. Our effort in building the content of our MLA-C01 study dumps lead to the development of MLA-C01 learning guide and strengthen their perfection.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deployment and Orchestration of ML Workflows | 22% | - Configure deployment for scalability and availability
|
| Topic 2: Data Preparation for Machine Learning | 28% | - Ingest and store data
|
| Topic 3: ML Solution Monitoring, Maintenance, and Security | 24% | - Optimize and maintain workloads
|
| Topic 4: ML Model Development | 26% | - Train, tune, and refine models
|
Do you want to have a new change about your life? Do you want to get more respects from other people? Do you long to become a powerful people? If your answer is yes, it is high time for you to use the MLA-C01 question torrent from our company. As the saying goes, opportunities for those who are prepared. If you have made up your mind to get respect and power, the first step you need to do is to get the MLA-C01 Certification, because the certification is a reflection of your ability. If you have the MLA-C01 certification, it will be easier for you to get respect and power. Our company happened to be designing the MLA-C01 exam question.
NEW QUESTION # 14
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.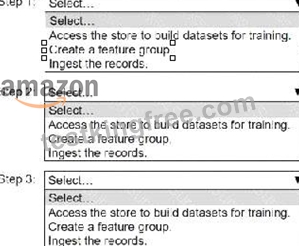
Answer:
Explanation: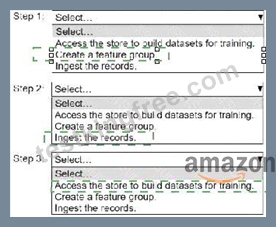
Explanation: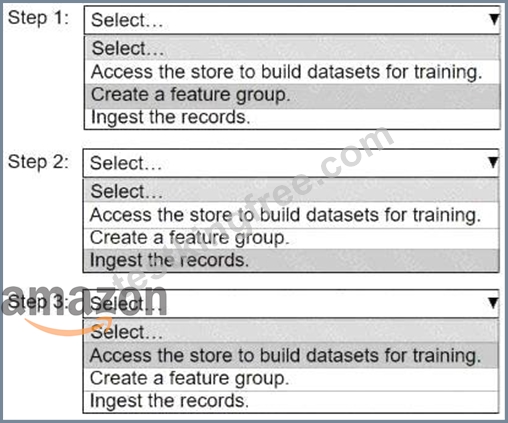
Step 1: Create a feature group.Step 2: Ingest the records.Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why?A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How?Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why?After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How?Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why?Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How?Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 15
A company needs to analyze a large dataset that is stored in Amazon S3 in Apache Parquet format. The company wants to use one-hot encoding for some of the columns.
The company needs a no-code solution to transform the data. The solution must store the transformed data back to the same S3 bucket for model training.
Which solution will meet these requirements?
Answer: C
Explanation:
AWS Glue DataBrew is specifically designed to provide no-code and low-code data preparation for analytics and machine learning. It supports common file formats such as Apache Parquet and integrates directly with Amazon S3.
Using DataBrew, users can visually create recipes that apply transformations such as one-hot encoding without writing any code. Once the recipe is defined, a DataBrew job can be run to process the dataset and store the transformed output back into Amazon S3.
Options B, C, and D all require writing SQL or code, which violates the no-code requirement. AWS documentation clearly identifies DataBrew as the correct service for interactive, visual data transformation at scale.
Therefore, Option A is the correct solution.
NEW QUESTION # 16
A company is developing a customer support AI assistant by using an Amazon Bedrock Retrieval Augmented Generation (RAG) pipeline. The AI assistant retrieves articles from a knowledge base stored in Amazon S3.
The company uses Amazon OpenSearch Service to index the knowledge base. The AI assistant uses an Amazon Bedrock Titan Embeddings model for vector search.
The company wants to improve the relevance of the retrieved articles to improve the quality of the AI assistant's answers.
Which solution will meet these requirements?
Answer: C
Explanation:
In a Retrieval Augmented Generation (RAG) architecture, retrieval quality directly impacts response accuracy. AWS documentation for Bedrock and OpenSearch highlights the use of reranker models to improve relevance after initial vector search retrieval.
Vector search retrieves documents based on embedding similarity, but the top results are not always the most contextually relevant. A reranker model evaluates the retrieved documents against the user query and reorders them based on semantic relevance before sending them to the foundation model.
Option A improves readability but does not improve retrieval relevance. Option C filters data before retrieval, which can reduce recall. Option D improves performance, not relevance.
AWS explicitly recommends reranking as a best practice for improving answer quality in RAG systems.
Therefore, Option B is the correct solution.
NEW QUESTION # 17
An ML engineer needs to process thousands of existing CSV objects and new CSV objects that are uploaded.
The CSV objects are stored in a central Amazon S3 bucket and have the same number of columns. One of the columns is a transaction date. The ML engineer must query the data based on the transaction date.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
Scenario:The ML engineer needs a low-overhead solution to query thousands of existing and new CSV objects stored in Amazon S3 based on a transaction date.
Why Athena?
* Serverless:Amazon Athena is a serverless query service that allows direct querying of data stored in S3 using standard SQL, reducing operational overhead.
* Ease of Use:By using the CTAS statement, the engineer can create a table with optimized partitions based on the transaction date. Partitioning improves query performance and minimizes costs by scanning only relevant data.
* Low Operational Overhead:No need to manage or provision additional infrastructure. Athena integrates seamlessly with S3, and CTAS simplifies table creation and optimization.
Steps to Implement:
* Organize Data in S3:Store CSV files in a bucket in a consistent format and directory structure if possible.
* Configure Athena:Use the AWS Management Console or Athena CLI to set up Athena to point to the S3 bucket.
* Run CTAS Statement:
CREATE TABLE processed_data
WITH (
format = 'PARQUET',
external_location = 's3://processed-bucket/',
partitioned_by = ARRAY['transaction_date']
) AS
SELECT *
FROM input_data;
This creates a new table with data partitioned by transaction date.
* Query the Data:Use standard SQL queries to fetch data based on the transaction date.
References:
* Amazon Athena CTAS Documentation
* Partitioning Data in Athena
NEW QUESTION # 18
An ML engineer is using Amazon SageMaker JumpStart to fine-tune a Llama 3.2 model for text generation.
The ML engineer is using an instruction-based fine-tuning method. The model uses 70 billion parameters.
Select the correct fine-tuning term from the following list to match each description. Select each term one time or not at all. (Select THREE.)
* Hyperparameter tuning
* Low-rank adaptation (LoRA)
* Fully Sharded Data Parallel (FSDP)
* Learning rate
* Int8 quantization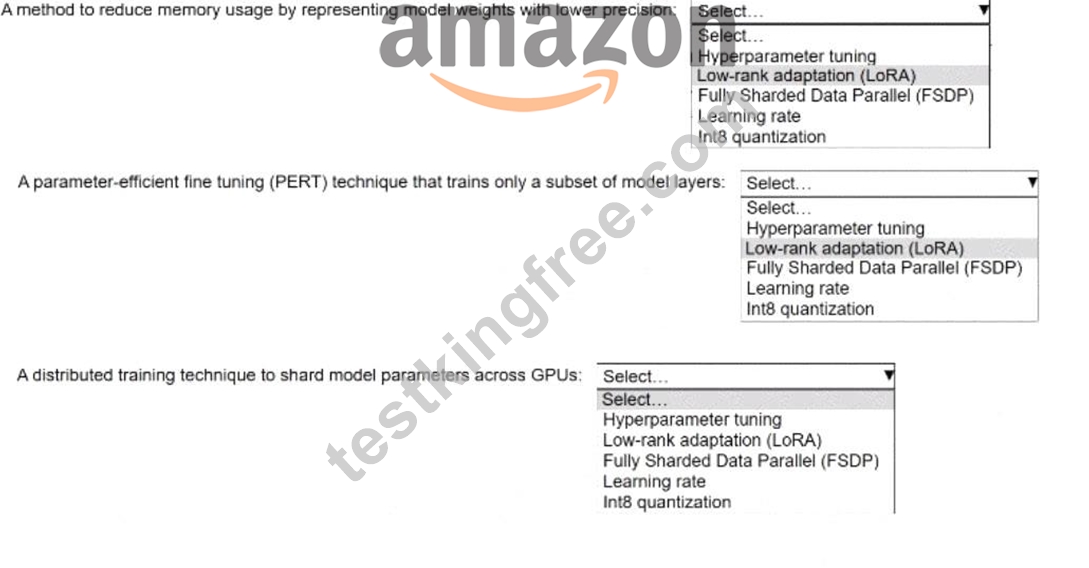
Answer:
Explanation: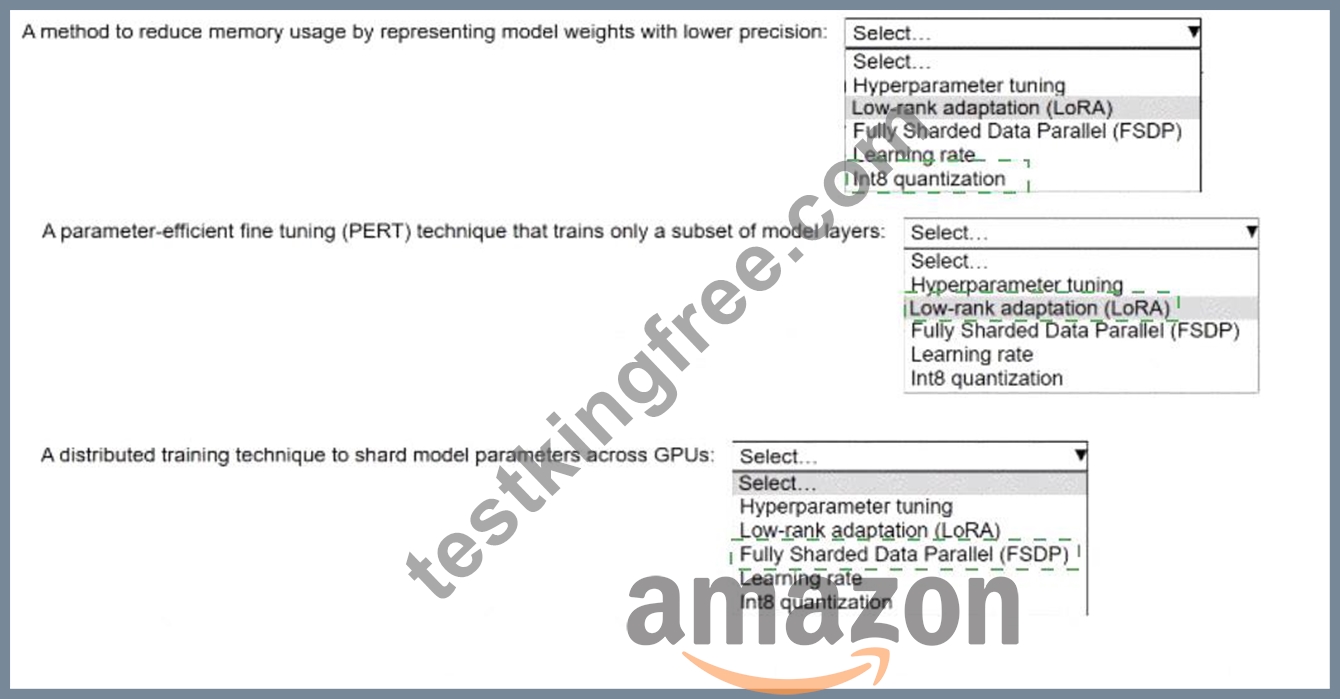
Explanation:
* Int8 quantization
* Low-rank adaptation (LoRA)
* Fully Sharded Data Parallel (FSDP)
These three mappings align with AWS documentation for large-model training and optimization in SageMaker AI.
For 1 , the correct answer is Int8 quantization . AWS documentation explains that quantization reduces hardware and memory requirements by using a less precise data type for weights and activations , including INT8 formats. AWS Prescriptive Guidance also states that quantization reduces memory footprint by converting higher-precision weights to lower-precision formats such as FP16 to INT8 . That matches the description of reducing memory usage by representing model weights with lower precision.
For 2 , the correct answer is Low-rank adaptation (LoRA) . In practice, LoRA is a standard parameter- efficient fine-tuning (PEFT) method that updates only a small subset of trainable parameters instead of full- model fine-tuning. In SageMaker JumpStart workflows for large language models, LoRA is used specifically to make fine-tuning large models more efficient by training adapter-style low-rank updates rather than all original model weights. This matches the description of a PEFT technique that trains only a subset of model parameters.
For 3 , the correct answer is Fully Sharded Data Parallel (FSDP) . AWS documentation states that SageMaker model parallelism integrates with PyTorch FSDP , which shards model states across GPUs and supports large-scale distributed training. That directly matches the description of a distributed training technique used to share or shard model parameters across GPUs.
NEW QUESTION # 19
......
We know that you care about your MLA-C01 actual test. Do you want to take a chance of passing your MLA-C01 actual test? Now, take the MLA-C01 practice test to assess your skills and focus on your studying. Firstly, download our MLA-C01 free pdf for a try now. With the try, you can get a sneak preview of what to expect in the MLA-C01 Actual Test. That MLA-C01 test engine simulates a real, timed testing situation will help you prepare well for the real test.
MLA-C01 Valid Test Labs: https://www.testkingfree.com/Amazon/MLA-C01-practice-exam-dumps.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by TestKingFree: https://drive.google.com/open?id=1Ug8f4NNK-dM_g_V9wlMD6zZeTMyB5rYR