Databricks Databricks-Certified-Professional-Data-Engineerテスト対策書、Databricks-Certified-Professional-Data-Engineer日本語版参考資料

さらに、Xhs1991 Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12JOQuQ_S0XO8ofVwpfYzcg3wBXICZ9jv
Databricks-Certified-Professional-Data-Engineer認定試験の難しさで近年、資格認定試験に合格した受験生はますます少なくなっていたと良く知られます。だから、我々社のIT専門家は長年にわたりDatabricks Databricks-Certified-Professional-Data-Engineer認定資格試験問題集作成に取り組んで、有効なDatabricks-Certified-Professional-Data-Engineer試験問題集を書きました。実際の試験に表示される質問と正確な解答はあなたのDatabricks Databricks-Certified-Professional-Data-Engineer認定資格試験合格を手伝ってあげます。素晴らしい試験参考書です。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Delta Lake | 20-25% | - Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
- Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Jobs and job scheduling
- 2. Monitoring and alerting
- 3. Task dependencies and orchestration
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
- Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
>> Databricks Databricks-Certified-Professional-Data-Engineerテスト対策書 <<
Databricks-Certified-Professional-Data-Engineer日本語版参考資料 & Databricks-Certified-Professional-Data-Engineer模擬練習
資格試験の意味は、いくつかの点で、さまざまな専門分野での能力を示すDatabricks-Certified-Professional-Data-Engineer資格を取得する受験者の能力を証明することです。 Databricks-Certified-Professional-Data-Engineer学習ガイド教材を選択すると、限られた学習時間でより多くの価値を創造し、より多くの知識を学び、受験できる試験を受けることができます。資格のあるDatabricks-Certified-Professional-Data-Engineer試験を通じて、これは私たちのDatabricks-Certified-Professional-Data-Engineerの実際の質問であり、すべてのユーザーの共通の目標であり、私たちは信頼できるヘルパーなので、このような良い機会をお見逃しなく。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q119-Q124):
質問 # 119
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. C++
- B. Scala Datasets
- C. Julia
- D. Regex
- E. pyspsark.ml.feature
正解:D
解説:
Explanation
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. References:
https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions
https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
質問 # 120
Which of the following two options are supported in identifying the arrival of new files, and incre-mental data from Cloud object storage using Auto Loader?
- A. Writing ahead logging, read head logging
- B. Checkpointing and Write ahead logging
- C. File hashing, Dynamic file lookup
- D. Directory listing, File notification
- E. Checking pointing, watermarking
正解:D
解説:
Explanation
The answer is A, Directory listing, File notifications
Directory listing: Auto Loader identifies new files by listing the input directory.
File notification: Auto Loader can automatically set up a notification service and queue service that subscribe to file events from the input directory.
Choosing between file notification and directory listing modes | Databricks on AWS
質問 # 121
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
- B. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- C. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- D. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- E. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date.
正解:D
解説:
Explanation
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed. This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table12. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
The other options are not as simple or efficient as the proposed approach, because:
Option A would require applying the churn model to all rows in the customer_churn_params table, which would be wasteful and redundant. It would also require implementing logic to perform an upsert into the predictions table, which would be more complex than using the merge statement.
Option B would require converting the batch job to a Structured Streaming job, which would involve changing the data ingestion and processing logic. It would also require using the complete output mode, which would output the entire result table every time there is a change in the source data, which would be inefficient and costly.
Option C would require calculating the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers, which would be computationally expensive and prone to errors. It would also require storing and accessing the previous predictions, which would add extra storage and I/O costs.
Option D would require modifying the overwrite logic to include a field populated by calling spark.sql.functions.current_timestamp() as data are being written, which would add extra complexity and overhead to the data engineering job. It would also require using this field to identify records written on a particular date, which would be less accurate and reliable than using the change data feed.
References: Merge, Change data feed
質問 # 122
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
- B. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- C. Define a view against the products_per_order table and define the dashboard against this view.
- D. Populate the dashboard by configuring a nightly batch job to save the required to quickly update the dashboard with each query.
正解:D
質問 # 123
Review the following error traceback:
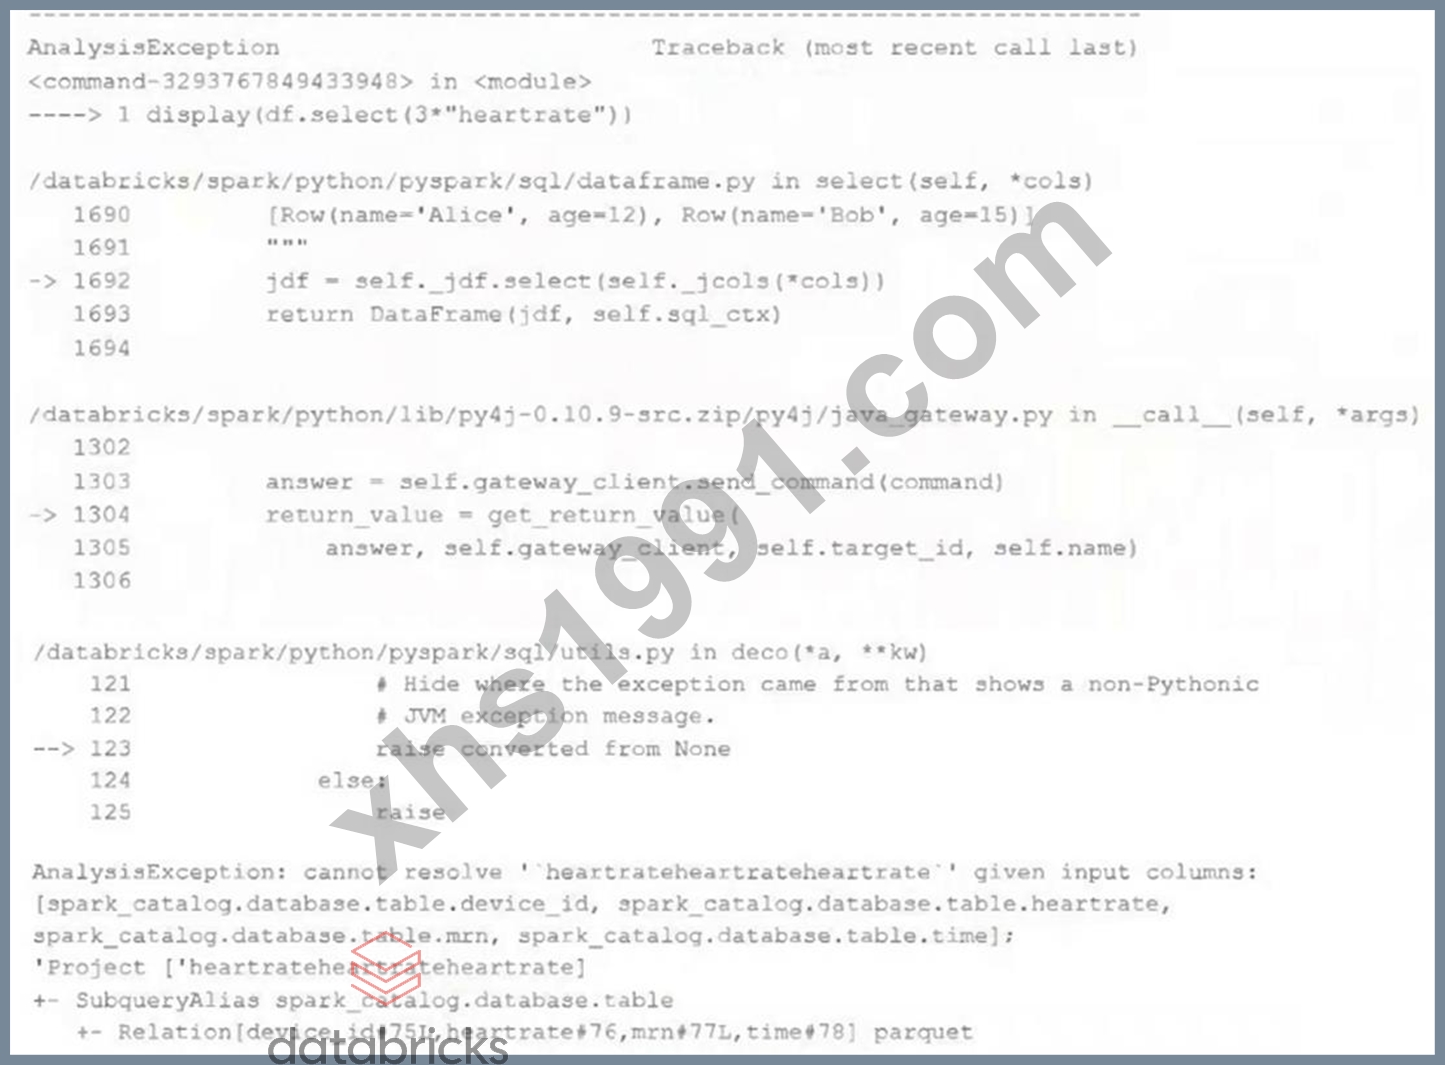
Which statement describes the error being raised?
- A. There is no column in the table named heartrateheartrateheartrate
- B. The code executed was PvSoark but was executed in a Scala notebook.
- C. There is a syntax error because the heartrate column is not correctly identified as a column.
- D. There is a type error because a DataFrame object cannot be multiplied.
- E. There is a type error because a column object cannot be multiplied.
正解:A
解説:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error1. In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns 'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as 'heartrate'. Reference: AnalysisException
質問 # 124
......
Databricks-Certified-Professional-Data-Engineerの実際の質問を使用するユーザーは、試験の準備をしていないユーザーよりも有利です。私たちの教材は、ユーザーが実際のテスト環境シミュレーショントレーニングに最も近いものにすることを可能にし、ユーザーがDatabricks-Certified-Professional-Data-Engineer実践ガイドで効果的に実践できるようにします。 。試験のために、力は試験に合格するだけでなく、受験者が能力を発揮する強い心を持っている必要があるため、Databricks-Certified-Professional-Data-Engineer学習ガイド教材は、継続的なシミュレーションテストを通じて、Databricks-Certified-Professional-Data-Engineer試験に合格するのに役立ちます。
Databricks-Certified-Professional-Data-Engineer日本語版参考資料: https://www.xhs1991.com/Databricks-Certified-Professional-Data-Engineer.html
- 完璧なDatabricks-Certified-Professional-Data-Engineerテスト対策書 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 | 権威のあるDatabricks-Certified-Professional-Data-Engineer模擬練習 🏛 最新▷ Databricks-Certified-Professional-Data-Engineer ◁問題集ファイルは➠ www.japancert.com 🠰にて検索Databricks-Certified-Professional-Data-Engineer無料問題
- Databricks-Certified-Professional-Data-Engineer無料問題 🦮 Databricks-Certified-Professional-Data-Engineer復習対策書 📣 Databricks-Certified-Professional-Data-Engineer教育資料 🎯 [ www.goshiken.com ]サイトにて➽ Databricks-Certified-Professional-Data-Engineer 🢪問題集を無料で使おうDatabricks-Certified-Professional-Data-Engineer難易度
- Databricks-Certified-Professional-Data-Engineer難易度 ❇ Databricks-Certified-Professional-Data-Engineer資格模擬 ⏫ Databricks-Certified-Professional-Data-Engineer試験復習赤本 📫 ⇛ www.xhs1991.com ⇚を開いて▛ Databricks-Certified-Professional-Data-Engineer ▟を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語試験情報
- Databricks-Certified-Professional-Data-Engineer認証pdf資料 🌈 Databricks-Certified-Professional-Data-Engineer資格模擬 🏎 Databricks-Certified-Professional-Data-Engineer資格模擬 🧯 ▷ www.goshiken.com ◁から簡単に➠ Databricks-Certified-Professional-Data-Engineer 🠰を無料でダウンロードできますDatabricks-Certified-Professional-Data-Engineer日本語独学書籍
- 試験Databricks-Certified-Professional-Data-Engineerテスト対策書 - 真実的なDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 | 大人気Databricks-Certified-Professional-Data-Engineer模擬練習 🥰 ☀ www.japancert.com ️☀️の無料ダウンロード⮆ Databricks-Certified-Professional-Data-Engineer ⮄ページが開きますDatabricks-Certified-Professional-Data-Engineer試験対応
- 試験の準備方法-ユニークなDatabricks-Certified-Professional-Data-Engineerテスト対策書試験-正確的なDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 🖌 サイト⏩ www.goshiken.com ⏪で➡ Databricks-Certified-Professional-Data-Engineer ️⬅️問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer日本語参考
- Databricks-Certified-Professional-Data-Engineer試験復習赤本 🥊 Databricks-Certified-Professional-Data-Engineer復習対策書 🍋 Databricks-Certified-Professional-Data-Engineer復習範囲 ⏮ 検索するだけで▷ www.xhs1991.com ◁から《 Databricks-Certified-Professional-Data-Engineer 》を無料でダウンロードDatabricks-Certified-Professional-Data-Engineer日本語試験情報
- Databricks-Certified-Professional-Data-Engineer試験関連赤本 🚧 Databricks-Certified-Professional-Data-Engineer無料問題 🧷 Databricks-Certified-Professional-Data-Engineer無料問題 🎼 ⏩ www.goshiken.com ⏪を開いて▶ Databricks-Certified-Professional-Data-Engineer ◀を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語独学書籍
- 試験の準備方法-実際的なDatabricks-Certified-Professional-Data-Engineerテスト対策書試験-信頼的なDatabricks-Certified-Professional-Data-Engineer日本語版参考資料 🧅 時間限定無料で使える▶ Databricks-Certified-Professional-Data-Engineer ◀の試験問題は➽ www.goshiken.com 🢪サイトで検索Databricks-Certified-Professional-Data-Engineer日本語版と英語版
- Databricks-Certified-Professional-Data-Engineer日本語試験情報 🥰 Databricks-Certified-Professional-Data-Engineer的中合格問題集 🙀 Databricks-Certified-Professional-Data-Engineer絶対合格 🧇 今すぐ{ www.goshiken.com }で➡ Databricks-Certified-Professional-Data-Engineer ️⬅️を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語独学書籍
- Databricks-Certified-Professional-Data-Engineer最新試験pdf、Databricks-Certified-Professional-Data-Engineer試験練習資料、Databricks-Certified-Professional-Data-Engineer有効な試験トピック 🥡 URL ▶ www.passtest.jp ◀をコピーして開き、☀ Databricks-Certified-Professional-Data-Engineer ️☀️を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語独学書籍
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.fanart-central.net, forum.anchorpointpodcast.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.zazzle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
無料でクラウドストレージから最新のXhs1991 Databricks-Certified-Professional-Data-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=12JOQuQ_S0XO8ofVwpfYzcg3wBXICZ9jv