P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1nSmT2tmG02xnuCCzoOBm9QX08IdcoGIc
The system of DP-100 test guide will keep track of your learning progress in the whole course. Therefore, you can have 100% confidence in our DP-100 exam guide. According to our overall evaluation and research, seldom do we have cases that customers fail the DP-100 exam after using our study materials. But to relieve your doubts about failure in the test, we guarantee you a full refund from our company by virtue of the related proof of your report card. Of course you can freely change another DP-100 Exam Guide to prepare for the next exam. Generally speaking, our company takes account of every client’ difficulties with fitting solutions.
| Section | Objectives |
|---|---|
| Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
It is well known that Microsoft certification plays a big part in the IT field and obtaining it means you have access to the big companies and recognized by the authority. But the reality is that the DP-100 Braindumps torrents are very difficult and the pass rate of DP-100 practice test is low. So choosing our exam training materials are very necessary to every candidate.
NEW QUESTION # 193
You need to define a process for penalty event detection.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
1 - Import the global model and build 1 the local model using PyTorch.
2 - Build the global model using PyTorch.
3 - Build the global model using TensorFlow
4 - Import the global model and build the local model using TensorFlow.
NEW QUESTION # 194
You have a feature set containing the following numerical features: X, Y, and Z.
The Poisson correlation coefficient (r-value) of X, Y, and Z features is shown in the following image:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: 0.859122
Box 2: a positively linear relationship
+1 indicates a strong positive linear relationship
-1 indicates a strong negative linear correlation
0 denotes no linear relationship between the two variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation
NEW QUESTION # 195
You train a machine learning model by using Aunt Machine Learning.
You use the following training script m Python to log an accuracy value.
You must use a Python script to define a sweep job.
You need to provide the primary metric and goal you want hyper parameter tuning to optimize.
How should you complete the Python script? To answer select the appropriate options in the answer area NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 196
You need to configure the Edit Metadata module so that the structure of the datasets match.
Which configuration options should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Floating point
Need floating point for Median values.
Scenario: An initial investigation shows that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format.
Box 2: Unchanged
Note: Select the Categorical option to specify that the values in the selected columns should be treated as categories.
For example, you might have a column that contains the numbers 0,1 and 2, but know that the numbers actually mean " Smoker " , " Non smoker " and " Unknown " . In that case, by flagging the column as categorical you can ensure that the values are not used in numeric calculations, only to group data.
NEW QUESTION # 197
You previously deployed a model that was trained using a tabular dataset named training-dataset, which is based on a folder of CSV files.
Over time, you have collected the features and predicted labels generated by the model in a folder containing a CSV file for each month. You have created two tabular datasets based on the folder containing the inference data: one named predictions-dataset with a schema that matches the training data exactly, including the predicted label; and another named features-dataset with a schema containing all of the feature columns and a timestamp column based on the filename, which includes the day, month, and year.
You need to create a data drift monitor to identify any changing trends in the feature data since the model was trained. To accomplish this, you must define the required datasets for the data drift monitor.
Which datasets should you use to configure the data drift monitor? To answer, drag the appropriate datasets to the correct data drift monitor options. Each source may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: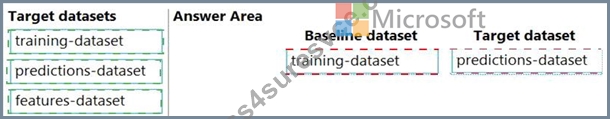
Explanation:
Box 1: training-dataset
Baseline dataset - usually the training dataset for a model.
Box 2: predictions-dataset
Target dataset - usually model input data - is compared over time to your baseline dataset. This comparison means that your target dataset must have a timestamp column specified.
The monitor will compare the baseline and target datasets.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-monitor-datasets
NEW QUESTION # 198
......
With the Microsoft DP-100 certification exam you will get an opportunity to learn new and in-demand skills. In this way, you will stay updated and competitive in the market and advance your career easily. To do this you just need to pass the Designing and Implementing a Data Science Solution on Azure DP-100 Certification Exam.
Examcollection DP-100 Vce: https://www.pass4suresvce.com/DP-100-pass4sure-vce-dumps.html
What's more, part of that Pass4suresVCE DP-100 dumps now are free: https://drive.google.com/open?id=1nSmT2tmG02xnuCCzoOBm9QX08IdcoGIc