Successful people are those who are willing to make efforts. If you have never experienced the wind and rain, you will never see the rainbow. Giving is proportional to the reward. Now, our Certified-Data-Engineer-Professional study materials just need you spend less time, then your life will take place great changes. Maybe you think that our Certified-Data-Engineer-Professional study materials cannot make a difference. But you must know that if you do not have a try, your life will never be improved. It is useless that you speak boast yourself but never act. Please muster up all your courage. No one will laugh at a hardworking person. Our Certified-Data-Engineer-Professional Study Materials are your good study partner.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 2: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 3: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 4: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 5: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 6: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 7: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 8: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 9: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
>> Latest Certified-Data-Engineer-Professional Test Vce <<
DumpsQuestion is responsible for our Certified-Data-Engineer-Professional study materials. Every exam product of DumpsQuestion have sold to customer will enjoy considerate after-sales service. If you have problems about our Certified-Data-Engineer-Professional study materials such as installation, operation and so on, we will quickly reply to you after our online workers have received your emails. We are not afraid of troubles. We warmly welcome to your questions and suggestions on the Certified-Data-Engineer-Professional Exam Questions. We sincerely hope we can help you solve your problem and help you pass the Certified-Data-Engineer-Professional exam.
NEW QUESTION # 35
A nightly batch job is configured to ingest all data files from a cloud object storage container where records are stored in a nested directory structure YYYY/MM/DD. The data for each date represents all records that were processed by the source system on that date, noting that some records may be delayed as they await moderator approval. Each entry represents a user review of a product and has the following schema:
user_id STRING, review_id BIGINT, product_id BIGINT, review_timestamp TIMESTAMP, review_text STRING The ingestion job is configured to append all data for the previous date to a target table reviews_raw with an identical schema to the source system. The next step in the pipeline is a batch write to propagate all new records inserted into reviews_raw to a table where data is fully deduplicated, validated, and enriched.
Which solution minimizes the compute costs to propagate this batch of data?
Answer: A
Explanation:
https://www.databricks.com/blog/2017/05/22/running-streaming-jobs-day-10x-cost-savings.html
NEW QUESTION # 36
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job: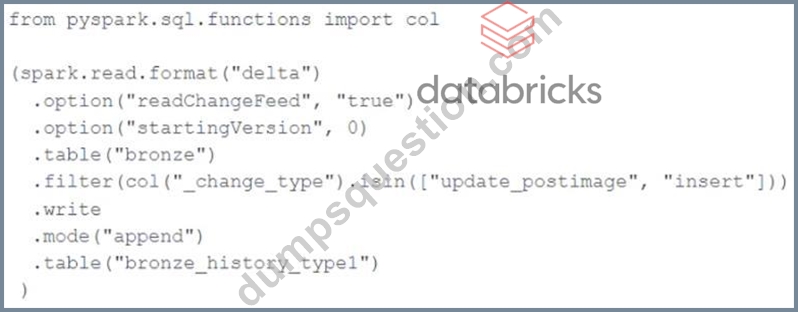
Which statement describes the execution and results of running the above query multiple times?
Answer: E
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 37
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
Answer: C
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 38
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability. Which piece of information is critical to this decision?
Answer: B
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
NEW QUESTION # 39
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: C
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 40
......
The Databricks Certified-Data-Engineer-Professional pdf questions learning material provided to the customers from DumpsQuestion is in three different formats. The first format is PDF format which is printable and portable. It means it can be accessed from tablets, laptops, and smartphones to prepare for the Databricks Certified-Data-Engineer-Professional Exam. The Databricks Certified-Data-Engineer-Professional PDF format can be used offline, and candidates can even prepare for it in the classroom or library by printing questions or on their smart devices.
Certified-Data-Engineer-Professional Exam Score: https://www.dumpsquestion.com/Certified-Data-Engineer-Professional-exam-dumps-collection.html