As the authoritative provider of Certified-Data-Engineer-Professional guide training, we can guarantee a high pass rate compared with peers, which is also proved by practice. Our good reputation is your motivation to choose our learning materials. We guarantee that if you under the guidance of our Certified-Data-Engineer-Professional study tool step by step you will pass the exam without a doubt and get a certificate. Our Certified-Data-Engineer-Professional Learning Materials are carefully compiled over many years of practical effort and are adaptable to the needs of the Certified-Data-Engineer-Professional exam. We firmly believe that you cannot be an exception.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 2: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 3: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 4: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 5: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 6: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures |
| Topic 7: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 8: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 9: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
>> Certified-Data-Engineer-Professional Reliable Braindumps Ppt <<
Our users of the Certified-Data-Engineer-Professional learning guide are all over the world. Therefore, we have seen too many people who rely on our Certified-Data-Engineer-Professional exam materials to achieve counterattacks. Everyone's success is not easily obtained if without our Certified-Data-Engineer-Professional study questions. Of course, they have worked hard, but having a competent assistant is also one of the important factors. And our Certified-Data-Engineer-Professional Practice Engine is the right key to help you get the certification and lead a better life!
NEW QUESTION # 59
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
Answer: A
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
NEW QUESTION # 60
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 61
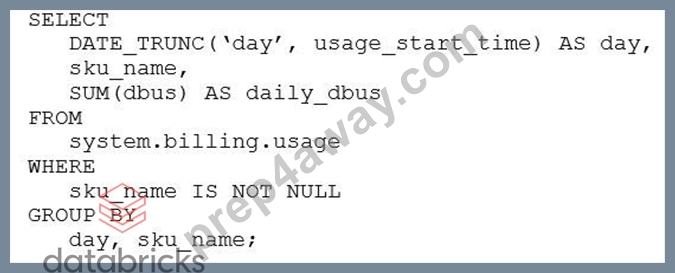
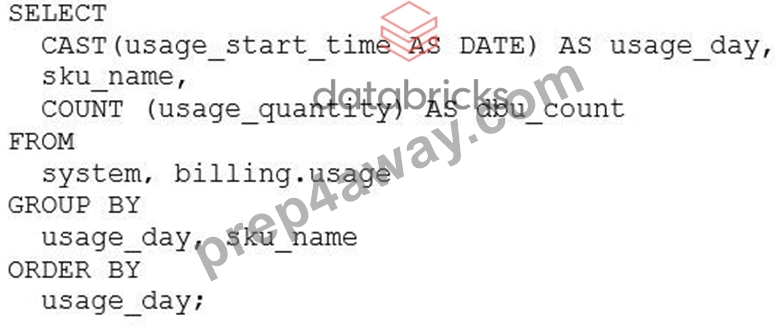
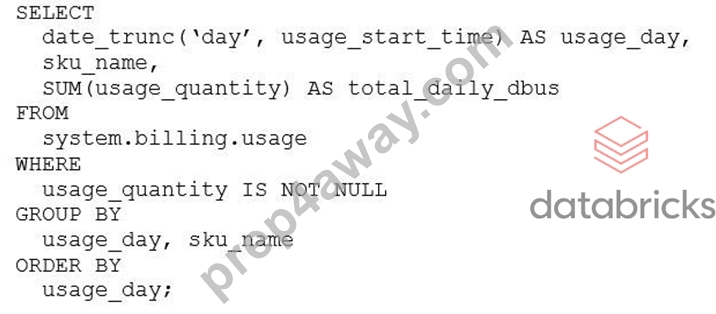
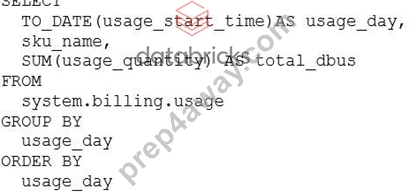
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
Answer: C
Explanation:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
NEW QUESTION # 62
What statement is true regarding the retention of job run history?
Answer: D
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 63
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: B
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 64
......
Dear everyone, to get yourself certified by our Certified-Data-Engineer-Professional exam prep. We offer you the real and updated Prep4away Certified-Data-Engineer-Professional study material for your exam preparation. The Certified-Data-Engineer-Professional online test engine can create an interactive simulation environment for you. When you try the Certified-Data-Engineer-Professional online test engine, you will really feel in the actual test. Besides, you can get your exam scores after each test. What's more, it is very convenient to do marks and notes. Thus, you can know your strengths and weakness after review your Certified-Data-Engineer-Professional test. Then you can do a detail study plan and the success will be a little case.
Certified-Data-Engineer-Professional Exam Dumps Free: https://www.prep4away.com/Databricks-certification/braindumps.Certified-Data-Engineer-Professional.ete.file.html