We are well-known for our wonderful performance on pushing more and more candidates to pass their Databricks-Certified-Professional-Data-Engineer exams and achieve their dreaming certifications. There is no exaggeration to say that with our Databricks-Certified-Professional-Data-Engineer study materials for 20 to 30 hours, you will be ready to pass your Databricks-Certified-Professional-Data-Engineer Exam. Since our Databricks-Certified-Professional-Data-Engineer exam torrent is designed on the purpose to be understood by our customers all over the world, it is compiled into the simplest language to save time and efforts.
Databricks Certified Professional Data Engineer certification exam is a rigorous and challenging exam that requires a deep understanding of data engineering concepts and the Databricks platform. Candidates must have a strong foundation in computer science and data engineering, as well as practical experience using the Databricks platform. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and hands-on exercises that test a candidate's ability to design, build, and maintain data pipelines using the Databricks platform.
>> Real Databricks-Certified-Professional-Data-Engineer Exam Dumps <<
After studying with our Databricks-Certified-Professional-Data-Engineer practice engine, as our loyal customers wrote to us that they are now more efficient than their colleagues, so they have received more attention from their leaders and got the promotion on both incomes and positions. We are all ordinary professional people. We must show our strength to show that we are worth the opportunity. And with the help of our Databricks-Certified-Professional-Data-Engineer Exam Braindumps, they all proved themselves and got their success. Just buy our Databricks-Certified-Professional-Data-Engineer learning guide, you will be one of them too!
To take the Databricks Certified Professional Data Engineer certification exam, candidates must have a strong background in data engineering and experience working with Databricks. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and hands-on tasks that require candidates to demonstrate their ability to design, build, and manage data processing systems using Databricks. Databricks-Certified-Professional-Data-Engineer Exam covers a wide range of topics, including data ingestion, data transformation, data storage, data processing, and data visualization. Upon successful completion of the exam, candidates will receive a Databricks Certified Professional Data Engineer certification, which demonstrates their expertise in using Databricks to build and maintain data processing systems.
NEW QUESTION # 26
You are asked to debug a databricks job that is taking too long to run on Sunday's, what are the steps you are going to take to identify the step that is taking longer to run?
Answer: E
Explanation:
Explanation
The answer is, Under Workflow UI and jobs select job you want to monitor and select the run, notebook activity can be viewed.
You have the ability to view current active runs or completed runs, once you click the run you can see the A picture containing graphical user interface Description automatically generated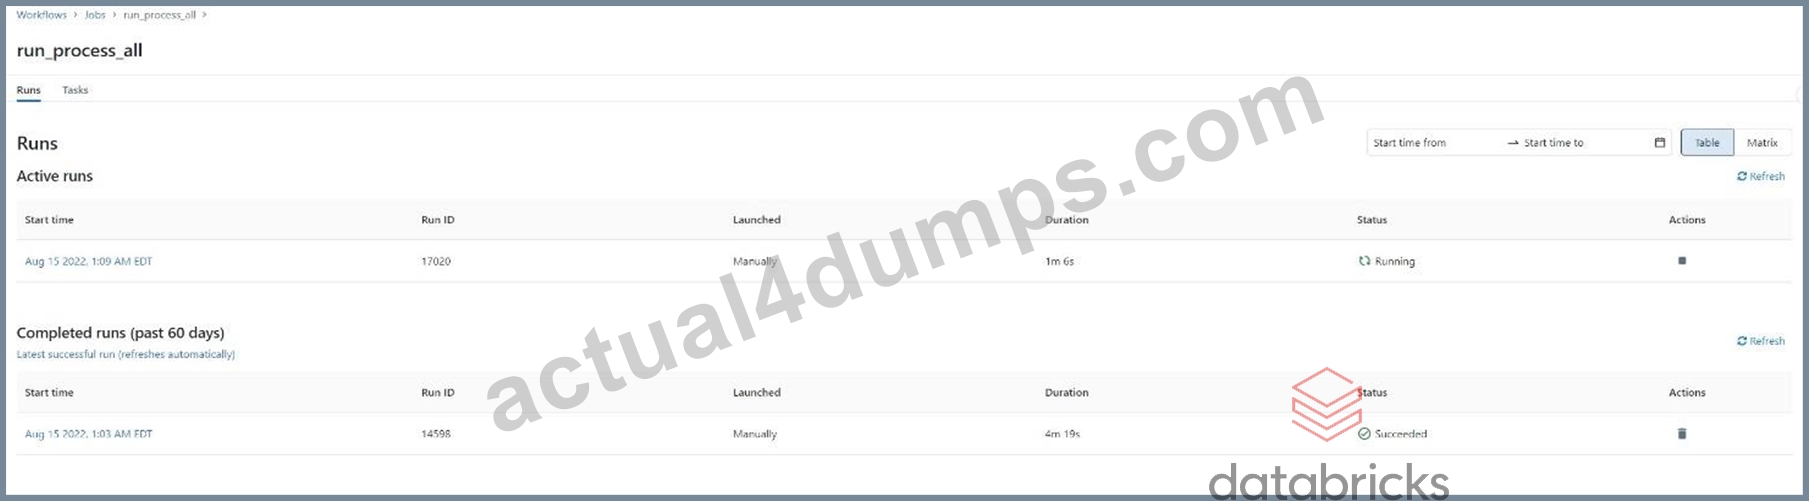
Click on the run to view the notebook output
Graphical user interface, text, application, email Description automatically generated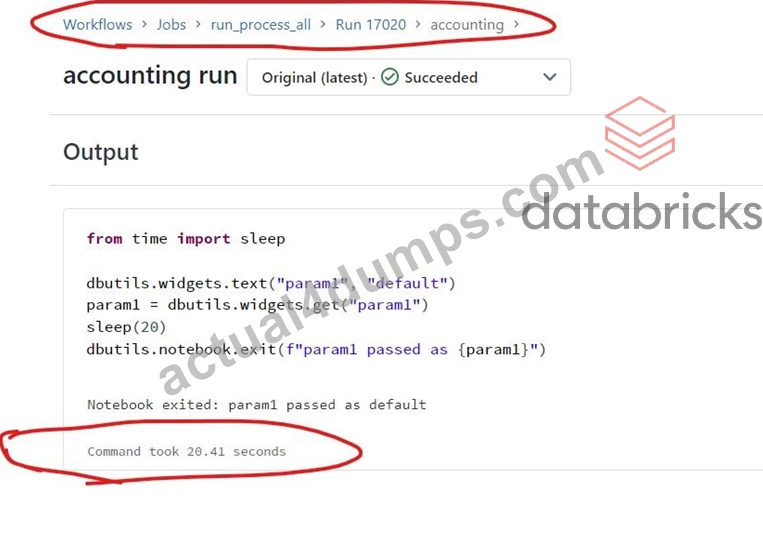
NEW QUESTION # 27
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: A
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) → records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) → records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) → records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount ≤ 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 28
Where in the Spark UI can one diagnose a performance problem induced by not leveraging predicate push-down?
Answer: D
Explanation:
This is the correct answer because it is where in the Spark UI one can diagnose a performance problem induced by not leveraging predicate push-down. Predicate push-down is an optimization technique that allows filtering data at the source before loading it into memory or processing it further. This can improve performance and reduce I/O costs by avoiding reading unnecessary data. To leverage predicate push-down, one should use supported data sources and formats, such as Delta Lake, Parquet, or JDBC, and use filter expressions that can be pushed down to the source. To diagnose a performance problem induced by not leveraging predicate push-down, one can use the Spark UI to access the Query Detail screen, which shows information about a SQL query executed on a Spark cluster. The Query Detail screen includes the Physical Plan, which is the actual plan executed by Spark to perform the query. The Physical Plan shows the physical operators used by Spark, such as Scan, Filter, Project, or Aggregate, and their input and output statistics, such as rows and bytes. By interpreting the Physical Plan, one can see if the filter expressions are pushed down to the source or not, and how much data is read or processed by each operator. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under
"Predicate pushdown" section; Databricks Documentation, under "Query detail page" section.
NEW QUESTION # 29
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
Answer: B
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use thedatabricks pipelines get --pipeline-idcommand to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing thepipeline_idto prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines createcommand to create a new pipeline with those settings.
References:
* Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
NEW QUESTION # 30
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver) . The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: A
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 31
......
Databricks-Certified-Professional-Data-Engineer Reliable Exam Cost: https://www.actual4dumps.com/Databricks-Certified-Professional-Data-Engineer-study-material.html