DOWNLOAD the newest ValidTorrent Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1arrsMk3lRrD1nrKll2gozCGnbeJsFObb
Constant improvements are the inner requirement for one person. As one person you can’t be satisfied with your present situation and must keep the pace of the times. You should constantly update your stocks of knowledge and practical skills. So you should attend the certificate exams such as the test Databricks-Generative-AI-Engineer-Associate Certification to improve yourself and buying our Databricks-Generative-AI-Engineer-Associate study materials is your optimal choice. Our Databricks-Generative-AI-Engineer-Associate study materials combine the real exam’s needs and the practicability of the knowledge.
| Section | Weight | Objectives |
|---|---|---|
| Application Development | 30% | - Develop LLM chains - Integrate Databricks tools (LangChain, etc.) - Implement prompt engineering |
| Assembling and Deploying Apps | 22% | - Build and deploy RAG pipelines - Package and deploy models - Use Vector Search |
| Design Applications | 14% | - Design and architect applications - Define functional requirements - Select appropriate models |
| Governance | 8% | - Apply safety filters and guidelines - Manage permissions and logging |
| Data Preparation | 14% | - Prepare data for RAG applications - Manage data quality and chunking |
| Evaluation and Monitoring | 12% | - Evaluate model quality and performance - Monitor deployed applications |
>> Databricks-Generative-AI-Engineer-Associate Valid Test Sample <<
Scenarios of our Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice tests are similar to the actual Databricks-Generative-AI-Engineer-Associate exam. You feel like sitting in the real Databricks-Generative-AI-Engineer-Associate exam while taking these Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice exams. Practicing under these conditions helps you cope with Databricks Databricks-Generative-AI-Engineer-Associate Exam anxiety. Moreover, regular attempts of the Databricks-Generative-AI-Engineer-Associate practice test are also beneficial to enhance your speed of completing the final Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) test within the given time.
NEW QUESTION # 84
A company has a typical RAG-enabled, customer-facing chatbot on its website.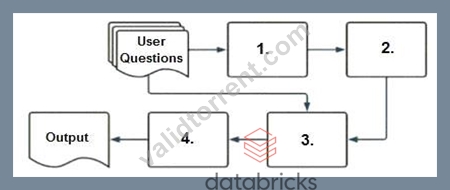
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 85
A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.
Which method should the engineer use to achieve this integration?
Answer: D
Explanation:
A Delta Sync index with managed embeddings supports the workflow described. The engineer identifies the source text column and configures the embedding model endpoint. Databricks computes embeddings as part of synchronization and maintains the corresponding searchable index. This removes the requirement to calculate vectors independently and write them into the source table before indexing. With self-managed embeddings, the application or upstream pipeline must already provide the embedding vectors. A Direct Vector Access index requires explicit updates through an API or SDK and does not automatically synchronize with the source Delta table. "Hybrid embedding computing" is not the relevant index configuration; hybrid search combines retrieval techniques. Managed embeddings and Delta synchronization therefore address both automatic vector generation and source-data integration. Databricks documentation
NEW QUESTION # 86
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: A
NEW QUESTION # 87
A Generative Al Engineer is tasked with improving the RAG quality by addressing its inflammatory outputs.
Which action would be most effective in mitigating the problem of offensive text outputs?
Answer: C
Explanation:
Addressing offensive or inflammatory outputs in a Retrieval-Augmented Generation (RAG) system is critical for improving user experience and ensuring ethical AI deployment. Here's whyDis the most effective approach:
* Manual data curation: The root cause of offensive outputs often comes from the underlying data used to train the model or populate the retrieval system. By manually curating the upstream data and conducting thorough reviews before the data is fed into the RAG system, the engineer can filter out harmful, offensive, or inappropriate content.
* Improving data quality: Curating data ensures the system retrieves and generates responses from a high-quality, well-vetted dataset. This directly impacts the relevance and appropriateness of the outputs from the RAG system, preventing inflammatory content from being included in responses.
* Effectiveness: This strategy directly tackles the problem at its source (the data) rather than just mitigating the consequences (such as informing users or restricting access). It ensures that the system consistently provides non-offensive, relevant information.
Other options, such as increasing the frequency of data updates or informing users about behavior expectations, may not directly mitigate the generation of inflammatory outputs.
NEW QUESTION # 88
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: B
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy, which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
Option A: Pick an embedding model trained on related domain knowledge
Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
Databricks Reference: "For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data" ("Building LLM Applications with Databricks," 2023).
Option B: Pick the most recent and most performant open LLM released at the time LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
Databricks Reference: Embedding models and LLMs are distinct in RAG workflows: "Embedding models convert text to vectors, while LLMs generate responses" ("Generative AI Cookbook").
Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
Databricks Reference: General performance is less critical than domain fit: "Benchmark rankings provide a starting point, but domain-specific evaluation is recommended" ("Databricks Generative AI Engineer Guide").
Option D: Pick an embedding model with multilingual support to support potential multilingual user questions Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
Databricks Reference: "Choose features like multilingual support based on application requirements" ("Building LLM-Powered Applications").
Conclusion: Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 89
......
PDF design has versatile and printable material for Databricks Databricks-Generative-AI-Engineer-Associate certification, so you all can breeze through the Databricks Databricks-Generative-AI-Engineer-Associate exam without any problem. You can get to the PDF concentrate on material from workstations, tablets, and cell phones for the readiness of Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam.
New Databricks-Generative-AI-Engineer-Associate Learning Materials: https://www.validtorrent.com/Databricks-Generative-AI-Engineer-Associate-valid-exam-torrent.html
What's more, part of that ValidTorrent Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1arrsMk3lRrD1nrKll2gozCGnbeJsFObb