
P.S.CertJukenがGoogle Driveで共有している無料の2026 Amazon SAA-C03ダンプ:https://drive.google.com/open?id=1TxFMQ9BnAWNCCOiFKlBmtjfTnwTalXSE
人間はそれぞれ夢を持っています。適当な方法を採用する限り、夢を現実にすることができます。CertJukenのAmazonのSAA-C03試験トレーニング資料を利用したら、AmazonのSAA-C03認定試験に合格することができるようになります。どうしてですかと質問したら、CertJukenのAmazonのSAA-C03試験トレーニング資料はIT認証に対する最高のトレーニング資料ですから。その資料は最完全かつ最新で、合格率が非常に高いということで人々に知られています。それを持っていたら、あなたは時間とエネルギーを節約することができます。CertJukenを利用したら、あなたは楽に試験に受かることができます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design Secure Architectures | 30% | - Design secure workloads and applications
|
| Topic 2: Design Cost-Optimized Architectures | 20% | - Design cost-effective compute and network solutions
|
| Topic 3: Design Resilient Architectures | 26% | - Design highly available and fault-tolerant architectures
|
| Topic 4: Design High-Performing Architectures | 24% | - Design high-performance compute solutions
|
人によって目標が違いますが、あなたにAmazon SAA-C03試験に順調に合格できるのは我々の共同の目標です。この目標の達成はあなたがIT技術領域へ行く更なる発展の一歩ですけど、我々社CertJuken存在するこそすべての意義です。だから、我々社は力の限りで弊社のAmazon SAA-C03試験資料を改善し、改革の変更に応じて更新します。あなたはいつまでも最新版の問題集を使用できるために、ご購入の一年間で無料の更新を提供します。
質問 # 965
A company wants to optimize Amazon S3 storage costs for the company's video content. The company needs to archive the video content 6 months after the company creates the content.
The company must delete the content after 24 months. Which solution will meet these requirements with the LEAST operational effort?
正解:C
解説:
An S3 Lifecycle configuration is the lowest-effort way to automate both actions on S3 objects:
transitioning the video content to S3 Glacier Flexible Retrieval after 6 months and expiring the objects after 24 months. AWS S3 Lifecycle is built specifically to transition objects to lower-cost storage classes and delete expired objects automatically, so no custom workflows or separate services are needed.
質問 # 966
A government agency plans to store confidential tax documents on AWS. Due to the sensitive information in the files, the Solutions Architect must restrict the data access requests made to the storage solution to a specific Amazon VPC only. The solution should also prevent the files from being deleted or overwritten to meet the regulatory requirement of having a write-once-read-many (WORM) storage model.
Which combination of the following options should the Architect implement? (Select TWO.)
正解:B、C
解説:
Amazon S3 access points simplify data access for any AWS service or customer application that stores data in S3. Access points are named network endpoints that are attached to buckets that you can use to perform S3 object operations, such as GetObject and PutObject.
Each access point has distinct permissions and network controls that S3 applies for any request that is made through that access point. Each access point enforces a customized access point policy that works in conjunction with the bucket policy that is attached to the underlying bucket. You can configure any access point to accept requests only from a virtual private cloud (VPC) to restrict Amazon S3 data access to a private network. You can also configure custom block public access settings for each access point.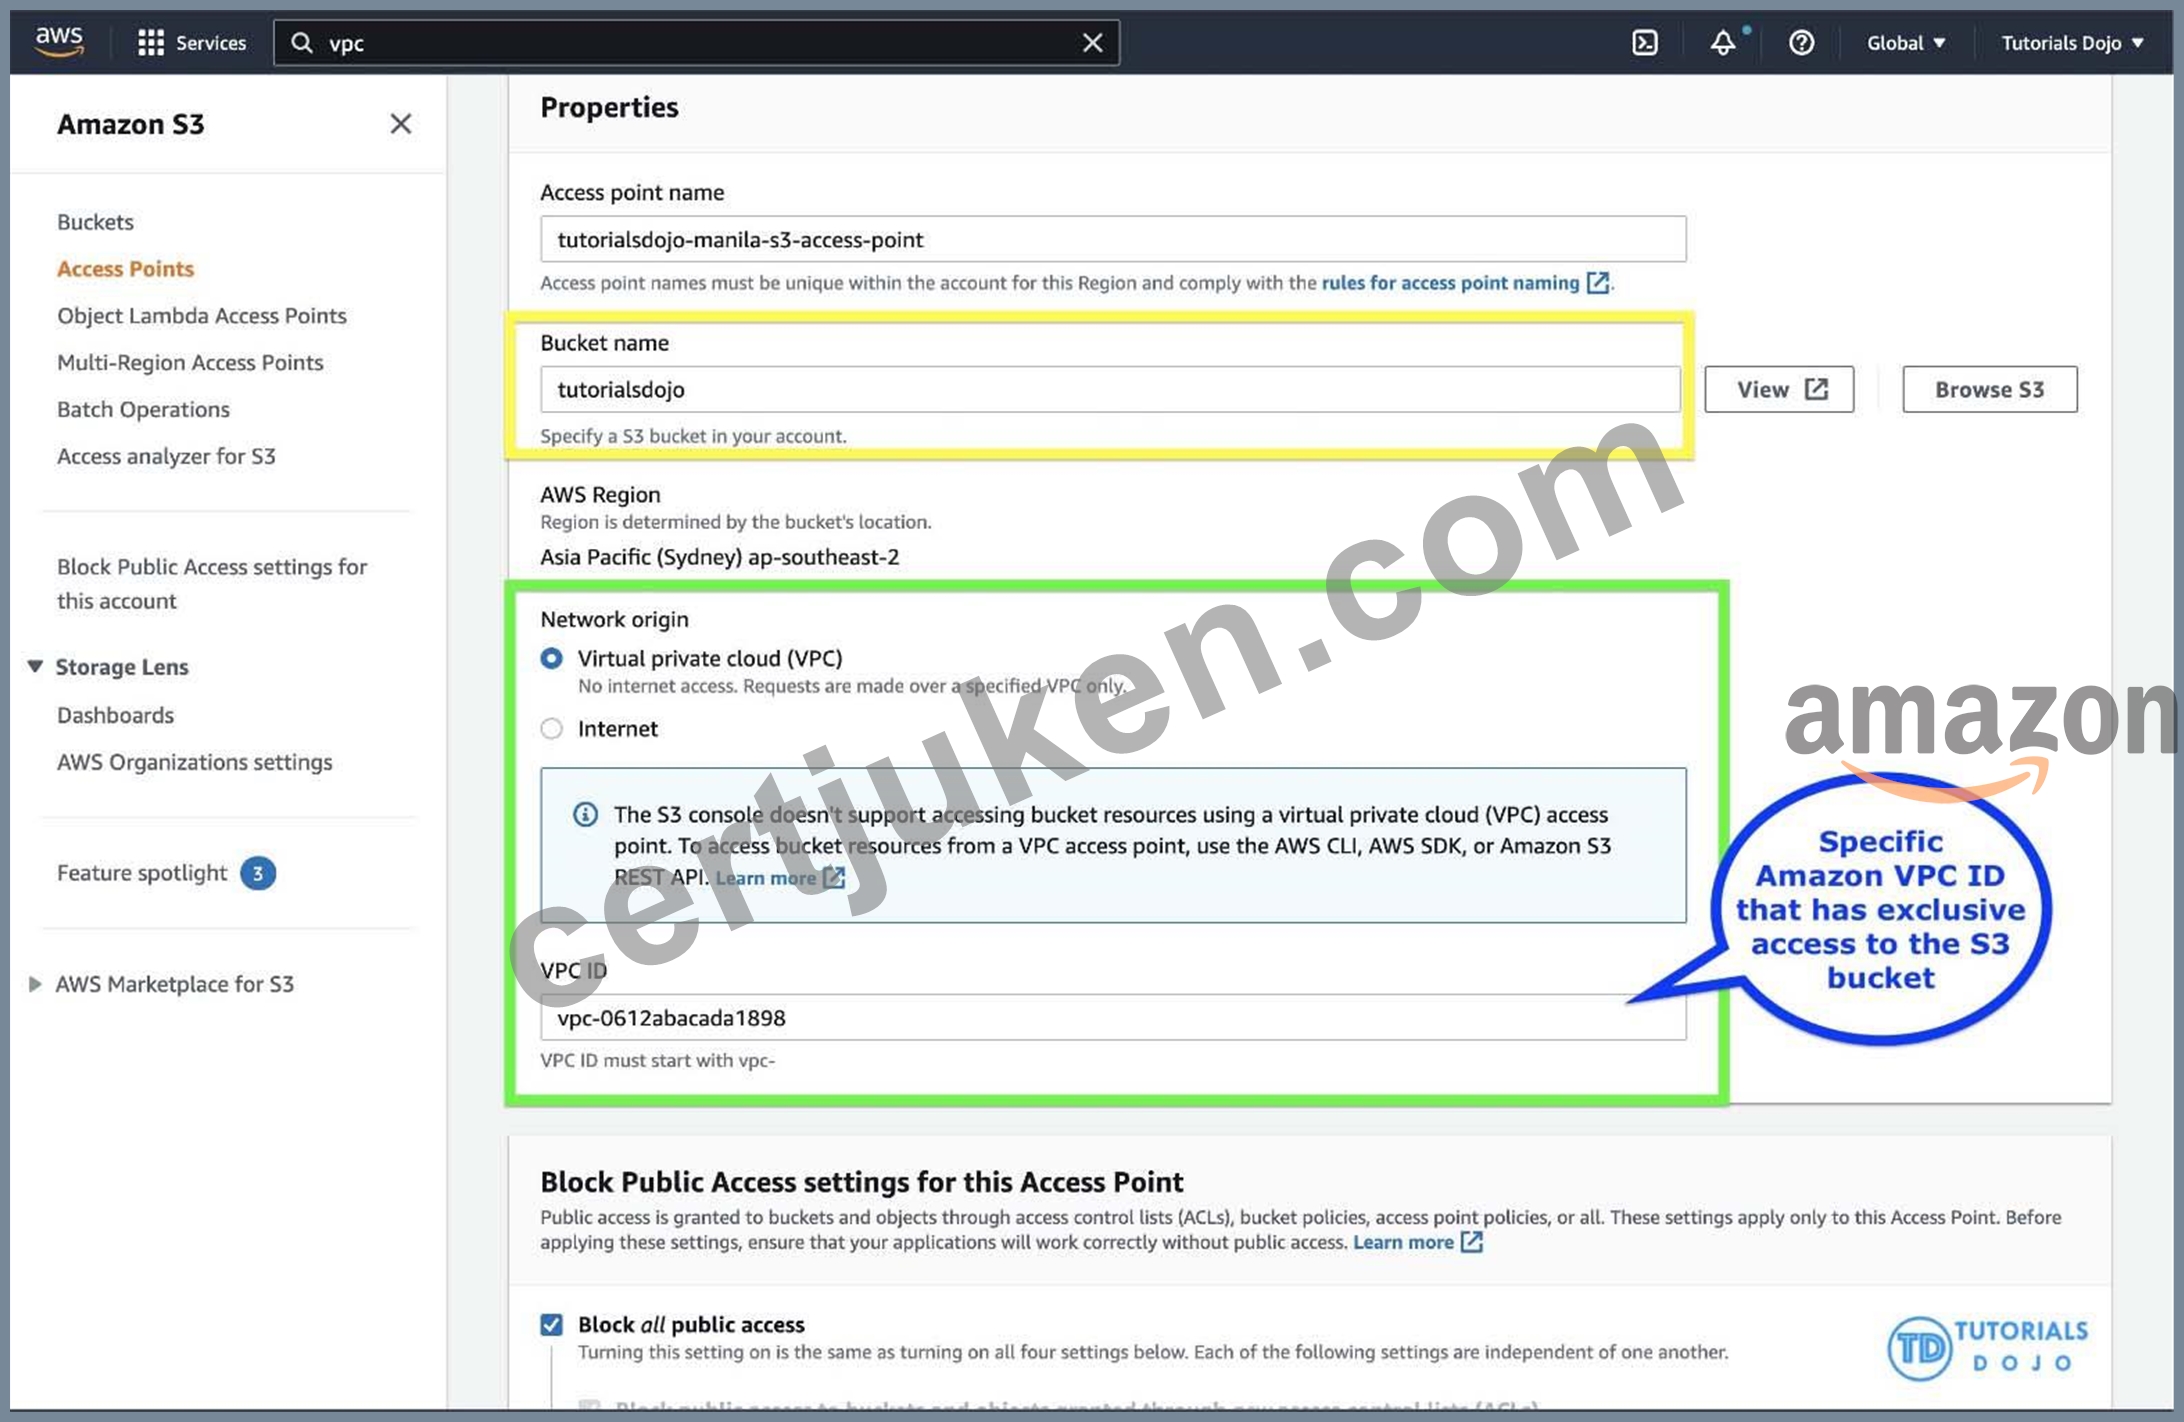
You can also use Amazon S3 Multi-Region Access Points to provide a global endpoint that applications can use to fulfill requests from S3 buckets located in multiple AWS Regions. You can use Multi-Region Access Points to build multi-Region applications with the same simple architecture used in a single Region, and then run those applications anywhere in the world. Instead of sending requests over the congested public internet, Multi-Region Access Points provide built-in network resilience with acceleration of internet-based requests to Amazon S3. Application requests made to a Multi-Region Access Point global endpoint use AWS Global Accelerator to automatically route over the AWS global network to the S3 bucket with the lowest network latency.
With S3 Object Lock, you can store objects using a write-once-read-many (WORM) model. Object Lock can help prevent objects from being deleted or overwritten for a fixed amount of time or indefinitely. You can use Object Lock to help meet regulatory requirements that require WORM storage, or to simply add another layer of protection against object changes and deletion.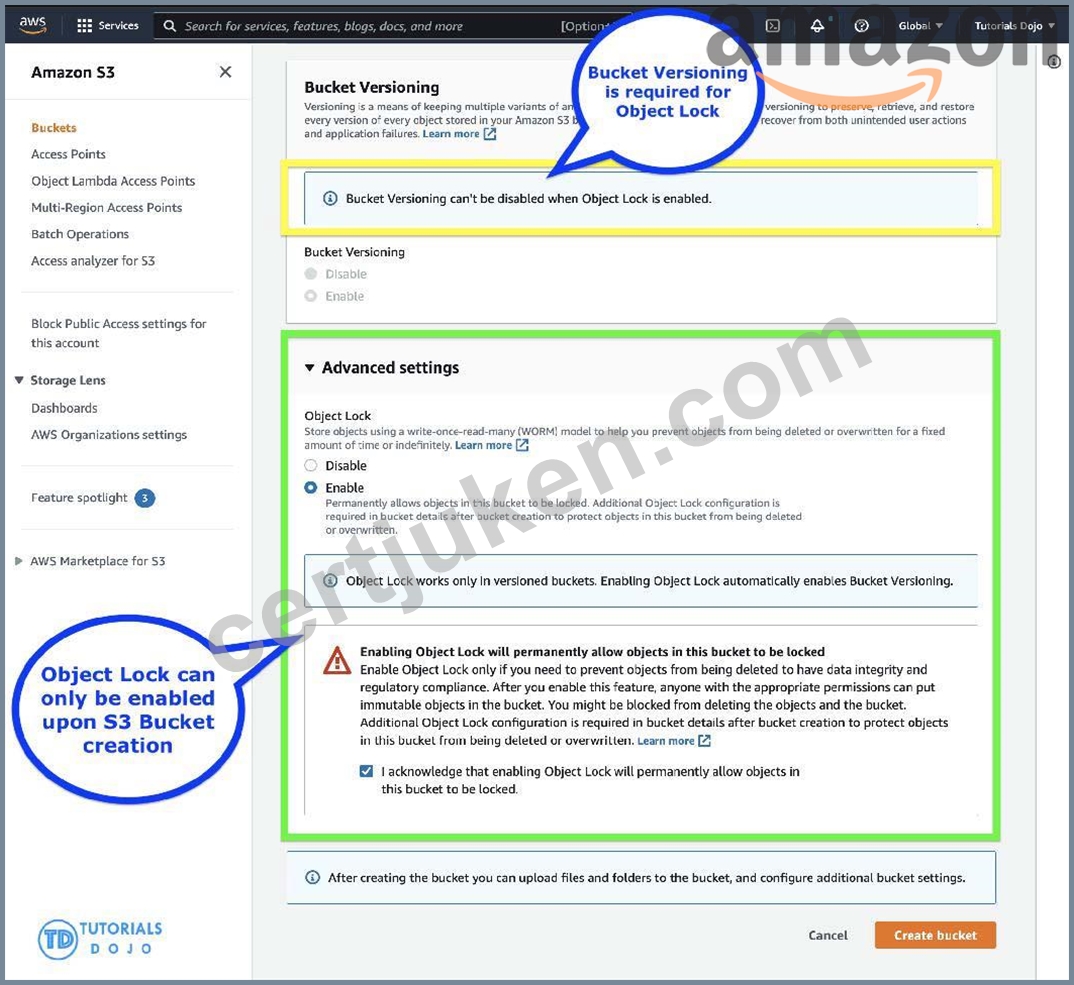
Before you lock any objects, you have to enable a bucket to use S3 Object Lock. You enable Object Lock when you create a bucket. After you enable Object Lock on a bucket, you can lock objects in that bucket. When you create a bucket with Object Lock enabled, you can't disable Object Lock or suspend versioning for that bucket.
Hence, the correct answers are:
- Configure an Amazon S3 Access Point for the S3 bucket to restrict data access to a particular Amazon VPC only.
- Create a new Amazon S3 bucket with the S3 Object Lock feature enabled. Store the documents in the bucket and set the Legal Hold option for object retention.
The option that says: Set up a new Amazon S3 bucket to store the tax documents and integrate it with AWS Network Firewall. Configure the Network Firewall to only accept data access requests from a specific Amazon VPC is incorrect because you cannot directly use an AWS Network Firewall to restrict S3 bucket data access requests to a specific Amazon VPC only. You have to use an Amazon S3 Access Point instead for this particular use case. An AWS Network Firewall is commonly integrated to your Amazon VPC and not to an S3 bucket.
The option that says: Store the tax documents in the Amazon S3 Glacier Instant Retrieval storage class to restrict fast data retrieval to a particular Amazon VPC of your choice is incorrect because Amazon S3 Glacier Instant Retrieval is just an archive storage class that delivers the lowest-cost storage for long- lived data that is rarely accessed and requires retrieval in milliseconds. It neither provides write-once- read-many (WORM) storage nor a fine-grained network control that restricts S3 bucket access to a specific Amazon VPC.
The option that says: Enable Object Lock but disable Object Versioning on the new Amazon S3 bucket to comply with the write-once-read-many (WORM) storage model requirement is incorrect. Although the Object Lock feature does provide write-once-read-many (WORM) storage, the Object Versioning feature must also be enabled too in order for this to work. In fact, you cannot manually disable the Object Versioning feature if you have already selected the Object Lock option. References:
https://docs.aws.amazon.com/AmazonS3/latest/userguide/access-points.html
https://docs.aws.amazon.com/AmazonS3/latest/userguide/object-lock.html
Check out this Amazon S3 Cheat Sheet:
https://tutorialsdojo.com/amazon-s3/
質問 # 967
A company is building a serverless application to process orders from an e-commerce site. The application needs to handle bursts of traffic during peak usage hours and to maintain high availability. The orders must be processed asynchronously in the order the application receives them. Which solution will meet this requirement?
正解:C
解説:
Key Requirements:
Serverless architecture.
Handle traffic bursts with high availability.
Process orders asynchronouslyin the order they are received.
Analysis of Options:
Option A: Amazon SNS delivers messages to subscribers. However, SNS does not ensure ordering, making it unsuitable for FIFO (First In, First Out) requirements.
Option B: Amazon SQS FIFO queues support ordering and ensure messages are delivered exactly once. AWS Lambda functions can be triggered by SQS to process messages asynchronously and efficiently. This satisfies all requirements.
Option C: Amazon SQS standard queues do not guarantee message order and have "at-least- once" delivery, making them unsuitable for the FIFO requirement.
Option D: Similar to Option A, SNS does not ensure message ordering, and using AWS Batch adds complexity without directly addressing the requirements.
質問 # 968
A company is looking for a way to analyze the calls between customers and service agents. Each conversation is transcribed, JSON-formatted, and saved to an Amazon S3 bucket. The company's solutions architect is tasked to design a solution for extracting and visualizing sentiments from the transcribed files.
Which solution meets the requirements while minimizing the amount of operational overhead?
正解:D
解説:
Amazon Comprehend uses machine learning to help you uncover the insights and relationships in your unstructured data. The service identifies the language of the text; extracts key phrases, places, people, brands, or events; understands how positive or negative the text is; analyzes text using tokenization and parts of speech, and automatically organizes a collection of text files by topic. You can also use AutoML capabilities in Amazon Comprehend to build a custom set of entities or text classification models that are tailored uniquely to your organization's needs.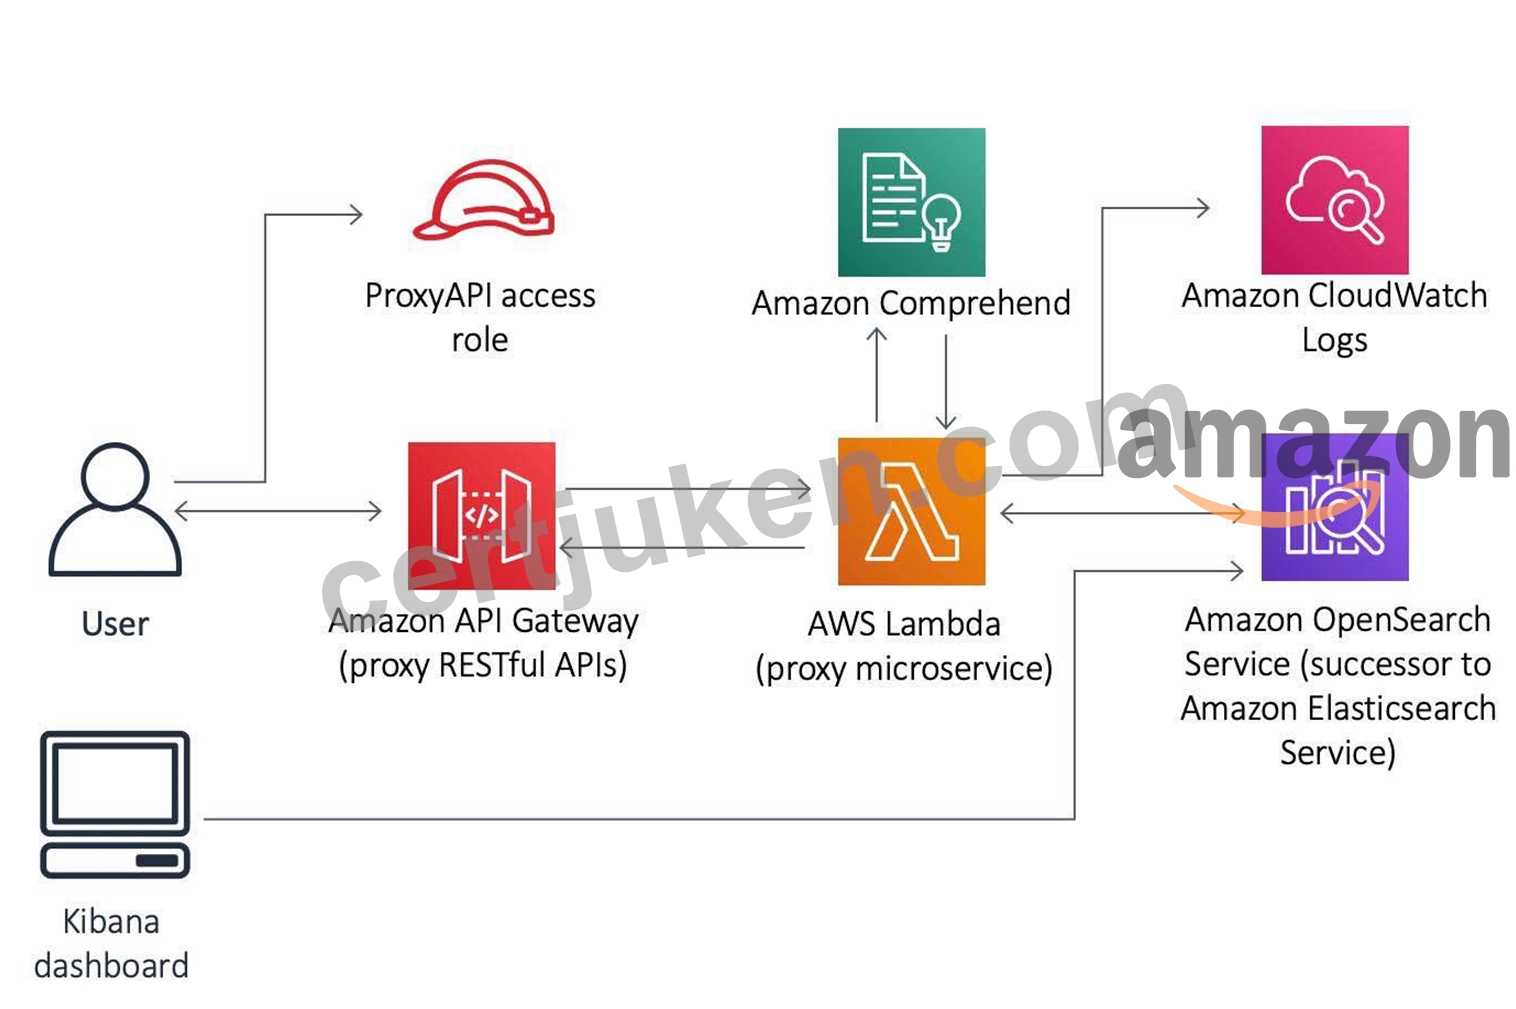
In this scenario, you can build the application with the help of Amazon Comprehend. You could expose the application through a RESTful endpoint, have it invoke a Lambda function that will call Amazon Comprehend for sentiment analysis, and index data into an Amazon OpenSearch cluster.
Hence, the correct answer is: Create an Amazon Comprehend analysis job. Index the sentiment along with the transcript to an Amazon OpenSearch cluster. Visualize the results using the OpenSearch Dashboard.
The option that says: Analyze the JSON files with Amazon Textract. Index the sentiment along with the transcript to an Amazon OpenSearch cluster. Visualize the results using Amazon Managed Grafana is incorrect. Amazon Textract is just an AI service used to extract text data from scanned documents in PNG, JPEG, TIFF, PDF formats and is not capable of running sentiment analysis. Furthermore, Grafana is more suited for the visualization of time-series data such as system metrics (CPU load, disk storage, memory utilization, temperature, etc). While there are hacks you can use to visualize non-time series like the one in the scenario, they come with additional overhead on your part. The built-in OpenSearch dashboard is enough to do the job.
The option that says: Create an Amazon Comprehend analysis job. Index the sentiment along with the transcript to an Amazon OpenSearch cluster. Visualize the results using Amazon Managed Grafana is incorrect. The Amazon OpenSearch dashboard is a more suitable service to use than Grafana since the sentiment data is already processed by an Amazon OpenSearch cluster. This solution needs a separate AWS data source configuration in the Grafana workspace console to integrate and read the sentiment data, which entails an additional operational overhead.
The option that says: Train a custom Natural Language Processing (NLP) model using Amazon SageMaker. Index the sentiment along with the transcript to an Amazon OpenSearch cluster. Visualize the results using the Amazon QuickSight Dashboard is incorrect. Although this may be a viable option, training your own ML model rather than using the readily available Amazon Comprehend service requires more time and effort. The same is true in using the Amazon QuickSight dashboard instead of the OpenSearch Dashboard. It takes a lot of steps to properly integrate Amazon QuickSight and an OpenSearch cluster which might cause delays in the project implementation.
References:
https://aws.amazon.com/solutions/implementations/text-analysis-with-amazon-opensearch-service-and-a mazon-comprehend/
https://docs.aws.amazon.com/opensearch-service/latest/developerguide/walkthrough.html#walkthrough- analysis Check out this Amazon Comprehend Cheat Sheet:
https://tutorialsdojo.com/amazon-comprehend/
質問 # 969
A company is moving its data management application to AWS. The company wants to transition to an event- driven architecture. The architecture needs to the more distributed and to use serverless concepts whit performing the different aspects of the workflow. The company also wants to minimize operational overhead.
Which solution will meet these requirements?
正解:C
解説:
This answer is correct because it meets the requirements of transitioning to an event-driven architecture, using serverless concepts, and minimizing operational overhead. AWS Step Functions is a serverless service that lets you coordinate multiple AWS services into workflows using state machines. State machines are composed of tasks and transitions that define the logic and order of execution of the workflow steps. AWS Lambda is a serverless function-as-a-service platform that lets you run code without provisioning or managing servers. Lambda functions can be invoked by Step Functions as tasks in a state machine, and can perform different aspects of the data management workflow, such as data ingestion, transformation, validation, and analysis. By using Step Functions and Lambda, the company can benefit from the following advantages:
* Event-driven: Step Functions can trigger Lambda functions based on events, such as timers, API calls, or other AWS service events. Lambda functions can also emit events to other services or state machines, creating an event-driven architecture.
* Serverless: Step Functions and Lambda are fully managed by AWS, so the company does not need to provision or manage any servers or infrastructure. The company only pays for the resources consumed by the workflows and functions, and can scale up or down automatically based on demand.
* Operational overhead: Step Functions and Lambda simplify the development and deployment of workflows and functions, as they provide built-in features such as monitoring, logging, tracing, error handling, retry logic, and security. The company can focus on the business logic and data processing rather than the operational details.
References:
* What is AWS Step Functions?
* What is AWS Lambda?
質問 # 970
......
ご存知のように、CertJukenオフィスワーカーは試験の準備をする時間がほとんどありません。 被験者の貴重な休息時間を無駄にするのは苦痛です。 ただし、AmazonのSAA-C03の練習資料がある場合は、状況が異なります。 SAA-C03学習教材には、主要なコア知識が含まれているだけでなく、分散時間を使用して学習できるため、より簡単に学習して乗数効果を得ることができます。 また、SAA-C03試験の質問で20〜30時間学習した後、AWS Certified Solutions Architect - AssociateのSAA-C03試験に確実に合格することができます。
SAA-C03合格率: https://www.certjuken.com/SAA-C03-exam.html
P.S.CertJukenがGoogle Driveで共有している無料の2026 Amazon SAA-C03ダンプ:https://drive.google.com/open?id=1TxFMQ9BnAWNCCOiFKlBmtjfTnwTalXSE