DOWNLOAD the newest PrepAwayTest Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BpqzRwbcNKuk-T5qCWbsGKQjvIIo3vBz
The Databricks Databricks-Certified-Data-Engineer-Associate practice exam software will provide you with feedback on your performance. The Databricks Databricks-Certified-Data-Engineer-Associate practice test software also includes a built-in timer and score tracker so students can monitor their progress. Databricks-Certified-Data-Engineer-Associate Practice Exam enables applicants to practice time management, answer strategies, and all other elements of the final Databricks Databricks-Certified-Data-Engineer-Associate certification exam and can check their scores.
The Databricks Certified Data Engineer Associate Exam certification exam consists of 60 multiple-choice questions that need to be answered within 90 minutes. Databricks-Certified-Data-Engineer-Associate exam is available in English and is delivered online through the GAQM testing platform. Databricks Certified Data Engineer Associate Exam certification exam is open to all individuals who are interested in data engineering and Databricks, regardless of their educational background.
The Databricks Databricks-Certified-Data-Engineer-Associate Exam is intended for data engineers, data architects, and developers who are responsible for designing, building, and maintaining data pipelines. Databricks Certified Data Engineer Associate Exam certification exam is comprised of 60 multiple-choice questions, and candidates have 90 minutes to complete the exam. Databricks-Certified-Data-Engineer-Associate exam measures candidates' knowledge and skills in various areas, including data ingestion, data transformation, and data processing.
>> Databricks-Certified-Data-Engineer-Associate New Question <<
Competition has a catalytic effect on human development and social progress. Competition will give us direct goals that can inspire our potential and give us a lot of pressure. We must translate these pressures into motivation for progress. This road may not be easy to go. But with our Databricks-Certified-Data-Engineer-Associate Exam Questions, you can be the most competitive genius in your field with the least time and efforts. As long as you follow with our Databricks-Certified-Data-Engineer-Associate study guide, you will succeed for sure. Just come and try our Databricks-Certified-Data-Engineer-Associate practice braindumps!
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) certification exam is an excellent opportunity for data professionals to validate their skills in designing, building, and maintaining data pipelines using Databricks. Databricks Certified Data Engineer Associate Exam certification exam covers a wide range of topics and is designed to test the candidate's knowledge of data engineering fundamentals, Databricks architecture, data modeling, and data processing. Passing the certification exam provides an individual with a globally recognized certification that can enhance their career prospects in the data engineering field.
NEW QUESTION # 159
A team creates YAML manifests that declare jobs, resources, and dependencies, then deploys them to Databricks using the Databricks CLI. The deployment succeeds.
Which feature are they using?
Answer: B
Explanation:
Databricks Asset Bundles are a Databricks CLI feature that lets teams define Databricks projects "as code" using YAML configuration files. In a bundle, metadata is expressed in YAML (for example, a required databricks.yml at the root), and the configuration can declare resources (such as Databricks Jobs/workflows and other supported assets), artifacts, and deployment targets. After defining these YAML manifests, teams use the Databricks CLI to validate, deploy, and run the bundle into a Databricks workspace, which matches the scenario described (YAML + CLI deployment). This approach standardizes how workflows and related resources are packaged and promoted across environments (dev/test/prod) while keeping definitions version-controlled and reproducible. GitHub is only a hosting/version-control platform (not the YAML deployment feature itself), Terraform is a separate IaC tool, and "DataOps" is a methodology rather than a specific Databricks feature. (Databricks Documentation)
NEW QUESTION # 160
An organization needs to share a dataset stored in its Databricks Unity Catalog with an external partner who uses a different data platform that is not Databricks. The goal is to maintain data security and ensure the partner can access the data efficiently. Which method should the data engineer use to securely share the dataset with the external partner?
Answer: C
Explanation:
Delta Sharing with the open sharing protocol allows secure data sharing from Unity Catalog to external partners, even if they are not using Databricks, while maintaining governance and efficient access.
NEW QUESTION # 161
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
Answer: A
Explanation:
JSON data is a text-based format that represents data as a collection of name-value pairs. By default, when Auto Loader infers the schema of JSON data, it treats all columns as strings. This is because JSON data can have varying data types for the same column across different files or records, and Auto Loader does not attempt to reconcile these differences. For example, a column named "age" may have integer values in some files, but string values in others. To avoid data loss or errors, Auto Loader infers the column as a string type.
However, Auto Loader also provides an option to infer more precise column types based on the sample data.
This option is called cloudFiles.inferColumnTypes and it can be set to true or false. When set to true, Auto Loader tries to infer the exact data types of the columns, such as integers, floats, booleans, or nested structures. When set to false, Auto Loader infers all columns as strings. The default value of this option is false. References: Configure schema inference and evolution in Auto Loader, Schema inference with auto loader (non-DLT and DLT), Using and Abusing Auto Loader's Inferred Schema, Explicit path to data or a defined schema required for Auto loader.
NEW QUESTION # 162
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. The data engineer wants to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing.
Which role must be in place to perform these actions across the metastore?
Answer: D
Explanation:
In Unity Catalog, the Metastore Admin role has the highest level of authority within a metastore and is responsible for governing all data assets registered in that metastore. Metastore admins can transfer ownership of catalogs, manage privileges across all securable objects (catalogs, schemas, tables, views), and administer storage credentials, external locations, and Delta Sharing objects such as shares and recipients. This makes the role essential when a platform owner departs and continuity must be maintained at an organizational level. Workspace admins (option B) manage workspace-level settings but do not automatically have authority over Unity Catalog ownership unless explicitly granted. Catalog owners (option D) are limited to a single catalog and cannot perform actions across the entire metastore. Account admins (option A) operate at the account level and are primarily responsible for creating metastores and assigning admins, not for day-to-day governance within an existing metastore. Databricks documentation clearly defines the Metastore Admin as the role required to centrally manage ownership, privileges, and data sharing across the metastore in Databricks.
NEW QUESTION # 163
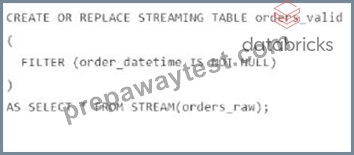
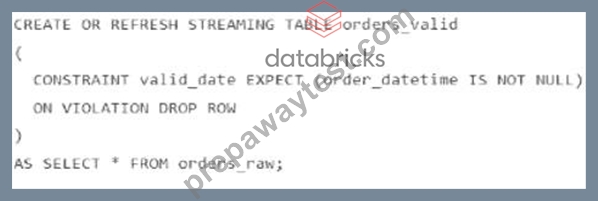
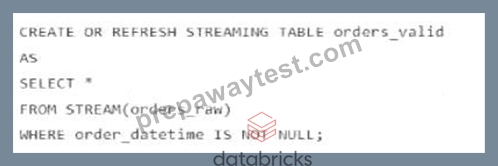
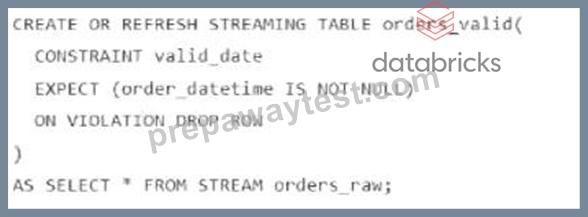
A data engineer is processing ingested streaming tables and needs to filter out NULL values in the order_datetime column from the raw streaming table orders_raw and store the results in a new table orders_valid using DLT.
Which code snippet should the data engineer use?
Answer: C
NEW QUESTION # 164
......
Databricks-Certified-Data-Engineer-Associate PDF Cram Exam: https://www.prepawaytest.com/Databricks/Databricks-Certified-Data-Engineer-Associate-practice-exam-dumps.html
BONUS!!! Download part of PrepAwayTest Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1BpqzRwbcNKuk-T5qCWbsGKQjvIIo3vBz