What's more, part of that Exam4Labs Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1MCvZxbqA-7FHRbpwbWYKHNue2M7Kgq9l
Our Google Professional-Machine-Learning-Engineer practice exam simulator mirrors the Professional-Machine-Learning-Engineer exam experience, so you know what to anticipate on Professional-Machine-Learning-Engineer certification exam day. Our Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice test software features various question styles and levels, so you can customize your Google Professional-Machine-Learning-Engineer exam questions preparation to meet your needs.
| Section | Objectives |
|---|---|
| Topic 1: Deployment and operations | - Monitoring and maintenance
|
| Topic 2: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 3: Designing ML solutions | - Framing ML problems
|
| Topic 4: ML model development | - Evaluation
|
| Topic 5: ML pipeline automation and orchestration | - Pipeline design
|
>> Professional-Machine-Learning-Engineer Vce Files <<
Keeping in mind all these benefits, we ensure you can pass the Google Professional Machine Learning Engineer Professional-Machine-Learning-Engineer exam on your maiden attempt with the help of our exceptional Google Professional-Machine-Learning-Engineer dumps material. Our dedicated and committed team takes feedback from over 90,000 experts worldwide in the Google Professional-Machine-Learning-Engineer Dumps field to update our product.
NEW QUESTION # 206
A Data Scientist is developing a machine learning model to classify whether a financial transaction is fraudulent. The labeled data available for training consists of 100,000 non-fraudulent observations and 1,000 fraudulent observations.
The Data Scientist applies the XGBoost algorithm to the data, resulting in the following confusion matrix when the trained model is applied to a previously unseen validation dataset. The accuracy of the model is 99.1%, but the Data Scientist has been asked to reduce the number of false negatives.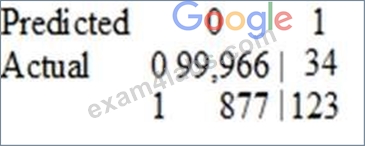
Which combination of steps should the Data Scientist take to reduce the number of false positive predictions by the model? (Choose two.)
Answer: A,E
NEW QUESTION # 207
You recently joined an enterprise-scale company that has thousands of datasets. You know that there are accurate descriptions for each table in BigQuery, and you are searching for the proper BigQuery table to use for a model you are building on AI Platform. How should you find the data that you need?
Answer: C
Explanation:
Data Catalog is a fully managed and scalable metadata management service that allows you to quickly discover, manage, and understand your data in Google Cloud. You can use Data Catalog to search the BigQuery datasets by using keywords in the table description, as well as other metadata attributes such as table name, column name, labels, tags, and more. Data Catalog also provides a rich browsing experience that lets you explore the schema, preview the data, and access the BigQuery console directly from the Data Catalog UI. Data Catalog helps you find the data that you need for your model building on AI Platform without writing any code or queries.
References:
* [Data Catalog documentation]
* [Data Catalog overview]
* [Searching for data assets]
NEW QUESTION # 208
You work for a biotech startup that is experimenting with deep learning ML models based on properties of biological organisms. Your team frequently works on early-stage experiments with new architectures of ML models, and writes custom TensorFlow ops in C++. You train your models on large datasets and large batch sizes. Your typical batch size has 1024 examples, and each example is about 1 MB in size. The average size of a network with all weights and embeddings is 20 GB. What hardware should you choose for your models?
Answer: B
Explanation:
The best hardware to choose for your models is a cluster with 2 a2-megagpu-16g machines, each with 16 NVIDIA Tesla A100 GPUs (640 GB GPU memory in total), 96 vCPUs, and 1.4 TB RAM. This hardware configuration can provide you with enough compute power, memory, and bandwidth to handle your large and complex deep learning models, as well as your custom TensorFlow ops in C++. The NVIDIA Tesla A100 GPUs are the latest and most advanced GPUs from NVIDIA, which offer high performance, scalability, and efficiency for various ML workloads. They also support multi-instance GPU (MIG) technology, which allows you to partition each GPU into up to seven smaller instances, each with its own memory, cache, and compute cores. This can enable you to run multiple experiments in parallel, or to optimize the resource utilization and cost efficiency of your models. The a2-megagpu-16g machines are part of the Google Cloud Accelerator- Optimized VM (A2) family, which are designed to provide the best performance and flexibility for GPU- intensive applications. They also offer high-speed NVLink interconnects between the GPUs, which can improve the data transfer and communication between the GPUs. Moreover, the a2-megagpu-16g machines have 96 vCPUs and 1.4 TB RAM, which can support the CPU and memory requirements of your models, as well as the data preprocessing and postprocessing tasks.
The other options are not optimal for the following reasons:
* A. A cluster with 2 n1-highcpu-64 machines, each with 8 NVIDIA Tesla V100 GPUs (128 GB GPU memory in total), and a n1-highcpu-64 machine with 64 vCPUs and 58 GB RAM is not a good option, as it has less GPU memory, compute power, and bandwidth than the a2-megagpu-16g machines. The NVIDIA Tesla V100 GPUs are the previous generation of GPUs from NVIDIA, which have lower performance, scalability, and efficiency than the NVIDIA Tesla A100 GPUs. They also do not support the MIG technology, which can limit the flexibility and optimization of your models. Moreover, the n1- highcpu-64 machines are part of the Google Cloud N1 VM family, which are general-purpose VMs that do not offer the best performance and features for GPU-intensive applications. They also have lower vCPUs and RAM than the a2-megagpu-16g machines, which can affect the CPU and memory requirements of your models, as well as the data preprocessing and postprocessing tasks.
* C. A cluster with an n1-highcpu-64 machine with a v2-8 TPU and 64 GB RAM is not a good option, as it has less GPU memory, compute power, and bandwidth than the a2-megagpu-16g machines. The v2-8 TPU is a cloud tensor processing unit (TPU) device, which is a custom ASIC chip designed by Google to accelerate ML workloads. However, the v2-8 TPU is the second generation of TPUs, which have lower performance, scalability, and efficiency than the latest v3-8 TPUs. They also have less memory and bandwidth than the NVIDIA Tesla A100 GPUs, which can limit the size and complexity of your models, as well as the data transfer and communication between the devices. Moreover, the n1-highcpu-
64 machine has lower vCPUs and RAM than the a2-megagpu-16g machines, which can affect the CPU and memory requirements of your models, as well as the data preprocessing and postprocessing tasks.
* D. A cluster with 4 n1-highcpu-96 machines, each with 96 vCPUs and 86 GB RAM is not a good option, as it does not have any GPUs, which are essential for accelerating deep learning models. The n1- highcpu-96 machines are part of the Google Cloud N1 VM family, which are general-purpose VMs that do not offer the best performance and features for GPU-intensive applications. They also have lower RAM than the a2-megagpu-16g machines, which can affect the memory requirements of your models, as well as the data preprocessing and postprocessing tasks.
:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud launches machine learning engineer certification NVIDIA Tesla A100 GPU Google Cloud Accelerator-Optimized VM (A2) family Google Cloud N1 VM family Cloud TPU
NEW QUESTION # 209
The displayed graph is from a forecasting model for testing a time series.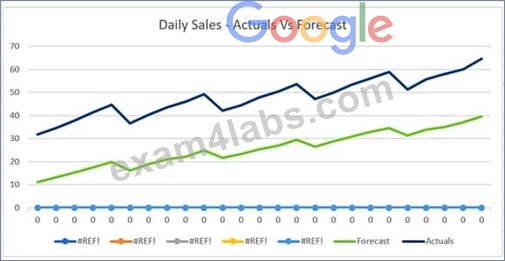
Considering the graph only, which conclusion should a Machine Learning Specialist make about the behavior of the model?
Answer: B
NEW QUESTION # 210
You work for a company that builds bridges for cities around the world. To track the progress of projects at construction sites, your company has set up cameras at each location. Each hour, the cameras take a picture that is sent to a Cloud Storage bucket. A team of specialists reviews the images, filters important ones, and then annotates unique specialized construction equipment in the images. You want to propose an ML solution that will help the company scale and reduce costs for this process. You need the solution to have minimal up-front cost. What method should you propose?
Answer: A
NEW QUESTION # 211
......
Two Professional-Machine-Learning-Engineer practice tests of Exam4Labs (desktop and web-based) create an actual test scenario and give you a Professional-Machine-Learning-Engineer real exam feeling. These Professional-Machine-Learning-Engineer practice tests also help you gauge your Google Certification Exams preparation and identify areas where improvements are necessary. You can alter the duration and quantity of Google Professional-Machine-Learning-Engineer Questions in these Professional-Machine-Learning-Engineer practice exams as per your training needs.
Reliable Professional-Machine-Learning-Engineer Test Sims: https://www.exam4labs.com/Professional-Machine-Learning-Engineer-practice-torrent.html
2026 Latest Exam4Labs Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1MCvZxbqA-7FHRbpwbWYKHNue2M7Kgq9l