P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=1noZ4HVKdIE0Lecl24vfigwpOoLyrJHq3
If you want to buy our SPS-C01 study guide in a preferential price, that’s completely possible. In order to give back to the society, our company will prepare a number of coupons on our official website. Once you enter into our websites, the coupons will be very conspicuous. Remember to write down your accounts and click the coupon. When you pay for our SPS-C01 Training Material, the coupon will save you lots of money. The number of our free coupon is limited. So you should click our website frequently. What’s more, our coupon has an expiry date. You must use it before the deadline day. What are you waiting for? Come to buy our SPS-C01 practice test in a cheap price.
| Section | Weight | Objectives |
|---|---|---|
| Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Minimizing data transfer - Query pushdown and optimization - Debugging and explain plans - Warehouse sizing for Snowpark - Caching strategies |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark architecture and core concepts - Stored procedures and conditional logic - Snowpark Sessions and connection management |
| Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Using built-in functions - Window functions - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames |
| Snowpark API for Python | 30% | - DataFrame creation and manipulation - Establishing connections and session management - Working with Semi-structured data - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures |
>> SPS-C01 Latest Exam Registration <<
This is a crucial part of your study to know your mistakes and overcome them before the Snowflake SPS-C01 final test. Customizable test sessions allow you to modify the setting of the SPS-C01 mock test according to your training needs. Both Snowflake SPS-C01 Practice Tests desktop and web-based create a scenario that gives an exact feeling of the Snowflake SPS-C01 real test.
NEW QUESTION # 330
You are working with a Snowpark DataFrame containing customer data'. One of the columns, 'phone number', contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize all phone numbers to the format '+1-123-456-7890' using Snowpark for Python. You also want to handle cases where the phone number is NULL gracefully, replacing them with '+1-000-000-0000'. Which of the following Snowpark code snippets is the most efficient and correct way to achieve this?
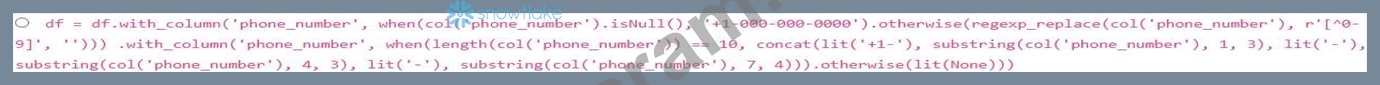




Answer: A
Explanation:
Option C is the most efficient because it uses built-in Snowpark functions (when, regexp_replace, substring, concat, length, and lit) to perform the transformation directly on the server-side. It first handles NULL values. It then removes non-numeric characters. Finally, it checks the length of the remaining digits before formatting, ensuring only valid 10-digit numbers are transformed, setting others to NULL. Options A, D, and E do not handle the case where after removing non-numeric characters, the length of phone number is not 10. Option B uses a UDF, which is generally less efficient than using built-in functions as it involves serialization/deserialization overhead .
NEW QUESTION # 331
You're using Snowpark in Python and need to execute a complex SQL query. The query involves several joins and aggregations, and you want to optimize its performance. You are using "session.sql(query)' to execute the query. Which of the following strategies, applied before executing 'session.sql(query)' , would likely lead to the most significant performance improvement for a very large dataset?
Answer: B
Explanation:
Option A provides the most significant improvement because Snowpark DataFrame operations allow Snowflake's query optimizer to leverage pushdown optimizations. When you express your logic as DataFrame operations, Snowpark translates these into SQL that is specifically tailored for Snowflake's engine. This gives Snowflake more control over the execution plan compared to simply passing in a pre-written SQL query via 'session.sql(queryy. DataFrame operations allow the query optimizer to push down operations such as filters and aggregations to the data source, significantly reducing the amount of data transferred and processed. Option B is incorrect because comments only improve readability, not performance. Option C, , can help if the DataFrame is used multiple times, but it doesn't address the initial optimization of the query itself. Option D could help, but converting to DataFrame operations provides more comprehensive optimization. Option E can assist, but often DataFrame creation and optimal query plan generation can be better using Option A.
NEW QUESTION # 332
Consider the following Snowpark Python code snippet designed to create a DataFrame and then register a custom function (UDF):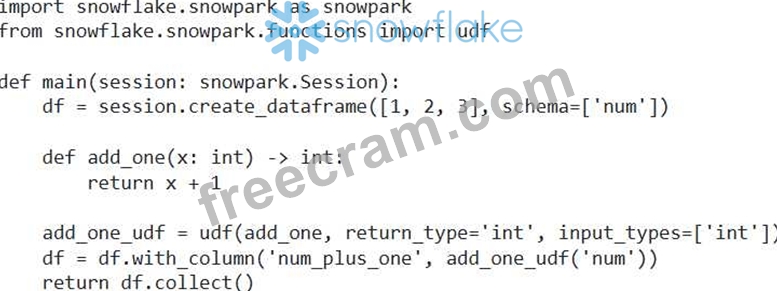
This code runs successfully. However, you need to deploy this as a stored procedure. What minimal changes are required to make this code runnable as a Snowpark Python stored procedure and callable from SQL?
Answer: E
Explanation:
When deploying as a stored procedure, 'return will cause an error since stored procedures cannot return Snowpark DataFrames directly to SQL. You need to return the DataFrame to pandas using 'return and remove 'return_type' and 'input_types' arguments of udf to allow inference.
NEW QUESTION # 333
You have a Snowpark Python application that reads data from a Snowflake table named 'SALES DATA', performs several transformations using DataFrames, and then writes the results back to a new table named 'AGGREGATED SALES'. The application runs successfully, but you notice that the write operation to 'AGGREGATED SALES' is consistently slow. After examining the query profile, you observe significant skew in the data being written, causing some worker nodes to be overloaded. Which of the following techniques could you use within your Snowpark application to mitigate the data skew and improve the write performance to 'AGGREGATED SALES'?
Answer: C,D
Explanation:
Both options B and D address data skew directly. Option B, , attempts to redistribute data evenly, which can alleviate skew if the repartitioning strategy is effective (e.g., using a hash function). Option D, using a UDF and 'repartitionByRange' , allows for more sophisticated custom partitioning based on the skew key, potentially achieving a more balanced distribution. Increasing warehouse size (A) might provide more resources, but it doesn't directly address the skew. Sorting (C) can exacerbate skew by concentrating similar values on single nodes. Clustering (E) improves read performance after the data is written, but does not improve the write performance itself. Therefore, B and D are the best choices to reduce skew during the write operation.
NEW QUESTION # 334
You are tasked with creating a secure UDF in Snowflake using Snowpark Python API that encrypts sensitive customer data before storing it. The UDF should be accessible only to users with specific roles. You have the following code snippet. What needs to be done to make it secure and operationalize for multiple users?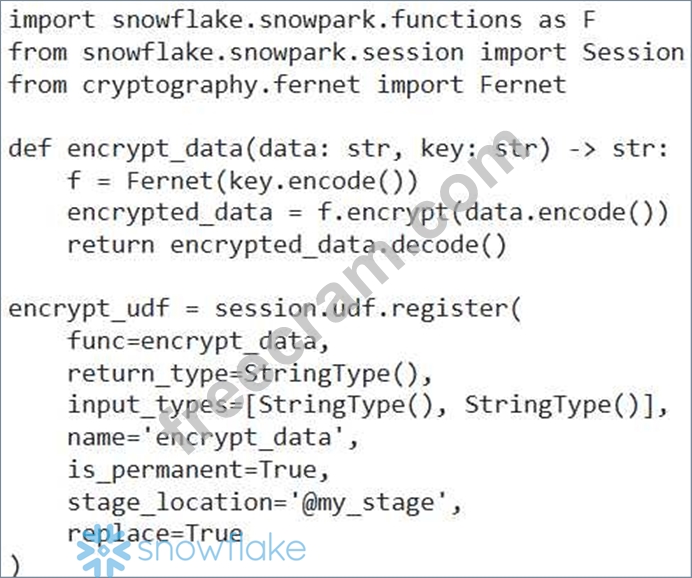
Considering Security best practices, what steps are critical for securing the UDF and granting appropriate permissions to other users?
Answer: C,D
Explanation:
Storing the encryption key directly in the UDF code is a major security vulnerability. Snowflake's Secret object provides a secure way to store and manage sensitive information like encryption keys. Granting EXECUTE privilege on the UDF and USAGE privilege on the database and schema is essential for allowing authorized users to execute the UDF. USAGE privilege on the database and schema allows users to 'see' the UDF. Option C is incorrect because granting global USAGE privilege on the stage location is overly permissive. Option E is incorrect as bypassing role-based access control is insecure.
NEW QUESTION # 335
......
Taking the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 test and beginning Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 exam preparation with the suggested SPS-C01 exam preparation materials is the best and quickest course of action. You can rely on Snowflake SPS-C01 Exam Questio Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 for thorough SPS-C01 exam preparation.
SPS-C01 Exam Demo: https://www.freecram.com/Snowflake-certification/SPS-C01-exam-dumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=1noZ4HVKdIE0Lecl24vfigwpOoLyrJHq3