If you buy the DP-750 study materials online, you may concern the safety of your money. If you do have the concern, you can just choose us. We use the international recognition third party for the payment. It will ensure the safety of your money. We are pass guaranteed if you buy DP-750 Exam Dumps of us, we also money back guarantee if you fail to pass the exam. If you find that your rights haven’t got enough guaranteed, you can ask for refund, and the third party will protect your interests.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 4: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
This is similar to the DP-750 desktop format but this is browser-based. It requires an active internet connection to run and is compatible with all browsers such as Google Chrome, Mozilla Firefox, Opera, MS Edge, Safari, Internet Explorer, and others. The Microsoft DP-750 Mock Exam helps you self-evaluate your Implementing Data Engineering Solutions Using Azure Databricks exam preparation and mistakes. This way you improve consistently and attempt the DP-750 certification exam in an optimal way for excellent results in the exam.
NEW QUESTION # 91
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: B
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 92
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
The File arrival trigger is exactly what you need for this use case. It natively solves your problem by launching a job the moment new files land in your Azure Storage container, automatically scaling down to zero compute when no data is processing.
Event-Driven: Instead of relying on a time-based schedule (cron) that wastes resources, the Lakeflow Job monitors the specific Azure location and starts exactly when new data appears.
Zero Idle Compute: You can use serverless compute or an ephemeral job cluster that spins up just for the duration of the run and terminates immediately after, meaning zero billing during downtime.
Cloud Cost Efficient: Listing files to detect new arrivals is typically free or fractions of a cent (only incurring minimal cloud provider API costs for listing the storage location).
Reference:
https://learn.microsoft.com/en-us/azure/databricks/jobs/file-arrival-triggers
NEW QUESTION # 93
A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?
Answer: A
Explanation:
Auto Loader supports schema inference and schema evolution, allowing new columns to be added automatically during ingestion. This reduces pipeline maintenance and avoids failures due to schema drift. Disabling enforcement is unsafe and risks data corruption. Overwrite mode deletes existing data. Manual updates are not scalable.
NEW QUESTION # 94
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.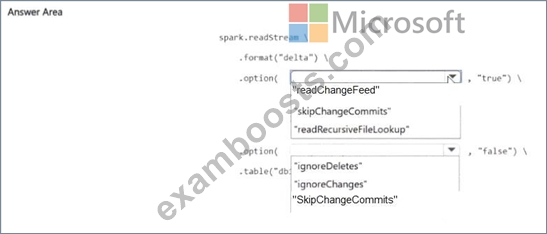
Answer:
Explanation: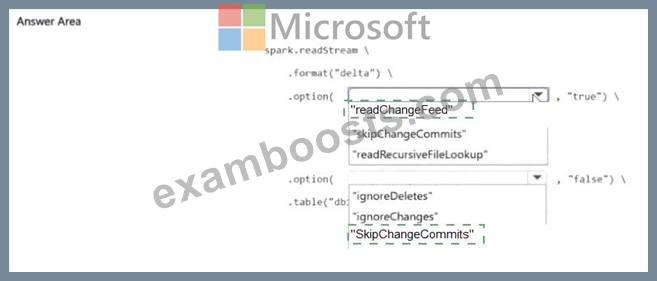
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 95
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
NEW QUESTION # 96
......
The best way for candidates to know our Microsoft DP-750 training dumps is downloading our free demo. We provide free PDF demo for each exam. This free demo is a small part of the official complete Implementing Data Engineering Solutions Using Azure Databricks DP-750 training dumps. The free demo can show you the quality of our exam materials. You can download any time before purchasing.
DP-750 Latest Dumps Book: https://www.examboosts.com/Microsoft/DP-750-practice-exam-dumps.html