P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=12iESO6EeylKMHaQ3-WKJpjly2mMNdIed
When you are studying for the DP-100 exam, maybe you are busy to go to work, for your family and so on. How to cost the less time to reach the goal? It’s a critical question for you. Time is precious for everyone to do the efficient job. If you want to get good DP-100 prep guide, it must be spending less time to pass it. Exactly, our product is elaborately composed with major questions and answers. We are choosing the key from past materials to finish our DP-100 Guide Torrent. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the DP-100 exam torrent. Then, you will have enough confidence to pass it.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Passing Score: | 700/1000 |
| Certificate Validity Period: | 1 year |
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
| Exam Price: | $165 USD |
| Exam Format: | Multiple Choice, Drag and Drop, Case Study, Lab, Interactive Tasks |
| Available Languages: | Portuguese, Chinese (Simplified), English, German, Spanish, Korean, French, Japanese |
| Exam Duration: | 100 minutes |
| Real Exam Qty: | 40-60 |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored exam or test center delivery through Pearson VUE. |
| Pre Condition: | Candidates should have experience with Azure services, Python programming, and machine learning frameworks such as Scikit-Learn, PyTorch, or TensorFlow. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-100/ |
>> Reliable DP-100 Test Guide <<
Considering many exam candidates are in a state of anguished mood to prepare for the DP-100 exam, our company made three versions of DP-100 real exam materials to offer help. All these variants due to our customer-oriented tenets. As a responsible company over ten years, we are trustworthy. In the competitive economy, this company cannot remain in the business for long. But we keep being the leading position in contrast. We are reactive to your concerns and also proactive to new trends happened in this DP-100 Exam.
Microsoft provides you with the elaborate outline of the skills that you need to acquire before attempting the test. The specific topics of the exam along with the main subtopics are enumerated below:
The skills measured within this topic include selecting an algorithmic approach; evaluating model performance; training the model; identifying data imbalances; splitting datasets, and so on.
This subject area revolves around cleansing and transforming data; performing EDA (Exploratory Data Analysis); transforming data into usable datasets.
Answering the questions that are drawn from this domain, the test takers should be able to perform the tasks such as performing feature selection as well as performing feature extraction.
To answer the questions within this objective, the applicants should have the professional ability to accomplish such technical tasks as selecting a development environment; quantifying the business problem; setting up a development environment; etc.
NEW QUESTION # 500
You are a data scientist building a deep convolutional neural network (CNN) for image classification.
The CNN model you build shows signs of overfitting.
You need to reduce overfitting and converge the model to an optimal fit.
Which two actions should you perform? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
B: Weight regularization provides an approach to reduce the overfitting of a deep learning neural network model on the training data and improve the performance of the model on new data, such as the holdout test set.
Keras provides a weight regularization API that allows you to add a penalty for weight size to the loss function.
Three different regularizer instances are provided; they are:
* L1: Sum of the absolute weights.
* L2: Sum of the squared weights.
* L1L2: Sum of the absolute and the squared weights.
D: Because a fully connected layer occupies most of the parameters, it is prone to overfitting. One method to reduce overfitting is dropout. At each training stage, individual nodes are either "dropped out" of the net with probability 1-p or kept with probability p, so that a reduced network is left; incoming and outgoing edges to a dropped-out node are also removed.
By avoiding training all nodes on all training data, dropout decreases overfitting.
Reference:
https://machinelearningmastery.com/how-to-reduce-overfitting-in-deep-learning-with-weight-regularization/
https://en.wikipedia.org/wiki/Convolutional_neural_network
NEW QUESTION # 501
You create a datastore named training_data that references a blob container in an Azure Storage account. The blob container contains a folder named csv_files in which multiple comma-separated values (CSV) files are stored.
You have a script named train.py in a local folder named ./script that you plan to run as an experiment using an estimator. The script includes the following code to read data from the csv_files folder: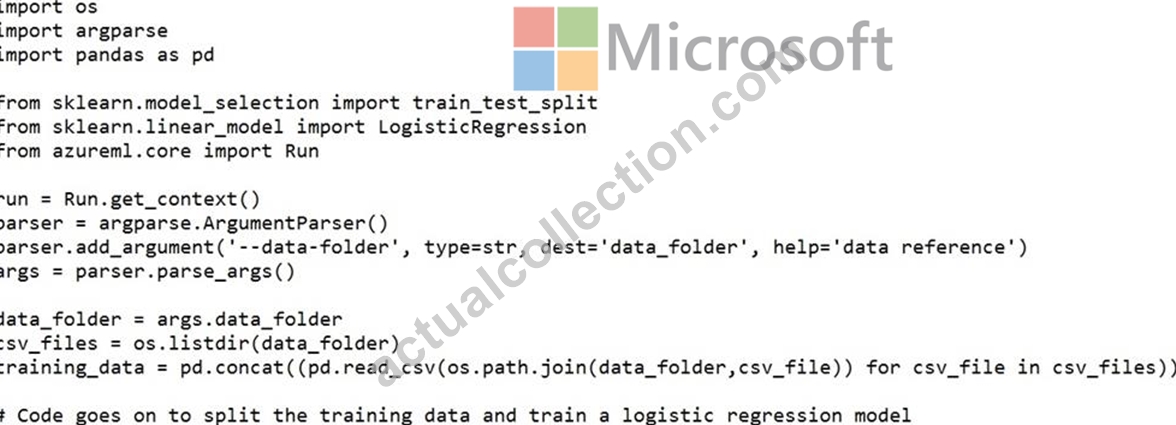
You have the following script.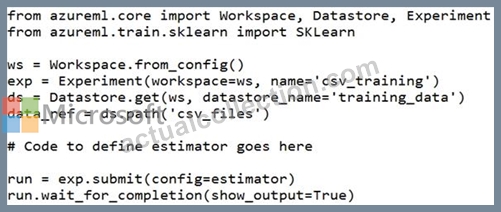
You need to configure the estimator for the experiment so that the script can read the data from a data reference named data_ref that references the csv_files folder in the training_data datastore.
Which code should you use to configure the estimator?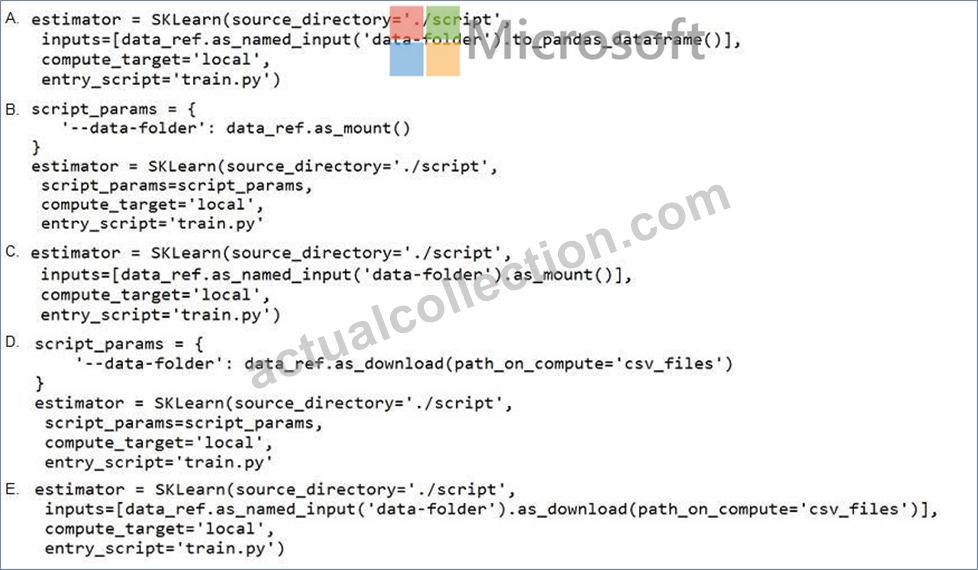
Answer: D
Explanation:
Besides passing the dataset through the inputs parameter in the estimator, you can also pass the dataset through script_params and get the data path (mounting point) in your training script via arguments. This way, you can keep your training script independent of azureml-sdk. In other words, you will be able use the same training script for local debugging and remote training on any cloud platform.
Example:
from azureml.train.sklearn import SKLearn
script_params = {
# mount the dataset on the remote compute and pass the mounted path as an argument to the training script
'--data-folder': mnist_ds.as_named_input('mnist').as_mount(),
'--regularization': 0.5
}
est = SKLearn(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train_mnist.py')
# Run the experiment
run = experiment.submit(est)
run.wait_for_completion(show_output=True)
Reference:
https://docs.microsoft.com/es-es/azure/machine-learning/how-to-train-with-datasets
NEW QUESTION # 502
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a new experiment in Azure Machine Learning Studio.
One class has a much smaller number of observations than the other classes in the training set.
You need to select an appropriate data sampling strategy to compensate for the class imbalance.
Solution: You use the Scale and Reduce sampling mode.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 503
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.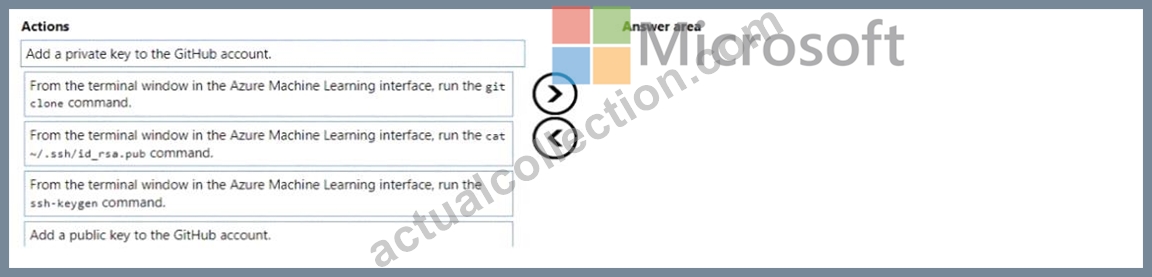
Answer:
Explanation: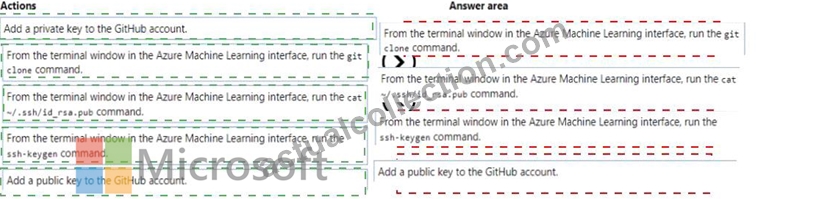
Explanation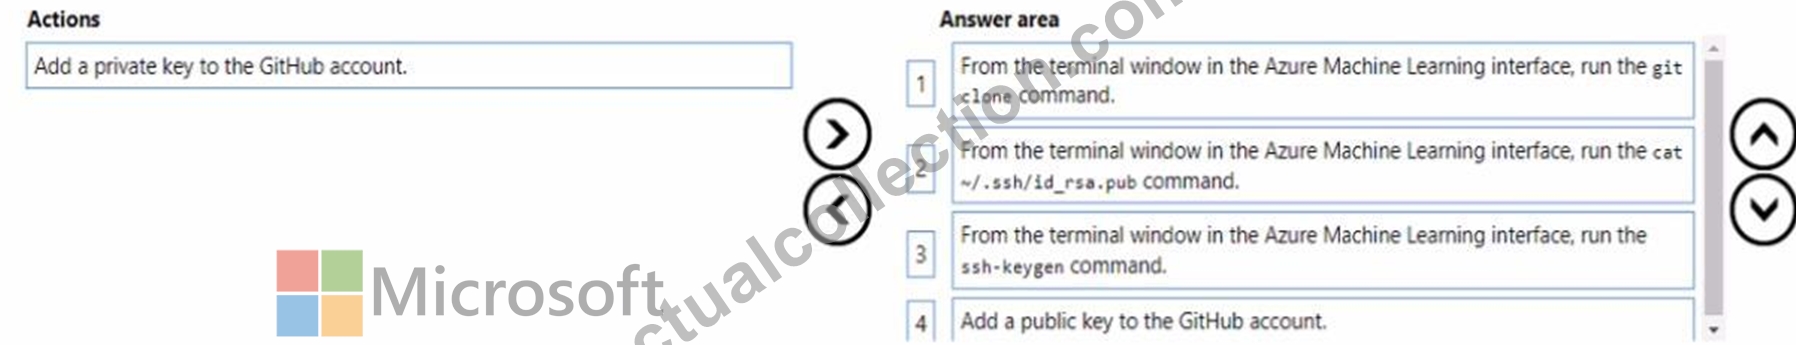
Topic 2, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1
+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: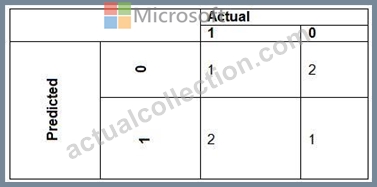
NEW QUESTION # 504
You are preparing to build a deep learning convolutional neural network model for image classification. You create a script to train the model using CUDA devices.
You must submit an experiment that runs this script in the Azure Machine Learning workspace.
The following compute resources are available:
a Microsoft Surface device on which Microsoft Office has been installed. Corporate IT policies prevent the installation of additional software a Compute Instance named in the workspace with 2 CPUs and 8 GB of memory an Azure Machine Learning compute target named with eight CPU-based nodes an Azure Machine Learning compute target named with four CPU and GPU-based nodes You need to specify the compute resources to be used for running the code to submit the experiment, and for running the script in order to minimize model training time.
Which resources should the data scientist use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.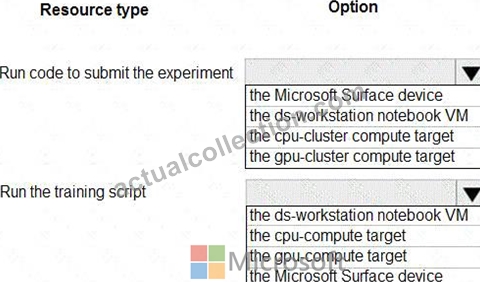
Answer:
Explanation: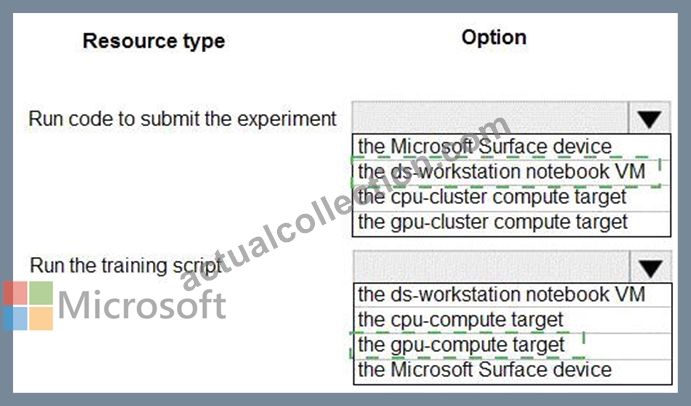
Explanation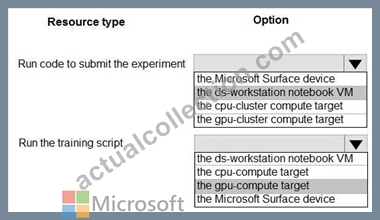
NEW QUESTION # 505
......
Valid DP-100 Test Cost: https://www.actualcollection.com/DP-100-exam-questions.html
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=12iESO6EeylKMHaQ3-WKJpjly2mMNdIed