ちなみに、Jpexam 3V0-24.25の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1tuhAbzVL_71FBcD4CoF9w8vFO5mPzrtP
安全で信頼できるウェブサイトとして、あなたの個人情報の隠しとお支払いの安全性を保障していますから、弊社のVMwareの3V0-24.25試験ソフトを安心にお買いください。我々は一番全面的な問題集を提供しています。Jpexamのサイトで探したり、弊社の係員に問い合わせたりすることができます。我々は試験の合格を保証することができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
効率的な3V0-24.25学習教材を使用すれば、専門的な資格試験に合格した製品を使用しなかった場合に必要な時間の半分を費やすだけで済みます。このようにして、旅行、パーティー、さらに別の試験の準備をする時間が増えます。あなたのための3V0-24.25トレーニングトレントの利点は、お金で測られるにはほど遠いです。一流の専門家チーム、高度な学習コンセプト、完全な学習モデルがあります。時間を節約し、3V0-24.25学習教材であなたの成功を保証することは、私たちにとって最大の見返りです。
質問 # 48
An administrator is deploying a vSphere Supervisor with NSX. What will determine the deployment size for the load balancer?
正解:C
解説:
VCF 9.0 design guidance for theSupervisor NSX Load Balancer modelstates that theNSX load balancers run on NSX Edges, and sets explicit sizing requirements at theEdge nodelevel. In the "NSX Load Balancer Design Requirements," VCF 9.0 requires that theNSX Edge cluster must be deployedbecause "NSX Load Balancers run on NSX Edges." It further requires that"NSX Edge nodes must be deployed with a minimum of Large form factor"because NSX load balancers havefixed resource allocations on NSX Edge nodes, and the Large form factor is needed to accommodate basic system and workload needs.
This directly ties "deployment size" of the load balancer service capacity to theEdge node form factor(Small/Medium/Large, etc.) rather than the number of pods or the number of clusters. The document also notes that if additional load balancers are required, NSX Edges can bescaled up or out, again reinforcing that sizing is anEdge nodesizing decision.
質問 # 49
A Cloud Administrator is tasked with resolving a complex "Split-Brain" scenario in a Zonal Supervisor deployment following a storage outage in Zone-B.
Context:
The Supervisor spans Zone-A, Zone-B, and Zone-C. A storage array failure in Zone-B caused the Supervisor Control Plane VM in that zone to become isolated and read-only. The outage is now resolved, but the Supervisor status remains Warning. TKG clusters in Zone-B are unreachable.
Review the following diagnostic data from the Supervisor:
# kubectl get nodes -L topology.kubernetes.io/zone
NAME STATUS ROLES ZONE
42018c-supervisor-control-plane-0 Ready master Zone-A
42018c-supervisor-control-plane-1 NotReady master Zone-B
42018c-supervisor-control-plane-2 Ready master Zone-C
# kubectl get etcd -n kube-system
NAME STATUS HEALTH
etcd-0 Healthy true
etcd-1 Unhealthy false <-- Corresponds to Zone-B node
etcd-2 Healthy true
The administrator determines that the etcd member in Zone-B has diverged and cannot automatically rejoin the quorum.
What is the correct recovery procedure to restore full health to the Supervisor? (Choose 2.)
正解:A、C
質問 # 50
Which protocols are supported for use as an external identity provider for VMware vSphere Kubernetes Service (VKS) clusters?
正解:D
解説:
In VMware Cloud Foundation (VCF) 9.0, providing secure, centralized access to Kubernetes clusters is a critical requirement for enterprise compliance. The vSphere Kubernetes Service (VKS) utilizes OpenID Connect (OIDC) as the primary supported protocol for integrating with external identity providers (IdPs).
While vCenter Server itself supports SAML 2.0 for administrative access to the vSphere Client, the workload clusters (VKS) specifically leverage OIDC to provide a modern, token-based authentication flow for developers and automated systems.
Through the integration of the Pinniped authentication service within the vSphere Supervisor, administrators can configure VKS clusters to delegate authentication to external providers like Okta, Microsoft Entra ID (formerly Azure AD), or PingFederate. When a developer uses the kubectl vsphere login command, the system facilitates an OIDC flow that issues short-lived identity tokens. This ensures that user identities are managed in a single source of truth rather than locally on each cluster. Although Active Directory (Option D) is a common identity source, it is typically reached via an OIDC provider or integrated into vCenter ' s SSO, which then presents an OIDC interface to the Kubernetes API. VCF 9.0 documentation emphasizes OIDC because of its native compatibility with Kubernetes authentication headers and its ability to handle complex claims and group memberships efficiently within a cloud-native SDDC environment.
質問 # 51
The administrator has completed a proof of concept for using Harbor as a container registry part of the Supervisor services and you are tasked for cleaning up the environment, starting with the unlnstall of the Harbor Supervisor service.
Drag and drop the four tasks into the correct order from Configuration Options on the left and place them into the Configuration Sequence on the right. (Choose four)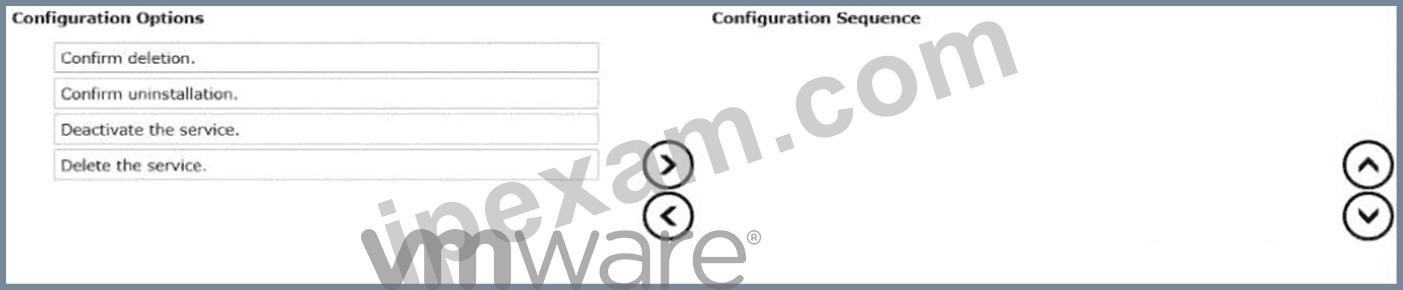
正解:
解説: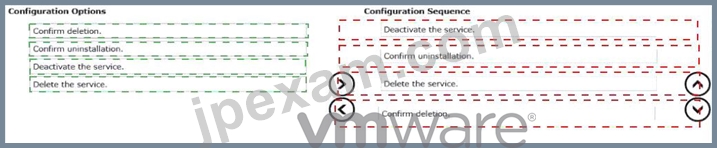
Explanation:
Configuration Sequence (in order):
Deactivate the service.
Confirm uninstallation.
Delete the service.
Confirm deletion.
Uninstalling a Supervisor Service cleanly follows a "stop/remove/cleanup" pattern to avoid orphaned components and to ensure the Supervisor isn't still reconciling the service while you remove it. First, youDeactivate the serviceso the Supervisor stops managing and running the Harbor service components. This prevents new service resources from being created while you are attempting to remove them and allows the platform to transition the service into a non-operational state safely.
Next, youConfirm uninstallationto initiate the removal workflow. This step acknowledges that the service's deployed components (such as pods, controllers, and any associated objects) will be removed from the Supervisor-managed environment. After the uninstall workflow is initiated and the service is no longer active, you proceed toDelete the serviceto remove the Harbor service registration/entry from the Supervisor Services list, ensuring it is no longer available to namespaces or consumers. Finally, youConfirm deletionas the last safeguard, since deletion is typically destructive and removes the service definition from the environment's available services catalog.
質問 # 52
A cloud operations team is managing multiple Supervisor Clusters across two regions. Each region hosts its own vSphere Kubernetes clusters, integrated through a federated service mesh to enable consistent service connectivity and policy enforcement across environments.
The application team wants to expose a multi-tier microservice named "GovApp", which includes front-end, API, and database services distributed between the two regions. Uniform traffic routing, identity, and security policies are also needed for these workloads regardless of the cluster or region in which they are deployed.
To meet these requirements, the architects decide to create a Global Namespace that spans both Supervisor Clusters.
Which two statements describe the requirements for a Global Namespace in a vSphere Kubernetes Service Mesh deployment? (Choose two.)
正解:A、B
解説:
A Global Namespace in a service-mesh-driven, multi-cluster design is fundamentally anorganizational and policy boundarythat lets platform teams treat multiple Kubernetes namespaces-across multiple clusters
/regions-as one logical application domain. That is whyBis correct: it defines an application boundary spanning clusters, which is exactly what "GovApp" needs when its tiers are distributed across regions but must still behave as one application. It also explains whyAis correct: the value of a Global Namespace is that you can applyconsistent identity, security, and traffic policiesacross all member namespaces and clusters, rather than configuring them separately per cluster. This supports uniform mTLS/authorization posture, consistent service-to-service access rules, and standardized routing behaviors regardless of where a service instance runs.
The other options describe outcomes that may be enabled by additional service-mesh features, but they are not the corerequirementsthat define a Global Namespace: distributed ingress/egress is not guaranteed simply by the namespace construct, automatic workload placement is typically handled by schedulers/placement engines rather than the namespace boundary, and centralized logging is an observability capability outside the namespace requirement itself.
質問 # 53
......
多くの時間と労力をかかってVMwareの3V0-24.25認定試験に合格するを冒険にすると代わりJpexamが提供した問題集を利用してわずか一度お金かかって合格するのは価値があるでしょう。今の社会の中で時間がそんなに重要で最も保障できるJpexamを選ばましょう。
3V0-24.25模擬対策: https://www.jpexam.com/3V0-24.25_exam.html
無料でクラウドストレージから最新のJpexam 3V0-24.25 PDFダンプをダウンロードする:https://drive.google.com/open?id=1tuhAbzVL_71FBcD4CoF9w8vFO5mPzrtP