BTW, DOWNLOAD part of PDF4Test DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1Q5JVaQ_uIwGSxtTJGhB51qtQIftqzNGd
You can enjoy free update for 365 days if you buying DP-100 study guide of us, that is to say, in the following year you can obtain the latest information for the exam timely. And the update version for DP-100 exam dumps will be sent to your email automatically. You just need to receive and exchange your learning ways in accordance with the new changes. In addition, DP-100 Study Materials are compiled by experienced experts, and they are quite familiar with the exam center, therefore the quality can be guaranteed. We also have online and offline chat service, if you have any questions about DP-100 exam dumps, you can consult us.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and prepare a machine learning solution | 20-25% | - Design an Azure Machine Learning workspace
|
| Topic 2: Explore data and train models | 35-40% | - Optimize model performance
|
| Topic 3: Prepare a model for deployment | 20-25% | - Deploy machine learning models
|
| Topic 4: Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
Frankly speaking, it is difficult to get the DP-100 certificate without help. Usually, the time you invest to prepare the exam is long. Now, all of your worries can be wiped out because of our DP-100 exam questions. Some people worry about that some difficult knowledge is hard to understand or the DP-100 test guide is not suitable for them. Actually, the difficult parts of the exam have been simplified, which will be easy for you to understand. Also, there will be examples, simulations and charts to make explanations vivid. In order to aid you to memorize the Designing and Implementing a Data Science Solution on Azure exam cram better, we have integrated knowledge structure. You will clearly know what you are learning and which part you need to learn carefully. You will regret if you give up challenging yourself.
NEW QUESTION # 239
You are producing a multiple linear regression model in Azure Machine Learning Studio.
Several independent variables are highly correlated.
You need to select appropriate methods for conducting effective feature engineering on all the data.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.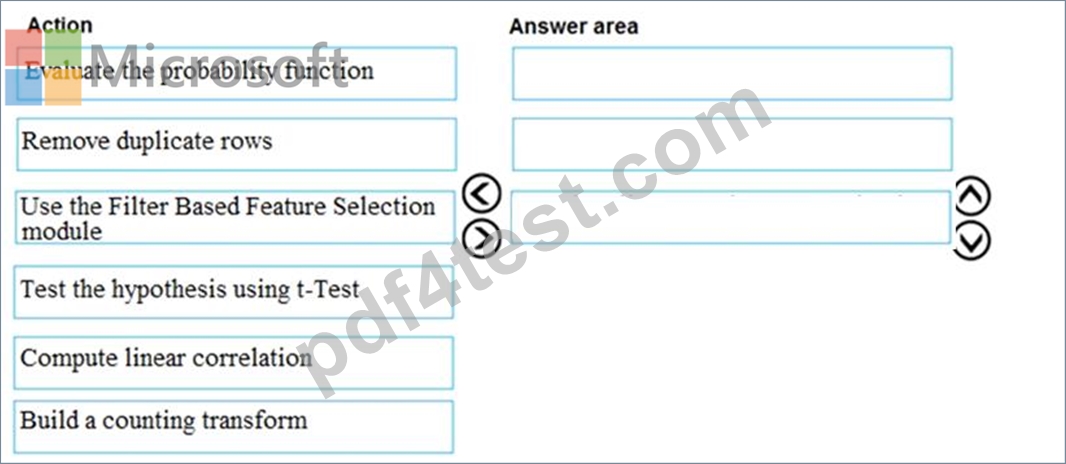
Answer:
Explanation: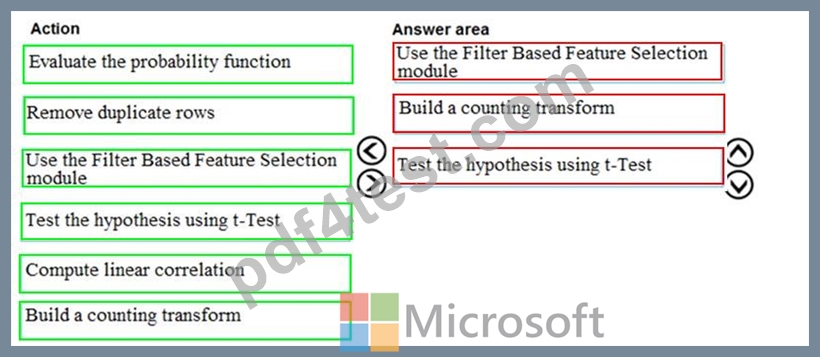
Explanation:
Step 1: Use the Filter Based Feature Selection module
Filter Based Feature Selection identifies the features in a dataset with the greatest predictive power.
The module outputs a dataset that contains the best feature columns, as ranked by predictive power. It also outputs the names of the features and their scores from the selected metric.
Step 2: Build a counting transform
A counting transform creates a transformation that turns count tables into features, so that you can apply the transformation to multiple datasets.
Step 3: Test the hypothesis using t-Test
References:
https://docs.microsoft.com/bs-latn-ba/azure/machine-learning/studio-module-reference/filter-based-feature-selection
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/build-counting-transform
NEW QUESTION # 240
You run an experiment that uses an AutoMLConfig class to define an automated machine learning task with a maximum of ten model training iterations. The task will attempt to find the best performing model based on a metric named accuracy.
You submit the experiment with the following code:
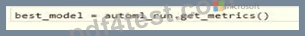
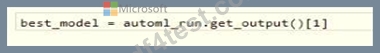
You need to create Python code that returns the best model that is generated by the automated machine learning task. Which code segment should you use?

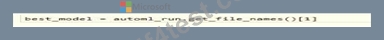
Answer: C
Explanation:
Explanation
The get_output method returns the best run and the fitted model.
Reference:
https://notebooks.azure.com/azureml/projects/azureml-getting-started/html/how-to-use-azureml/automated-mach
NEW QUESTION # 241
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create a compute cluster in the workspace. The compute cluster must run workloads and properly handle interruptions. You start by calculating the maximum amount of compute resources required by the workloads and size the cluster to match the calculations.
The cluster definition includes the following properties and values:
* name="mlcluster1''
* size="STANDARD.DS3.v2"
* min_instances=1
* maxjnstances=4
* tier="dedicated"
The cost of the compute resources must be minimized when a workload is active Of idle. Cluster property changes must not affect the maximum amount of compute resources available to the workloads run on the cluster.
You need to modify the cluster properties to minimize the cost of compute resources.
Which properties should you modify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.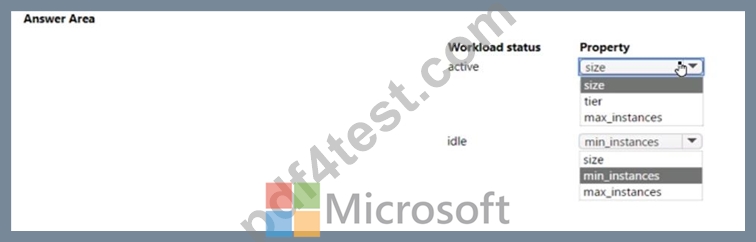
Answer:
Explanation: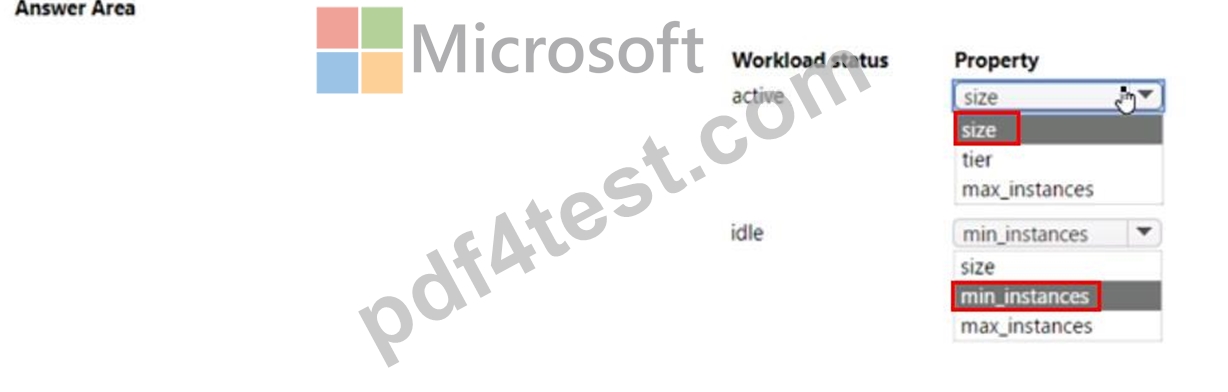
NEW QUESTION # 242
You are implementing a machine learning model to predict stock prices.
The model uses a PostgreSQL database and requires GPU processing.
You need to create a virtual machine that is pre-configured with the required tools.
What should you do?
Answer: D
Explanation:
Incorrect Answers:
A, C: PostgreSQL (CentOS) is only available in the Linux Edition.
B: The Azure Geo AI Data Science VM (Geo-DSVM) delivers geospatial analytics capabilities from Microsoft's Data Science VM. Specifically, this VM extends the AI and data science toolkits in the Data Science VM by adding ESRI's market-leading ArcGIS Pro Geographic Information System.
D: DLVM is a template on top of DSVM image. In terms of the packages, GPU drivers etc are all there in the DSVM image. Mostly it is for convenience during creation where we only allow DLVM to be created on GPU VM instances on Azure.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/data-science-virtual-machine/overview
NEW QUESTION # 243
You have machine learning models produce unfair predictions across sensitive features.
You must use a post-processing technique to apply a constraint to the models to mitigate their unfairness.
You need to select a post-processing technique and model type.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.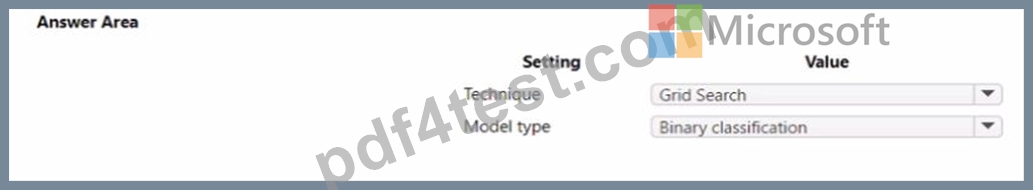
Answer:
Explanation: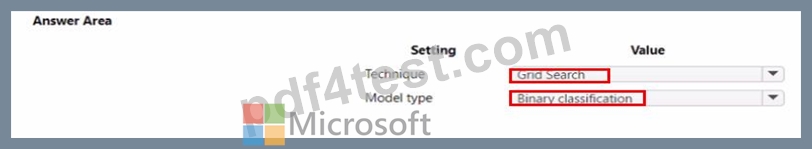
NEW QUESTION # 244
......
These latest Designing and Implementing a Data Science Solution on Azure (DP-100) Questions were made by PDF4Test professionals after working day and night so that users can prepare for the Microsoft DP-100 exam successfully. PDF4Test even guarantees you that you can pass the Microsoft DP-100 Certification test on the first try with your untiring efforts.
DP-100 Valid Exam Preparation: https://www.pdf4test.com/DP-100-dump-torrent.html
BONUS!!! Download part of PDF4Test DP-100 dumps for free: https://drive.google.com/open?id=1Q5JVaQ_uIwGSxtTJGhB51qtQIftqzNGd