Databricks Certified-Data-Engineer-Professional Valid Test Materials - Certified-Data-Engineer-Professional New Braindumps Questions

The Certified-Data-Engineer-Professional real questions are written and approved by our It experts, and tested by our senior professionals with many years' experience. The content of our Certified-Data-Engineer-Professional pass guide covers the most of questions in the actual test and all you need to do is review our Certified-Data-Engineer-Professional VCE Dumps carefully before taking the exam. Then you can pass the actual test quickly and get certification easily.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
>> Databricks Certified-Data-Engineer-Professional Valid Test Materials <<
Certified-Data-Engineer-Professional PDF Dumps Files for Busy Professionals
It is possible for you to easily pass Certified-Data-Engineer-Professional exam. Many users who have easily pass Certified-Data-Engineer-Professional exam with our Certified-Data-Engineer-Professional exam software of Pass4SureQuiz. You will have a real try after you download our free demo of Certified-Data-Engineer-Professional Exam software. We will be responsible for every customer who has purchased our product. We ensure that the Certified-Data-Engineer-Professional exam software you are using is the latest version.
Databricks Certified Data Engineer Professional Sample Questions (Q93-Q98):
NEW QUESTION # 93
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
- A. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to compute the daily aggregated distance and fuel efficiency per truck_id reporting. Create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
- B. Define a streaming table to ingest and store the raw telemetry data, and create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting. - C. Define a materialized view to ingest and store the raw telemetry data, and create a streaming table to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting. - D. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to incrementally compute the latest location, speed, and fuel_level per truck_id for real-time monitoring. Create a materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
Answer: D
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 94
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
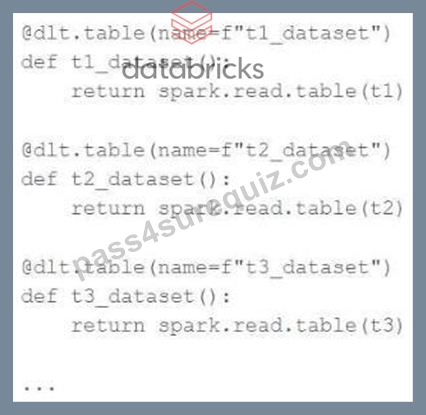
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
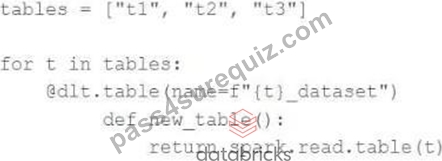
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- D. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
Answer: B
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 95
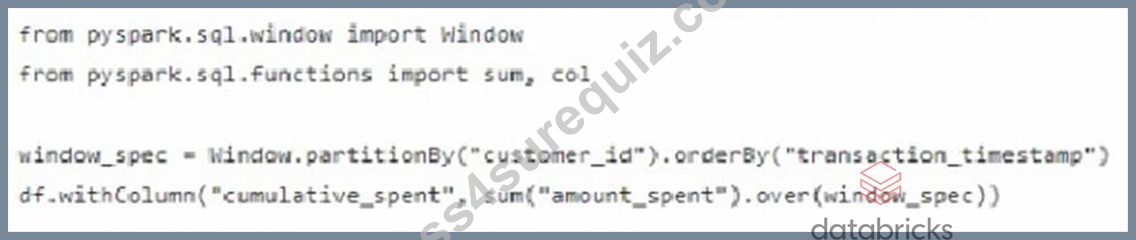
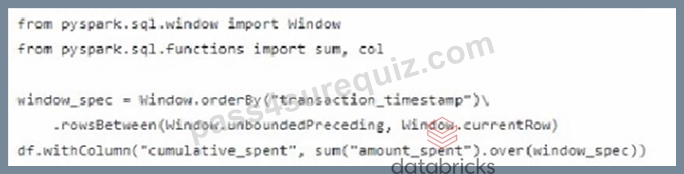
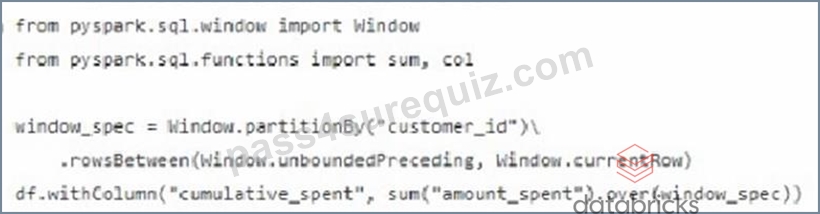
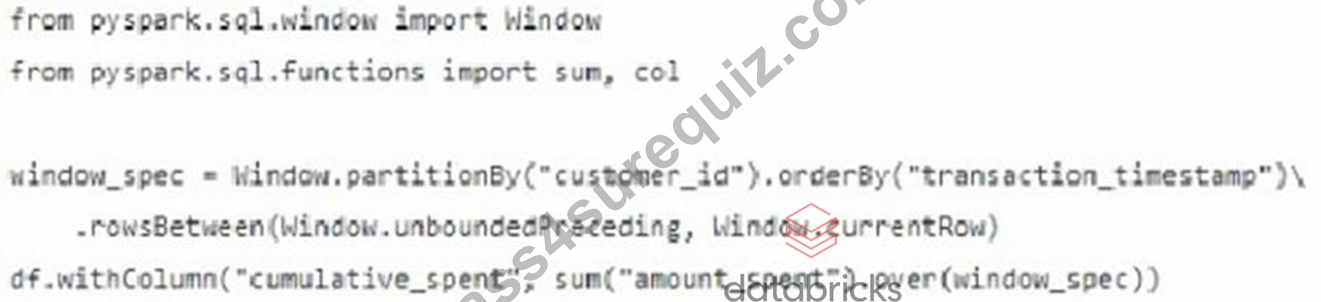
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
Answer: D
Explanation:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
NEW QUESTION # 96
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- B. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- C. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- D. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- E. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
Answer: A
NEW QUESTION # 97
A data engineer needs to design an efficient pipeline that automatically processes new CSV files as they arrive in S3 storage. Which Databricks feature should the data engineer use to meet these requirements?
- A. Auto Loader with schema inference and evolution enabled
- B. COPY INTO SQL command with parameters to track processed files
- C. Traditional batch processing with scheduled Databricks Jobs
- D. Streaming from cloud storage using standard Spark readStream with format ("csv") and format ("json")
Answer: A
Explanation:
Auto Loader is designed to efficiently and incrementally process new files as they arrive in cloud object storage. It provides scalable file discovery, supports schema inference and evolution, and minimizes overhead compared to traditional batch or manual streaming approaches.
NEW QUESTION # 98
......
If you suffer from procrastination and cannot make full use of your sporadic time during your learning process, it is an ideal way to choose our Certified-Data-Engineer-Professional training dumps. We can guarantee that you are able not only to enjoy the pleasure of study but also obtain your Certified-Data-Engineer-Professional Certification successfully, which can be seen as killing two birds with one stone. And you will be surprised to find our superiorities of our Certified-Data-Engineer-Professional exam questioms than the other vendors’.
Certified-Data-Engineer-Professional New Braindumps Questions: https://www.pass4surequiz.com/Certified-Data-Engineer-Professional-exam-quiz.html
- Databricks Certified Data Engineer Professional pass4sure cram - Certified-Data-Engineer-Professional pdf vce - Databricks Certified Data Engineer Professional practice torrent 🕺 Open ➽ www.practicevce.com 🢪 and search for [ Certified-Data-Engineer-Professional ] to download exam materials for free 🧶Test Certified-Data-Engineer-Professional Cram Review
- Databricks Certified Data Engineer Professional pass4sure cram - Certified-Data-Engineer-Professional pdf vce - Databricks Certified Data Engineer Professional practice torrent 🤼 Enter ▶ www.pdfvce.com ◀ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 🔶New Certified-Data-Engineer-Professional Exam Camp
- Authorized Certified-Data-Engineer-Professional Certification ⏳ Exam Certified-Data-Engineer-Professional Study Solutions ⚠ Certified-Data-Engineer-Professional Key Concepts ❗ Open website ▶ www.examcollectionpass.com ◀ and search for ➤ Certified-Data-Engineer-Professional ⮘ for free download ⏫Certified-Data-Engineer-Professional Customizable Exam Mode
- Databricks Certified Data Engineer Professional pass4sure cram - Certified-Data-Engineer-Professional pdf vce - Databricks Certified Data Engineer Professional practice torrent ⛳ Enter ⇛ www.pdfvce.com ⇚ and search for “ Certified-Data-Engineer-Professional ” to download for free 🚹Study Certified-Data-Engineer-Professional Material
- Databricks Certified Data Engineer Professional pass4sure cram - Certified-Data-Engineer-Professional pdf vce - Databricks Certified Data Engineer Professional practice torrent 🥄 Easily obtain { Certified-Data-Engineer-Professional } for free download through “ www.practicevce.com ” 🚲Key Certified-Data-Engineer-Professional Concepts
- Wonderful Certified-Data-Engineer-Professional Exam Dumps Materials provide you the most accurate Practice Braindumps - Pdfvce 😢 Open ▶ www.pdfvce.com ◀ enter ✔ Certified-Data-Engineer-Professional ️✔️ and obtain a free download 🧔New Certified-Data-Engineer-Professional Exam Camp
- 2026 Certified-Data-Engineer-Professional Valid Test Materials - The Best Databricks Certified-Data-Engineer-Professional New Braindumps Questions: Databricks Certified Data Engineer Professional 🧽 Search on ( www.examcollectionpass.com ) for ⏩ Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 👉Certified-Data-Engineer-Professional Exam Reference
- Certified-Data-Engineer-Professional Valid Test Braindumps ➕ Latest Certified-Data-Engineer-Professional Exam Pattern 🎒 Exam Certified-Data-Engineer-Professional Discount ⏮ Enter ▷ www.pdfvce.com ◁ and search for ( Certified-Data-Engineer-Professional ) to download for free 🦐Key Certified-Data-Engineer-Professional Concepts
- Exam Certified-Data-Engineer-Professional Discount 👍 New Certified-Data-Engineer-Professional Exam Camp 🚆 Test Certified-Data-Engineer-Professional Cram Review 🐑 Search for ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download on ( www.easy4engine.com ) 🎳New Certified-Data-Engineer-Professional Study Notes
- Exam Certified-Data-Engineer-Professional Study Solutions 🏥 Test Certified-Data-Engineer-Professional Cram Review 👾 Latest Certified-Data-Engineer-Professional Cram Materials 💢 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free on 【 www.pdfvce.com 】 website 🐩Certified-Data-Engineer-Professional Valid Test Braindumps
- Beneficial Databricks Certified-Data-Engineer-Professional Dumps to Achieve Your Activity [2026] ❔ Go to website ➤ www.practicevce.com ⮘ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🚮Certified-Data-Engineer-Professional Valid Test Braindumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes