BONUS!!! Download part of Prep4sures DEA-C02 dumps for free: https://drive.google.com/open?id=1lBr2U2xtE0mjaNXInmiFOZ6jayVf8o3q
Without bothering to stick to any formality, our DEA-C02 learning quiz can be obtained within five minutes. No need to line up or queue up to get our practice materials. No harangue is included within DEA-C02 training materials and every page is written by our proficient experts with dedication. Our website experts simplify complex concepts and add examples, simulations, and diagrams to explain anything that might be difficult to understand. so even ordinary examiners can master all the learning problems without difficulty. In addition, DEA-C02 candidates can benefit themselves by using our test engine and get a lot of test questions like exercises and answers.
| Section | Objectives |
|---|---|
| Topic 1: Data Engineering Fundamentals | - Data pipelines concepts and patterns - Snowflake architecture for data engineering |
| Topic 2: Data Transformation and Processing | - Streams and Tasks for ELT pipelines - Handling semi-structured data (JSON, Avro, Parquet) - SQL-based transformations in Snowflake |
| Topic 3: Security and Data Governance | - Data masking and encryption - Secure data sharing - Role-based access control (RBAC) |
| Topic 4: Performance and Optimization | - Clustering and partition strategies - Warehouse sizing and scaling - Query optimization techniques |
| Topic 5: Data Ingestion and Integration | - Snowpipe usage and automation - Staging data and loading mechanisms - Batch and streaming ingestion approaches |
>> Reliable DEA-C02 Exam Book <<
Our DEA-C02 practice prep provides you with a brand-new learning method that lets you get rid of heavy schoolbags, lose boring textbooks, and let you master all the important knowledge in the process of making a question. Please believe that with DEA-C02 Real Exam, you will fall in love with learning. Our DEA-C02 exam questions are contained in three versions: the PDF, Software and APP online which can cater to different needs of our customers.
NEW QUESTION # 334
You are tasked with loading a large CSV file (1 T B) into Snowflake. The file contains data for the past 5 years, partitioned by year in the filename (e.g., 'data 2019.csv', 'data 2020.csv', etc.). You need to minimize data loading time and ensure data quality. You have a Snowflake virtual warehouse 'XSMALL' and a stage 'my_stage'. Which of the following strategies would be MOST effective?
Answer: D
Explanation:
Option B is the most effective. Increasing the warehouse size to 'LARGE allows for parallel processing and faster loading. ERROR = CONTINUE ensures that the load process doesn't halt on minor errors, and post-load data quality checks are more efficient. A allows validation during load which slows down the process significantly. C will halt the entire process upon encountering an error. D is not suitable because it will be throttled by the XSMALL warehouse, which is not good for initial data loading. E isn't realistic as files should have a standard headen
NEW QUESTION # 335
You are tasked with creating a Python script to load data from a CSV file stored in an AWS S3 bucket into a Snowflake table. You have the following requirements: 1. Use the 'COPY INTO' command for efficient data loading. 2. Handle potential schema evolution in the CSV file (e.g., new columns being added). 3. Automatically create the target table if it doesn't exist, inferring the schema from the CSV. Which combination of Snowflake Python connector functionalities and 'COPY INTO' options would best address these requirements, assuming you have an AWS IAM role configured for Snowflake access to S3?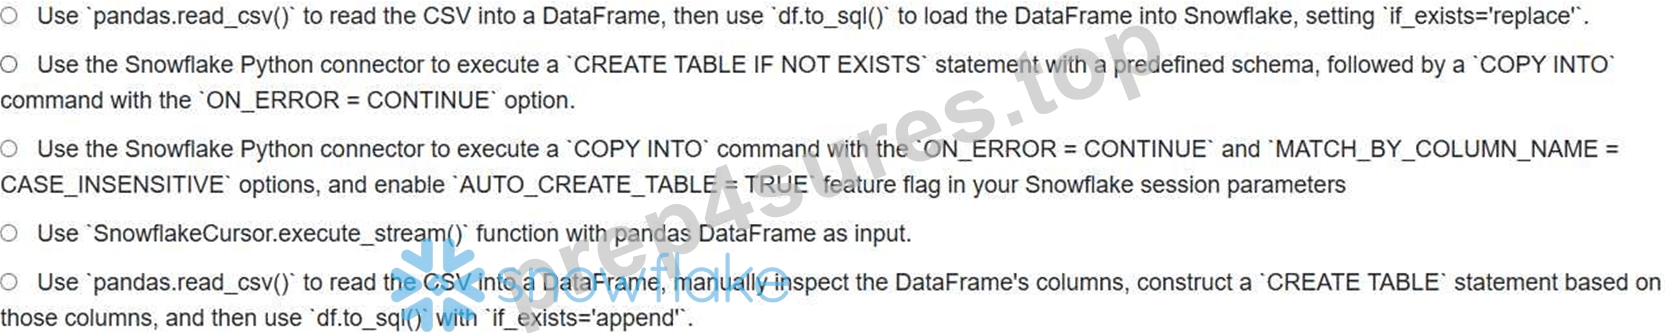
Answer: A
Explanation:
Option C is the most effective solution. 'ON_ERROR = CONTINUE allows the 'COPY INTO' command to proceed even if it encounters errors (e.g., due to extra columns). = CASE INSENSITIVE' handles slight variations in column names between the CSV and the Snowflake table. Setting = TRUE in the Snowflake session (this is a hypothetical feature, Snowflake doesn't directly have AUTO_CREATE_TABLE in COPY INTO, so this tests knowledge of workarounds and understanding of COPY INTO capabilities). Other options have drawbacks. Option A doesn't directly use COPY INTO and is generally slower. Option B requires a predefined schema, negating the ability to handle schema evolution. Option D is used with in memory stream, rather s3. Option E involves manual schema inspection and construction, which is cumbersome and error-prone.
NEW QUESTION # 336
You have a Snowpark DataFrame 'df_products' with columns 'product id', 'category', and 'price'. You need to perform the following transformations in a single, optimized query using Snowpark Python: 1. Filter for products in the 'Electronics' or 'Clothing' categories. 2. Group the filtered data by category. 3. Calculate the average price for each category. 4. Rename the aggregated column to 'average_price'. Which of the following code snippets demonstrates the most efficient way to achieve this?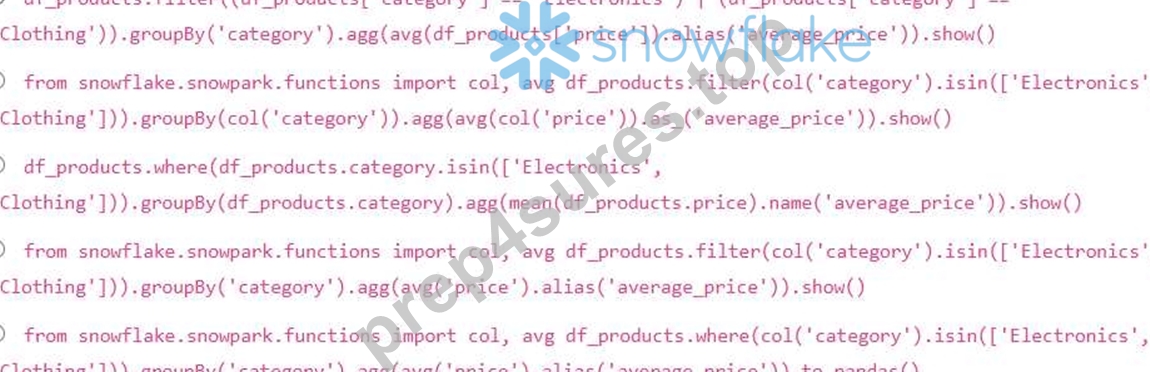
Answer: C
Explanation:
Option B is the most efficient and correct. It uses 'col()' from 'snowflake.snowpark.functions' to properly reference the 'category' and 'price' columns, uses 'isin()' for a more concise and efficient filtering of multiple category values, groups by the category using and calculates the average price with 'avg(col('price')).as_('average_price')'. Option A, C, and D are syntactically incorrect or less efficient ways to accomplish the same task within Snowpark. Option E is incorrect because it utilizes 'to_pandas()' which returns the result as a Pandas DataFrame rather than a Snowpark DataFrame, failing to adhere to the Snowpark environment. While Option D is very similar, it lacks the proper syntax for specifying column references with 'col('category')' in the groupBy and 'col('price')' in the avg function.
NEW QUESTION # 337
You are using the Snowflake Developer API to automate the creation and management of masking policies. You need to create a masking policy that masks an email address using SHA256 hashing. You also want to ensure that the policy can be applied to multiple tables and columns without modification. Assuming you have already established a connection to Snowflake using the Developer API, which of the following code snippets BEST demonstrates how to create and apply this masking policy using Python?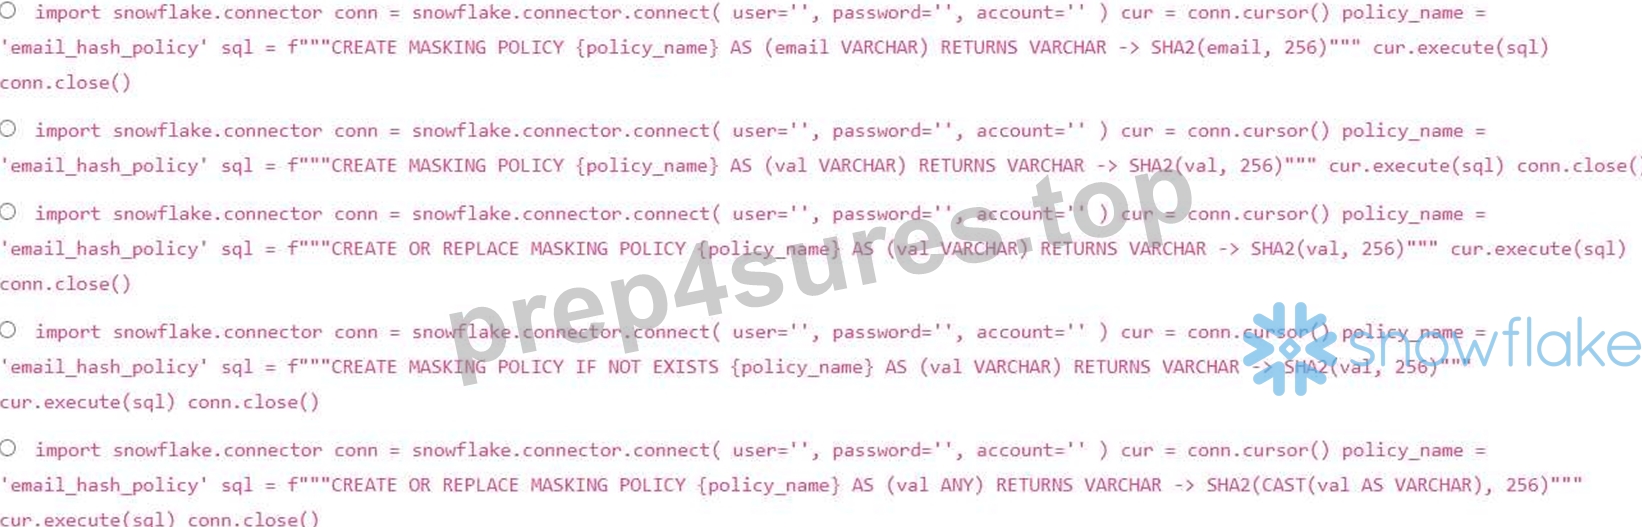
Answer: E
Explanation:
Option E is the best approach because: It uses 'CREATE OR REPLACE MASKING POLICY', which allows you to update the policy definition if it already exists. It defines the input parameter as 'ANY' and then casts it to 'VARCHAR within the SHA2 function. This makes the policy more versatile and applicable to columns with different data types (as long as they can be cast to VARCHAR). Using CREATE OR REPLACE MASKING POLICY ensure no error will be raised when the policy already exist. The 'val ANY part ensures that policy work for all type of data.
NEW QUESTION # 338
You are designing a Snowpipe pipeline to ingest data from an AWS SQS queue. The queue contains notifications about new files arriving in an S3 bucket. However, due to network issues, some notifications are delayed, causing Snowpipe to potentially miss files. Which of the following strategies, when combined, will BEST address the problem of delayed notifications and ensure data completeness?
Answer: C
Explanation:
Option E provides the most robust solution. Setting 'MAX FILE AGE to 'DEFAULT' ensures that Snowpipe considers all files, regardless of their age. 'SYSTEM$PIPE FORCE RESUME' can help in some cases. The key component is the supplemental process that actively compares the S3 bucket contents with the loaded data, identifying and loading any missing files due to delayed notifications. This approach guarantees data completeness even with delayed or missed SQS notifications. A,B,C,D doesn't guarantee data completeness. A alone can cause huge latency issue. B is not optimal. C addresses the SQS issue but not guaranteed to catch every case. D requires manual load intervention
NEW QUESTION # 339
......
Combined with your specific situation and the characteristics of our DEA-C02 exam questions, our professional services will recommend the most suitable version of DEA-C02 study materials for you. We introduce a free trial version of the DEA-C02 learning guide because we want users to see our sincerity. DEA-C02 exam prep sincerely hopes that you can achieve your goals and realize your dreams.
DEA-C02 Test Duration: https://www.prep4sures.top/DEA-C02-exam-dumps-torrent.html
What's more, part of that Prep4sures DEA-C02 dumps now are free: https://drive.google.com/open?id=1lBr2U2xtE0mjaNXInmiFOZ6jayVf8o3q