Certified-Data-Engineer-Professional試験の準備方法|高品質なCertified-Data-Engineer-Professional合格対策試験|信頼的なDatabricks Certified Data Engineer Professional的中合格問題集

現在、IT業界での激しい競争に直面しているあなたは、無力に感じるでしょう。これは避けられないことですから、あなたがしなければならないことは、自分のキャリアを護衛するのです。色々な選択がありますが、Tech4ExamのDatabricksのCertified-Data-Engineer-Professional問題集と解答をお勧めします。それはあなたが成功認定を助ける良いヘルパーですから、あなたはまだ何を待っているのですか。速く最新のTech4ExamのDatabricksのCertified-Data-Engineer-Professionalトレーニング資料を取りに行きましょう。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 2: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 4: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Compare streaming tables and materialized views
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Develop unit and integration tests for data processing code
- 7. Use control flow operators in pipeline components
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 6: Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 8: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Topic 9: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 10: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
>> Certified-Data-Engineer-Professional合格対策 <<
信頼できるCertified-Data-Engineer-Professional合格対策試験-試験の準備方法-素晴らしいCertified-Data-Engineer-Professional的中合格問題集
これは高効率の時代であり、DatabricksおそらくCertified-Data-Engineer-Professional証明書を通じてのみ競争力を証明する方法が最も簡単です。 ただし、他の問題に巻き込まれる可能性があるため、多くの人にとって時間は限られています。Tech4Exam Certified-Data-Engineer-Professional学習教材を使用すると、すべての問題が疑いなく簡単に解決されます。 信頼できる有効なCertified-Data-Engineer-Professional試験トレントだけでなく、最も柔軟な学習方法も提供できます。 また、他の多くのお客様と同様に、Databricks Certified Data Engineer Professional試験に合格する必要があることを確認できます。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q91-Q96):
質問 # 91
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- B. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
- C. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB*
1024*1024/512), and then write to parquet. - D. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- E. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
正解:D
解説:
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly. Setting spark.sql.files.maxPartitionBytes to 512 MB configures Spark to process data in chunks of 512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB. The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
質問 # 92
A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace. Which approach should the data engineer use?
- A. Grant all users CAN MANAGE permission on all jobs to avoid access issues.
- B. Grant CAN RUN permission to everyone and CAN MANAGE to a single admin group.
- C. Use only folder-level permissions and avoid setting permissions on individual jobs.
- D. Assign users only the minimum permission level (e.g., CAN RUN or CAN VIEW) required for their role on each job.
正解:D
解説:
Assigning the minimum required permission level on each job ensures users can perform only the actions necessary for their role. This directly enforces the principle of least privilege while maintaining secure and controlled access in a collaborative workspace.
質問 # 93
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.files.maxPartitionBytes
- B. spark.sql.files.openCostInBytes
- C. spark.sql.adaptive.advisoryPartitionSizeInBytes
- D. spark.sql.adaptive.coalescePartitions.minPartitionNum
- E. spark.sql.autoBroadcastJoinThreshold
正解:A
解説:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file- based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file.
質問 # 94
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- B. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
- C. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
- D. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
正解:D
解説:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
質問 # 95
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
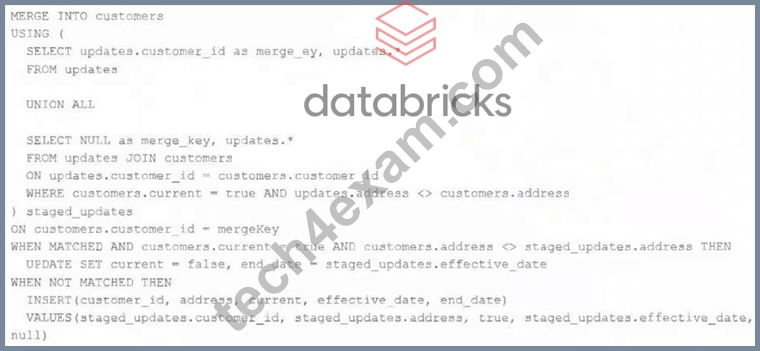
Which statement describes this implementation?
- A. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- B. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- C. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- D. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- E. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
正解:E
質問 # 96
......
Tech4ExamのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料は正確性が高くて、カバー率も広いです。それは君の文化知識を増強でき、君の実践水準も増強でき、君をIT業種での本当のエリートになって、君に他人に羨ましい給料のある仕事をもたらすことができます。うちのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料を購入する前に、Tech4Examのサイトで、一部分のフリーな試験問題と解答をダンロードでき、試用してみます。
Certified-Data-Engineer-Professional的中合格問題集: https://www.tech4exam.com/Certified-Data-Engineer-Professional-pass-shiken.html
- 実際的なCertified-Data-Engineer-Professional合格対策 - 合格スムーズCertified-Data-Engineer-Professional的中合格問題集 | ユニークなCertified-Data-Engineer-Professional最新対策問題 🥋 “ Certified-Data-Engineer-Professional ”の試験問題は“ jp.fast2test.com ”で無料配信中Certified-Data-Engineer-Professionalソフトウエア
- Certified-Data-Engineer-Professional資格トレーニング 🤹 Certified-Data-Engineer-Professional赤本合格率 🦔 Certified-Data-Engineer-Professional日本語受験教科書 🍰 【 www.goshiken.com 】で使える無料オンライン版“ Certified-Data-Engineer-Professional ” の試験問題Certified-Data-Engineer-Professional専門知識訓練
- 有難いCertified-Data-Engineer-Professional合格対策 - 合格スムーズCertified-Data-Engineer-Professional的中合格問題集 | ユニークなCertified-Data-Engineer-Professional最新対策問題 👿 ▶ www.passtest.jp ◀を開き、【 Certified-Data-Engineer-Professional 】を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional資格トレーニング
- Certified-Data-Engineer-Professional合格対策|Databricks Certified Data Engineer Professional最適に合格 🦢 ⏩ www.goshiken.com ⏪には無料の▛ Certified-Data-Engineer-Professional ▟問題集がありますCertified-Data-Engineer-Professional最新テスト
- Certified-Data-Engineer-Professional赤本合格率 😌 Certified-Data-Engineer-Professional対応問題集 🎌 Certified-Data-Engineer-Professional対応問題集 🥊 ⮆ www.passtest.jp ⮄に移動し、☀ Certified-Data-Engineer-Professional ️☀️を検索して、無料でダウンロード可能な試験資料を探しますCertified-Data-Engineer-Professional赤本合格率
- Certified-Data-Engineer-Professional日本語受験攻略 🌈 Certified-Data-Engineer-Professional日本語受験攻略 🪁 Certified-Data-Engineer-Professional赤本合格率 🦞 ウェブサイト➡ www.goshiken.com ️⬅️を開き、➥ Certified-Data-Engineer-Professional 🡄を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional技術内容
- Certified-Data-Engineer-Professionalソフトウエア ℹ Certified-Data-Engineer-Professional認証pdf資料 ❗ Certified-Data-Engineer-Professional認証pdf資料 🍘 ⏩ www.xhs1991.com ⏪に移動し、➽ Certified-Data-Engineer-Professional 🢪を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional専門知識訓練
- Certified-Data-Engineer-Professional認証pdf資料 👛 Certified-Data-Engineer-Professional模擬練習 😫 Certified-Data-Engineer-Professional模擬練習 📃 ▷ www.goshiken.com ◁サイトにて最新➽ Certified-Data-Engineer-Professional 🢪問題集をダウンロードCertified-Data-Engineer-Professional最新資料
- 最新のDatabricks Certified-Data-Engineer-Professional合格対策 - 合格スムーズCertified-Data-Engineer-Professional的中合格問題集 | 便利なCertified-Data-Engineer-Professional最新対策問題 💗 ウェブサイト⇛ www.mogiexam.com ⇚を開き、( Certified-Data-Engineer-Professional )を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional資格関連題
- 試験の準備方法-素敵なCertified-Data-Engineer-Professional合格対策試験-最新のCertified-Data-Engineer-Professional的中合格問題集 🕋 ☀ www.goshiken.com ️☀️から➠ Certified-Data-Engineer-Professional 🠰を検索して、試験資料を無料でダウンロードしてくださいCertified-Data-Engineer-Professionalソフトウエア
- 試験の準備方法-素敵なCertified-Data-Engineer-Professional合格対策試験-最新のCertified-Data-Engineer-Professional的中合格問題集 💄 今すぐ⏩ www.shikenpass.com ⏪で➠ Certified-Data-Engineer-Professional 🠰を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional専門知識訓練
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, tooter.in, www.fotor.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes