What's more, part of that VCETorrent Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1u1Y57QyTplJiSibCSNJ8_OdRz03G8f6U
The price for Professional-Machine-Learning-Engineer learning materials is quite reasonable, and no matter you are a student or you are an employee, you can afford them. Besides, we offer you free demo to have a try, and through free demo, you can know some detailed information of Professional-Machine-Learning-Engineer Exam Dumps. With experienced experts to compile and verify, Professional-Machine-Learning-Engineer learning materials are high quality. Besides, Professional-Machine-Learning-Engineer exam dumps contain both questions and answers, and you check your answers quickly after practicing.
Google Professional Machine Learning Engineer Certification Exam has become increasingly popular among individuals who are looking to enhance their career in machine learning engineering. Google Professional Machine Learning Engineer certification is recognized globally and is highly valued by employers. It helps professionals to develop their skills and knowledge in the field of machine learning engineering and provides them with an opportunity to showcase their expertise to potential employers. With the increasing demand for machine learning engineers, obtaining this certification can help individuals to stand out in the competitive job market.
The Google Professional-Machine-Learning-Engineer Exam consists of a series of multiple-choice questions and practical tasks that are designed to test candidates' knowledge and skills in machine learning. Candidates must demonstrate a deep understanding of the principles and techniques of machine learning, as well as a strong ability to apply these principles to real-world problems.
>> Professional-Machine-Learning-Engineer Most Reliable Questions <<
If your problems on studying the Professional-Machine-Learning-Engineer learning quiz are divulging during the review you can pick out the difficult one and focus on those parts. You can re-practice or iterate the content of our Professional-Machine-Learning-Engineer exam questions if you have not mastered the points of knowledge once. Especially for exam candidates who are scanty of resourceful products, our Professional-Machine-Learning-Engineer study prep can whittle down distention of disagreement and reach whole acceptance.
Google Professional Machine Learning Engineer Exam is a comprehensive program that covers a wide range of topics related to machine learning. Professional-Machine-Learning-Engineer Exam consists of multiple-choice questions, coding challenges, and hands-on tasks that evaluate the candidate's practical skills and knowledge. By earning this certification, candidates can demonstrate their proficiency in machine learning and stand out in a competitive job market.
NEW QUESTION # 271
You have built a model that is trained on data stored in Parquet files. You access the data through a Hive table hosted on Google Cloud. You preprocessed these data with PySpark and exported it as a CSV file into Cloud Storage. After preprocessing, you execute additional steps to train and evaluate your model. You want to parametrize this model training in Kubeflow Pipelines. What should you do?
Answer: C
Explanation:
The best option for parametrizing the model training in Kubeflow Pipelines is to add a ContainerOp to the pipeline that spins a Dataproc cluster, runs a transformation, and then saves the transformed data in Cloud Storage. This option has the following advantages:
* It allows the data transformation to be performed as part of the Kubeflow Pipeline, which can ensure the consistency and reproducibility of the data processing and the model training. By adding a ContainerOp to the pipeline, you can define the parameters and the logic of the data transformation step, and integrate it with the other steps of the pipeline, such as the model training and evaluation.
* It leverages the scalability and performance of Dataproc, which is a fully managed service that runs Apache Spark and Apache Hadoop clusters on Google Cloud. By spinning a Dataproc cluster, you can run the PySpark transformation on the Parquet files stored in the Hive table, and take advantage of the parallelism and speed of Spark. Dataproc also supports various features and integrations, such as autoscaling, preemptible VMs, and connectors to other Google Cloud services, that can optimize the data processing and reduce the cost.
* It simplifies the data storage and access, as the transformed data is saved in Cloud Storage, which is a scalable, durable, and secure object storage service. By saving the transformed data in Cloud Storage,
* you can avoid the overhead and complexity of managing the data in the Hive table or the Parquet files.
Moreover, you can easily access the transformed data from Cloud Storage, using various tools and frameworks, such as TensorFlow, BigQuery, or Vertex AI.
The other options are less optimal for the following reasons:
* Option A: Removing the data transformation step from the pipeline eliminates the parametrization of the model training, as the data processing and the model training are decoupled and independent. This option requires running the PySpark transformation separately from the Kubeflow Pipeline, which can introduce inconsistency and unreproducibility in the data processing and the model training. Moreover, this option requires managing the data in the Hive table or the Parquet files, which can be cumbersome and inefficient.
* Option B: Containerizing the PySpark transformation step, and adding it to the pipeline introduces additional complexity and overhead. This option requires creating and maintaining a Docker image that can run the PySpark transformation, which can be challenging and time-consuming. Moreover, this option requires running the PySpark transformation on a single container, which can be slow and inefficient, as it does not leverage the parallelism and performance of Spark.
* Option D: Deploying Apache Spark at a separate node pool in a Google Kubernetes Engine cluster, and adding a ContainerOp to the pipeline that invokes a corresponding transformation job for this Spark instance introduces additional complexity and cost. This option requires creating and managing a separate node pool in a Google Kubernetes Engine cluster, which is a fully managed service that runs Kubernetes clusters on Google Cloud. Moreover, this option requires deploying and running Apache Spark on the node pool, which can be tedious and costly, as it requires configuring and maintaining the Spark cluster, and paying for the node pool usage.
NEW QUESTION # 272
You are training a custom language model for your company using a large dataset. You plan to use the Reduction Server strategy on Vertex Al. You need to configure the worker pools of the distributed training job. What should you do?
Answer: B
NEW QUESTION # 273
You have deployed a model on Vertex AI for real-time inference. During an online prediction request, you get an "Out of Memory" error. What should you do?
Answer: A
Explanation:
* Option A is incorrect because using batch prediction mode instead of online mode does not solve the
"Out of Memory" error, but rather changes the latency and throughput of the prediction service. Batch prediction mode is suitable for large-scale, asynchronous, and non-urgent predictions, while online prediction mode is suitable for low-latency, synchronous, and real-time predictions1.
* Option B is correct because sending the request again with a smaller batch of instances can reduce the memory consumption of the prediction service and avoid the "Out of Memory" error. The batch size is the number of instances that are processed together in one request. A smaller batch size means less data to load into memory at once2.
* Option C is incorrect because using base64 to encode your data before using it for prediction does not reduce the memory consumption of the prediction service, but rather increases it. Base64 encoding is a way of representing binary data as ASCII characters, which increases the size of the data by about
33%3. Base64 encoding is only required for certain data types, such as images and audio, that cannot be represented as JSON or CSV4.
* Option D is incorrect because applying for a quota increase for the number of prediction requests does not solve the "Out of Memory" error, but rather increases the number of requests that can be sent to the prediction service per day. Quotas are limits on the usage of Google Cloud resources, such as CPU, memory, disk, and network5. Quotas do not affect the performance of the prediction service, but rather the availability and cost of the service.
References:
* Choosing between online and batch prediction
* Online prediction input data
* Base64 encoding
* Preparing data for prediction
* Quotas and limits
NEW QUESTION # 274
You work with a team of researchers to develop state-of-the-art algorithms for financial analysis. Your team develops and debugs complex models in TensorFlow. You want to maintain the ease of debugging while also reducing the model training time. How should you set up your training environment?
Answer: A
Explanation:
A TPU VM is a virtual machine that has direct access to a Cloud TPU device. TPU VMs provide a simpler and more flexible way to use Cloud TPUs, as they eliminate the need for a separate host VM and network setup. TPU VMs also support interactive debugging tools such as TensorFlow Debugger (tfdbg) and Python Debugger (pdb), which can help researchers develop and troubleshoot complex models. A v3-8 TPU VM has 8 TPU cores, which can provide high performance and scalability for training large models. SSHing into the TPU VM allows the user to run and debug the TensorFlow code directly on the TPU device, without any network overhead or data transfer issues. Reference:
1: TPU VMs Overview
2: TPU VMs Quickstart
3: Debugging TensorFlow Models on Cloud TPUs
NEW QUESTION # 275
Given the following confusion matrix for a movie classification model, what is the true class frequency for Romance and the predicted class frequency for Adventure?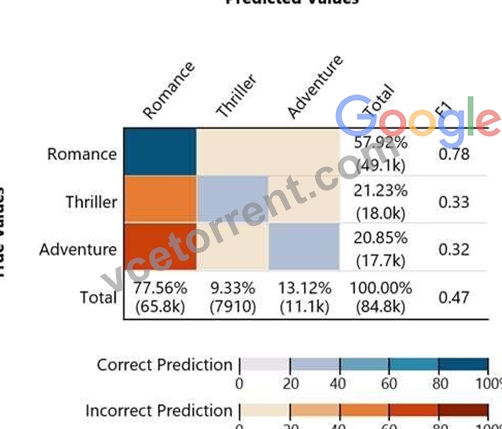
Answer: D
NEW QUESTION # 276
......
Professional-Machine-Learning-Engineer Valid Exam Answers: https://www.vcetorrent.com/Professional-Machine-Learning-Engineer-valid-vce-torrent.html
DOWNLOAD the newest VCETorrent Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1u1Y57QyTplJiSibCSNJ8_OdRz03G8f6U