Professional-Data-Engineer Latest Exam Practice | Training Professional-Data-Engineer Kit
BONUS!!! Download part of TestPassKing Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1pqXDR2GZvN2BulgFfj3Aw69GWtPA0DyB
According to the years of the test data analysis, we are very confident that almost all customers using our products passed the exam, and in o the Professional-Data-Engineer question guide, with the help of their extremely easily passed the exam and obtained qualification certificate. We firmly believe that you can do it! Therefore, the choice of the Professional-Data-Engineer real study dumps are to choose a guarantee, which can give you the opportunity to get a promotion and a raise in the future, even create conditions for your future life. And, more importantly, when you can show your talent in these areas, naturally, your social circle is constantly expanding, you will be more and more with your same interests and can impact your career development of outstanding people. Since there is such a high rate of return, why hesitate to buy the Professional-Data-Engineer Exam Questions?
| Section | Weight | Objectives |
|---|
| Topic 1: Operationalizing machine learning models | 20% | - Deploying and maintaining ML models
- 1. Optimizing model performance and cost
- 2. Model serving and monitoring
- Preparing data for ML
- 1. Feature engineering and data preparation
- 2. Handling structured and unstructured data
|
| Topic 2: Ensuring solution quality and reliability | 17% | - Troubleshooting and optimization
- 1. Optimizing queries and workloads
- 2. Diagnosing performance issues
- Testing and validating data systems
- 1. Data quality validation
- 2. Performance and scalability testing
|
| Topic 3: Designing data processing systems | 20% | - Designing for regulatory and security requirements
- 1. Implementing access control and data protection
- 2. Ensuring data privacy and compliance
- Designing for business requirements
- 1. Selecting appropriate storage solutions
- 2. Designing for reliability and fault tolerance
- 3. Designing for scalability and elasticity
|
| Topic 4: Building and operationalizing data processing systems | 25% | - Deploying and managing systems
- 1. Monitoring and logging data processes
- 2. Managing infrastructure and resources
- Building data pipelines
- 1. Transforming and cleaning data
- 2. Ingesting data from various sources
- 3. Orchestrating data workflows
|
| Topic 5: Maintaining and automating data workloads | 18% | - Automation and repeatability
- 1. Automating deployment and updates
- 2. Implementing CI/CD for data systems
- Resource optimization
- 1. Choosing appropriate compute and storage options
- 2. Cost management and resource allocation
|
>> Professional-Data-Engineer Latest Exam Practice <<
Training Professional-Data-Engineer Kit - Pdf Professional-Data-Engineer Dumps
If you want to get Professional-Data-Engineer certification, you may need to spend a lot of time and energy. With our Professional-Data-Engineer study materials, you can save a lot of time and effort. We know that you must have a lot of other things to do, and our Professional-Data-Engineer learning guide will relieve your concerns in some ways. We can claim that if you study with our Professional-Data-Engineer practice engine for 20 to 30 hours, you will be confident to pass the exam by the first attempt.
Google Certified Professional Data Engineer Exam Sample Questions (Q410-Q415):
NEW QUESTION # 410
You are deploying 10,000 new Internet of Things devices to collect temperature data in your warehouses globally. You need to process, store and analyze these very large datasets in real time. What should you do?
- A. Send the data to Google Cloud Datastore and then export to BigQuery.
- B. Send the data to Cloud Storage and then spin up an Apache Hadoop cluster as needed in Google Cloud Dataproc whenever analysis is required.
- C. Export logs in batch to Google Cloud Storage and then spin up a Google Cloud SQL instance, import the data from Cloud Storage, and run an analysis as needed.
- D. Send the data to Google Cloud Pub/Sub, stream Cloud Pub/Sub to Google Cloud Dataflow, and store the data in Google BigQuery.
Answer: D
Explanation:
Pubsub for realtime, Dataflow for pipeline, Bigquery for analytics.
NEW QUESTION # 411
You want to archive data in Cloud Storage. Because some data is very sensitive, you want to use the "Trust No One" (TNO) approach to encrypt your data to prevent the cloud provider staff from decrypting your data.
What should you do?
- A. Use gcloud kms keys create to create a symmetric key. Then use gcloud kms encrypt to encrypt each archival file with the key and unique additional authenticated data (AAD). Use gsutil cp to upload each encrypted file to the Cloud Storage bucket, and keep the AAD outside of Google Cloud.
- B. Specify customer-supplied encryption key (CSEK) in the .boto configuration file. Use gsutil cp to upload each archival file to the Cloud Storage bucket. Save the CSEK in a different project that only the security team can access.
- C. Specify customer-supplied encryption key (CSEK) in the .boto configuration file. Use gsutil cp to upload each archival file to the Cloud Storage bucket. Save the CSEK in Cloud Memorystore as permanent storage of the secret.
- D. Use gcloud kms keys create to create a symmetric key. Then use gcloud kms encrypt to encrypt each archival file with the key. Use gsutil cp to upload each encrypted file to the Cloud Storage bucket.
Manually destroy the key previously used for encryption, and rotate the key once.
Answer: D
NEW QUESTION # 412
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie' the property 'actors' and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname> ordered by date_released or all movies with tag=Comedy ordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
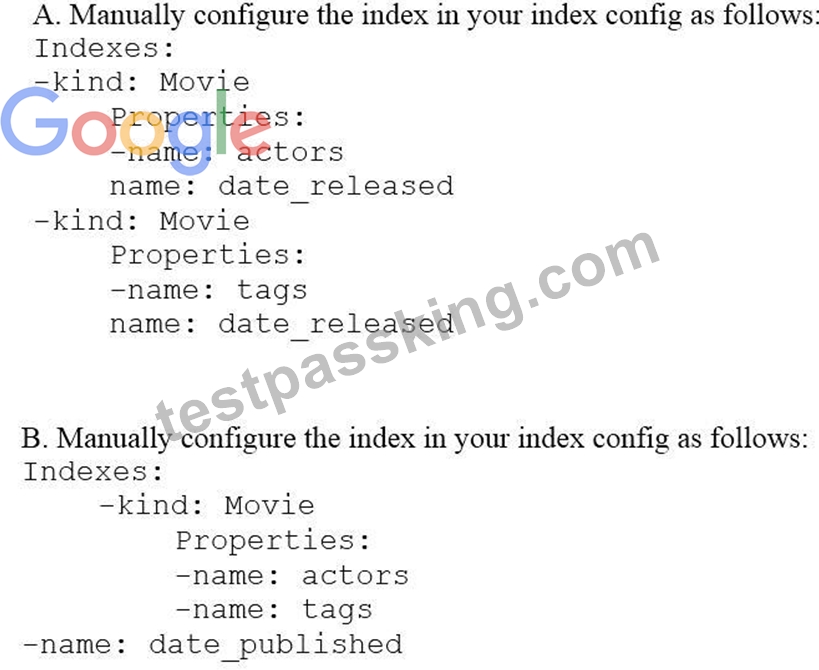
- A. Option C
- B. Option B.
- C. Option D
- D. Option A
Answer: D
NEW QUESTION # 413
You are deploying 10,000 new Internet of Things devices to collect temperature data in your warehouses globally. You need to process, store and analyze these very large datasets in real time.
What should you do?
- A. Send the data to Google Cloud Datastore and then export to BigQuery.
- B. Send the data to Cloud Storage and then spin up an Apache Hadoop cluster as needed in Google Cloud Dataproc whenever analysis is required.
- C. Export logs in batch to Google Cloud Storage and then spin up a Google Cloud SQL instance, import the data from Cloud Storage, and run an analysis as needed.
- D. Send the data to Google Cloud Pub/Sub, stream Cloud Pub/Sub to Google Cloud Dataflow, and store the data in Google BigQuery.
Answer: D
Explanation:
Pubsub for realtime, Dataflow for pipeline, Bigquery for analytics.
NEW QUESTION # 414
You used Cloud Dataprep to create a recipe on a sample of data in a BigQuery table. You want to reuse this recipe on a daily upload of data with the same schema, after the load job with variable execution time completes. What should you do?
- A. Export the recipe as a Cloud Dataprep template, and create a job in Cloud Scheduler.
- B. Create an App Engine cron job to schedule the execution of the Cloud Dataprep job.
- C. Create a cron schedule in Cloud Dataprep.
- D. Export the Cloud Dataprep job as a Cloud Dataflow template, and incorporate it into a Cloud Composer job.
Answer: D
Explanation:
Topic 1, Flowlogistic Case Study
Company Overview
Flowlogistic is a leading logistics and supply chain provider. They help businesses throughout the world manage their resources and transport them to their final destination. The company has grown rapidly, expanding their offerings to include rail, truck, aircraft, and oceanic shipping.
Company Background
The company started as a regional trucking company, and then expanded into other logistics market. Because they have not updated their infrastructure, managing and tracking orders and shipments has become a bottleneck. To improve operations, Flowlogistic developed proprietary technology for tracking shipments in real time at the parcel level. However, they are unable to deploy it because their technology stack, based on Apache Kafka, cannot support the processing volume. In addition, Flowlogistic wants to further analyze their orders and shipments to determine how best to deploy their resources.
Solution Concept
Flowlogistic wants to implement two concepts using the cloud:
Use their proprietary technology in a real-time inventory-tracking system that indicates the location of their loads Perform analytics on all their orders and shipment logs, which contain both structured and unstructured data, to determine how best to deploy resources, which markets to expand info. They also want to use predictive analytics to learn earlier when a shipment will be delayed.
Existing Technical Environment
Flowlogistic architecture resides in a single data center:
Databases
8 physical servers in 2 clusters
SQL Server - user data, inventory, static data
3 physical servers
Cassandra - metadata, tracking messages
10 Kafka servers - tracking message aggregation and batch insert
Application servers - customer front end, middleware for order/customs
60 virtual machines across 20 physical servers
Tomcat - Java services
Nginx - static content
Batch servers
Storage appliances
iSCSI for virtual machine (VM) hosts
Fibre Channel storage area network (FC SAN) - SQL server storage
Network-attached storage (NAS) image storage, logs, backups
Apache Hadoop /Spark servers
Core Data Lake
Data analysis workloads
20 miscellaneous servers
Jenkins, monitoring, bastion hosts,
Business Requirements
Build a reliable and reproducible environment with scaled panty of production.
Aggregate data in a centralized Data Lake for analysis
Use historical data to perform predictive analytics on future shipments Accurately track every shipment worldwide using proprietary technology Improve business agility and speed of innovation through rapid provisioning of new resources Analyze and optimize architecture for performance in the cloud Migrate fully to the cloud if all other requirements are met Technical Requirements Handle both streaming and batch data Migrate existing Hadoop workloads Ensure architecture is scalable and elastic to meet the changing demands of the company.
Use managed services whenever possible
Encrypt data flight and at rest
Connect a VPN between the production data center and cloud environment
SEO Statement
We have grown so quickly that our inability to upgrade our infrastructure is really hampering further growth and efficiency. We are efficient at moving shipments around the world, but we are inefficient at moving data around.
We need to organize our information so we can more easily understand where our customers are and what they are shipping.
CTO Statement
IT has never been a priority for us, so as our data has grown, we have not invested enough in our technology. I have a good staff to manage IT, but they are so busy managing our infrastructure that I cannot get them to do the things that really matter, such as organizing our data, building the analytics, and figuring out how to implement the CFO' s tracking technology.
CFO Statement
Part of our competitive advantage is that we penalize ourselves for late shipments and deliveries. Knowing where out shipments are at all times has a direct correlation to our bottom line and profitability. Additionally, I don't want to commit capital to building out a server environment.
NEW QUESTION # 415
......
The TestPassKing is one of the leading Google Professional-Data-Engineer exam preparation study material providers in the market. The TestPassKing offers valid, updated, and real Google Certified Professional Data Engineer Exam Professional-Data-Engineer exam practice test questions that assist you in your Professional-Data-Engineer Exam Preparation. The Google Professional-Data-Engineer exam questions are designed and verified by experienced and qualified Google exam trainers.
Training Professional-Data-Engineer Kit: https://www.testpassking.com/Professional-Data-Engineer-exam-testking-pass.html
- Realistic Professional-Data-Engineer Latest Exam Practice - Google Certified Professional Data Engineer Exam 100% Pass Quiz 🟤 Search for { Professional-Data-Engineer } and obtain a free download on ➥ www.vce4dumps.com 🡄 🙊Training Professional-Data-Engineer For Exam
- Professional-Data-Engineer Latest Exam Practice - High Pass-Rate Google Training Professional-Data-Engineer Kit: Google Certified Professional Data Engineer Exam 🌗 Open website { www.pdfvce.com } and search for ➽ Professional-Data-Engineer 🢪 for free download 🅾Professional-Data-Engineer Valid Exam Experience
- Free Professional-Data-Engineer Dumps 🏠 Free Professional-Data-Engineer Dumps 🧷 Professional-Data-Engineer Valid Exam Experience 🕗 Open ☀ www.torrentvce.com ️☀️ enter ▷ Professional-Data-Engineer ◁ and obtain a free download 🍗Valid Professional-Data-Engineer Exam Sample
- Professional-Data-Engineer Study Center ❗ Professional-Data-Engineer Intereactive Testing Engine 😋 Simulation Professional-Data-Engineer Questions 🚘 Download ➡ Professional-Data-Engineer ️⬅️ for free by simply searching on ▶ www.pdfvce.com ◀ 🪒Exam Professional-Data-Engineer Flashcards
- Valid Professional-Data-Engineer Exam Sample 💁 Professional-Data-Engineer Valid Exam Experience 🔽 Professional-Data-Engineer Study Center 🧀 The page for free download of 【 Professional-Data-Engineer 】 on ( www.vce4dumps.com ) will open immediately 😨Valid Professional-Data-Engineer Exam Sample
- Training Professional-Data-Engineer For Exam 🍀 Professional-Data-Engineer Reliable Exam Prep 🥒 Reliable Professional-Data-Engineer Test Notes 🐎 Search for ▛ Professional-Data-Engineer ▟ and download it for free on 「 www.pdfvce.com 」 website 🚝Professional-Data-Engineer Valid Exam Dumps
- Pdf Professional-Data-Engineer Dumps ⬆ Professional-Data-Engineer Valid Exam Experience 👋 Professional-Data-Engineer Valid Exam Dumps 🖌 Easily obtain ▶ Professional-Data-Engineer ◀ for free download through ⮆ www.prep4away.com ⮄ 🍕Professional-Data-Engineer Reliable Exam Prep
- Simulation Professional-Data-Engineer Questions 🏂 Dumps Professional-Data-Engineer Download 🦁 New Professional-Data-Engineer Exam Sample 🌺 Search for [ Professional-Data-Engineer ] on ⏩ www.pdfvce.com ⏪ immediately to obtain a free download 🔌Free Professional-Data-Engineer Dumps
- Actual Professional-Data-Engineer Google Certified Professional Data Engineer Exam Exam Questions with accurate answers 🥣 Simply search for 《 Professional-Data-Engineer 》 for free download on ▷ www.prepawayexam.com ◁ 🌌Free Professional-Data-Engineer Dumps
- Valid Professional-Data-Engineer Test Labs 🚼 Professional-Data-Engineer Valid Exam Experience 🍪 Reliable Professional-Data-Engineer Test Cram ✨ Download [ Professional-Data-Engineer ] for free by simply entering ➤ www.pdfvce.com ⮘ website ✋Professional-Data-Engineer Current Exam Content
- Google Professional-Data-Engineer Questions – Best Way To Clear The Exam [2026] 🕚 Simply search for ⇛ Professional-Data-Engineer ⇚ for free download on ⮆ www.prepawaypdf.com ⮄ 💑Professional-Data-Engineer Valid Exam Experience
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, wanderlog.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.kickstarter.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, jobs.electronicsweekly.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of TestPassKing Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1pqXDR2GZvN2BulgFfj3Aw69GWtPA0DyB