弊社Microsoftの資料を使用すると、最短でDeveloping AI-Enabled Database Solutionsの最高の質問トレントを習得し、他のことを完了するための時間とエネルギーを節約できます。最も重要なのは、DP-800学習資料を安全にダウンロード、インストール、Pass4Test使用できることです。製品にウイルスがないことを保証できます。それだけでなく、最高のサービスと最高のDeveloping AI-Enabled Database Solutions試験トレントを提供し、製品の品質が良好であることを保証できます。そのため、購入後はお気軽にご利用ください。お金を無駄にさせません。
| Section | Weight | Objectives |
|---|---|---|
| Design and develop database solutions | 35-40% | - Design database solutions
|
| Secure, optimize, and deploy database solutions | 35-40% | - Deploy and maintain solutions
|
| Implement AI capabilities in database solutions | 25-30% | - Integrate AI models and services
|
Microsoft知識ベースの経済の支配下で、私たちは変化する世界に歩調を合わせ、まともな仕事とより高い生活水準を追求して知識を更新しなければなりません。 この状況では、ポケットにDP-800認定を取得すると、Pass4Test労働市場での競争上の優位性を完全に高め、他の求職者との差別化を図ることができます。 したがって、当社のDP-800学習ガイドは、夢を実現するための献身的な支援を提供します。 そして、DP-800試験の質問で20〜30時間学習Developing AI-Enabled Database Solutionsした後にのみ、DP-800試験に合格することができます。
質問 # 86
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.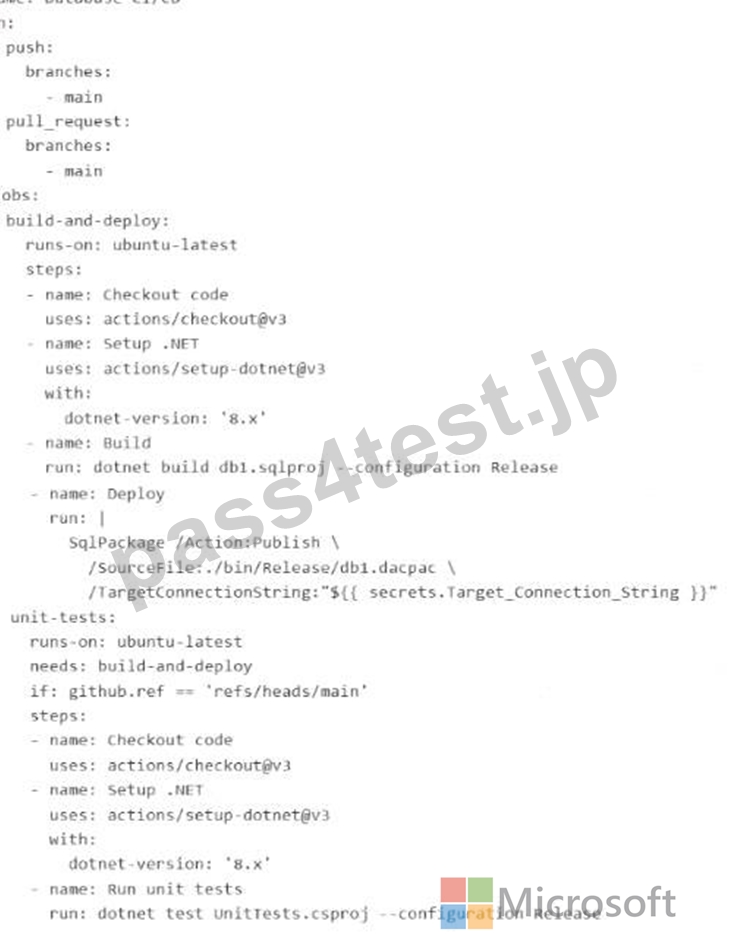
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.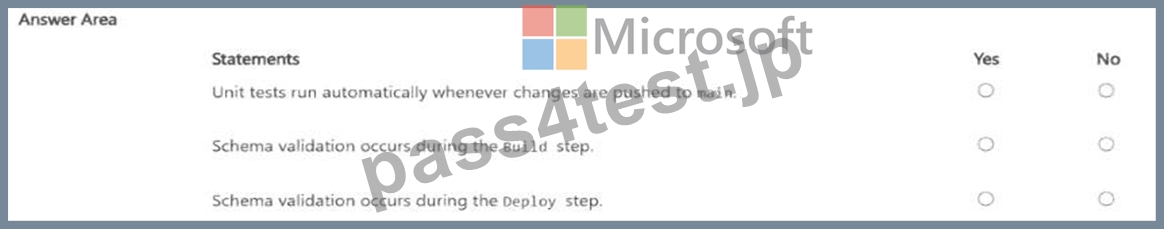
正解:
解説: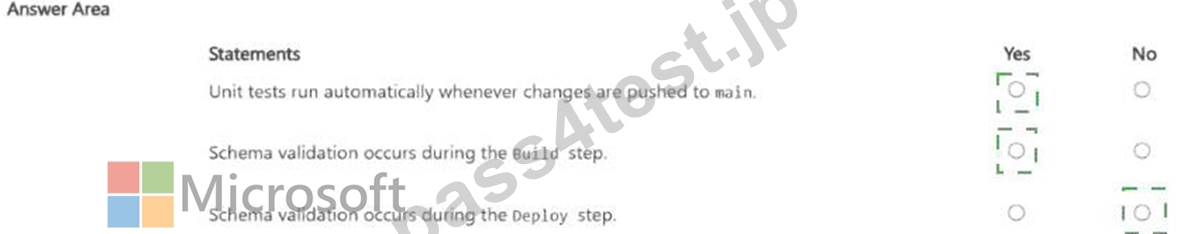
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
質問 # 87
Your development team uses GitHub Copilot Chat in Microsoft SQL Server Management Studio (SSMS) to generate and run Transact-SQL queries against an Azure SQL database named DB1 DB1 contains tables that store sensitive customer data.
You need to ensure that any Transact SQL queries that run from GitHub Copilot Chat In SSMS are restricted by the same permissions as the developer ' s database login.
What prevents the GitHub Copilot Chat-run queries from accessing data beyond the developer ' s access?
正解:D
解説:
The correct answer is B . Microsoft's SSMS Copilot documentation states that queries from Copilot in SSMS are executed under the context of the user's login and permissions , and that there are no separate permissions for Copilot in SSMS . That means Copilot-run Transact-SQL cannot access more data than the developer's own database principal is already allowed to access.
That is why the other options are incorrect:
* A is wrong because Copilot does not use a separate read-only sandbox in place of database permissions.
* C is wrong because enforcement is not a client-side filtering trick; it is enforced by the database security context of the current login.
* D is wrong because Copilot does not apply a different RLS model from the developer; it simply runs under the same login context.
So the security boundary is the developer's existing database identity and permissions .
質問 # 88
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.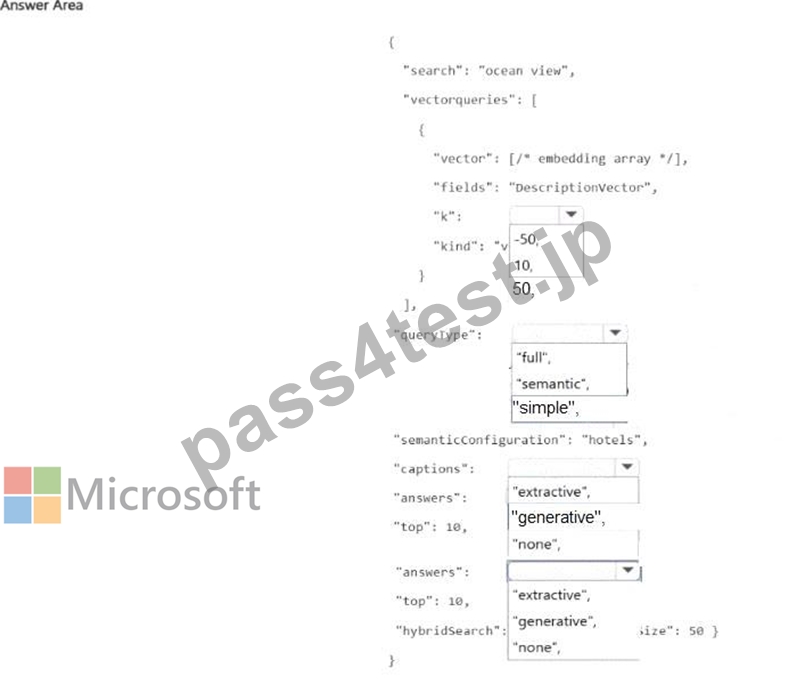
正解:
解説: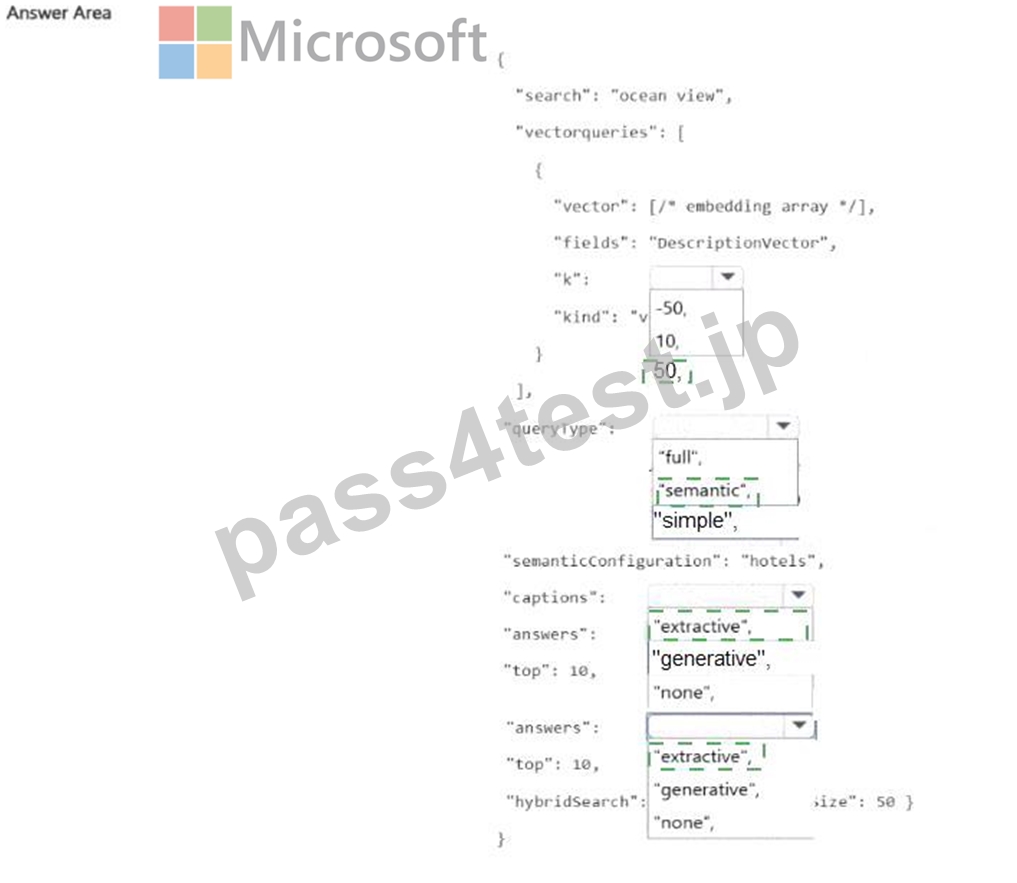
Explanation: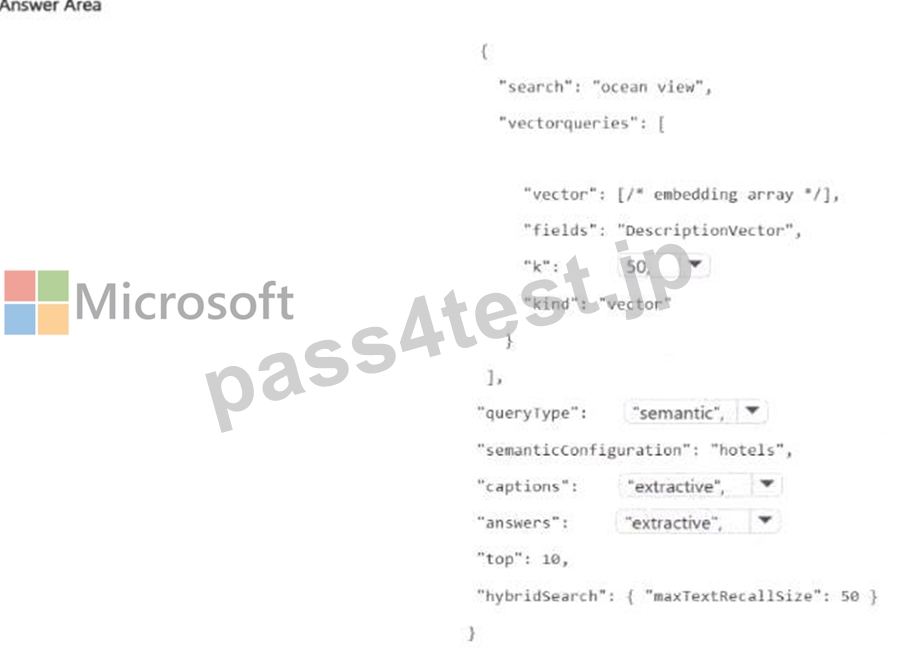
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
質問 # 89
You have an Azure SQL database.
You need to create a scalar user-defined function (UDF) that returns the number of whole years between an input parameter named 0orderDate and the current date/time as a single positive integer. The function must be created in Azure SQL Database. You write the following code.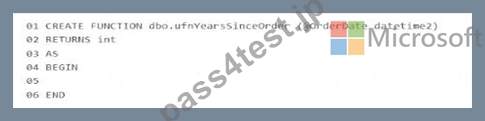
What should you insert at line 05?
正解:B
解説:
The correct answer is D because the scalar UDF must return the number of whole years from the input
@OrderDate to the current date/time as a single positive integer . The correct DATEDIFF order is:
DATEDIFF(year, @OrderDate, GETDATE())
Microsoft documents that DATEDIFF(datepart, startdate, enddate) returns the count of specified datepart boundaries crossed between the start and end values. Since @OrderDate is the earlier date and GETDATE() is the later date, this ordering returns a positive result for past order dates.
The other choices are incorrect:
* A reverses the arguments and would return a negative value for a past order date.
* B is missing RETURN, and converting month difference to years by dividing by 12 is not the direct whole-year expression the question asks for.
* C subtracts year parts only, which can be off around anniversary boundaries because it ignores whether the full year has actually elapsed.
So the correct insertion at line 05 is:
RETURN DATEDIFF(year, @OrderDate, GETDATE());
質問 # 90
Hotspot Question
You have an Azure SQL database that contains a table named stores. stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
- Uses full-text search on description for the keyword portion
- Returns the top 20 results based on a combined score that uses a
weighted formula of 60% vector distance and 40% full-text rank
How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.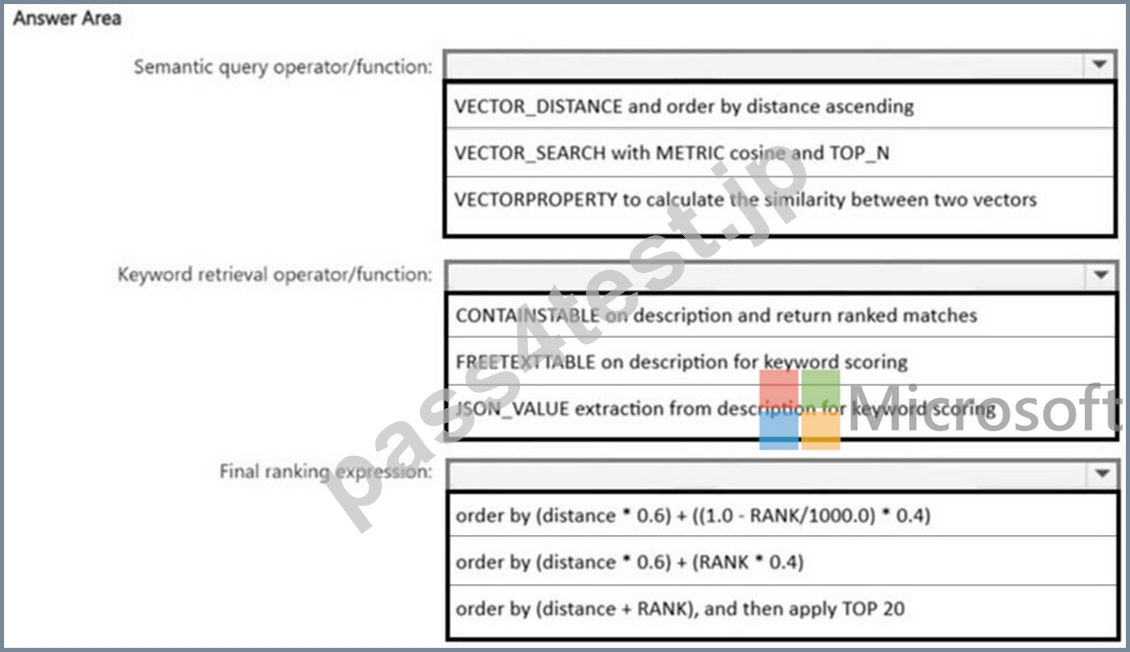
正解:
解説: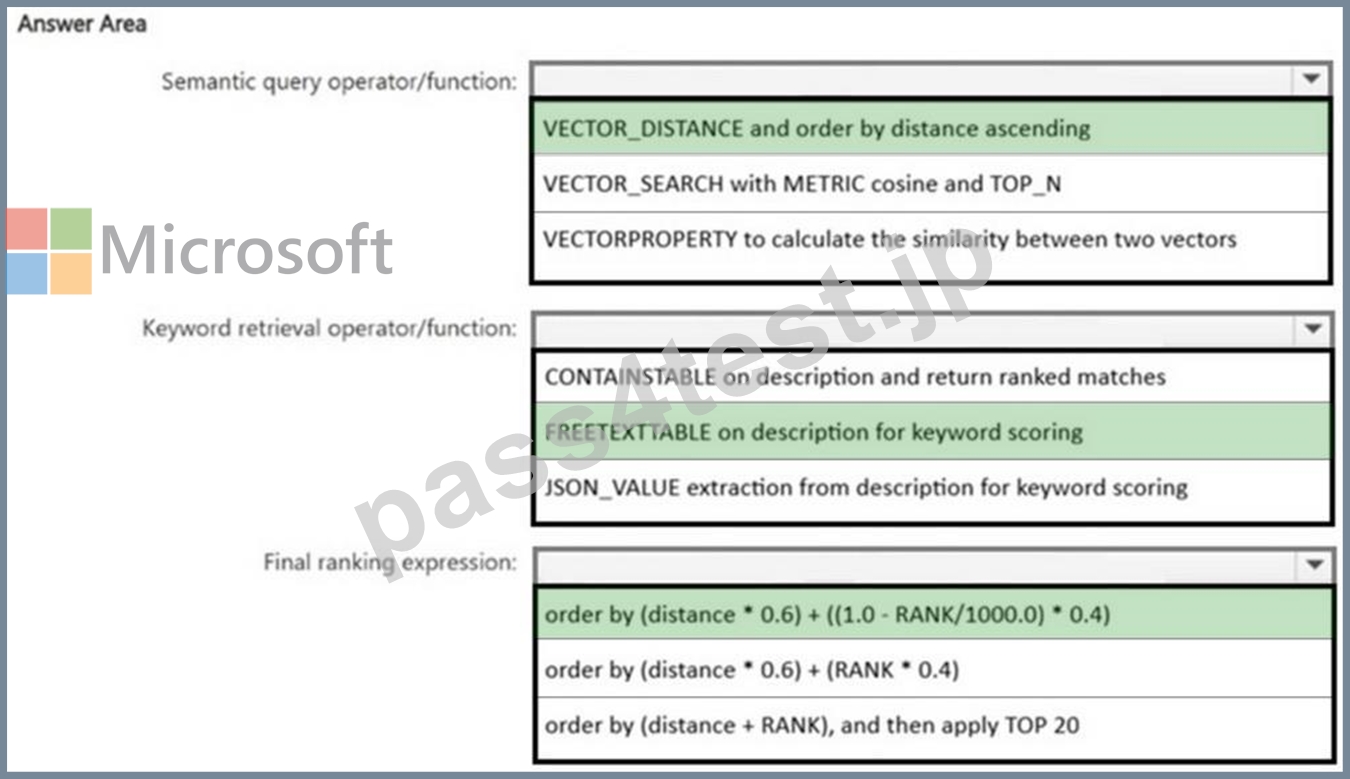
質問 # 91
......
どのようにすればもっと楽にMicrosoftのDP-800認定試験に合格することができるかについて考えたことがありますか。試験に合格する秘密を見つけましたか。それを行う方法がわからない場合、私は教えてあげましょう。実際には、認定試験に合格できる方法が多くあります。試験に関連する知識を一生懸命習得することがただ一つの方法です。今はそのようにしていますか。しかし、これが一番時間を無駄にして、望ましい効果を得られない方法です。それに、毎日仕事で忙しいあなたは、恐らく試験に準備する充分な時間がないでしょう。では、Pass4TestのDP-800問題集を試しましょう。この試験参考書はきっとあなたに思えぬ良い結果を与えられます。
DP-800日本語サンプル: https://www.pass4test.jp/DP-800.html