NCP-AII Reliable Exam Online & Test NCP-AII Vce Free

P.S. Free 2026 NVIDIA NCP-AII dumps are available on Google Drive shared by CertkingdomPDF: https://drive.google.com/open?id=1cp31VfFdVxB-lH44SFojgyJoCwAoxrs1
There are three different versions provided by our company. Every version is very convenient and practical. The three different versions of our NCP-AII study torrent have different function. We believe that you must find the version that is suitable for you. Now I am willing to show you the special function of the PDF version of NCP-AII test torrent. If you prefer to read paper materials rather than learning on computers, the PDF version of our NVIDIA AI Infrastructure guide torrent must the best choice for you. Because the study materials on the PDF version are printable, you can download our NCP-AII study torrent by the PDF version and print it on papers. We believe that it will be very helpful for you to protect your eyes. In addition, the PDF version also has many other special functions. If you use the PDF version of our NCP-AII test torrent, you will find more special function about the PDF version.
| Topic | Details |
|---|
| Topic 1 | - Control Plane Installation and Configuration: Covers deploying the software stack including Base Command Manager, OS, Slurm
- Enroot
- Pyxis, NVIDIA GPU and DOCA drivers, container toolkit, and NGC CLI.
|
| Topic 2 | - Cluster Test and Verification: Covers full cluster validation through HPL and NCCL benchmarks, NVLink and fabric bandwidth tests, cable and firmware checks, and burn-in testing using HPL, NCCL, and NeMo.
|
| Topic 3 | - Physical Layer Management: Covers configuring BlueField network platform devices and setting up Multi-Instance GPU (MIG) partitioning for AI and HPC workloads.
|
| Topic 4 | - Troubleshoot and Optimize: Covers identifying and replacing faulty hardware components such as GPUs, network cards, and power supplies, along with performance optimization for AMD
- Intel servers and storage.
|
| Topic 5 | - System and Server Bring-up: Covers end-to-end physical setup of GPU-based AI infrastructure, including BMC
- OOB
- TPM configuration, firmware upgrades, hardware installation, and power and cooling validation to ensure servers are workload-ready.
|
>> NCP-AII Reliable Exam Online <<
NVIDIA AI Infrastructure Training Material - NCP-AII Updated Torrent & NVIDIA AI Infrastructure Reliable Practice
We can confidently say that Our NCP-AII training quiz will help you. First of all, our company is constantly improving our products according to the needs of users. If you really want a learning product to help you, our NCP-AII study materials are definitely your best choice, you can't find a product more perfect than it. Second, our NCP-AII learning questions have really helped a lot of people. Looking at the experiences of these seniors, I believe that you will definitely be more determined to pass the NCP-AII exam.
NVIDIA AI Infrastructure Sample Questions (Q53-Q58):
NEW QUESTION # 53
Consider this Python code snippet used for loading data for a deep learning model:
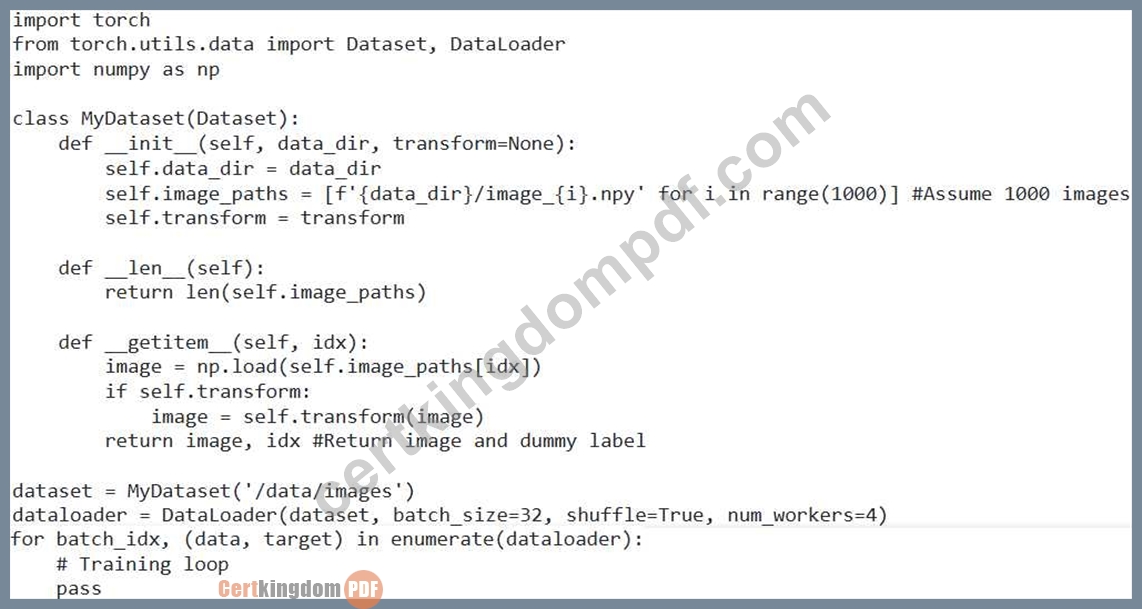
Assuming the images are stored on a remote file system accessed over NFS, and training is slow due to I/O bottlenecks, which change to the 'DataLoader' would MOST directly improve performance?
- A. Implement multithreaded data loading inside _getitem
- B. Decrease 'num workers' to 1.
- C. Set in the DataLoader.
- D. Increase 'num_workers' to a value equal to the number of CPU cores on each training node.
- E. Increase 'batch_size' significantly (e.g., to 256).
Answer: D
Explanation:
Explanation: Increasing 'num_workerS allows the DataLoader to load data in parallel, which can help to overcome the I/O bottleneck when using NFS. Setting it to the number of CPU cores on each training node often yields the best performance. Increasing 'batch_size' helps, but it has diminishing returns if I/O is the primary bottleneck. Decreasing 'num_workers' will worsen the bottleneck. Primarily improves GPU memory transfer performance, not I/O performance from NFS. Multithreading inside _getitem is more complex and can lead to contention if not implemented carefully.
NEW QUESTION # 54
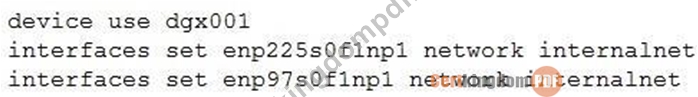
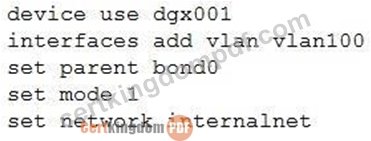
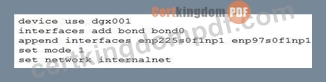
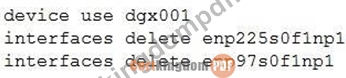
During BCM cluster setup, an engineer must configure bonded network interfaces on DGX nodes for high availability. Which cmsh command sequence properly configures a bond0 interface with two physical NICs?
Answer: C
Explanation:
In BCM cmsh, a bonded interface is created by adding a bond interface, appending the two physical NICs as bond members, setting the bonding mode, and assigning the bond to the appropriate network. This configures bond0 with the two physical interfaces for high availability on the internal network.
NEW QUESTION # 55
During HPL execution on a DGX cluster, the benchmark fails with "not enough memory" errors despite sufficient physical RAM. Which HPL.dat parameter adjustment is most effective?
- A. Disable double-buffering via BCAST parameter.
- B. Increase block size to 6144 to maximize GPU utilization.
- C. Set PMAP to 1 to enable process mapping.
- D. Reduce the problem size while maintaining the same block size.
Answer: D
Explanation:
High-Performance Linpack (HPL) is a memory-intensive benchmark that allocates a large portion of available GPU memory to store the matrix $N$. While a server may have 2TB of physical system RAM, the "not enough memory" error usually refers to theHBM (High Bandwidth Memory)on the GPUs themselves. In a DGX H100 system, each GPU has 80GB of HBM3. If the problem size ($N$) specified in the HPL.dat file is too large, the required memory for the matrix will exceed the aggregate capacity of the GPU memory.
Reducing the problem size ($N$) while maintaining the optimal block size ($NB$) ensures that the problem fits within the GPU memory limits while still pushing the computational units to their peak performance.
Increasing the block size (Option C) would actually increase the memory footprint of certain internal buffers, potentially worsening the issue. Reducing $N$ is the standard procedure to stabilize the run during the initial tuning phase of an AI cluster bring-up.
NEW QUESTION # 56
You have a server equipped with multiple NVIDIA GPUs connected via NVLink. You want to monitor the NVLink bandwidth utilization in real-time. Which tool or method is the most appropriate and accurate for this?
- A. Utilizing DCGM (Data Center GPU Manager) with its NVLink monitoring capabilities.
- B. Using 'nvidia-smi' with the '-display=nvlink' option.
- C. Monitoring network interface traffic using 'iftop' or 'tcpdump' .
- D. Using 'gpustat' .
- E. Parsing the output of *nvprof during a representative workload.
Answer: A
Explanation:
DCGM is specifically designed for monitoring and managing GPUs in data centers, including detailed NVLink statistics in real time.
'nvidia-smi -display=nvlink' provides a snapshot, not real-time data. 'nvprof is a profiling tool and not ideal for continuous monitoring. 'iftop' and 'tcpdump' monitor network traffic, not NVLink. 'gpustat' does not offer the granular NVLink data of DCGM.
NEW QUESTION # 57
You are deploying a cloud-native AI inference service using Kubernetes and NVIDIA GPUs. You need to ensure that GPU resources are efficiently allocated and monitored. Which of the following approaches is MOST effective for achieving this within the Kubernetes environment?
- A. Manually assigning specific GPU devices to pods using hostPath volumes and environment variables.
- B. Overcommitting GPU resources and relying on the Kubernetes scheduler to handle potential out-of-memory (OOM) errors.
- C. Relying solely on Kubernetes' default CPU and memory resource requests and limits, assuming GPU usage will be implicitly managed.
- D. Using the NVIDIA Device Plugin for Kubernetes to advertise GPU resources and utilizing resource requests and limits to schedule pods on nodes with available GPUs.
- E. Deploying a dedicated monitoring agent on each node to track GPU utilization and manually adjusting pod resource requests based on these metrics.
Answer: D
Explanation:
The NVIDIA Device Plugin for Kubernetes is specifically designed to advertise GPU resources to the Kubernetes scheduler, enabling efficient allocation and utilization. Resource requests and limits ensure pods are scheduled on nodes with sufficient GPU capacity, preventing resource contention and 00M errors. Options A, C, D, and E are either ineffective, manual, or potentially lead to instability.
NEW QUESTION # 58
......
This age changes quickly, so we can't be passively, we should be actively to follow the age. When you choose to participate in NCP-AII exam, you are proved to be an active person who wants better development opportunities for yourself. Our CertkingdomPDF is willing to help those active people like you to achieve their goals. The most comprehensive and Latest NCP-AII Exam Materials provided by us can meet all your need to prepare for NCP-AII exam.
Test NCP-AII Vce Free: https://www.certkingdompdf.com/NCP-AII-latest-certkingdom-dumps.html
- 100% Pass 2026 NCP-AII: Updated NVIDIA AI Infrastructure Reliable Exam Online 🍺 Search for { NCP-AII } and download it for free immediately on ☀ www.examdiscuss.com ️☀️ 🕞Certification NCP-AII Book Torrent
- Preparing for the NVIDIA NCP-AII Certification Exam with Examssolutions ⏬ Open ⮆ www.pdfvce.com ⮄ and search for 【 NCP-AII 】 to download exam materials for free ☎New NCP-AII Dumps Questions
- Pass4sure NCP-AII Pass Guide ☯ Reliable NCP-AII Braindumps Book 🏕 Valid NCP-AII Study Plan 🐓 Download ▶ NCP-AII ◀ for free by simply entering ⏩ www.practicevce.com ⏪ website 🎾Valid NCP-AII Exam Guide
- NCP-AII pdf braindumps, NVIDIA NCP-AII real braindumps, NCP-AII valid dumps 🕯 Immediately open { www.pdfvce.com } and search for 【 NCP-AII 】 to obtain a free download 🌘Pass4sure NCP-AII Pass Guide
- Certification NCP-AII Book Torrent 🙎 Pass4sure NCP-AII Pass Guide 🍯 Exam NCP-AII Quizzes 🎓 Download ➠ NCP-AII 🠰 for free by simply entering ⇛ www.practicevce.com ⇚ website 🚨Exam NCP-AII Quizzes
- NCP-AII pdf braindumps, NVIDIA NCP-AII real braindumps, NCP-AII valid dumps 🌠 Search on ▷ www.pdfvce.com ◁ for ▷ NCP-AII ◁ to obtain exam materials for free download 🤵Latest Test NCP-AII Simulations
- Test NCP-AII Questions Vce ↩ Test NCP-AII Questions Vce 🌍 NCP-AII Study Materials Review 🎸 Easily obtain free download of ➠ NCP-AII 🠰 by searching on ▷ www.troytecdumps.com ◁ 🤓New NCP-AII Dumps Questions
- Free PDF Quiz NCP-AII NVIDIA AI Infrastructure Latest Reliable Exam Online 🐎 The page for free download of [ NCP-AII ] on ▷ www.pdfvce.com ◁ will open immediately 💐Test NCP-AII Free
- Valid Braindumps NCP-AII Questions 🐼 Exam NCP-AII Quizzes 🖐 Test NCP-AII Questions Vce 🏨 The page for free download of ➤ NCP-AII ⮘ on [ www.vce4dumps.com ] will open immediately 🔨Test NCP-AII Free
- NCP-AII pdf braindumps, NVIDIA NCP-AII real braindumps, NCP-AII valid dumps ❕ Open website 《 www.pdfvce.com 》 and search for ➡ NCP-AII ️⬅️ for free download 🦅Valid NCP-AII Test Review
- NCP-AII Valid Test Pass4sure 🏉 NCP-AII New Study Guide 🟦 Valid NCP-AII Test Review 🧓 Easily obtain ( NCP-AII ) for free download through { www.dumpsquestion.com } 🎭Pass4sure NCP-AII Pass Guide
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of CertkingdomPDF NCP-AII dumps from Cloud Storage: https://drive.google.com/open?id=1cp31VfFdVxB-lH44SFojgyJoCwAoxrs1