DOWNLOAD the newest FreeCram Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Y77_Ns7vSwYifIuq_136BP_2l-v7n5p8
If you want to know the latest information for the exam timely, you can choose us, we can do that for you. We offer you free update for one year for Databricks-Generative-AI-Engineer-Associate learning materials, so that you can obtain the latest information for the exam. Our system will send you the latest version automatically, and you just need to examine your email for the latest version. In addition, Databricks-Generative-AI-Engineer-Associate Exam Materials are high-quality, and you can improve your efficiency by using them. We have online and offline service, and if you have any questions for Databricks-Generative-AI-Engineer-Associate exam braindumps, you can contact us, and we will give you reply as quickly as we can.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable Databricks-Generative-AI-Engineer-Associate Test Pass4sure <<
First of all, we have the best and most first-class operating system, in addition, we also solemnly assure users that users can receive the information from the Databricks-Generative-AI-Engineer-Associate certification guide within 5-10 minutes after their payment. Second, once we have written the latest version of the Databricks-Generative-AI-Engineer-Associate certification guide, our products will send them the latest version of the Databricks-Generative-AI-Engineer-Associate Test Practice question free of charge for one year after the user buys the Databricks-Generative-AI-Engineer-Associate exam questions. Last but not least, our perfect customer service staff will provide users with the satisfaction in the hours.
NEW QUESTION # 66
A Generative AI Engineer is developing a chatbot designed to assist users with insurance-related queries. The chatbot is built on a large language model (LLM) and is conversational. However, to maintain the chatbot's focus and to comply with company policy, it must not provide responses to questions about politics. Instead, when presented with political inquiries, the chatbot should respond with a standard message:
"Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance." Which framework type should be implemented to solve this?
Answer: A
Explanation:
In this scenario, the chatbot must avoid answering political questions and instead provide a standard message for such inquiries. Implementing aSafety Guardrailis the appropriate solution for this:
* What is a Safety Guardrail?Safety guardrails are mechanisms implemented in Generative AI systems to ensure the model behaves within specific bounds. In this case, it ensures the chatbot does not answer politically sensitive or irrelevant questions, which aligns with the business rules.
* Preventing Responses to Political Questions:The Safety Guardrail is programmed to detect specific types of inquiries (like political questions) and prevent the model from generating responses outside its intended domain. When such queries are detected, the guardrail intervenes and provides a pre-defined response: "Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance."
* How It Works in Practice:The LLM system can include aclassification layeror trigger rules based on specific keywords related to politics. When such terms are detected, the Safety Guardrail blocks the normal generation flow and responds with the fixed message.
* Why Other Options Are Less Suitable:
* B (Security Guardrail): This is more focused on protecting the system from security vulnerabilities or data breaches, not controlling the conversational focus.
* C (Contextual Guardrail): While context guardrails can limit responses based on context, safety guardrails are specifically about ensuring the chatbot stays within a safe conversational scope.
* D (Compliance Guardrail): Compliance guardrails are often related to legal and regulatory adherence, which is not directly relevant here.
Therefore, aSafety Guardrailis the right framework to ensure the chatbot only answers insurance-related queries and avoids political discussions.
NEW QUESTION # 67
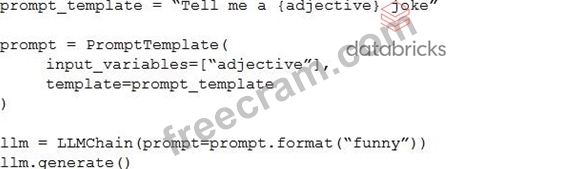
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.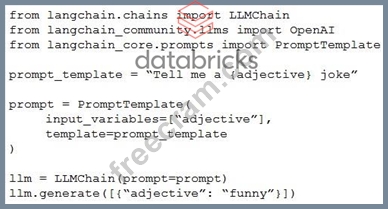
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
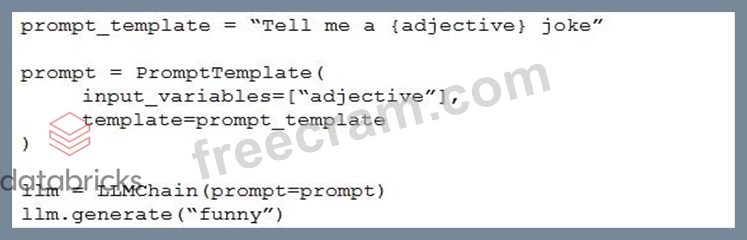
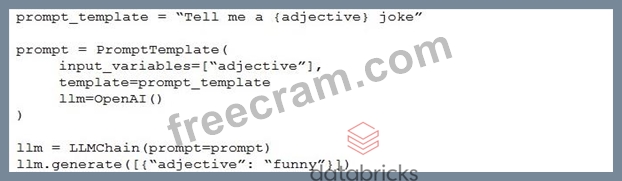
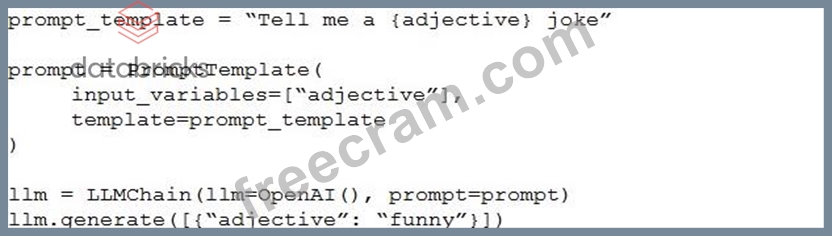
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 68
A Generative Al Engineer has successfully ingested unstructured documents and chunked them by document sections. They would like to store the chunks in a Vector Search index. The current format of the dataframe has two columns: (i) original document file name (ii) an array of text chunks for each document.
What is the most performant way to store this dataframe?
Answer: C
Explanation:
* Problem Context: The engineer needs an efficient way to store chunks of unstructured documents to facilitate easy retrieval and search. The current dataframe consists of document filenames and associated text chunks.
* Explanation of Options:
* Option A: Splitting into train and test sets is more relevant for model training scenarios and not directly applicable to storage for retrieval in a Vector Search index.
* Option B: Flattening the dataframe such that each row contains a single chunk with a unique identifier is the most performant for storage and retrieval. This structure aligns well with how data is indexed and queried in vector search applications, making it easier to retrieve specific chunks efficiently.
* Option C: Creating a unique identifier for each document only does not address the need to access individual chunks efficiently, which is critical in a Vector Search application.
* Option D: Storing each chunk as an independent JSON file creates unnecessary overhead and complexity in managing and querying large volumes of files.
OptionBis the most efficient and practical approach, allowing for streamlined indexing and retrieval processes in a Delta table environment, fitting the requirements of a Vector Search index.
NEW QUESTION # 69
A Generative Al Engineer is deciding between using LSH (Locality Sensitive Hashing) and HNSW (Hierarchical Navigable Small World) for indexing their vector database Their top priority is semantic accuracy Which approach should the Generative Al Engineer use to evaluate these two techniques?
Answer: A
Explanation:
The task is to choose between LSH and HNSW for a vector database index, prioritizing semantic accuracy. The evaluation must assess how well each method retrieves semantically relevant results. Let's evaluate the options.
Option A: Compare the cosine similarities of the embeddings of returned results against those of a representative sample of test inputs Cosine similarity measures semantic closeness between vectors, directly assessing retrieval accuracy in a vector database. Comparing returned results' embeddings to test inputs' embeddings evaluates how well LSH or HNSW preserves semantic relationships, aligning with the priority.
Databricks Reference: "Cosine similarity is a standard metric for evaluating vector search accuracy" ("Databricks Vector Search Documentation," 2023).
Option B: Compare the Bilingual Evaluation Understudy (BLEU) scores of returned results for a representative sample of test inputs BLEU evaluates text generation (e.g., translations), not vector retrieval accuracy. It's irrelevant for indexing performance.
Databricks Reference: "BLEU applies to generative tasks, not retrieval" ("Generative AI Cookbook").
Option C: Compare the Recall-Oriented-Understudy for Gisting Evaluation (ROUGE) scores of returned results for a representative sample of test inputs ROUGE is for summarization evaluation, not vector search. It doesn't measure semantic accuracy in retrieval.
Databricks Reference: "ROUGE is unsuited for vector database evaluation" ("Building LLM Applications with Databricks").
Option D: Compare the Levenshtein distances of returned results against a representative sample of test inputs Levenshtein distance measures string edit distance, not semantic similarity in embeddings. It's inappropriate for vector-based retrieval.
Databricks Reference: No specific support for Levenshtein in vector search contexts.
Conclusion: Option A (cosine similarity) is the correct approach, directly evaluating semantic accuracy in vector retrieval, as recommended by Databricks for Vector Search assessments.
NEW QUESTION # 70
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: D
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 71
......
The FreeCram has specially designed the Databricks Databricks-Generative-AI-Engineer-Associate desktop practice exam software for the self-assessment of the learned concepts. Our Databricks Databricks-Generative-AI-Engineer-Associate desktop practice exam software can be installed on all types of windows operating computers. This is Databricks Databricks-Generative-AI-Engineer-Associate practice exam for the applicant's practice that could be solved without internet access. The Databricks Databricks-Generative-AI-Engineer-Associate exam questions preparation products have been designed to provide ease to their customers in all aspects. Everybody can use our Databricks-Generative-AI-Engineer-Associate Exam Questions And Answers conveniently. We provide 365 days of free updates after the date of purchase so that you can get updated Databricks Databricks-Generative-AI-Engineer-Associate exam questions for the Databricks-Generative-AI-Engineer-Associate exam preparation. FreeCram offers reliable Databricks Databricks-Generative-AI-Engineer-Associate exam questions and also provides a 30% exclusive discount on all Databricks exam questions. Use coupon code ‘30OFF’ while purchasing Databricks Databricks-Generative-AI-Engineer-Associate exam questions preparation products.
Exam Databricks-Generative-AI-Engineer-Associate Duration: https://www.freecram.com/Databricks-certification/Databricks-Generative-AI-Engineer-Associate-exam-dumps.html
BONUS!!! Download part of FreeCram Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1Y77_Ns7vSwYifIuq_136BP_2l-v7n5p8