SPS-C01資格認定は重要な課題になっていて、この資格認定書を所有している人は会社に得られる給料が高いです。我々SPS-C01問題集を利用し、試験に参加しましょう。試験に成功したら、あなたの知識と能力を証明することができます。あなたはこれらのSPS-C01資格認定を持つ人々の一員になれると、いい仕事を探させます。
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 3: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 5: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
SPS-C01試験ガイドの3つのバージョンはPDF版、PC版とAPPオンライン版を含め、当社のテストプラットフォーム上で利用可能です。その結果、携帯電話またはコンピューターでSPS-C01学習教材のオンラインテストエンジンを学習できます。また、自宅、会社、または地下鉄でSPS-C01実際の試験を勉強することもできます。ベテランであれば、SPS-C01試験の質問で勉強し、SPS-C01試験に合格するために、非常に効率的な方法で断片化時間を最大限に活用できます。
質問 # 63
You have a Snowpark DataFrame containing sales data with columns 'sale_date', and 'sale_amount'. You need to calculate the cumulative sales amount for each product over time, ordered by 'sale_date'. Which of the following Snowpark code snippets correctly implements this using window functions?





正解:E
解説:
Option A is correct. It correctly uses to group by 'product_id' and 'order_by' to sort by 'sale_date' within each product group. It then calculates the cumulative sum using Options B, C, D and E contain typos or incorrect function usage or order of arguments. 'cumulative_surn' is not a standard function provided.
質問 # 64
You have two Snowpark DataFrames, 'dfl' and 'df2', representing customer data'. 'dfl' contains customer IDs and names, while 'df2' contains customer IDs and email addresses. You need to create a new DataFrame that contains all customer IDs, names, and email addresses, including customers present in only one of the DataFrames. Which Snowpark set operation and join type would be most appropriate for achieving this?
正解:B
解説:
Option C is the correct answer. 'UNION' is used to combine the rows from both DataFrames, removing duplicate rows. T-ULL OUTER JOIN' is used to include all rows from both DataFrames, even if there is no matching customer ID in the other DataFrame. The combination of 'UNION' and FULL OUTER JOIN' ensures that all customers and their associated information are included in the resulting DataFrame. The other options would either result in only matching records, missing records, or incorrect combination.
質問 # 65
You have a Snowflake table 'PRODUCT REVIEWS' with columns 'product_id', 'review_text', 'review_date', and 'sentiment_score'. You are using Snowpark to build a data pipeline that analyzes these reviews and identifies potentially malicious or spam reviews. Based on a machine learning model deployed as a Snowflake UDF, you have identified a set of 'product_id' values that are associated with malicious reviews, and are stored in a python list called 'malicious_product_ids'. You need to delete all rows from the 'PRODUCT REVIEWS' table where the 'product_id' is present in the list. Assume 'malicious_product_ids' contains thousands of product IDs. Which of the following approaches is the MOST efficient and scalable for deleting these records using Snowpark?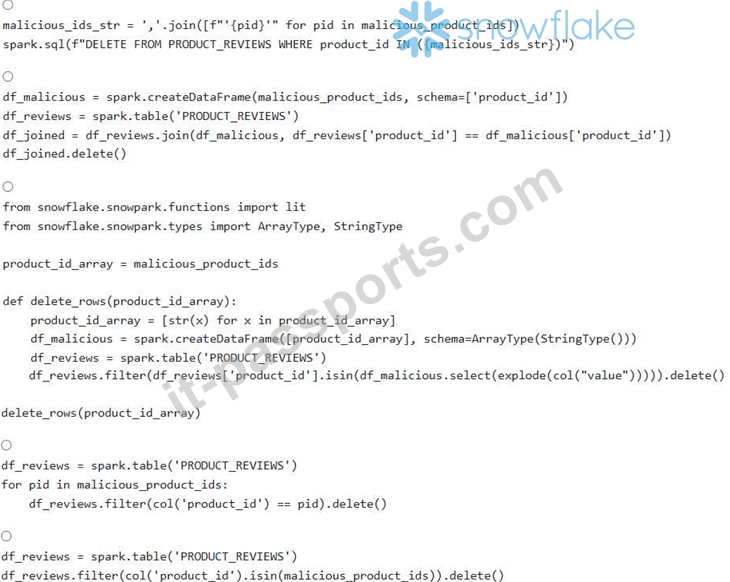
正解:C
解説:
Option E is the most efficient and scalable. Using operator allows Snowpark to leverage Snowflake's internal optimizations for filtering based on a list of values. Option A is limited by the maximum length of SQL statement and also uses SQL directly. Option B has a subtle problem, DataFrame.delete() cannot use join condition. Option C has incorrect schema definition. Option D iterates through each , which is highly inefficient for a large list of IDs.
質問 # 66
A data engineering team has deployed a Snowpark Python application that reads data from a Snowflake table, performs several complex transformations using Snowpark DataFrames, and writes the results back to another Snowflake table. The team is concerned about the cost associated with the virtual warehouse used by the Snowpark application. Which of the following strategies would be MOST effective in minimizing the virtual warehouse costs while maintaining acceptable performance?
正解:A、D、E
解説:
Implementing a resource monitor (C) provides a hard limit on credit consumption, preventing unexpected cost overruns. Optimizing the Snowpark code (D) to reduce data shuffling and processed data directly reduces resource usage. Using serverless compute (E) can reduce warehouse management overhead and potentially lower costs, especially for intermittent workloads. Setting a very short AUTO_SUSPEND (A) can lead to frequent warehouse starts, increasing costs due to warm-up time. Using the smallest warehouse size (B) might not provide acceptable performance and could lead to longer processing times, potentially increasing costs overall. Code optimization and resource monitoring are critical for cost control.
質問 # 67
You have created a Snowpark stored procedure in Python that accesses a Snowflake stage to read configuration files. To enhance security, you want to grant the stored procedure specific permissions to only read files from that stage, without granting broader account- level access. Which of the following approaches is the MOST secure and granular way to achieve this?
正解:E
解説:
Using 'EXECUTE AS CALLER ensures the stored procedure executes with the privileges of the user calling it. This is the most secure and granular approach because you don't need to grant any specific privileges to the stored procedure itself. The user calling it must already have the necessary permissions to access the stage.
質問 # 68
......
クライアントが厄介な問題に遭遇した場合、専門家にSPS-C01試験問題に関する長距離支援を提供するよう依頼します。カスタマーサービススタッフは1日と1年中働いているため、安心してカスタマーサービススタッフがオフラインになることを心配しないでください。また、クライアントは、思いやりのある快適なサービスをお楽しみいただけます。その後、専門家チームがそれらを入念に処理し、テストバンクにまとめます。 Googleのシステムは、定期的にSPS-C01試験実践ガイドの最新アップデートをお客様に送信します。
SPS-C01日本語版テキスト内容: https://www.it-passports.com/SPS-C01.html