With our software version of our Databricks-Certified-Professional-Data-Engineer guide braindumps, you can practice and test yourself just like you are in a real exam for our Databricks-Certified-Professional-Data-Engineer study materials have the advandage of simulating the real exam. The results of your Databricks-Certified-Professional-Data-Engineer Exam will be analyzed and a statistics will be presented to you. So you can see how you have done and know which kinds of questions of the Databricks-Certified-Professional-Data-Engineer exam are to be learned more.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Real Exam Qty: | 60-70 |
| Exam Duration: | 120 minutes |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Passing Score: | 70% |
| Exam Format: | Multiple choice, Scenario-based questions, Multiple select |
| Exam Price: | USD 200 |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks Databricks-Certified-Professional-Data-Engineer Sure Pass <<
You can prepare for the Databricks Certified Professional Data Engineer Exam exam without an internet connection using the offline version of the mock exam. Databricks Databricks-Certified-Professional-Data-Engineer practice test not only gives you the opportunity to practice with real exam questions but also provides you with a self-assessment report highlighting your performance in an attempt. PassSureExam keeps an eye on changes in the Databricks Databricks Certified Professional Data Engineer Exam exam syllabus and updates Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps accordingly to make sure they are relevant to the latest exam topics. After making the payment for Databricks Databricks-Certified-Professional-Data-Engineer dumps questions you’ll be able to get free updates for up to 365 days. Another thing you will get from using the Databricks-Certified-Professional-Data-Engineer exam study material is free to support. If you encounter any problem while using the Databricks-Certified-Professional-Data-Engineer prep material, you have nothing to worry about.
Databricks Certified Professional Data Engineer is a valuable certification for data professionals looking to demonstrate their expertise in the Databricks platform. Databricks Certified Professional Data Engineer Exam certification validates the skills and knowledge required to design and implement data processing solutions using Databricks and Apache Spark. The DCPDE certification is recognized globally and is highly valued by employers looking for data professionals with expertise in Databricks.
The Databricks Certified Professional Data Engineer Exam certification exam covers a broad range of topics, including data processing with Spark, data engineering with Delta Lake, machine learning with MLflow, and cloud infrastructure with AWS and Azure. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the candidate's understanding of these topics and their ability to apply this knowledge to real-world scenarios. Databricks-Certified-Professional-Data-Engineer exam is also designed to test the candidate's ability to design and implement scalable data pipelines and machine learning workflows using Databricks.
NEW QUESTION # 179
A company wants to implement Lakehouse Federation across multiple data sources but is concerned about data consistency and ensuring that all teams access the same authoritative version of their data.
Which statement is applicable for Lakehouse Federations to maintain data consistency?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Lakehouse Federation allows Databricks to query and manage external data sources through a single governance layer, without moving or copying data. The documentation specifies that "Federated queries provide read-only access to data, reflecting the current state of the underlying source system." This ensures consistency across teams since all users access the same source of truth directly from the external system through Unity Catalog. Federation does not perform CDC replication or local caching; it queries live data on demand. Hence, option A accurately represents how Lakehouse Federation maintains consistency across federated sources.
NEW QUESTION # 180
Which of the following SQL statements can replace python variables in Databricks SQL code, when the notebook is set in SQL mode?
1.%python
2.table_name = "sales"
3.schema_name = "bronze"
4.
5.%sql
6.SELECT * FROM ____________________
Answer: D
Explanation:
Explanation
The answer is, SELECT * FROM ${schema_name}.${table_name}
%python
table_name = "sales"
schema_name = "bronze"
%sql
SELECT * FROM ${schema_name}.${table_name}
${python variable} -> Python variables in Databricks SQL code
NEW QUESTION # 181
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the " Owner " for each job. They attempt to transfer " Owner " privileges to the " DevOps " group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: A
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. References:
* Jobs access control : https://docs.databricks.com/security/access-control/table-acls/index.html
* Job permissions : https://docs.databricks.com/security/access-control/table-acls/privileges.html#job- permissions
NEW QUESTION # 182
The following table consists of items found in user carts within an e-commerce website.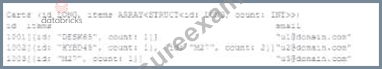
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.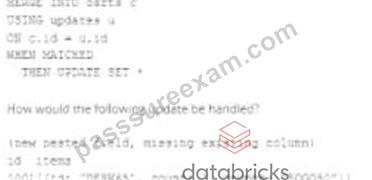
How would the following update be handled?
Answer: A
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
References:
* Databricks documentation on schema evolution in Delta Lake:
https://docs.databricks.com/delta/delta-batch.html#schema-evolution
NEW QUESTION # 183
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?
Answer: C
Explanation:
This is the correct answer because it is the cluster configuration that will result in maximum performance for a job with at least one wide transformation. A wide transformation is a type of transformation that requires shuffling data across partitions, such as join, groupBy, or orderBy. Shuffling can be expensive and time-consuming, especially if there are too many or too few partitions. Therefore, it is important to choose a cluster configuration that can balance the trade-off between parallelism and network overhead. In this case, having 8 VMs with 50 GB per executor and 20 cores per executor will create 8 partitions, each with enough memory and CPU resources to handle the shuffling efficiently. Having fewer VMs with more memory and cores per executor will create fewer partitions, which will reduce parallelism and increase the size of each shuffle block. Having more VMs with less memory and cores per executor will create more partitions, which will increase parallelism but also increase the network overhead and the number of shuffle files. Verified References: [Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Cluster configurations" section.
NEW QUESTION # 184
......
Valid Exam Databricks-Certified-Professional-Data-Engineer Vce Free: https://www.passsureexam.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-exam-dumps.html