P.S. VCESoft在Google Drive上分享了免費的、最新的Mule-Arch-201考試題庫:https://drive.google.com/open?id=1x0cAExnidX9YEOABV7Sb8X5pZ7VK_M0V
因為Salesforce技術一直在快速發展,所以Mule-Arch-201認證考試的試題也在不斷變化。因此, VCESoft的考古題也在一直更新。並且,如果你購買了VCESoft的資料,VCESoft將為你提供一年的免費更新服務。只要試題一更新,VCESoft馬上把最新版的資料發送給你。這樣就可以保證你隨時擁有最新版的資料。VCESoft不僅可以幫助你通過考試,還可以幫助你學習最新的知識。这样实惠的资料你千万不要错过。
| Section | Objectives |
|---|---|
| API Management and Governance | - API lifecycle management - API security policies and enforcement - Governance frameworks and best practices |
| Integration Architecture Strategy | - API-led connectivity principles - Designing enterprise integration architecture - System, process, and experience APIs |
| Security and Compliance | - Authentication and authorization mechanisms - Secure API exposure and threat protection |
| Data Integration and Transformation | - Data mapping and transformation strategies - Batch vs real-time integration patterns |
| Anypoint Platform Architecture | - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) - Runtime Fabric architecture overview |
| Performance and Scalability | - Scaling Mule applications - High availability design patterns |
VCESoft題供了不同培訓工具和資源來準備Salesforce的Mule-Arch-201考試,編制指南包括課程,實踐的檢驗,測試引擎和部分免費PDF下載,我們的考題及答案反應的問題問Salesforce的Mule-Arch-201考試。
問題 #32
Version 3.0.1 of a REST API implementation represents time values in PST time using ISO 8601 hh:mm:ss format. The API implementation needs to be changed to instead represent time values in CEST time using ISO 8601 hh:mm:ss format. When following the semver.org semantic versioning specification, what version should be assigned to the updated API implementation?
答案:A
解題說明:
Correct Answe r: 4.0.0
*****************************************
As per semver.org semantic versioning specification:
Given a version number MAJOR.MINOR.PATCH, increment the:
- MAJOR version when you make incompatible API changes.
- MINOR version when you add functionality in a backwards compatible manner.
- PATCH version when you make backwards compatible bug fixes.
As per the scenario given in the question, the API implementation is completely changing its behavior. Although the format of the time is still being maintained as hh:mm:ss and there is no change in schema w.r.t format, the API will start functioning different after this change as the times are going to come completely different.
Example: Before the change, say, time is going as 09:00:00 representing the PST. Now on, after the change, the same time will go as 18:00:00 as Central European Summer Time is 9 hours ahead of Pacific Time.
>> This may lead to some uncertain behavior on API clients depending on how they are handling the times in the API response. All the API clients need to be informed that the API functionality is going to change and will return in CEST format. So, this considered as a MAJOR change and the version of API for this new change would be 4.0.0
問題 #33
What is the most performant out-of-the-box solution in Anypoint Platform to track transaction state in an asynchronously executing long-running process implemented as a Mule application deployed to multiple CloudHub workers?
答案:B
解題說明:
Correct Answe r: Persistent Object Store
*****************************************
>> Redis distributed cache is performant but NOT out-of-the-box solution in Anypoint Platform
>> File-storage is neither performant nor out-of-the-box solution in Anypoint Platform
>> java.util.WeakHashMap needs a completely custom implementation of cache from scratch using Java code and is limited to the JVM where it is running. Which means the state in the cache is not worker aware when running on multiple workers. This type of cache is local to the worker. So, this is neither out-of-the-box nor worker-aware among multiple workers on cloudhub. https://www.baeldung.com/java-weakhashmap
>> Persistent Object Store is an out-of-the-box solution provided by Anypoint Platform which is performant as well as worker aware among multiple workers running on CloudHub. https://docs.mulesoft.com/object-store/ So, Persistent Object Store is the right answer.
問題 #34
An Order API triggers a sequence of other API calls to look up details of an order's items in a back-end inventory database. The Order API calls the OrderItems process API, which calls the Inventory system API. The Inventory system API performs database operations in the back-end inventory database.
The network connection between the Inventory system API and the database is known to be unreliable and hang at unpredictable times.
Where should a two-second timeout be configured in the API processing sequence so that the Order API never waits more than two seconds for a response from the Orderltems process API?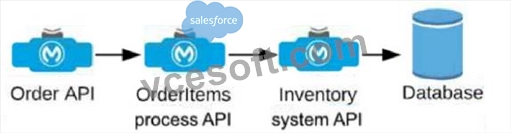
答案:B
解題說明:
Understanding the API Flow and Timeout Requirement:
The Order API initiates a call to the OrderItems process API, which in turn calls the Inventory system API to fetch details from the inventory database.
The requirement specifies that the Order API should not wait more than two seconds for a response from the OrderItems process API, even if there are delays further down the chain (between Inventory system API and the database).
Choosing the Appropriate Timeout Location:
Setting the timeout at the OrderItems process API level ensures that if the Inventory system API takes longer than two seconds to respond, the OrderItems process API will terminate the request and send a timeout response back to the Order API. This prevents the Order API from waiting indefinitely due to the unreliable connection to the database.
If the timeout were set in the Inventory system API or database, it would not help the Order API directly, as the OrderItems process API would still be waiting for a response.
Detailed Analysis of Each Option:
Option A (Correct Answer): Setting the timeout in the OrderItems process API allows it to control how long it waits for a response from the Inventory system API. If the Inventory system API does not respond within two seconds, the OrderItems process API can terminate the call and return a timeout response to the Order API, meeting the requirement.
Option B: Setting the timeout in the Order API would not limit the wait time at the OrderItems process API level, meaning the OrderItems process API could still wait indefinitely for the Inventory system API, leading to a longer delay.
Option C: Setting the timeout in the Inventory system API only affects the connection to the database and does not influence how long the OrderItems process API waits for the Inventory system API's response.
Option D: Setting a timeout in the database is not feasible in this context since database timeouts are typically configured for database operations and would not directly control the API response times in the overall API chain.
Conclusion:
Option A is the best choice, as it ensures that the OrderItems process API does not hold the Order API longer than the required two seconds, even if the downstream connection to the database hangs. This configuration aligns with MuleSoft best practices for setting timeouts in API orchestration to manage dependencies and prevent delays across a chain of API calls.
For additional information on timeout settings, refer to MuleSoft documentation on handling timeouts and API orchestration best practices.
問題 #35
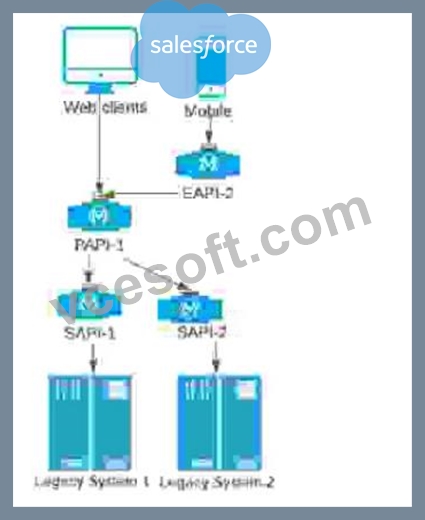
A company stores financial transaction data in two legacy systems. For each legacy system, a separate, dedicated System API (SAPI) exposes data for that legacy system. A Process API (PAPI) merges the data retrieved from ail of the System APIs into a common format. Several API clients call the PAPI through its public domain name.
The company now wants to expose a subset of financial data to a newly developed mobile application that uses a different Bounded Context Data Model. The company wants to follow MuleSoft's best practices for building out an effective application network.
Following MuleSoft's best practices, how can the company expose financial data needed by the mobile application in a way that minimizes the impact on the currently running API clients, API implementations, and support asset reuse?
答案:B
解題說明:
To achieve the goal of exposing financial data to a new mobile application while following MuleSoft's best practices, the company should follow an API-led connectivity approach. This approach ensures minimal disruption to existing clients, maximizes reusability, and respects the separation of concerns across API layers.
of Solution:
Experience APIs for Client-Specific Requirements:
Create two new Experience APIs (EAPI-1 and EAPI-2) for the mobile application, tailored to meet the specific data and format requirements of the mobile application. These APIs encapsulate the client-specific needs and provide a custom interface without impacting other clients.
Process API Layer for Data Transformation:
By adding Mobile PAPI-2, we allow the mobile application to access the required subset of data, formatted according to the mobile application's requirements. This approach ensures that data transformation and aggregation are handled in the Process layer, maintaining consistency and reusability across different applications.
Reuse of System APIs:
Both the new Mobile PAPI-2 and existing PAPI-1 access data from System APIs (SAPI-1 and SAPI-2), which continue to expose data from each legacy system in a consistent, reusable manner. This avoids duplicating logic and ensures that data access remains centralized and manageable.
Why Option A is Correct:
Option A aligns with MuleSoft's best practices by isolating client-specific requirements in the Experience layer, utilizing Process APIs for data orchestration and transformation, and maintaining reusable System APIs for backend access.
This approach also ensures that the current API clients are not impacted, as new clients (e.g., the mobile app) interact with newly defined Experience APIs without modifying the existing API setup.
of Incorrect Options:
Option B: This option seems similar but lacks clarity on the separation of mobile-specific requirements and does not explicitly mention data transformation, which is essential in this scenario.
Option C: Creating a single mobile Experience API that exposes a subset of PAPI endpoints directly adds unnecessary complexity and may violate the separation of concerns, as transformation logic should not be in the Experience layer.
Option D: Deploying a new PAPI and using an API Proxy to redirect existing endpoints would add unnecessary complexity, disrupt the current API clients, and increase maintenance efforts.
Reference
For additional guidance, refer to MuleSoft documentation on API-led connectivity best practices and best practices for structuring Experience, Process, and System APIs.
問題 #36
A circuit breaker strategy is planned in order to meet the goal of improved response time and demand on a downstream API.
* Circuit Open: More than 10 errors per minute for three minutes
* Circuit Half-Open: One error per minute
* Circuit Closed: Less than one error per minute for five minutes
Out of several proposals from the engineering team, which option will meet this goal?
答案:D
解題說明:
Understanding Circuit Breaker Policy:
A circuit breaker is a design pattern used to detect failures and prevent an application from continually trying to execute a failing operation. In this case, it will help improve response time and reduce demand on the downstream API.
The specified configuration includes conditions for opening, half-opening, and closing the circuit based on error rates over time:
Circuit Open: Triggered if there are more than 10 errors per minute for three consecutive minutes.
Circuit Half-Open: The circuit transitions to half-open if there is one error per minute.
Circuit Closed: The circuit closes if the error rate is less than one error per minute for five minutes.
Evaluating the Options:
Option A: Creating a custom policy with template expressions could work, but it would require custom development. Since the Anypoint Platform already has a Circuit Breaker policy available, this would be a less efficient and more complex solution.
Option B: Anypoint Monitoring alerts can be used for monitoring the API, but they do not provide circuit-breaking functionality. Additionally, implementing a retry strategy for the half-open state is not sufficient to achieve the required circuit breaker behavior.
Option C (Correct Answer): Adding the Circuit Breaker policy to the API instance on Anypoint Platform allows you to set up circuit-breaking conditions directly. This approach uses the built-in Circuit Breaker policy, where you can configure parameters such as error thresholds and time intervals to match the requirements. This solution is efficient, reliable, and leverages Anypoint's out-of-the-box capabilities.
Option D: Implementing the strategy within a Mule application with a YAML configuration could be complex and less manageable. Additionally, it does not leverage Anypoint Platform's built-in Circuit Breaker policy, which is more suited to this scenario.
Conclusion:
Option C is the correct choice, as it leverages Anypoint Platform's Circuit Breaker policy. This solution allows for configuring thresholds and time intervals as specified, improving response time and reducing demand on the downstream API while utilizing Anypoint's managed policy feature.
Refer to MuleSoft's documentation on implementing the Circuit Breaker policy in API Manager for detailed configuration guidance.
問題 #37
......
VCESoft提供的Salesforce Mule-Arch-201 認證考試測試練習題和真實的考試題目很相似。如果你選擇了VCESoft提供的測試練習題和答案,我們會給你提供一年的免費線上更新服務。VCESoft可以100%保證你通過考試,如果你的考試未通過,我們將全額退款給你。
Mule-Arch-201在線題庫: https://www.vcesoft.com/Mule-Arch-201-pdf.html
BONUS!!! 免費下載VCESoft Mule-Arch-201考試題庫的完整版:https://drive.google.com/open?id=1x0cAExnidX9YEOABV7Sb8X5pZ7VK_M0V