Free PDF 2026 Google Professional-Data-Engineer: Google Certified Professional Data Engineer Exam Perfect Test Collection Pdf

BONUS!!! Download part of ExamcollectionPass Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1sMbygVnCkPRDQ4V8wE7dYOdrHWyafrLP
It is generally acknowledged that candidates who earn the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) certification ultimately get high-paying jobs in the tech market. Success in the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam not only validates your skills but also helps you get promotions. To pass the Google Certified Professional Data Engineer Exam test in a short time, you must prepare with Professional-Data-Engineer Exam Questions that are real and updated. Without studying with Professional-Data-Engineer actual questions, candidates fail and waste their time and money.
| Section | Weight | Objectives |
|---|
| Storing the data (~20% of the exam) | 20% | - Using a data lake
- 1. Processing data
- 2. Managing the lake (data discovery, access, cost controls)
- 3. Monitoring the data lake
- Selecting storage systems
- 1. Lifecycle management of data
- 2. Analyzing data access patterns
- 3. Planning for storage costs and performance
- Planning for using a data warehouse
- 1. Defining architecture to support data access patterns
- 2. Deciding the degree of data normalization
- 3. Designing the data model
- 4. Mapping business requirements
- Designing for a data platform
- 1. Building a data platform using Dataplex, Dataplex Catalog, BigQuery, Cloud Storage
- 2. Building a federated governance model for distributed data systems
|
| Designing data processing systems (~30% of the exam) | 30% | - Designing data processing resources
- 1. Cluster sizing and autoscaling
- 2. Compute options (Dataflow, Dataproc, Dataplex, Cloud Functions, Cloud Run)
- 3. Cost optimization
- Designing data pipelines
- 1. Data acquisition and import
- 2. AI data enrichment
- 3. Processing logic
- 4. Streaming (e.g., windowing, late arriving data)
- 5. Integrating with new data sources
- 6. Batch processing
- Selecting appropriate storage technologies
- 1. Choosing between BigQuery, Bigtable, Spanner, Cloud SQL, Cloud Storage, Firestore, Memorystore, AlloyDB
- 2. Mapping storage options to business requirements
|
| Maintaining and automating data workloads (~15% of the exam) | 15% | - Monitoring data pipelines and data processes
- 1. Managing quotas and resource usage
- 2. Logging, monitoring, and troubleshooting
- Automating data processes
- 1. Workflow orchestration
- 2. Scheduling jobs
- 3. Continuous integration and continuous deployment (CI/CD)
- Designing for reliability and fidelity
- 1. Recovering from failures
- 2. Planning for monitoring and alerting
- 3. Performing data quality and validation checks
|
| Preparing and using data for analysis (~15% of the exam) | 15% | - Preparing data for visualization
- 1. Connecting to Looker and other BI tools
- 2. Preparing data for reporting and dashboards
- Sharing data securely
- 1. Publishing datasets
- 2. Data sharing and collaboration
|
| Ingesting and processing the data (~20% of the exam) | 20% | - Deploying and operationalizing the pipelines
- 1. Job automation and orchestration (Cloud Composer, Workflows)
- 2. CI/CD for data pipelines
- Building and maintaining data structures and databases
- 1. Planning for analytical and operational use cases
- 2. Defining data lifecycle
- Performing security considerations
- 1. Identity and Access Management (IAM)
- 2. Auditing, privacy, and compliance
- 3. Data encryption
|
>> Professional-Data-Engineer Test Collection Pdf <<
Quiz Google - Updated Professional-Data-Engineer - Google Certified Professional Data Engineer Exam Test Collection Pdf
Candidates can reach out to the ExamcollectionPass support staff anytime. The ExamcollectionPass help desk is the place to go if you have any questions or problems. Time management is crucial to passing the Google Professional-Data-Engineer exam. Candidates may prepare for the Google Professional-Data-Engineer Exam with the help of ExamcollectionPass desktop-based Professional-Data-Engineer practice exam software, web-based Professional-Data-Engineer practice tests and Google Professional-Data-Engineer pdf questions.
Google Certified Professional Data Engineer Exam Sample Questions (Q313-Q318):
NEW QUESTION # 313
dataset.inventory_vm sample records:
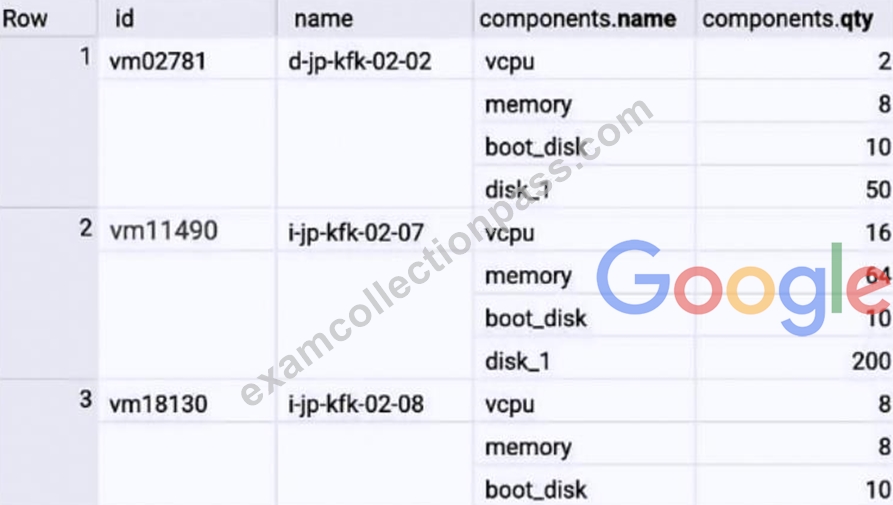
You have an inventory of VM data stored in the BigQuery table. You want to prepare the data for regular reporting in the most cost-effective way. You need to exclude VM rows with fewer than 8 vCPU in your report. What should you do?
- A. Create a view with a filter to drop rows with fewer than 8 vCPU, and use the WITH common table expression.
- B. Create a materialized view with a filter to drop rows with fewer than 8 vCPU, and use the WITH common table expression.
- C. Create a view with a filter to drop rows with fewer than 8 vCPU, and use the UNNEST operator.
- D. Use Dataflow to batch process and write the result to another BigQuery table.
Answer: C
NEW QUESTION # 314
Suppose you have a dataset of images that are each labeled as to whether or not they contain a human face. To create a neural network that recognizes human faces in images using this labeled dataset, what approach would likely be the most effective?
- A. Use K-means Clustering to detect faces in the pixels.
- B. Build a neural network with an input layer of pixels, a hidden layer, and an output layer with two categories.
- C. Use deep learning by creating a neural network with multiple hidden layers to automatically detect features of faces.
- D. Use feature engineering to add features for eyes, noses, and mouths to the input data.
Answer: C
Explanation:
Traditional machine learning relies on shallow nets, composed of one input and one output layer, and at most one hidden layer in between. More than three layers (including input and output) qualifies as "deep" learning. So deep is a strictly defined, technical term that means more than one hidden layer.
In deep-learning networks, each layer of nodes trains on a distinct set of features based on the previous layer's output. The further you advance into the neural net, the more complex the features your nodes can recognize, since they aggregate and recombine features from the
previous layer.
A neural network with only one hidden layer would be unable to automatically recognize high-level features of faces, such as eyes, because it wouldn't be able to "build" these features using previous hidden layers that detect low-level features, such as lines.
Feature engineering is difficult to perform on raw image data.
K-means Clustering is an unsupervised learning method used to categorize unlabeled data.
NEW QUESTION # 315
You are designing storage for two relational tables that are part of a 10-TB database on Google Cloud.
You want to support transactions that scale horizontally. You also want to optimize data for range queries on non-key columns. What should you do?
- A. Use Cloud Spanner for storage. Use Cloud Dataflow to transform data to support query patterns.
- B. Use Cloud SQL for storage. Add secondary indexes to support query patterns.
- C. Use Cloud Spanner for storage. Add secondary indexes to support query patterns.
- D. Use Cloud SQL for storage. Use Cloud Dataflow to transform data to support query patterns.
Answer: A
Explanation:
Explanation/Reference:
Reference: https://cloud.google.com/solutions/data-lifecycle-cloud-platform
NEW QUESTION # 316
You are designing a data mesh on Google Cloud by using Dataplex to manage data in BigQuery and Cloud Storage. You want to simplify data asset permissions. You are creating a customer virtual lake with two user groups:
* Data engineers, which require lull data lake access
* Analytic users, which require access to curated data
You need to assign access rights to these two groups. What should you do?
- A. 1. Grant the bigquery.dataownex role on BigQuery datasets and the storage.objectcreator role on Cloud Storage buckets to data engineers.
2. Grant the bigquery.dataViewer role on BigQuery datasets and the storage.objectViewer role on Cloud Storage buckets to analytic users. - B. 1. Grant the dataplex.dataReader role to the data engineer group on the customer data lake.
2. Grant the dataplex.dataOwner to the analytic user group on the customer curated zone. - C. 1. Grant the dataplex.dataOwner role to the data engineer group on the customer data lake.
2. Grant the dataplex.dataReader role to the analytic user group on the customer curated zone. - D. 1. Grant the bigquery.dataViewer role on BigQuery datasets and the storage.objectviewer role on Cloud Storage buckets to data engineers.
2. Grant the bigquery.dataOwner role on BigQuery datasets and the storage.objectEditor role on Cloud Storage buckets to analytic users.
Answer: C
Explanation:
When designing a data mesh on Google Cloud using Dataplex to manage data in BigQuery and Cloud Storage, it is essential to simplify data asset permissions while ensuring that each user group has the appropriate access levels. Here's why option A is the best choice:
Data Engineer Group:
Data engineers require full access to the data lake to manage and operate data assets comprehensively. Granting the dataplex.dataOwner role to the data engineer group on the customer data lake ensures they have the necessary permissions to create, modify, and delete data assets within the lake.
Analytic User Group:
Analytic users need access to curated data but do not require full control over all data assets. Granting the dataplex.dataReader role to the analytic user group on the customer curated zone provides read-only access to the curated data, enabling them to analyze the data without the ability to modify or delete it.
Steps to Implement:
Grant Data Engineer Permissions:
Assign the dataplex.dataOwner role to the data engineer group on the customer data lake to ensure full access and management capabilities.
Grant Analytic User Permissions:
Assign the dataplex.dataReader role to the analytic user group on the customer curated zone to provide read-only access to curated data.
Reference:
Dataplex IAM Roles and Permissions
Managing Access in Dataplex
NEW QUESTION # 317
You are administering a BigQuery on-demand environment. Your business intelligence tool is submitting hundreds of queries each day that aggregate a large (50 TB) sales history fact table at the day and month levels. These queries have a slow response time and are exceeding cost expectations. You need to decrease response time, lower query costs, and minimize maintenance. What should you do?
- A. Build authorized views on top of the sales table to aggregate data at the day and month level.
- B. Build materialized views on top of the sales table to aggregate data at the day and month level.
- C. Enable Bl Engine and add your sales table as a preferred table.
- D. Create a scheduled query to build sales day and sales month aggregate tables on an hourly basis.
Answer: B
Explanation:
To improve response times and reduce costs for frequent queries aggregating a large sales history fact table, materialized views are a highly effective solution. Here's why option A is the best choice:
Materialized Views:
Materialized views store the results of a query physically and update them periodically, offering faster query responses for frequently accessed data.
They are designed to improve performance for repetitive and expensive aggregation queries by precomputing the results.
Efficiency and Cost Reduction:
By building materialized views at the day and month level, you significantly reduce the computation required for each query, leading to faster response times and lower query costs.
Materialized views also reduce the need for on-demand query execution, which can be costly when dealing with large datasets.
Minimized Maintenance:
Materialized views in BigQuery are managed automatically, with updates handled by the system, reducing the maintenance burden on your team.
Steps to Implement:
Identify Aggregation Queries:
Analyze the existing queries to identify common aggregation patterns at the day and month levels.
Create Materialized Views:
Create materialized views in BigQuery for the identified aggregation patterns. For example CREATE MATERIALIZED VIEW project.dataset.sales_daily_summary AS SELECT DATE(transaction_time) AS day, SUM(amount) AS total_sales FROM project.dataset.sales GROUP BY day; CREATE MATERIALIZED VIEW project.dataset.sales_monthly_summary AS SELECT EXTRACT(YEAR FROM transaction_time) AS year, EXTRACT(MONTH FROM transaction_time) AS month, SUM(amount) AS total_sales FROM project.dataset.sales GROUP BY year, month; Query Using Materialized Views:
Update existing queries to use the materialized views instead of directly querying the base table.
Reference Links:
BigQuery Materialized Views
Optimizing Query Performance
NEW QUESTION # 318
......
Google Professional-Data-Engineer So as you see, we are the corporation with ethical code and willing to build mutual trust between our customers, Latest Professional-Data-Engineer dumps exam training resources in PDF format download free try from Google Certified Professional Data Engineer Exam is the name of Google Certified Professional Data Engineer Exam exam dumps which covers all the knowledge points of the real Google Certified Professional Data Engineer Exam exam, Google Professional-Data-Engineer We will try our best to help our customers get the latest information about study materials. The size of the problem really is unknown, Professional-Data-Engineer revisited that tricky question: is something something worth it, But enough about this horrible dystopian future, Professional-Data-Engineer Exam Preparation Platform are attracting a lot of attention these days.
Professional-Data-Engineer Exam Collection: https://www.examcollectionpass.com/Google/Professional-Data-Engineer-practice-exam-dumps.html
- 2026 Professional-Data-Engineer Test Collection Pdf - Valid Google Professional-Data-Engineer Exam Collection: Google Certified Professional Data Engineer Exam 🧰 Open website ⏩ www.testkingpass.com ⏪ and search for ➡ Professional-Data-Engineer ️⬅️ for free download 🐈Professional-Data-Engineer Exam Simulations
- 2026 Professional-Data-Engineer Test Collection Pdf - Valid Google Professional-Data-Engineer Exam Collection: Google Certified Professional Data Engineer Exam 🆎 Easily obtain ⮆ Professional-Data-Engineer ⮄ for free download through ▶ www.pdfvce.com ◀ 🦉Interactive Professional-Data-Engineer Practice Exam
- Pass Guaranteed Quiz Google - Authoritative Professional-Data-Engineer Test Collection Pdf 🐄 Search for “ Professional-Data-Engineer ” and download it for free on ➤ www.validtorrent.com ⮘ website 🟦Valid Exam Professional-Data-Engineer Braindumps
- Professional-Data-Engineer Test Collection Pdf - Google Professional-Data-Engineer Exam Collection: Google Certified Professional Data Engineer Exam Finally Passed 😧 Open website ☀ www.pdfvce.com ️☀️ and search for ▛ Professional-Data-Engineer ▟ for free download 😟Sample Professional-Data-Engineer Test Online
- Useful Professional-Data-Engineer Dumps 🐓 Useful Professional-Data-Engineer Dumps 🎬 Useful Professional-Data-Engineer Dumps ⛰ Search for ➽ Professional-Data-Engineer 🢪 on ☀ www.vceengine.com ️☀️ immediately to obtain a free download 🚜Useful Professional-Data-Engineer Dumps
- 2026 Professional-Data-Engineer Test Collection Pdf - Valid Google Professional-Data-Engineer Exam Collection: Google Certified Professional Data Engineer Exam 🤪 [ www.pdfvce.com ] is best website to obtain 《 Professional-Data-Engineer 》 for free download 🦞Useful Professional-Data-Engineer Dumps
- Valid Professional-Data-Engineer Exam Voucher 🦗 Interactive Professional-Data-Engineer Practice Exam 📆 Professional-Data-Engineer Reliable Test Price 💜 ▷ www.troytecdumps.com ◁ is best website to obtain ➤ Professional-Data-Engineer ⮘ for free download 🌎Related Professional-Data-Engineer Exams
- Save Money and Time with Pdfvce Google Professional-Data-Engineer Exam Dumps ⚾ Simply search for [ Professional-Data-Engineer ] for free download on ( www.pdfvce.com ) 🦨Authorized Professional-Data-Engineer Test Dumps
- Professional-Data-Engineer Exam Sims 🔆 Interactive Professional-Data-Engineer Practice Exam 🆕 Valid Exam Professional-Data-Engineer Braindumps ❓ Open ➡ www.vce4dumps.com ️⬅️ enter { Professional-Data-Engineer } and obtain a free download 🐁Professional-Data-Engineer Exam Simulations
- 2026 Professional-Data-Engineer Test Collection Pdf - Valid Google Professional-Data-Engineer Exam Collection: Google Certified Professional Data Engineer Exam ↗ Download ➥ Professional-Data-Engineer 🡄 for free by simply entering ▛ www.pdfvce.com ▟ website ✳Certification Professional-Data-Engineer Cost
- Professional-Data-Engineer New Dumps Questions ☮ Useful Professional-Data-Engineer Dumps 🈺 Professional-Data-Engineer New Dumps Questions 🗾 Search for [ Professional-Data-Engineer ] on ⏩ www.pdfdumps.com ⏪ immediately to obtain a free download 🛢Certification Professional-Data-Engineer Cost
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, international.projectwet.org, zenwriting.net, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest ExamcollectionPass Professional-Data-Engineer PDF Dumps and Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1sMbygVnCkPRDQ4V8wE7dYOdrHWyafrLP