What's more, part of that TestPassKing DP-100 dumps now are free: https://drive.google.com/open?id=1jwSi1-PInkSWOd2_Hu9kBdBndARRAb6S
You can easily download these formats of Microsoft DP-100 actual dumps and use them to prepare for the Microsoft DP-100 certification test. You do not need to enroll yourself in expensive DP-100 Exam Training classes. With the Microsoft DP-100 valid dumps, you can easily prepare well for the actual Designing and Implementing a Data Science Solution on Azure exam at home.
Microsoft DP-100 exam is designed for data scientists who want to demonstrate their skills in designing and implementing data science solutions on Azure. DP-100 exam focuses on evaluating the candidate's knowledge and proficiency in various areas such as data exploration and preparation, modeling, deployment, and monitoring. DP-100 Exam also includes topics related to machine learning, data engineering, and data visualization.
As long as you study with our DP-100 training braindump, then you will find that it is designed to deepened the understanding of the users and memory. Simple text messages, deserve to go up colorful stories and pictures beauty, make the DP-100 test guide better meet the zero basis for beginners, let them in the relaxed happy atmosphere to learn more useful knowledge, more good combined with practical, so as to achieve the state of unity. It is easy to pass with our DP-100 Practice Questions as our pass rate of DP-100 exam material is more than 98%.
The DP-100 Exam is a popular choice for data scientists looking to broaden their skillset and stay relevant in the field. It covers topics such as data exploration and preparation, data storage and processing, machine learning model development, and deployment. Additionally, the exam also tests the candidate's understanding of data security, compliance, and ethical considerations.
NEW QUESTION # 43
You have a multi-class image classification deep learning model that uses a set of labeled photographs. You create the following code to select hyperparameter values when training the model.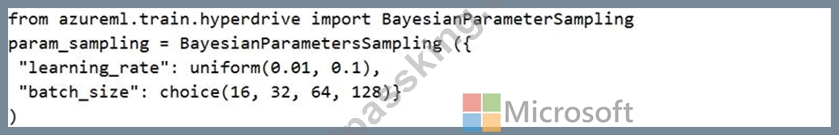
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
NEW QUESTION # 44
You create a new Azure Databricks workspace.
You configure a new cluster for long-running tasks with mixed loads on the compute cluster as shown in the image below.
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: No
Running user code in separate processes is not possible in Scala.
Box 2: No
Autoscaling is enabled. Minimum 2 workers, Maximum 8 workers.
Reference:
https://docs.databricks.com/clusters/configure.html
NEW QUESTION # 45
You are retrieving data from a large datastore by using Azure Machine Learning Studio.
You must create a subset of the data for testing purposes using a random sampling seed based on the system clock.
You add the Partition and Sample module to your experiment.
You need to select the properties for the module.
Which values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation
Box 1: Sampling
Create a sample of data
This option supports simple random sampling or stratified random sampling. This is useful if you want to create a smaller representative sample dataset for testing.
1. Add the Partition and Sample module to your experiment in Studio, and connect the dataset.
2. Partition or sample mode: Set this to Sampling.
3. Rate of sampling. See box 2 below.
Box 2: 0
3. Rate of sampling. Random seed for sampling: Optionally, type an integer to use as a seed value.
This option is important if you want the rows to be divided the same way every time. The default value is 0, meaning that a starting seed is generated based on the system clock. This can lead to slightly different results each time you run the experiment.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/partition-and-sample
NEW QUESTION # 46
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.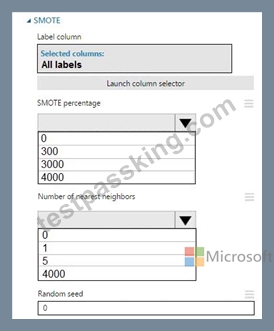
Answer:
Explanation:
Explanation:
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 47
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: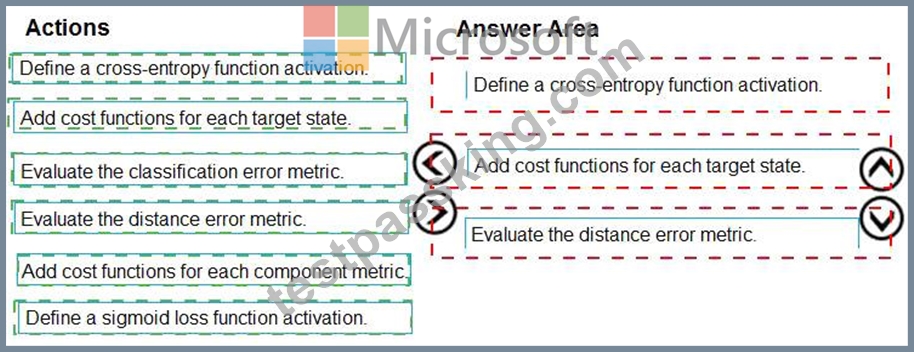
Explanation
Step 1: Define a cross-entropy function activation
When using a neural network to perform classification and prediction, it is usually better to use cross-entropy error than classification error, and somewhat better to use cross-entropy error than mean squared error to evaluate the quality of the neural network.
Step 2: Add cost functions for each target state.
Step 3: Evaluated the distance error metric.
References:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
NEW QUESTION # 48
......
DP-100 Valid Exam Prep: https://www.testpassking.com/DP-100-exam-testking-pass.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by TestPassKing: https://drive.google.com/open?id=1jwSi1-PInkSWOd2_Hu9kBdBndARRAb6S