
BTW, DOWNLOAD part of LatestCram MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1aq9EtHY4T-dXa7ffjQl7o69Tx8W1s0N9
Like other Amazon examinations, the MLA-C01 exam preparation calls for a strong preparation and precise MLA-C01 practice material. Finding original and latest 121 exam questions however, is a difficult process. Candidates require assistance finding the MLA-C01 updated questions. It will be hard for applicants to pass the Amazon MLA-C01 exam on their first try if AWS Certified Machine Learning Engineer - Associate questions they have are not real and updated.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Real Testing Environment <<
How you can gain the MLA-C01 certification with ease in the least time? The answer is our MLA-C01 study materials for we have engaged in this field for over ten years and we have become the professional standard over all the exam materials. You can free download the demos which are part of our MLA-C01 Exam Braindumps, you will find that how good they are for our professionals devote of themselves on compiling and updating the most accurate content of our MLA-C01 exam questions.
NEW QUESTION # 15
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm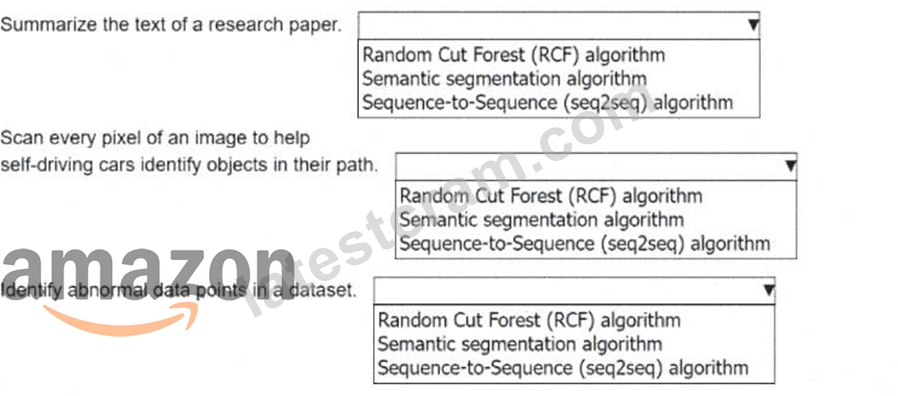
Answer:
Explanation: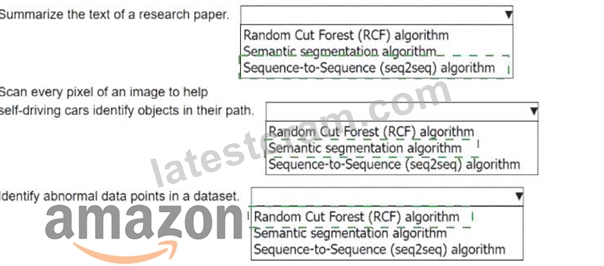
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
NEW QUESTION # 16
A company must install a custom script on any newly created Amazon SageMaker notebook instances.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: C
NEW QUESTION # 17
Hotspot Question
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
- Feature splitting
- Logarithmic transformation
- One-hot encoding
- Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)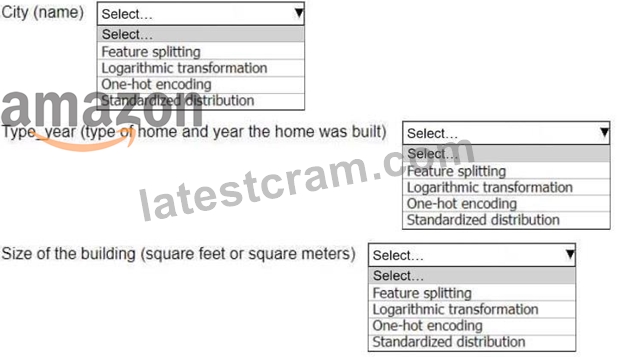
Answer:
Explanation: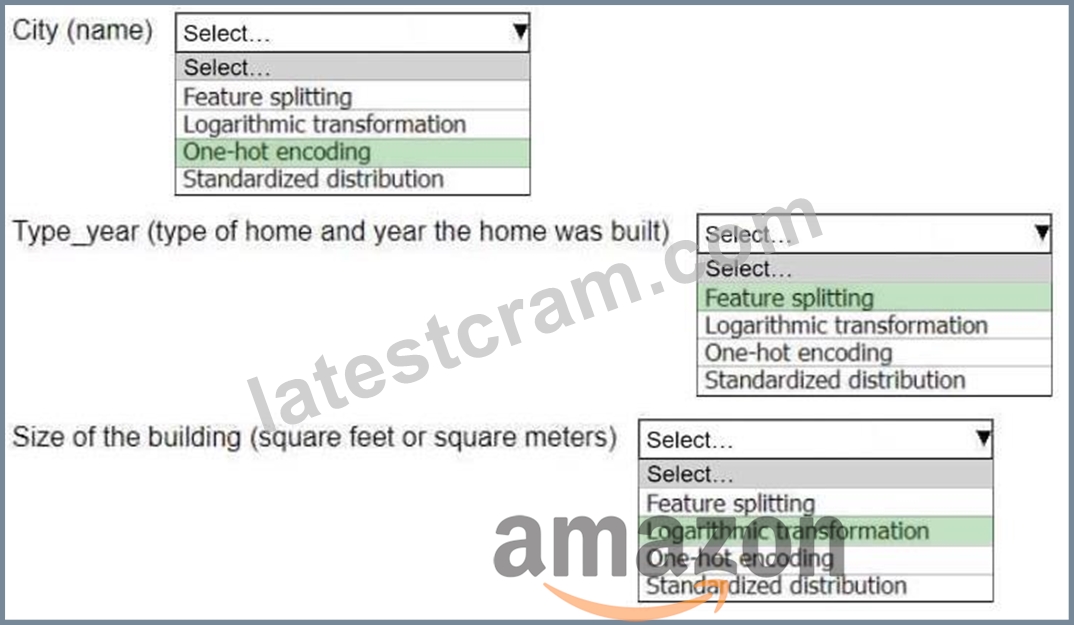
NEW QUESTION # 18
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token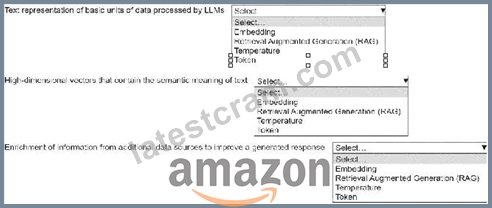
Answer:
Explanation: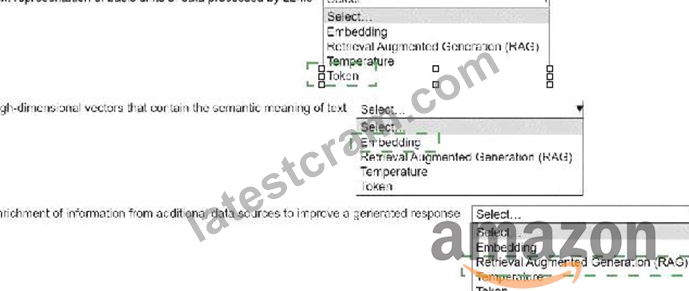
Explanation: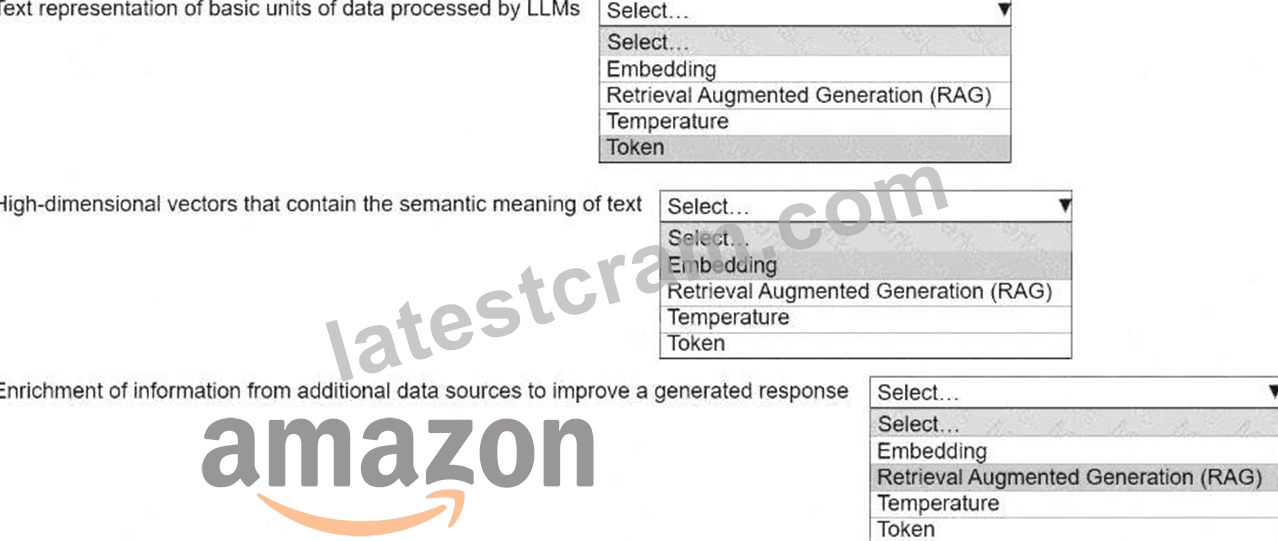
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 19
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.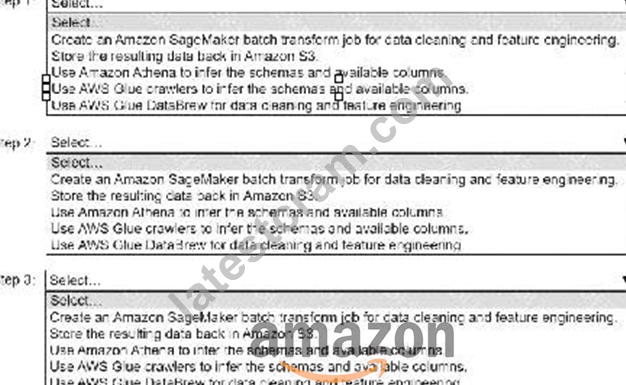
Answer:
Explanation: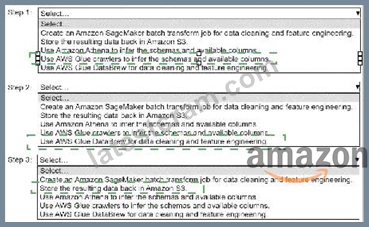
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
Step 3: Store the Resulting Data Back in Amazon S3
Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
Use AWS Glue crawlers to infer schemas and available columns.
Use AWS Glue DataBrew for data cleaning and feature engineering.
Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 20
......
The MLA-C01 dumps of LatestCram include valid MLA-C01 questions PDF and customizable AWS Certified Machine Learning Engineer - Associate (MLA-C01) practice tests. Our 24/7 customer support provides assistance to help MLA-C01 Dumps users solve their technical hitches during their test preparation. The MLA-C01 exam questions of LatestCram come with up to 365 days of free updates and a free demo.
Sample MLA-C01 Exam: https://www.latestcram.com/MLA-C01-exam-cram-questions.html
BTW, DOWNLOAD part of LatestCram MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1aq9EtHY4T-dXa7ffjQl7o69Tx8W1s0N9