BONUS!!! Download part of SurePassExams DP-750 dumps for free: https://drive.google.com/open?id=1PRv0U-ABCFvfm2d0Z7GCDGQ7UJhN8M_w
Preparing with outdated DP-750 exam questions results in failure and loss of time and money. You can get success in the exam on first attempt and save your resources with the help of updated exam questions. We offer Microsoft DP-750 real questions to help pupils in getting ready for the exam in a short time. Students who choose SurePassExams will get the latest and updated exam questions they need to prepare for the DP-750 examination in a short time.
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data ingestion
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
If you want to pass your exam and get your certification, we can make sure that our Microsoft Certified: Fabric Data Engineer Associate guide questions will be your ideal choice. Our company will provide you with professional team, high quality service and reasonable price. In order to help customers solve problems, our company always insist on putting them first and providing valued service. We deeply believe that our DP-750 question torrent will help you pass the exam and get your certification successfully in a short time. Maybe you cannot wait to understand our DP-750 Guide questions; we can promise that our products have a higher quality when compared with other study materials. At the moment I am willing to show our DP-750 guide torrents to you, and I can make a bet that you will be fond of our products if you understand it.
NEW QUESTION # 23
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.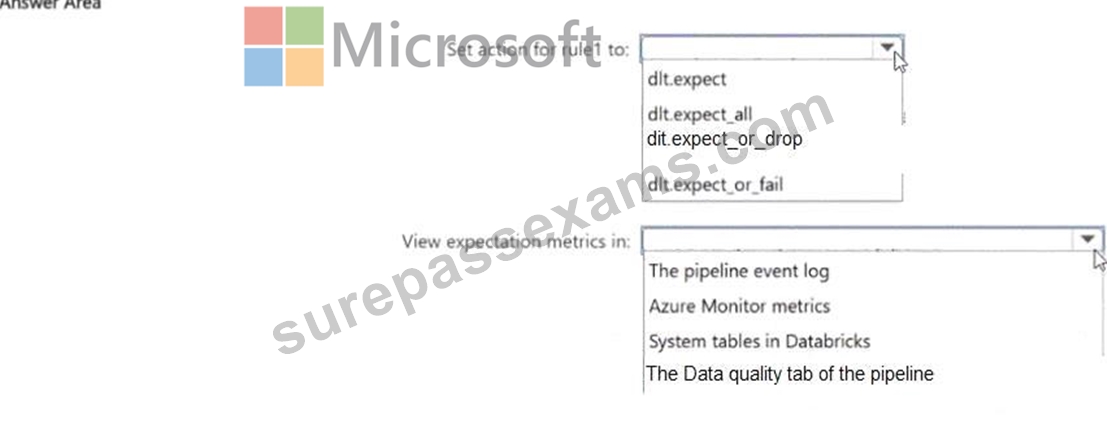
Answer:
Explanation: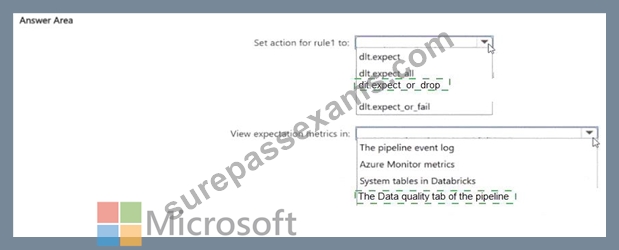
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 24
You have an Azure Databricks workspace that contains a Delta table named Customer.
A job named Job1 performs frequent upserts into Customer.
You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
What should you do?
Answer: A
Explanation:
The OPTIMIZE command performs bin-packing compaction, combining the Customer table's existing small Parquet files into fewer, larger files. This reduces file-open overhead and improves data-skipping efficiency without changing the logical table contents. Enabling optimized writes affects future write operations but does not compact the small files already stored. VACUUM removes unreferenced data files that are older than the configured retention threshold; it does not reorganize active small files and can restrict time-travel availability. Reducing delta.deletedFileRetentionDuration changes how long obsolete files remain available and can directly reduce the time-travel window, contrary to the requirement. OPTIMIZE is therefore the correct operation for improving the physical layout of current data while preserving Delta table semantics and history. Microsoft Learn
NEW QUESTION # 25
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: C
Explanation:
A file arrival trigger starts Job1 when new files are detected in the monitored Azure Storage location. Because the job is launched only after a qualifying arrival, compute does not remain active while the source is idle.
This is well suited to unpredictable file-delivery patterns and avoids the unnecessary executions produced by a fixed schedule. A continuous trigger keeps the workload running and therefore consumes compute even when no files are available. A scheduled trigger starts the job at predetermined times whether or not new data exists. A manual trigger cannot provide automatic processing. File arrival triggers consequently provide the required event-driven behavior while improving resource utilization and controlling cost during inactive periods. Microsoft Learn
NEW QUESTION # 26
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.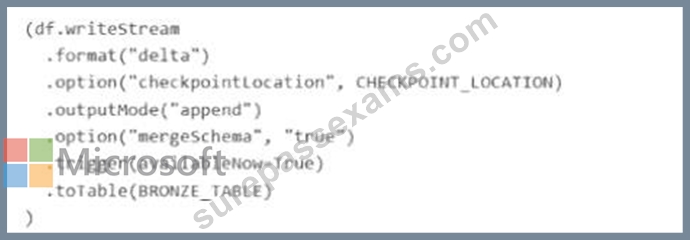
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.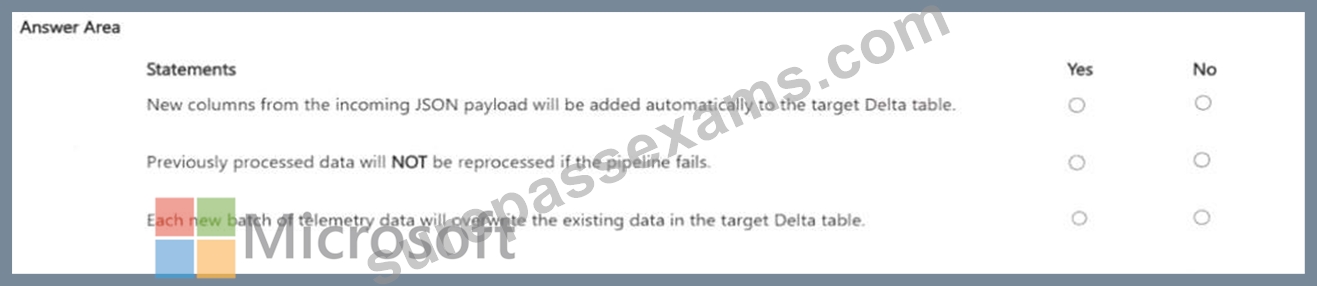
Answer:
Explanation: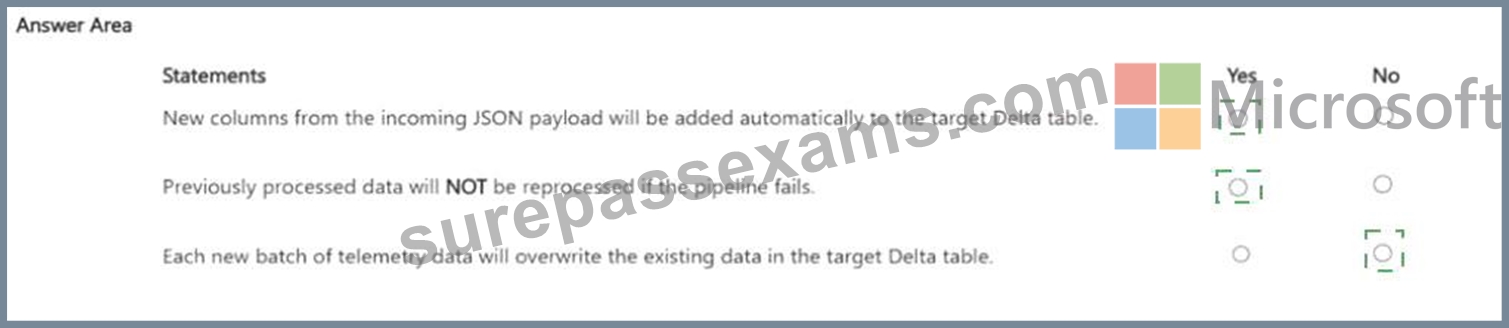
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 27
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.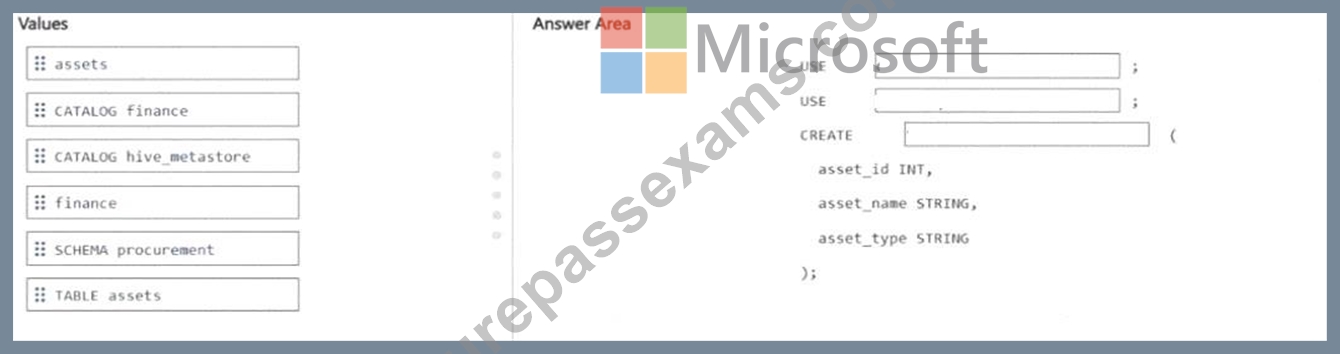
Answer:
Explanation: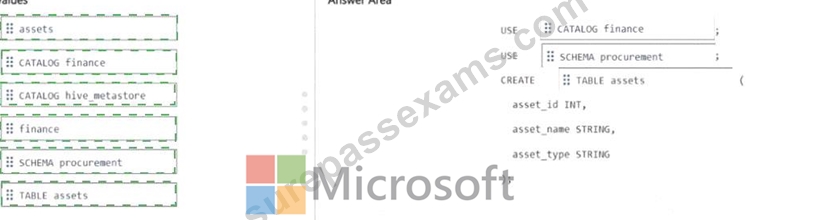
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
NEW QUESTION # 28
......
Our DP-750 practice questions are not famous for nothing. As long as you choose our DP-750 study guide, you will find that the exam questions and answers are always the most accurate and up-to-date. It is all due to the hard work of our professionals who always keep a close eye on the updationg. The DP-750 learning braindumps are regularly updated in line with the changes introduced in the exam contents. You will always find our DP-750 exam simulating highly relevant to your needs.
Valid DP-750 Test Labs: https://www.surepassexams.com/DP-750-exam-bootcamp.html
BONUS!!! Download part of SurePassExams DP-750 dumps for free: https://drive.google.com/open?id=1PRv0U-ABCFvfm2d0Z7GCDGQ7UJhN8M_w