P.S. Free & New DP-800 dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=16LxwSg5PROBGpfTX0YdrGcfnbKoHeZYd
This Developing AI-Enabled Database Solutions (DP-800) practice exam software is easily accessible on all Windows laptops and computers. You do not require an active internet connection after installation of the Developing AI-Enabled Database Solutions (DP-800) practice exam software. Repetitive attempts of Developing AI-Enabled Database Solutions (DP-800) exam dumps boosts confidence and provide familiarity with the DP-800 actual exam format.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest DP-800 Test Sample <<
Customizable Developing AI-Enabled Database Solutions (DP-800) exam conditions in such a way that you can create your desired DP-800 exam with pre-determined questions and exam duration. You will be able to see instant results after going through the DP-800 Practice Exam To confirm the product licence. For customer satisfaction, FreeCram has also designed a Developing AI-Enabled Database Solutions (DP-800) demo version so the candidate can assure the reliability of the Microsoft PDF Dumps.
NEW QUESTION # 27
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.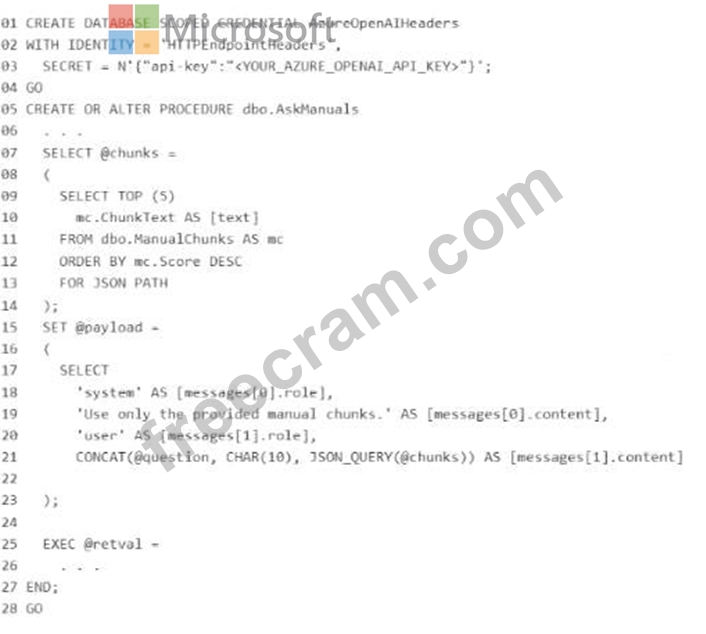
What should you insert at line 22?
Answer: C
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 28
You have an Azure SQL database named DB1 that contains two tables named knowledgebase and query_cache. knowledge_base contains support articles and embeddings. query_cache contains chat questions, responses, and embeddings DB1 supports an Al-enabled chat agent.
You need to design a solution that meets the following requirements:
* Serializes the retrieved rows from knowledee_base
* Extracts the answer field from the response
* Extracts the embeddings to store in query_cache
You will call the external large language model (LLM) by using the sp_irwoke_external_re standpoint stored procedure.
Which Transact-SGL commands should you use for each requirement? To answer, drag the appropriate commands to the correct requirements. Each command may be used once, mote than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.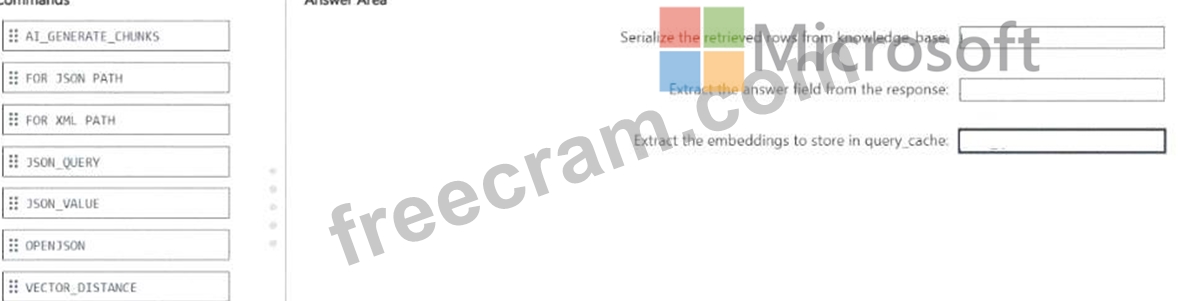
Answer:
Explanation: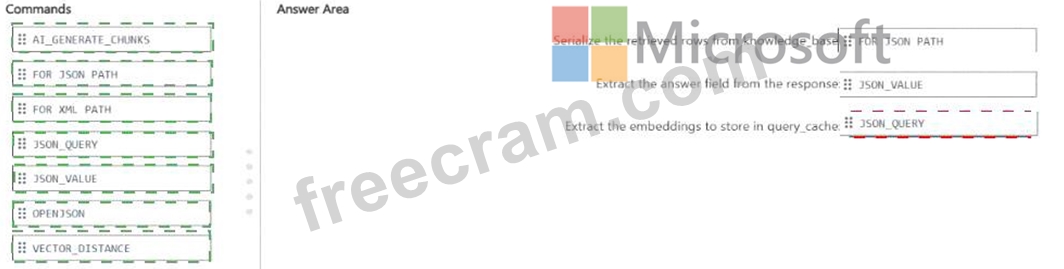
Explanation: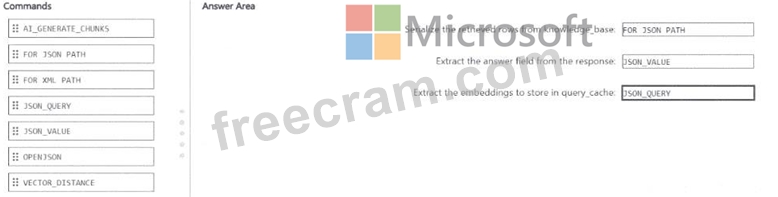
The correct mapping is:
* FOR JSON PATH
* JSON_VALUE
* JSON_QUERY
To serialize the retrieved rows from knowledge_base , the correct command is FOR JSON PATH .
Microsoft documents that FOR JSON formats query results as JSON, and PATH mode is the standard way to shape relational rows into JSON for downstream application or AI use.
To extract the answer field from the response , the correct command is JSON_VALUE because answer is a single scalar field . Microsoft states that JSON_VALUE is used to extract a scalar value from JSON text.
To extract the embeddings to store in query_cache , the correct command is JSON_QUERY because embeddings are returned as a JSON array , not a scalar. Microsoft states that JSON_QUERY extracts an object or array from JSON text, which is exactly the right behavior for an embeddings payload.
The unused options are not the best fit here:
* OPENJSON is mainly for shredding JSON into rows and columns.
* AI_GENERATE_CHUNKS is for chunking text, not extracting fields from a response payload.
* VECTOR_DISTANCE computes similarity between vectors and is unrelated to JSON extraction.
* FOR XML PATH produces XML, not JSON.
NEW QUESTION # 29
You have an Azure SQL database that supports an OLTP application.
You need to write Transact-SQL code that returns blocking chain details. The output must return only sessions that ate blocked or are blocking other sessions.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.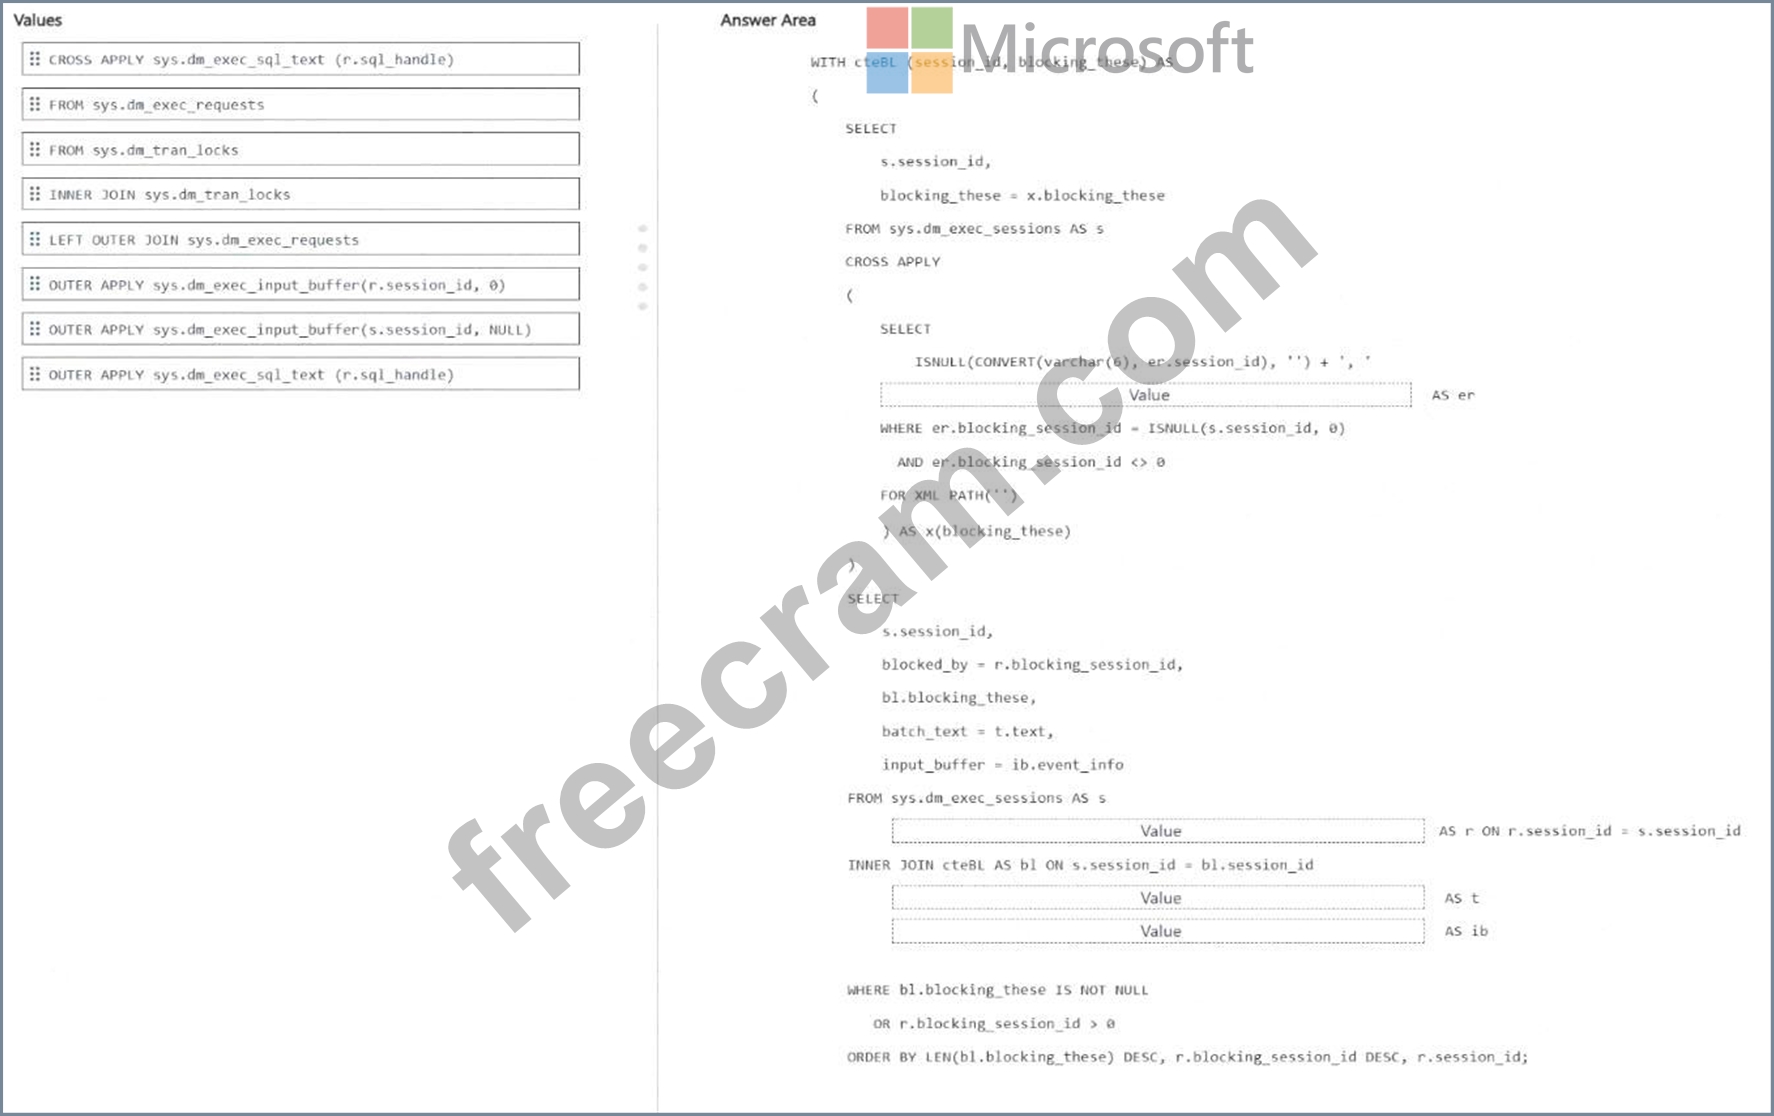
Answer:
Explanation: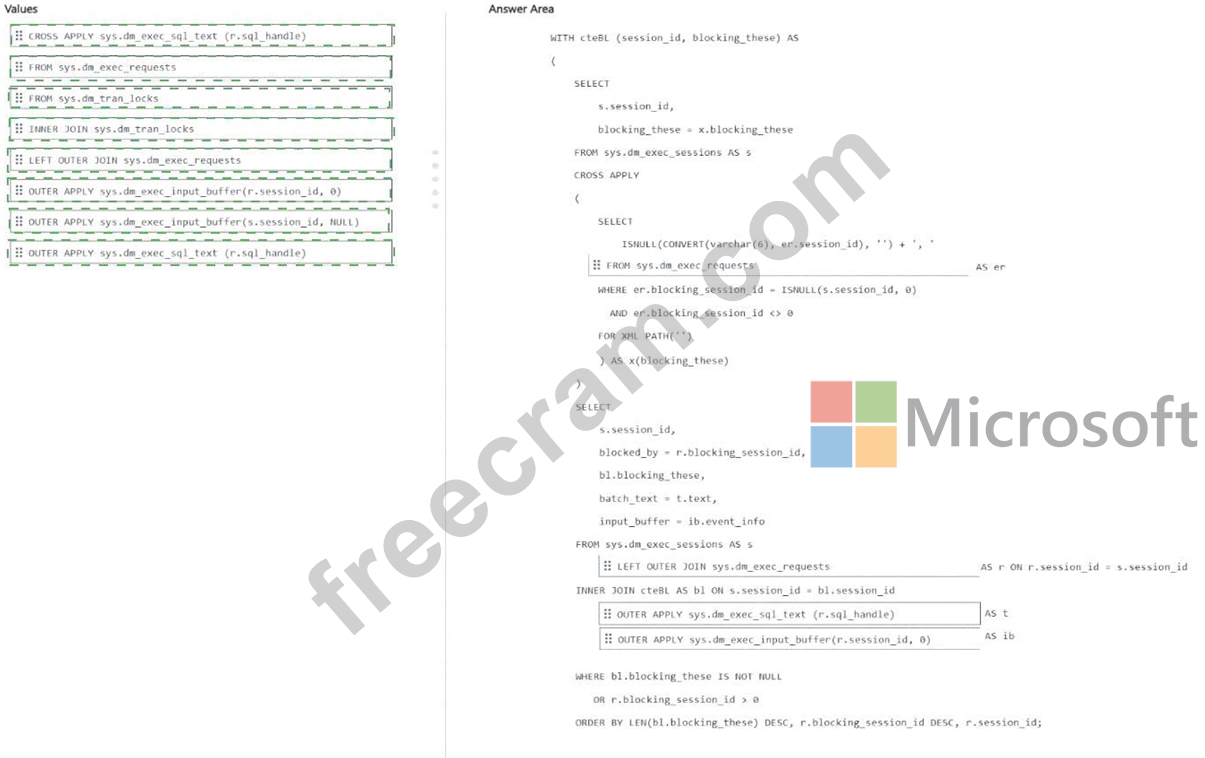
Explanation:
* CTE inner source # FROM sys.dm_exec_requests
* Join after sys.dm_exec_sessions AS s # LEFT OUTER JOIN sys.dm_exec_requests
* Text retrieval # OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* Input buffer retrieval # OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) The correct drag-and-drop choices are based on how blocking-chain details are normally assembled in Azure SQL Database.
The CTE must read from sys.dm_exec_requests because the alias er is used with er.session_id and er.
blocking_session_id, and those columns come from sys.dm_exec_requests. Microsoft documents that sys.
dm_exec_requests returns information about executing requests and includes the blocking_session_id column used to identify blockers.
After FROM sys.dm_exec_sessions AS s, the correct join is LEFT OUTER JOIN sys.dm_exec_requests so the query can still return sessions from sys.dm_exec_sessions even when a current request row is missing.
This is useful when showing sessions that are blocked or blocking, while still attempting to attach current request details when available.
For batch text, use OUTER APPLY sys.dm_exec_sql_text(r.sql_handle) because Microsoft documents sys.
dm_exec_sql_text(sql_handle) as the function that returns the SQL batch text for the specified sql_handle.
For the input buffer, use OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) because Microsoft documents that sys.dm_exec_input_buffer takes session_id and request_id and returns event_info, which is commonly used when sys.dm_exec_sql_text is null or when you want the last command text.
So the completed code uses:
* FROM sys.dm_exec_requests
* LEFT OUTER JOIN sys.dm_exec_requests
* OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id)
NEW QUESTION # 30
You have an Azure SQL database that stores order data. A reporting query aggregates monthly revenue per customer runs frequently.
You need to reduce how long it takes to retrieve the calculated values. The solution must NOT alter any underlying table structure. What should you do?
Answer: A
Explanation:
To speed up repeated aggregate retrieval without changing base-table structure, the right pattern is an indexed view . Microsoft requires that an indexed view be created with WITH SCHEMABINDING , and if the view uses GROUP BY , it must also include COUNT_BIG(*) . After that, the first index on the view must be a unique clustered index .
The other options fail Microsoft's indexed-view rules:
* A is invalid because ORDER BY is not allowed in the indexed-view definition.
* B is invalid because indexed views require WITH SCHEMABINDING , and the first index cannot just be a nonclustered index.
* C is incomplete because a grouped indexed view must include COUNT_BIG(*) .
NEW QUESTION # 31
You have an Azure SQL database.
You need to create a scalar user-defined function (UDF) that returns the number of whole years between an input parameter named 0orderDate and the current date/time as a single positive integer. The function must be created in Azure SQL Database. You write the following code.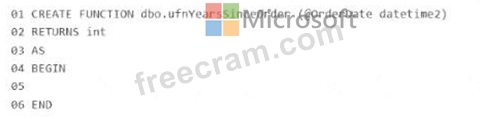
What should you insert at line 05?
Answer: D
Explanation:
The correct answer is D because the scalar UDF must return the number of whole years from the input
@OrderDate to the current date/time as a single positive integer . The correct DATEDIFF order is:
DATEDIFF(year, @OrderDate, GETDATE())
Microsoft documents that DATEDIFF(datepart, startdate, enddate) returns the count of specified datepart boundaries crossed between the start and end values. Since @OrderDate is the earlier date and GETDATE() is the later date, this ordering returns a positive result for past order dates.
The other choices are incorrect:
* A reverses the arguments and would return a negative value for a past order date.
* B is missing RETURN, and converting month difference to years by dividing by 12 is not the direct whole-year expression the question asks for.
* C subtracts year parts only, which can be off around anniversary boundaries because it ignores whether the full year has actually elapsed.
So the correct insertion at line 05 is:
RETURN DATEDIFF(year, @OrderDate, GETDATE());
NEW QUESTION # 32
......
We have the DP-800 Questions and answers with high accuracy and timely update. Our professional team checks DP-800 answers and questions carefully with their professional knowledge. We also have the latest information about the exam center, and will update the version according to the new requirements. Pass guarantee and money back guarantee are also our principles, and if you have any questions, you can also consult the service stuff.
Certification DP-800 Exam Cost: https://www.freecram.com/Microsoft-certification/DP-800-exam-dumps.html
BTW, DOWNLOAD part of FreeCram DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=16LxwSg5PROBGpfTX0YdrGcfnbKoHeZYd