Fast2test 培訓資源是個很了不起的資源網站,包括了Nutanix 的 NCP-BC-7.5 考試材料,研究材料,技術材料。認證培訓和詳細的解釋和答案。還有完善的售后服務,我們對所有購買 NCP-BC-7.5 題庫學習資料的客戶提供跟蹤服務,在你購買 NCP-BC-7.5 題庫學習資料后的半年內,享受免費升級題庫學習資料的服務。如果在這期間,Nutanix NCP-BC-7.5 的考試知識點發生變動,我們會在第一時間更新相關題庫學習資料,并免費提供給你下載。
| Section | Objectives |
|---|---|
| Nutanix Disaster Recovery Solutions | - Configuring and managing replication policies - Failover procedures and execution - Recovery workflows using Nutanix native tools - Integration with third-party backup solutions - Metro Availability configuration and management |
| Monitoring, Testing and Troubleshooting | - Diagnosing network, storage and replication failures - Setting up alerts for replication lag - Resolving third-party backup integration problems - Documenting runbooks for incident response - Troubleshooting permission issues and misconfigured DR environments - Non-disruptive recovery testing |
| Data Protection and Snapshots | - Snapshot scheduling and management - Data restoration at VM and application level - Snapshot retention policies design - Storage configuration for BCDR - Incremental backup implementation |
| Replication and Failover Architecture | - Failover readiness validation - Asynchronous replication planning - Synchronous replication across sites - Recovery site capacity management - Network segmentation for BCDR environments |
| BCDR Fundamentals and Requirements Interpretation | - Understanding RTO and RPO concepts and business impact analysis - Selecting appropriate replication types (async, near-sync, synchronous, metro) - Defining recovery strategies aligned to business requirements and risk tolerance - Availability metrics and SLA definitions - Translating business requirements into resilient recovery architectures |
| Security and Hardening | - RBAC implementation for disaster recovery - Approval policies configuration - Designing secure BCDR environments - Security best practices for replication |
Fast2test Nutanix 的 NCP-BC-7.5 題庫全面更新,是全球暢銷書籍、讀者公認 Nutanix 認證考試必備參考書。能讓您充滿信心地面對 Nutanix NCP-BC-7.5 認證考試。這更新版反映了 Nutanix 考試的最新變動, 不僅涵蓋了各項重要問題, 還加上了最新的考試知識。你的第一次嘗試使用我們的 NCP-BC-7.5 的培訓材料,這可能會極大地促進你的事業打開新的視野的就業機會。
問題 #65
An administrator recently expanded a Nutanix cluster by adding several new nodes. Shortly after, multiple backup jobs began failing. The following error is consistently reported: " Failed to perform backup: Cannot complete process ' iscsiadm --mode discovery --type sendtargets --portal X.X.X.X ' within timeout " . What is the most likely cause of the failure?
答案:B
解題說明:
Nutanix storage is often accessed by external backup solutions (like Veeam, Commvault, or HYCU) using the iSCSI protocol. This allows the backup server to mount snapshots and read data directly from the storage tier.
The error message " iscsiadm... discovery... timeout " specifically indicates that the backup server ' s iSCSI initiator is unable to communicate with the Nutanix Data Services IP or the Controller VMs (CVMs) over the network.
When a Nutanix cluster is expanded, it is essential that all networking and firewall configurations applied to the existing nodes are also applied to the new nodes. The iSCSI protocol relies on specific TCP ports: port
3260 is the standard port for iSCSI traffic, and port 3205 is often used for iSCSI discovery and metadata operations within Nutanix. If these ports are not open in the physical firewall or the host-based security rules for the newly added nodes, the backup server will be unable to discover the targets on those specific nodes, leading to the timeout errors . This highlights a common " Day 2 " operational trap: cluster expansion requires careful auditing of network security groups and firewall whitelists to ensure that external integrations- especially BCDR and backup services-continue to have uninterrupted access to the expanded storage fabric.
Verifying and opening ports 3205 and 3260 for the new node IPs is the first step to resolving this timeout issue.
問題 #66
A solution architect designs a protection policy in Prism Central to protect a specific set of VMs. The design calls for synchronous replication to two separate availability zones (AZs) simultaneously to ensure zero data loss at multiple physical locations. Which configuration limitation prevents the implementation of this specific design?
答案:B
解題說明:
Nutanix Disaster Recovery provides multisite replication capabilities, allowing a single cluster to protect workloads across multiple locations. However, there are specific architectural constraints regarding the type of replication schedules that can coexist within a single Protection Policy.
The primary limitation in this architect ' s design is that a single Nutanix Protection Policy supports only one synchronous replication schedule. While you can configure a policy to replicate to multiple sites using Asynchronous or NearSync schedules, you cannot natively instruct the system to perform a synchronous " 3- way " write where a single VM mirrors every I/O to two different physical destination clusters simultaneously. This is due to the extreme latency and metadata synchronization overhead that would be required to maintain zero-RPO consistency across three sites for every single write operation. Prism Central does allow pairing with more than one AZ (negating Option B), and synchronous replication is fully supported in Protection Policies (negating Option D). Therefore, to achieve the desired level of protection, the architect would need to use a combination of one synchronous schedule and additional asynchronous schedules to the second AZ, rather than attempting two simultaneous synchronous links within one policy.
問題 #67
What snapshot recovery point interval does Self-Service Restore support in a Nearsync setup?
答案:D
解題說明:
Self-Service Restore (SSR) is a Nutanix feature that allows end-users to recover individual files by mounting a recovery point as a local drive within the guest VM. NearSync replication provides high-frequency protection with Recovery Point Objectives (RPOs) as low as 1 minute using Lightweight Snapshots (LWS).
However, there is a technical distinction in how these high-frequency points are handled for end-user recovery.
In a NearSync configuration, the system generates dozens of LWS throughout an hour. While these are available for full VM disaster recovery, Nutanix limits the " granularity " available for Self-Service Restore to manage metadata overhead and guest agent performance. By default, SSR in a NearSync environment typically supports recovery point intervals of 1 hour. This means that while an administrator can restore the entire VM to a state from 5 minutes ago, an end-user using the SSR browser inside the VM will see recovery points at 1-hour increments (the " consolidated " points). This design balances the need for high-frequency disaster protection with the operational efficiency of file-level recovery. If a user needs a file from a point between the hourly intervals, an administrator may need to perform a full VM clone or an " Out-of-place " restore to provide access to those more granular lightweight recovery points.
問題 #68
An administrator has received the following alert: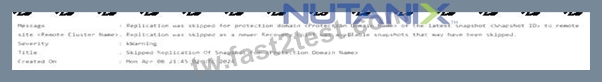
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
答案:B
解題說明:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
問題 #69
Which combination of Replication Schedules within the same Recovery Plan will cause the recovery to fail?
答案:C
解題說明:
A Recovery Plan in Nutanix is the orchestration engine that defines the power-on sequence, network mappings, and script execution for disaster recovery. While a single cluster can support various types of replication-Asynchronous, NearSync, and Synchronous-there are strict architectural limits on how these can be mixed within a single automated plan.
The primary conflict arises when mixing Synchronous (0 RPO) schedules with snapshot-based Asynchronous or NearSync schedules. Synchronous replication is an " Active-Standby " or " Active-Active " storage state where the destination site already has the data in a " mounted " but inactive container. In contrast, Asynchronous and NearSync recovery involve " restoring " a VM from a specific recovery point (snapshot), which includes registering the VM and attaching the disks during the failover process. Because the orchestration logic for a Zero-RPO synchronous failover is fundamentally different from a snapshot restoration, Nutanix prevents placing them in the same Recovery Plan. Attempting to do so will cause validation errors and lead to execution failure, as the orchestrator cannot simultaneously manage real-time failover and snapshot-based restoration for the same logical group. To successfully protect an environment with both types of RPO requirements, administrators must create separate Recovery Plans: one dedicated to Synchronous workloads and another for snapshot-based Asynchronous/NearSync workloads, ensuring that each set of VMs follows its appropriate recovery workflow.
問題 #70
......
Nutanix的NCP-BC-7.5考試認證肯定會導致你有更好的職業前景,通過Nutanix的NCP-BC-7.5考試認證不僅驗證你的技能,也證明你的證書和專業知識,Fast2test Nutanix的NCP-BC-7.5考試培訓資料是實踐檢驗的軟體,有了它你會得到的理解理論比以前任何時候都要好,將是和你最配備知識。在你決定購買之前,你可以嘗試一個免費的使用版本,這樣一來你就知道Fast2test Nutanix的NCP-BC-7.5考試培訓資料的品質,也是你最佳的選擇。
新版NCP-BC-7.5考古題: https://tw.fast2test.com/NCP-BC-7.5-premium-file.html