P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1btaeqyKEc8fHwzWLEM1LDcuTbIxm73b2
If you want to pass the AWS Certified Machine Learning Engineer - Associate exam as shortly as possible, we will provide you the MLA-C01 exam dumps to help you to pass it. You only need to practice the AWS Certified Machine Learning Engineer - Associate exam dumps for adot 20 to 70 hours, you can pass it successfully. Our AWS Certified Machine Learning Engineer - Associate exam braindumps will save your time as well as improve your efficiency. Since the skilled professionals will guide you through you practice MLA-C01 the exam dumps.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Reliable Exam Camp <<
According to the statistic about candidates, we find that some of them take part in the Amazon exam for the first time. Considering the inexperience of most candidates, we provide some free trail for our customers to have a basic knowledge of the MLA-C01 exam guide and get the hang of how to achieve the MLA-C01 exam certification in their first attempt. You can download a small part of PDF demo, which is in a form of questions and answers relevant to your coming MLA-C01 Exam; and then you may have a decision about whether you are content with it. In fact, there are no absolutely right MLA-C01 exam questions for you; there is just a suitable learning tool for your practices. Therefore, for your convenience and your future using experience, we sincere suggest you to have a download to before payment.
NEW QUESTION # 30
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token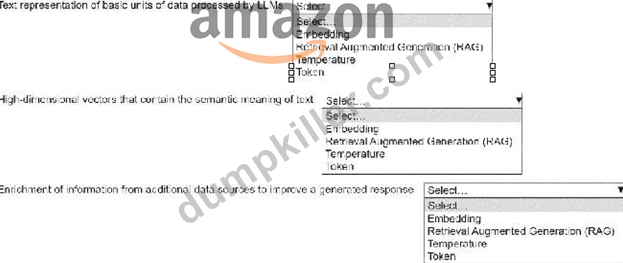
Answer:
Explanation: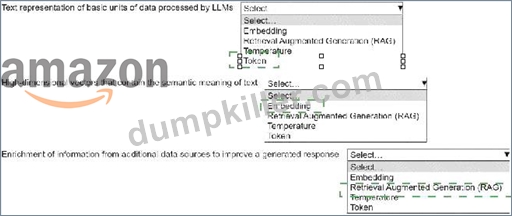
Explanation: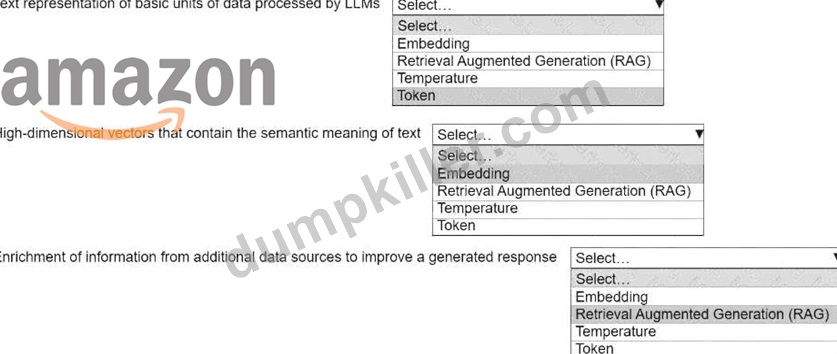
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 31
A company uses Amazon Athena to query a dataset in Amazon S3. The dataset has a target variable that the company wants to predict.
The company needs to use the dataset in a solution to determine if a model can predict the target variable.
Which solution will provide this information with the LEAST development effort?
Answer: C
Explanation:
The requirement is to quickly determine whether the target variable is predictable, with minimal development effort. Amazon SageMaker Autopilot is specifically designed for this purpose.
SageMaker Autopilot automatically handles data preprocessing, feature engineering, algorithm selection, model training, and evaluation. It generates multiple candidate models and provides detailed performance metrics, allowing teams to quickly assess predictability without writing custom code.
Option B requires significant manual development. Option C is incorrect because Amazon Macie is a data security and classification service, not an ML modeling service. Option D is unsuitable because Amazon Bedrock models are not intended for structured tabular prediction tasks.
Therefore, SageMaker Autopilot provides the fastest and least effort solution.
NEW QUESTION # 32
A company needs an AWS solution that will automatically create versions of ML models as the models are created. Which solution will meet this requirement?
Answer: C
Explanation:
Option D is correct because Amazon SageMaker Model Registry is the AWS feature specifically designed to catalog models, manage model versions, and organize them into model groups . AWS documentation states that you can create a Model Group and then register each model you train , and the Model Registry adds it to the Model Group as a new model version . That directly matches the requirement to automatically create versions of ML models as models are created.
The AWS docs also describe a standard workflow in which you first create a Model Group, then create an ML pipeline, and for each run of the ML pipeline , create a model version that is registered in that group. This means Model Registry supports exactly the kind of lifecycle management and version tracking needed in an MLOps workflow where new model artifacts are produced over time and need consistent governance.
The other options do not meet the requirement. Amazon ECR stores container images, not model version history. SageMaker Marketplace model packages are for discovering or subscribing to third-party or prebuilt solutions, not for automatically versioning your organization's trained models. SageMaker ML Lineage Tracking helps trace artifacts, datasets, and processing steps for reproducibility, but AWS documentation distinguishes lineage from the actual model version management capability provided by Model Registry. Model Registry is the AWS-native feature for keeping versioned records of trained models and managing approval status, deployment readiness, and metadata in a centralized way.
Therefore, the fully verified AWS-docs answer is D , because SageMaker Model Registry is the service purpose-built to create and manage model versions as new models are produced.
NEW QUESTION # 33
Hotspot Question
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store.
Each step should be selected one time. (Select and order three.)
- Access the store to build datasets for training.
- Create a feature group.
- Ingest the records.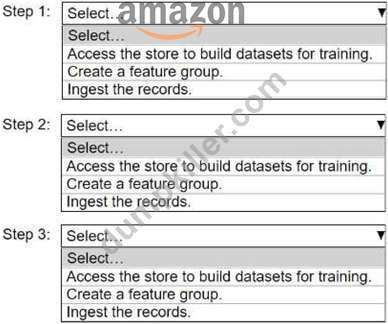
Answer:
Explanation: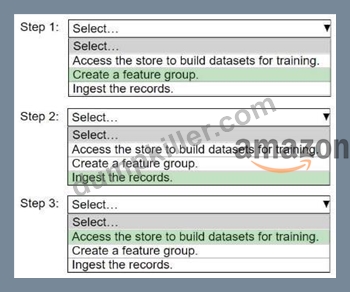
NEW QUESTION # 34
A bank needs to use Amazon SageMaker AI to create an ML model to determine which customers qualify for a new product. The bank must use algorithms that SageMaker AI directly supports. The model must be explainable to the bank ' s regulators.
Which modeling approach will meet these requirements?
Answer: B
Explanation:
Option B is correct because the bank needs a SageMaker-supported algorithm and the resulting model must be explainable for regulators. AWS documentation states that the Amazon SageMaker AI linear learner algorithm is a built-in algorithm that provides a solution for classification and regression problems. Since determining whether customers qualify for a new product is a classification-style decision problem, linear learner fits the business requirement directly.
The explainability requirement strongly favors a simpler and more interpretable model family. AWS Prescriptive Guidance on model interpretability states that simple models are considered more interpretable because the effects of input features on the output are easier to understand. It specifically gives linear regression as an example where the magnitudes of coefficients provide a clear global feature-importance signal. While the question does not explicitly mention SageMaker Clarify, AWS documentation also says SageMaker offers explainability features to help interpret predictions, which complements inherently interpretable model types such as linear models.
The other options are weaker fits. Object2Vec is mainly for learning embeddings and similarity relationships rather than a straightforward explainable eligibility model. A neural network may work technically, but it is generally less interpretable for regulatory review. k-means is an unsupervised clustering algorithm and is not suitable for predicting whether a customer qualifies for a product. Because the bank wants a directly supported SageMaker algorithm and a model that is easier to explain to regulators, the best AWS-aligned answer is B, linear learner.
NEW QUESTION # 35
......
We can proudly claim that you can successfully pass the exam just on the condition that you study with our MLA-C01 preparation materials for 20 to 30 hours. And not only you will get the most rewards but also you will get an amazing study experience by our MLA-C01 Exam Questions. For we have three different versions of our MLA-C01 study guide, and you will have different feelings if you have a try on them.
Dumps MLA-C01 Download: https://www.dumpkiller.com/MLA-C01_braindumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1btaeqyKEc8fHwzWLEM1LDcuTbIxm73b2