2026 Latest DumpsQuestion AI-103 PDF Dumps and AI-103 Exam Engine Free Share: https://drive.google.com/open?id=1YsxhCTxQqh3V66erxbd5Vvj3LohPnQxg
The AI-103 exam questions by experts based on the calendar year of all kinds of exam after analysis, it is concluded that conforms to the AI-103 exam thesis focus in the development trend, and summarize all kind of difficulties you will face and highlight the user review must master the knowledge content. And as far as possible with extremely concise prominent text of AI-103 Test Guide is accurate incisive expression of the proposition of this year's forecast trend, and through the simulation of topic design meticulously. Your success is ready with our AI-103 exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Implement agentic solutions | 20-25% | - Manage agent operations
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
>> Microsoft AI-103 New Study Plan <<
We stick to the principle "Credit management first and first class service". While purchasing our AI-103 exma questions, not only you have no need to worry about the quality of our AI-103 exam materials quality but also our service is satisfying on the AI-103 study guide. We promise buyers “Pass Guaranteed” and we only offer the latest AI-103 Training Materials. If you would like to choose safely high passing rate of AI-103 exam torrent materials, our AI-103 learning guide will be the first choice for you.
NEW QUESTION # 96
You have a product support manual.
You need to build a product support chatbot based on the manual. The solution must minimize development effort and costs.
What should you use?
Answer: A
Explanation:
Azure OpenAI On Your Data makes it easier for developers to connect, ingest and ground their enterprise data to create personalized copilots (preview) rapidly. It enhances user comprehension, expedites task completion, improves operational efficiency, and aids decision- making.
Azure OpenAI On Your Data enables you to run advanced AI models such as GPT-35-Turbo and GPT-4 on your own enterprise data without needing to train or fine-tune models. You can chat on top of and analyze your data with greater accuracy. You can specify sources to support the responses based on the latest information available in your designated data sources.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/openai/concepts/use-your-data
NEW QUESTION # 97
You have a Microsoft Foundry project that contains a customer support agent built on a deployed chat model.
The agent responses are validated by using an automated testing system that compares generated answers to stored expected outputs. Identical prompts must return consistent responses to prevent automated test failures.
You need to reduce response variability, without modifying the prompt or reducing factual accuracy.
Answer: B
Explanation:
The temperature parameter controls randomness during token selection. A higher temperature broadens the probability distribution and permits less-likely tokens to be selected, producing more varied or creative responses. A lower temperature concentrates selection on the highest-probability tokens, resulting in responses that are more focused, concrete, and consistent across repeated requests. Microsoft's prompt- engineering guidance explicitly states that higher temperatures produce more divergent output, whereas lower values reduce randomness.
Therefore, decreasing the temperature-typically toward zero for automated validation scenarios-is the appropriate configuration change. It reduces wording and structural variation without changing the prompt or intentionally limiting the information available to the model. Although probabilistic model execution does not guarantee byte-for-byte identical output in every circumstance, this is the correct parameter for minimizing variability among the available choices.
Increasing max_tokens only raises the maximum response length and does not control sampling randomness.
Stop sequences define where generation terminates; removing them can change response length but does not make responses deterministic. Increasing temperature would directly increase variability.
Study Guide alignment: Optimize and operationalize generative AI systems-tune generation behavior through prompt engineering and model parameters, and evaluate agent behavior for production reliability.
NEW QUESTION # 98
You need to recommend a plan to create a customer support agent by using the Microsoft Foundry Agent Service. The agent must meet the following requirements:
* Retain user preferences across multiple conversations.
* Enable users to provide contextual grounding by directly uploading documents during a chat.
Which Foundry capability should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.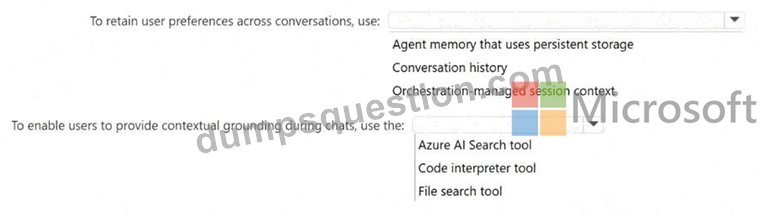
Answer:
Explanation: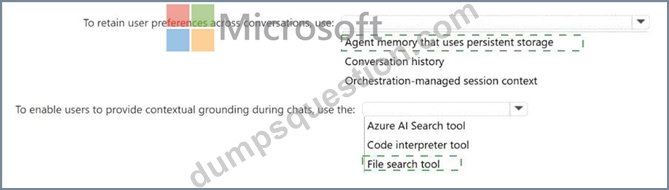
Explanation:
To retain user preferences across conversations, use: Agent memory that uses persistent storage To enable users to provide contextual grounding during chats, use the: file search tool The correct capability for retaining user preferences is agent memory that uses persistent storage .
Microsoft Foundry Agent Service memory is a managed long-term memory capability that enables continuity across sessions, devices, and workflows. It is specifically intended to let agents retain user preferences, maintain relevant historical context, and personalize responses across separate conversations. Memory stores provide the persistent storage layer, and scope can be used to segment memories for secure user-specific experiences.
The correct capability for contextual grounding from user-uploaded documents is the file search tool .
Microsoft describes file search as the tool that enables Foundry agents to search through documents and retrieve relevant information from outside the base model, including proprietary product information and user- provided documents. The file search workflow supports uploading files, creating a vector store, enabling the tool on the agent, and querying those documents through the agent.
Conversation history alone supports continuity within a conversation, but it is not durable preference memory across multiple conversations. An Azure AI Search tool is better for preconfigured enterprise indexes, while file search is the direct document-upload grounding capability. Reference topics: Foundry Agent Service memory, memory stores, File Search tool, vector stores, and grounded agent responses.
NEW QUESTION # 99
You have a Microsoft Foundry project that contains an internal Q & A agent.
Users report the following issues when they ask the agent questions:
* An increase in the following response: "No relevant information found"
* Periodic HTTP 429 rate limit exceeded errors during peak hours
You need to identify whether each issue is caused by model unavailability, resource limits, or inference failures.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.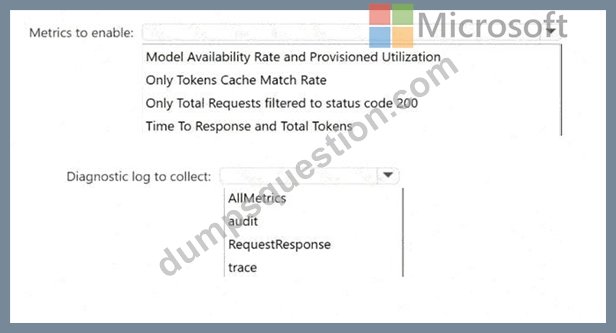
Answer:
Explanation: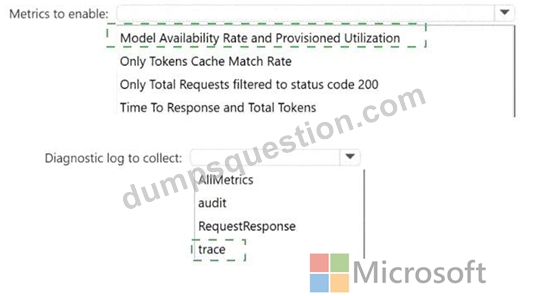
Explanation:
Metrics to enable: Model Availability Rate and Provisioned Utilization
Diagnostic log to collect: trace
The correct metrics are Model Availability Rate and Provisioned Utilization . Model Availability Rate identifies whether failures are caused by service-side model unavailability because it is calculated from total calls minus server errors. Provisioned Utilization identifies resource-limit conditions because Microsoft states that when utilization reaches or exceeds 100%, calls are throttled and HTTP 429 errors are returned. This directly maps to the reported peak-hour rate-limit errors.
The correct diagnostic log is trace . For an internal Q & A scenario, trace logging is required to analyze question-answering behavior, including unanswered questions. Microsoft's custom question answering analytics guidance states that diagnostic logging stores telemetry and chat logs and instructs enabling Trace in addition to Audit, RequestResponse, and AllMetrics. The sample Kusto queries for unanswered questions inspect the answer, question, score, and knowledge base ID, and filter unanswered results by a score of zero.
RequestResponse is useful for request status and latency, and Audit is for administrative operations, but neither is the best diagnostic category for analyzing Q & A inference behavior such as "No relevant information found." Reference topics: Foundry monitoring, model availability, provisioned utilization, diagnostic logging, custom question answering analytics, and trace logs.
NEW QUESTION # 100
Hotspot Question
You have a Microsoft Foundry project that contains an agent.
You use a GitHub Actions workflow for CI/CD.
You need to configure the workflow to automatically evaluate the agent when a pull request (PR) is created and prevent branches from merging if the evaluation results do NOT meet the defined thresholds.
How should you configure the workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.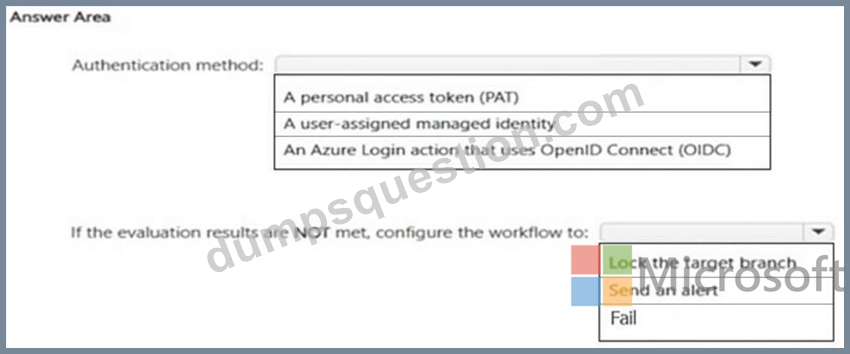
Answer:
Explanation: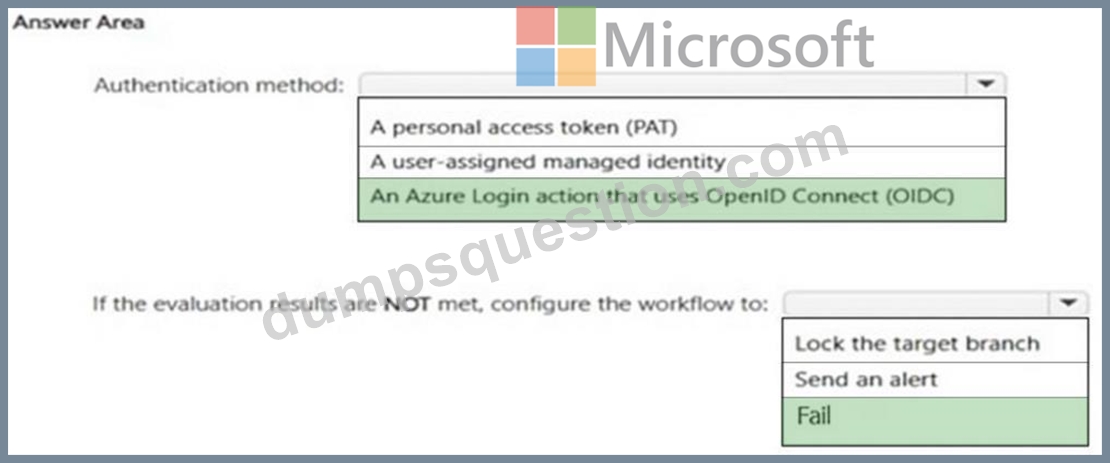
NEW QUESTION # 101
......
As you see, all of the three versions of our AI-103 exam dumps are helpful for you to get the AI-103 certification. So there is another choice for you to purchase the comprehensive version which contains all the three formats. And no matter which format of AI-103 study engine you choose, we will give you 24/7 online service and one year's free updates. Moreover, we can assure you a 99% percent pass rate.
New AI-103 Test Forum: https://www.dumpsquestion.com/AI-103-exam-dumps-collection.html
2026 Latest DumpsQuestion AI-103 PDF Dumps and AI-103 Exam Engine Free Share: https://drive.google.com/open?id=1YsxhCTxQqh3V66erxbd5Vvj3LohPnQxg