You will fail and waste time and money if you do not prepare with real and updated Anthropic CCAR-P Questions. You should practice with actual CCAR-P exam questions that are aligned with the latest content of the CCAR-P test. These Anthropic CCAR-P exam questions remove the need for you to spend time on unnecessary or irrelevant material, allowing you to complete your CCAR-P Certification Exam preparation swiftly. You can save time and clear the Claude Certified Architect - Professional (CCAR-P) test in one sitting if you skip unnecessary material and focus on our CCAR-P actual questions.
| Section | Weight | Objectives |
|---|---|---|
| Integration | 19% | - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations - Integrate Claude with enterprise systems, APIs, and tools |
| Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
| Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost - Define evaluation metrics and success criteria |
| Governance, Safety & Risk Management | 14% | - Address ethical AI considerations and bias mitigation - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Implement guardrails and safety controls - Manage data privacy and security compliance |
| Stakeholder Communication & Lifecycle Management | 14% | - Communicate architectural decisions and trade-offs - Conduct structured discovery and requirement gathering - Manage stakeholder feedback and expectation alignment - Document architectures and support full lifecycle phases |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Select appropriate Claude models based on trade-offs - Design system prompts, templates, and guardrails - Mitigate prompt injection, leaks, and jailbreak risks |
| Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Design end-to-end architectures and feedback loops - Select architectural patterns: workflow, agentic, augmented LLM - Translate business problems into Claude-based AI solutions - Align solutions to business value pillars |
>> Question CCAR-P Explanations <<
Providing our customers with up to 1 year of free Anthropic CCAR-P questions updates is also our offer. These Anthropic CCAR-P free dumps updates will help you prepare according to the latest CCAR-P test syllabus in case of changes. 24/7 customer support is available at 2Pass4sure to assist users of the CCAR-P Exam Questions through the journey. Above all, 2Pass4sure also offers a full refund guarantee (terms and conditions apply) to our customers. Don't miss these amazing offers. Download Claude Certified Architect - Professional (CCAR-P) actual exam Dumps today!
NEW QUESTION # 120
You are a solution architect designing a Claude-based assistant with access to 60 internal tools across multiple business domains. Loading every tool definition on every request increases token usage and time to first response.
Which design pattern best addresses this issue without sacrificing capability breadth?
Answer: D
Explanation:
Progressive tool discovery preserves the complete capability catalog while limiting initial context to a curated set of common common common tools and a discovery mechanism. When the task requires an additional capability, Claude searches the catalog and loads only the relevant tool definitions.
Anthropic's Tool Search mechanism implements implements this pattern through deferred loading. The context initially contains the search search search tool and any deliberately non-deferred tools; relevant definitions are expanded only when discovered. This reduces token consumption and helps maintain tool- selection accuracy in large catalogs. ToolTool Search Tool Option B adds a model call and still repeatedly processes all definitions, increasing latency latency latency and cost while potentially losing important schema details. Option C treats a larger context window as permission to waste context and does not address time-to-first-response overhead. Option D reduces capability breadth because the fixed five tools may be irrelevant to a given task.
The architect should provide clear tool and server server server descriptions, define which high-frequency tools remain immediately available, and evaluate discovery recall, selection accuracy
NEW QUESTION # 121
You are designing a content moderation classifier that processes high volumes of user-generated comments under a tight per-message latency budget using well-defined classification labels.
Which model selection best aligns with the workload?
Answer: C
Explanation:
Haiku is the appropriate starting point because the workload is high-volume, latency-sensitive, and based on a stable closed set of moderation labels. These characteristics favor a fast, cost-efficient model capable of consistent classification without incurring the additional inference time and expense associated with deeper reasoning.
Anthropic's model-selection guidance requires architects to balance capability, speed, and cost rather than automatically selecting the most capable model. Its content-moderation guidance specifically identifies Haiku as a cost-effective option for processing moderation workloads at substantial scale. Choosing the Right Model
, Content Moderation
Opus is disproportionate to a routine closed-set classification problem. Sonnet may become justified if evaluation demonstrates that Haiku fails materially on complex policy distinctions, multilingual ambiguity, or adversarial edge cases, but it should not be selected merely because it is larger. Enabling extended thinking on every request would further increase latency and token consumption without evidence that the additional reasoning improves the defined success metrics. The correct architectural practice is to establish a representative moderation evaluation set, validate Haiku against accuracy and safety thresholds, and escalate only the cases that genuinely need deeper reasoning.
Study Guide references/topics: Model selection; capability-latency-cost trade-offs; classification workloads; evaluation-driven routing; moderation architecture.
NEW QUESTION # 122
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.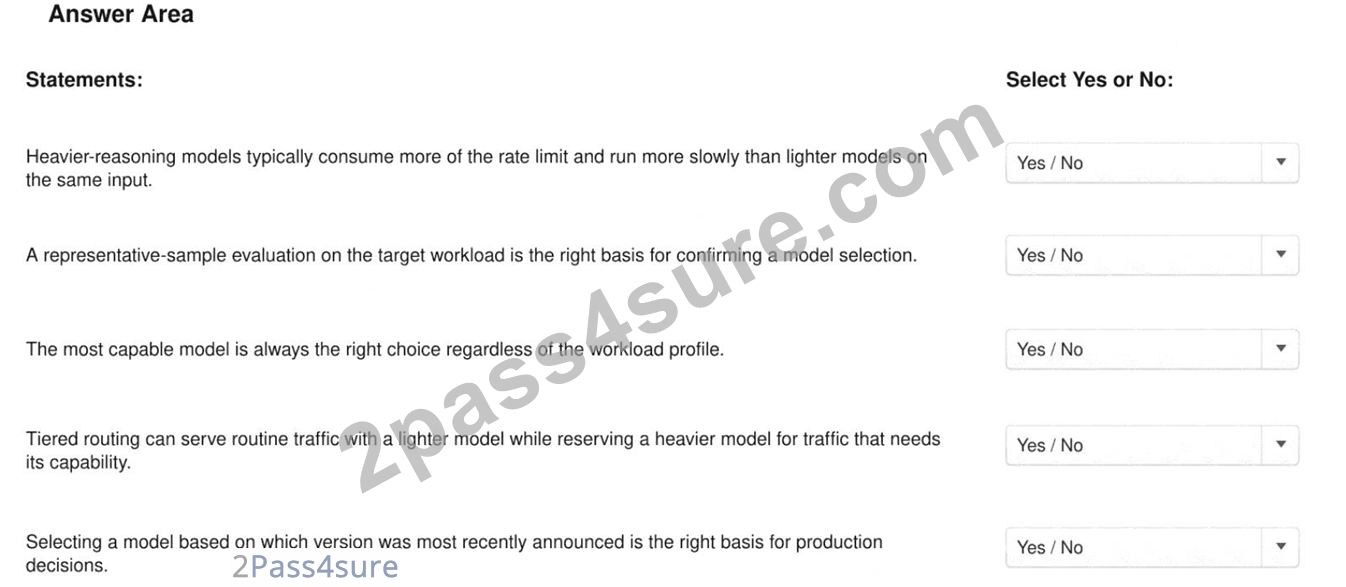
Answer:
Explanation: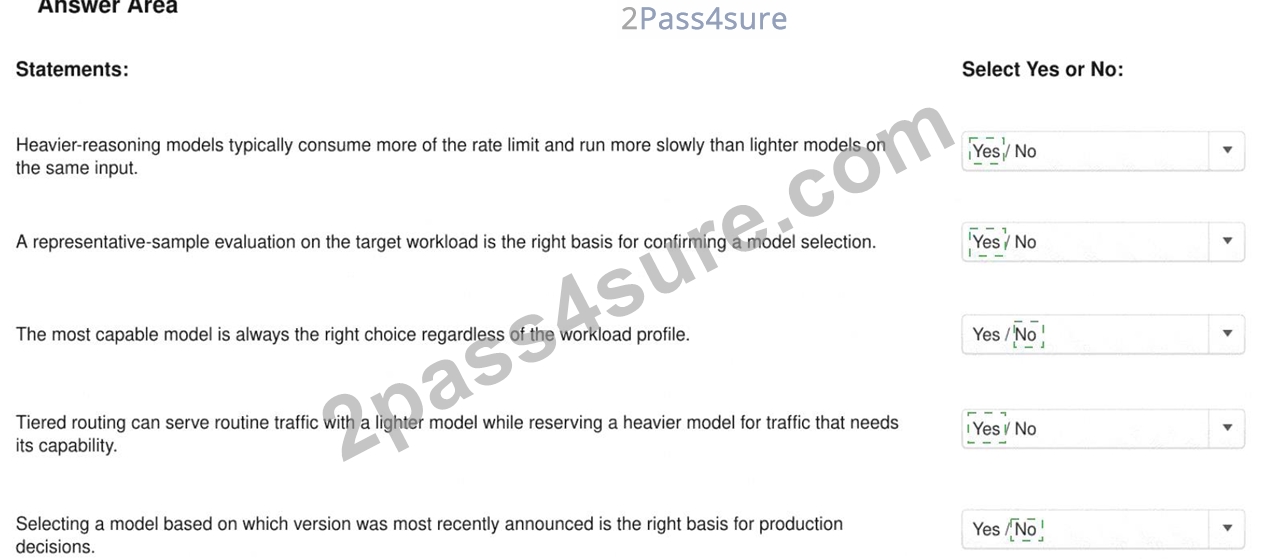
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
NEW QUESTION # 123
A revenue projection assistant has missed its monthly cost target by 38 percent. Profiling shows three contributors: a 6,000-token policy preamble repeated on every call (45 percent of cost), retrieval of historical sales chunks averaging 3,000 tokens per call (30 percent), and inference on a flagship-tier model (25 percent).
Stakeholders require that projection accuracy remain unchanged.
Which two optimizations should you sequence first to reduce cost without affecting accuracy? (Select two.) Each correct answer presents part of the solution.
Answer: C,D
Explanation:
The required sequence must reduce repeated computation without changing the information or model capability used to generate projections. Prompt caching the static 6,000-token policy preamble directly addresses the largest cost contributor while preserving the complete instruction set. Anthropic states that cache reads cost substantially less than uncached input tokens, making repeated, stable prompt prefixes an ideal caching target. Prompt Caching Caching frequently reused historical-sales chunks applies the same principle to the retrieval layer. When identical, version-controlled chunks are repeatedly fetched and supplied to the model, caching their retrieval or reusable representation eliminates redundant work while maintaining the same evidence available to the projection process. The cache must use appropriate invalidation or source-version keys so updated sales data cannot be replaced by stale content.
Options A and B modify the information supplied to Claude. Fewer sales chunks could remove relevant historical evidence, while truncating policy instructions could alter constraints or projection behavior. Option D introduces a model-capability change and therefore cannot guarantee unchanged accuracy without a comparative evaluation. Those interventions may be considered later, but only after representative regression testing establishes equivalence.
Study Guide references/topics: Cost profiling; prompt caching; retrieval caching; cache invalidation; accuracy- preserving optimization; model and context trade-offs.
NEW QUESTION # 124
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.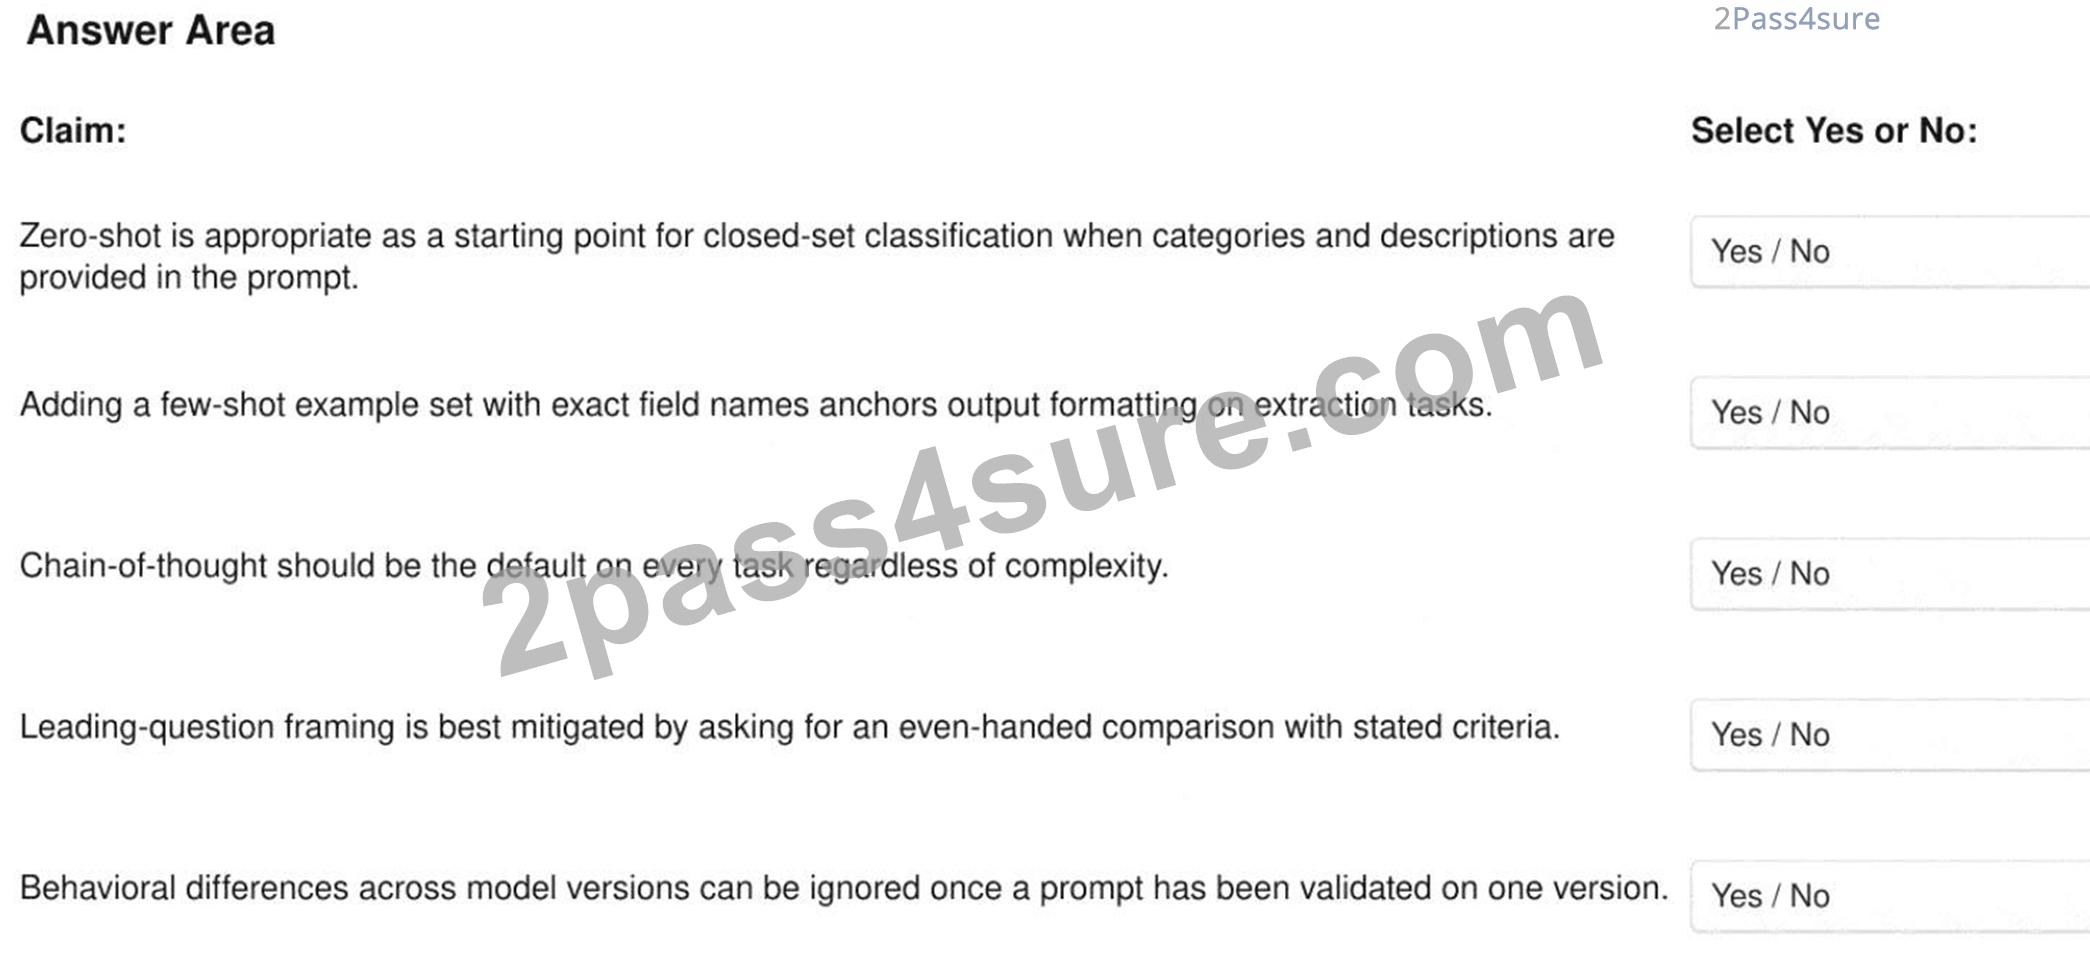
Answer:
Explanation: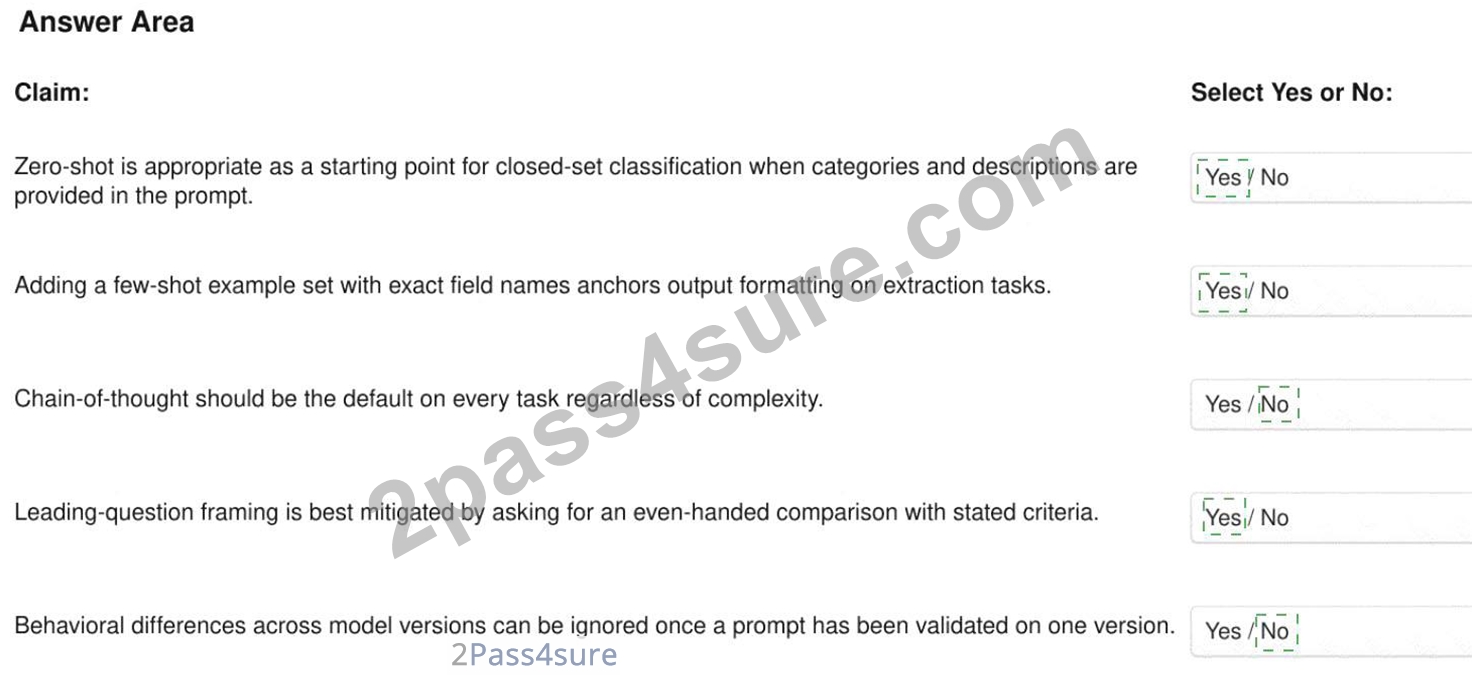
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 125
......
If you purchasing our CCAR-P simulating questions, you will get a comfortable package services afforded by our considerate after-sales services. We respect your needs toward the useful CCAR-P practice materials by recommending our CCAR-P Guide preparations for you. Only in a few minutes, your ordered CCAR-P exam questions are sent to you, and whenever you have any question on the CCAR-P practice guide, you can contact with our service at 24/7.
CCAR-P Passing Score: https://www.2pass4sure.com/Claude-Certified-Architect/CCAR-P-actual-exam-braindumps.html