Certified-Data-Engineer-Professional Test Guide | Certified-Data-Engineer-Professional Popular Exams

BTW, DOWNLOAD part of RealValidExam Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1eH5vYbAKB6fwJW4H252-YRsnujQu2JQE
Our company is a professional certification exam materials provider, we have occupied in the field for more than ten years, and therefore we have rich experiences. In addition, Certified-Data-Engineer-Professional Exam Materials have free demo, and you can have a try before buying, so that you can have a deeper understanding for Certified-Data-Engineer-Professional exam dumps. We are pass guarantee and money back guarantee, and if you fail to pass the exam, we will give you full refund. You can receive your download link and password within ten minutes, so that you can start your learning as quickly as possible. We have online and offline chat service, if you have any questions for the exam, you can consult us.
| Section | Objectives |
|---|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Use control flow operators in pipeline components
- 6. Develop unit and integration tests for data processing code
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
>> Certified-Data-Engineer-Professional Test Guide <<
Valid Certified-Data-Engineer-Professional exam materials offer you accurate preparation dumps - RealValidExam
We offer you free update for 365 days for Certified-Data-Engineer-Professional study guide materials, so that you can have a better understanding of what you are going to buy. And update version for Certified-Data-Engineer-Professional exam materials will be sent to your email automatically. In addition, Certified-Data-Engineer-Professional exam materials are compiled by experienced experts, and they are quite familiar with the exam center, therefore if you choose us, you can get the latest information for the exam We also have online and offline chat service, if you have any questions about Certified-Data-Engineer-Professional Study Guide, you can contact with us online or by email, and we will give you reply as quickly as we can.
Databricks Certified Data Engineer Professional Sample Questions (Q167-Q172):
NEW QUESTION # 167
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
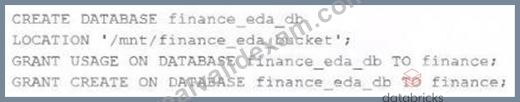
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
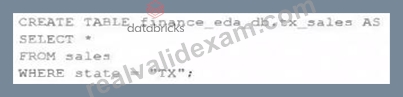
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- B. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- C. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- D. A managed table will be created in the DBFS root storage container.
- E. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
Answer: B
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 168
A data engineering team is configuring access controls in Databricks Unity Catalog. They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog. What describes the privilege inheritance behavior in Unity Catalog?
- A. Granting SELECT at the catalog level applies to existing schemas and tables but not to those created in the future.
- B. Privileges in Unity Catalog do not cascade; SELECT must be explicitly granted on each schema and table, even if granted at the catalog level.
- C. Granting SELECT on a catalog automatically applies SELECT to all current and future schemas, tables, and views within that catalog.
- D. Privileges granted at the schema level override any catalog-level privileges and prevent access unless explicitly revoked.
Answer: B
Explanation:
In Unity Catalog, privileges are non-cascading--meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
NEW QUESTION # 169
The data engineer is using Spark's MEMORY_ONLY storage level. Which indicators should the data engineer look for in the spark UI's Storage tab to signal that a cached table is not performing optimally?
- A. The RDD Block Name included the '' annotation signaling failure to cache
- B. The number of Cached Partitions> the number of Spark Partitions
- C. Size on Disk is> 0
- D. Size on Disk is < Size in Memory
- E. On Heap Memory Usage is within 75% of off Heap Memory usage
Answer: C
Explanation:
When using Spark's MEMORY_ONLY storage level, the ideal scenario is that the data is fully cached in memory, and the Size on Disk should be 0 (indicating that the data is not spilled to disk). If the Size on Disk is greater than 0, it suggests that some data has been spilled to disk, which can lead to degraded performance as reading from disk is slower than reading from memory.
NEW QUESTION # 170
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
- A. @dlt.table
@dlt.expect("valid_customer", "customer_id IS NOT NULL")
@dlt.expect("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - B. @dlt.table
@dlt.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
@dlt.expect_or_drop("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - C. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect("valid_customer", "customer_id IS NOT NULL")
.expect("valid_amount", "amount > 0")
) - D. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
.expect_or_drop("valid_amount", "amount > 0")
)
Answer: D
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 171
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. The Delta log creates a term matrix for free text fields to support selective filtering.
- B. ZORDER ON review will need to be run to see performance gains.
- C. Delta Lake statistics are only collected on the first 4 columns in a table.
- D. Text data cannot be stored with Delta Lake.
- E. Delta Lake statistics are not optimized for free text fields with high cardinality.
Answer: E
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 172
......
Using these Databricks Certified-Data-Engineer-Professional practice test software you will identify your mistakes, gain confidence and learn time-management skills. It will help you to prepare better for the final Certified-Data-Engineer-Professional exam. RealValidExam Databricks Certified-Data-Engineer-Professional Valid Dumps - Free Demo Download & Refund Guarantee Databricks Certified-Data-Engineer-Professional exam dumps are the best option if you really want to pass the Databricks Certified Data Engineer Professional exam on your first attempt.
Certified-Data-Engineer-Professional Popular Exams: https://www.realvalidexam.com/Certified-Data-Engineer-Professional-real-exam-dumps.html
- Free Certified-Data-Engineer-Professional Exam ✳ Reliable Certified-Data-Engineer-Professional Exam Cram 🈺 Relevant Certified-Data-Engineer-Professional Questions 🗓 Open website ⏩ www.testkingpass.com ⏪ and search for [ Certified-Data-Engineer-Professional ] for free download 🎫Free Certified-Data-Engineer-Professional Download Pdf
- Reliable Certified-Data-Engineer-Professional Test Guide Covers the Entire Syllabus of Certified-Data-Engineer-Professional 🔀 Easily obtain free download of ▛ Certified-Data-Engineer-Professional ▟ by searching on ➥ www.pdfvce.com 🡄 🎱Practical Certified-Data-Engineer-Professional Information
- Reliable Certified-Data-Engineer-Professional Braindumps Ebook 💿 Certified-Data-Engineer-Professional Certification Test Answers 🐢 Reliable Certified-Data-Engineer-Professional Exam Registration 🌃 Easily obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download through ➥ www.prep4sures.top 🡄 ✏Dump Certified-Data-Engineer-Professional File
- Free Certified-Data-Engineer-Professional Download Pdf 🚖 Certified-Data-Engineer-Professional Valid Exam Format 🙍 Reliable Certified-Data-Engineer-Professional Braindumps Sheet 🐛 Go to website ✔ www.pdfvce.com ️✔️ open and search for [ Certified-Data-Engineer-Professional ] to download for free 📕Free Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Guide Torrent: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Learning Materials 🏔 Easily obtain ☀ Certified-Data-Engineer-Professional ️☀️ for free download through ➥ www.pdfdumps.com 🡄 🧔Relevant Certified-Data-Engineer-Professional Questions
- Certified-Data-Engineer-Professional - Reliable Databricks Certified Data Engineer Professional Test Guide 🖼 Easily obtain free download of ➥ Certified-Data-Engineer-Professional 🡄 by searching on ⮆ www.pdfvce.com ⮄ 🏖Free Certified-Data-Engineer-Professional Download Pdf
- Perfect Certified-Data-Engineer-Professional – 100% Free Test Guide | Certified-Data-Engineer-Professional Popular Exams 🏳 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering “ www.torrentvce.com ” website 🏪Reliable Certified-Data-Engineer-Professional Exam Registration
- Test Certified-Data-Engineer-Professional Engine 🚒 Free Certified-Data-Engineer-Professional Download Pdf 🐚 Latest Certified-Data-Engineer-Professional Exam Guide 🚴 Search for ▶ Certified-Data-Engineer-Professional ◀ and download exam materials for free through ⮆ www.pdfvce.com ⮄ 📆Latest Certified-Data-Engineer-Professional Exam Guide
- Reliable Certified-Data-Engineer-Professional Braindumps Sheet 🧧 Certified-Data-Engineer-Professional Prepaway Dumps 🍊 Reliable Certified-Data-Engineer-Professional Braindumps Ebook 🍣 The page for free download of ( Certified-Data-Engineer-Professional ) on 【 www.verifieddumps.com 】 will open immediately ☮Free Certified-Data-Engineer-Professional Exam
- 2026 Fantastic Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Test Guide ⬇ Search on ➥ www.pdfvce.com 🡄 for ▛ Certified-Data-Engineer-Professional ▟ to obtain exam materials for free download 🦜Reliable Certified-Data-Engineer-Professional Braindumps Ebook
- Reliable Certified-Data-Engineer-Professional Test Guide Covers the Entire Syllabus of Certified-Data-Engineer-Professional 📦 Search for “ Certified-Data-Engineer-Professional ” and easily obtain a free download on ➥ www.verifieddumps.com 🡄 🧤Reliable Certified-Data-Engineer-Professional Exam Registration
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.fotor.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest RealValidExam Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1eH5vYbAKB6fwJW4H252-YRsnujQu2JQE