As an authorized website, ExamcollectionPass provide you with the products that can be utilized most efficiently. We provide 24/7 customer service for all of you, please feel free to send us any questions about Microsoft exam test through email or online chat, and we will always try our best to keeping our customer satisfied. AI-500 Study Material will give you a better way to prepare for the actual test with its validity and reliability AI-500 questions & answers. Now, please choose our AI-500 dumps torrent for your 100% passing.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Design and implement evaluation and validation strategies
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
| Topic 4: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
Achieving the Microsoft AI-500 test certification can open up unlimited possibilities for your future career, if you are truly dedicated to jump out your career and willing to make additional learning and extra income. ExamcollectionPass AI-500 exam dumps can help you to overcome the difficulty—from understanding the necessary and basic knowledge to passing the Microsoft Certified: Multi-Agent AI Solutions Expert Designing and Implementing Multi-Agent AI Solutions exam test. The goal of Microsoft AI-500 is to help our customers optimize their IT technology by providing convenient, high quality Microsoft Certified: Multi-Agent AI Solutions Expert exam prep training that they can rely on. Microsoft AI-500 sure pass exam dumps empower the candidates to master their desired technologies for their own Microsoft Certified: Multi-Agent AI Solutions Expert exam test.Dear every one, passing the Microsoft AI-500 actual test is an easy case for you.
NEW QUESTION # 53
You have a Microsoft Foundry claims-assistance solution that includes a primary claims agent and three specialist agents. The primary claims agent invokes the specialist agents.
You need to recommend a coordination approach. The solution must meet the following requirements:
* The primary claims agent must retain ownership of the task and synthesize the final response.
* The specialist agents must have a least-privilege view of the claim for their assigned work.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.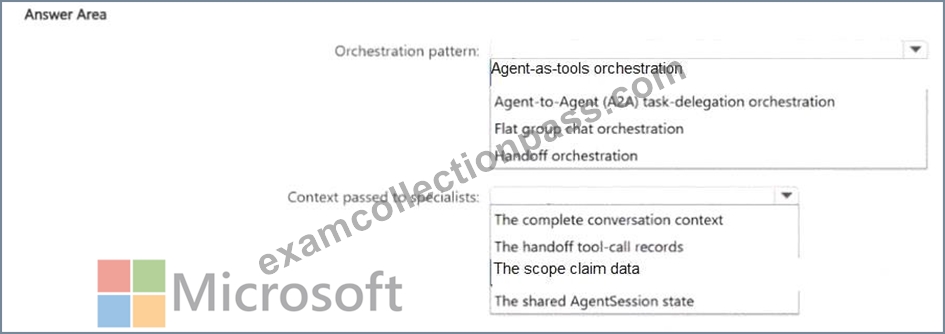
Answer:
Explanation: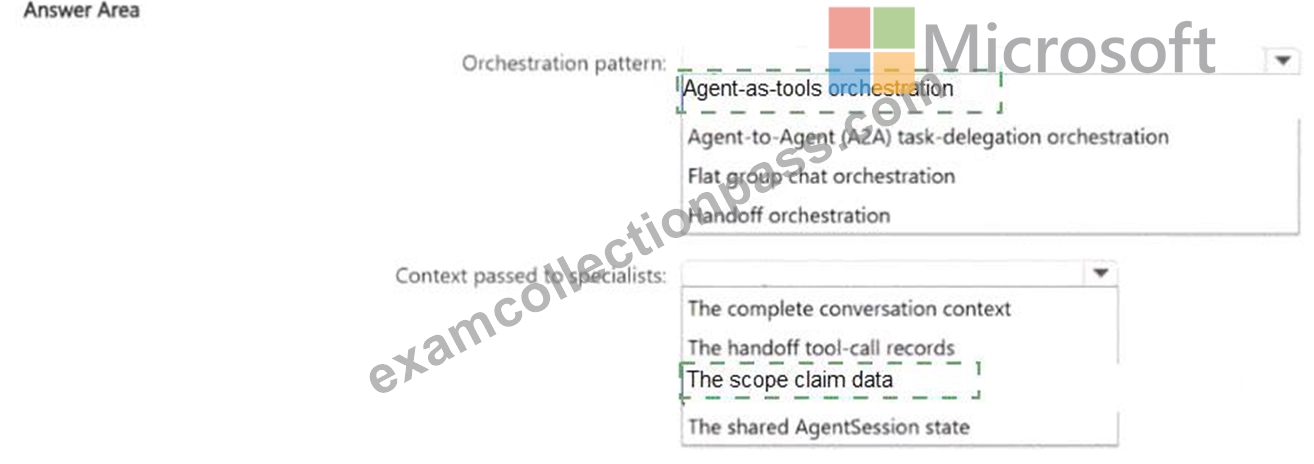
Explanation:
Orchestration pattern: Agent-as-tools; Context passed to specialists: Scoped claim data only.
The primary claims agent must retain task ownership and synthesize the final response, which is the defining property of the agents-as-tools pattern. The primary agent decides when to invoke each specialist, receives the specialist ' s result, and remains responsible for the overall conversation. Handoff orchestration would instead transfer control to another agent and therefore weaken the ownership requirement. Microsoft Agent Framework also makes it possible for the outer agent to pass only the arguments needed by the inner agent rather than sharing the entire conversation history automatically. That supports least-privilege context: each specialist receives only the claim fields required for its assigned work. Passing the whole claim or a shared transcript would unnecessarily expose data outside the specialist ' s domain. The selected combination therefore satisfies both control ownership and data minimization. The architecture should still be validated with representative end-to-end tests, but the selected component establishes the correct structural boundary first. Microsoft ' s AI-500 blueprint consistently favors explicit scopes, interfaces, and persistence or identity boundaries over prompt-only conventions.
Official Microsoft reference: Microsoft Agent Framework - Agents as tools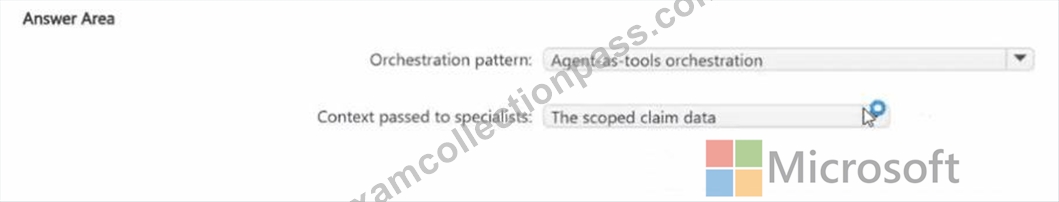
NEW QUESTION # 54
HOTSPOT -
You have a multi-agent solution in a Microsoft Foundry project. The project is connected to an Application Insights resource.
You have the following code that implements tracing.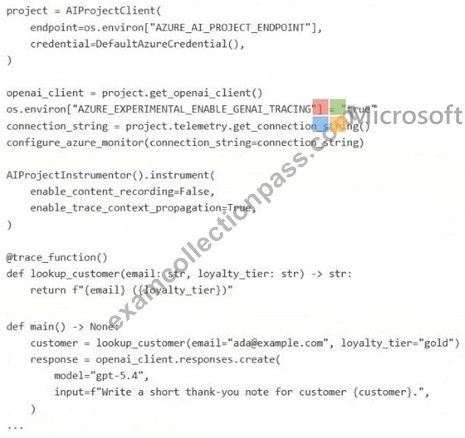
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.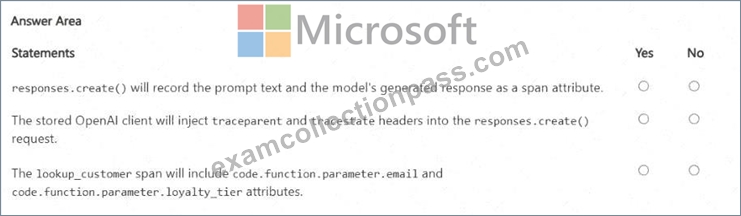
Answer:
Explanation: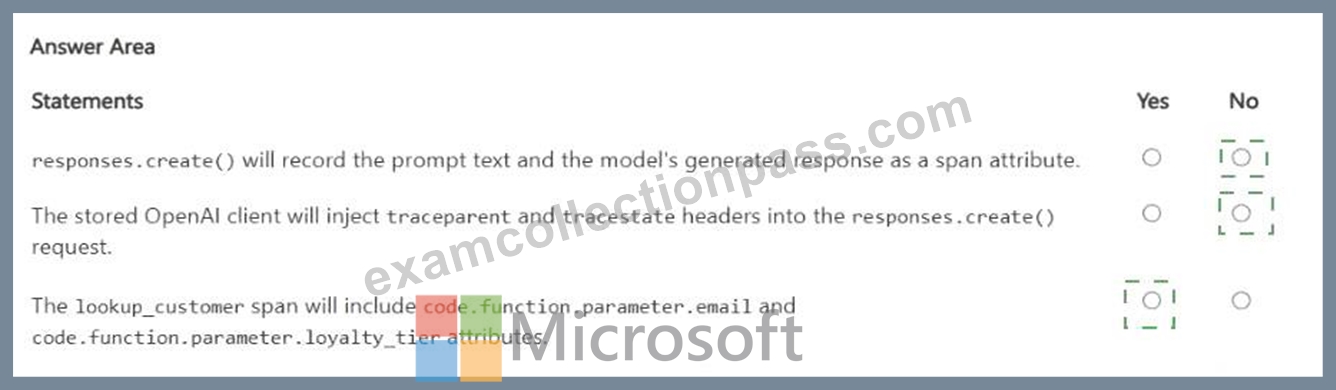
Explanation:
No / No / Yes
The first statement is false because content recording is explicitly disabled, so prompt and generated response text are not stored as GenAI span content attributes even though tracing remains active. The second is false because the OpenAI client is obtained before trace-context propagation is enabled; Microsoft documents that clients created before the instrumentation change are not retroactively configured for that propagation behavior. The third statement is true because the tracing decorator for ordinary functions records supported function parameters as `code.function.parameter. < name > ` attributes. Those parameter attributes are separate from GenAI prompt-content recording, so disabling message content does not suppress them.
Consequently `email` and `loyalty_tier` can appear on the `lookup_customer` span. The correct sequence is No, No, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - client-side agent tracing
NEW QUESTION # 55
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.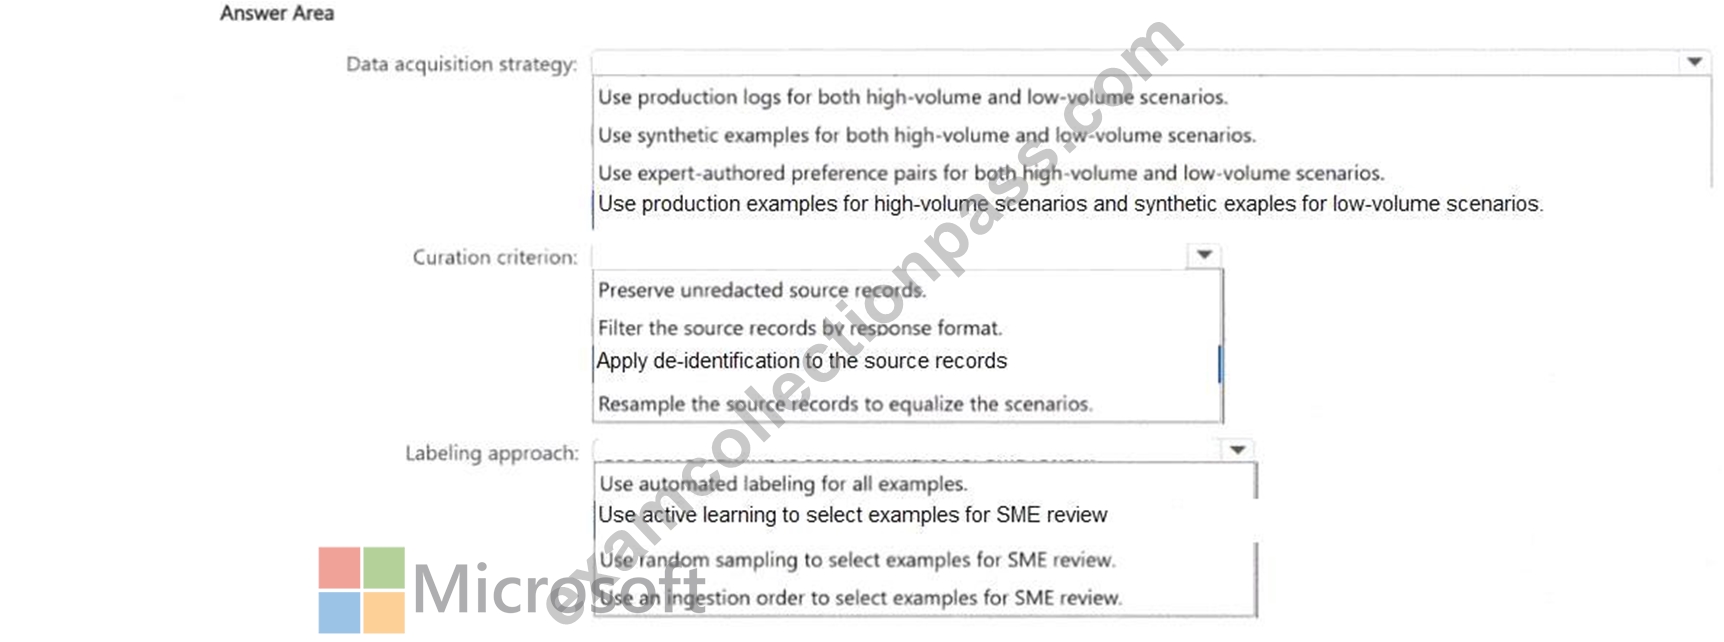
Answer:
Explanation: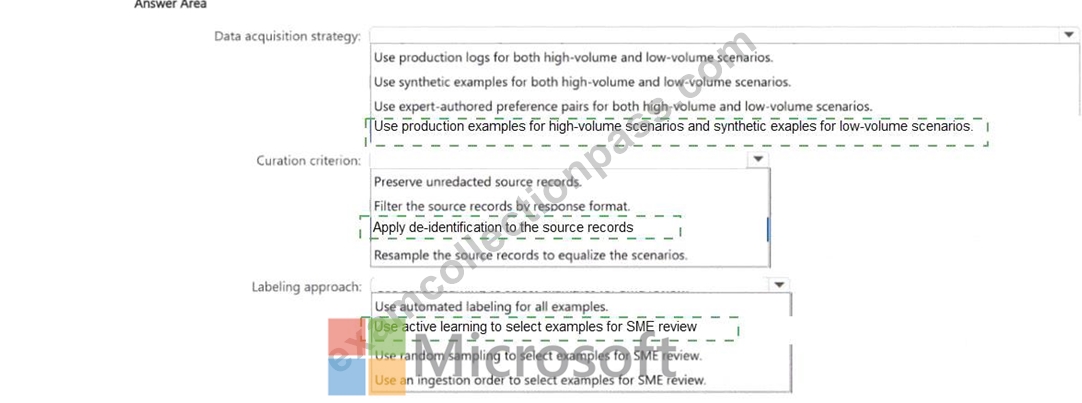
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation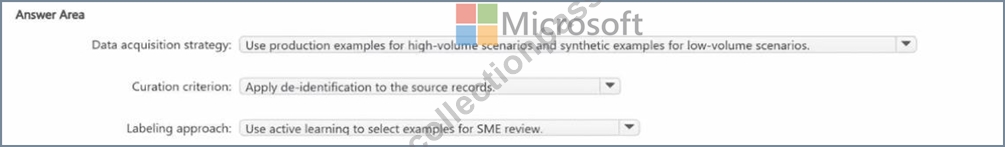
NEW QUESTION # 56
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.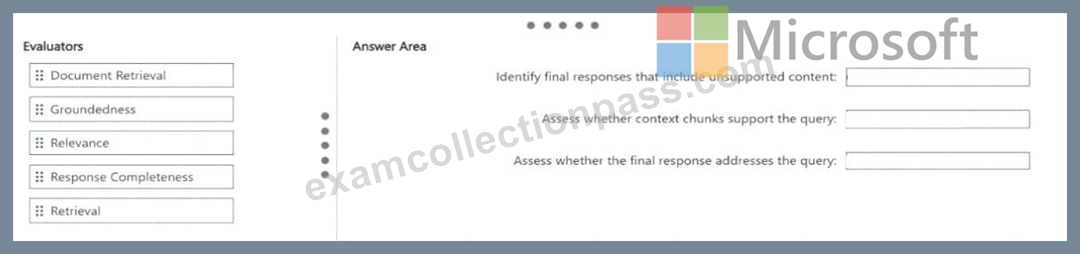
Answer:
Explanation: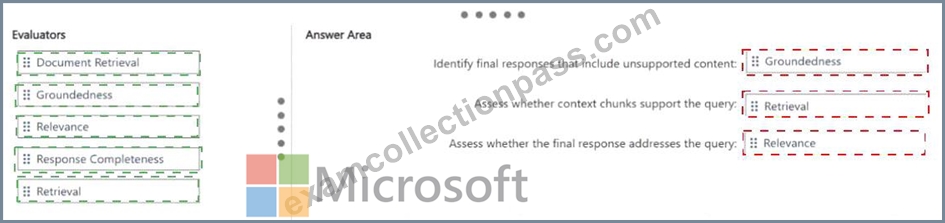
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators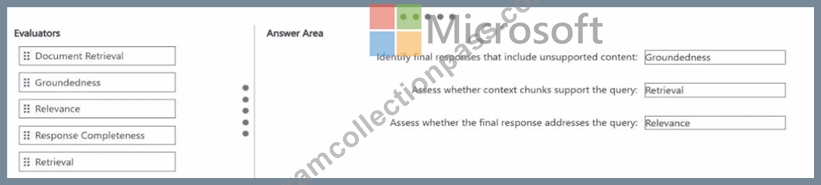
NEW QUESTION # 57
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
Answer: D
Explanation:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
NEW QUESTION # 58
......
Do you want to pass AI-500 exam certification at your first attempt to attend AI-500 test? With ExamcollectionPass, we will meet all of your needs, and make you pass AI-500 certification exam at one time in a limited time. Because ExamcollectionPass have AI-500 Exam Certification training materials, which are summarized by experienced IT experts with many years' practice, and is a combination of AI-500 exam dumps and answers, you can't regret to choose ExamcollectionPass.
Exams AI-500 Torrent: https://www.examcollectionpass.com/Microsoft/AI-500-practice-exam-dumps.html