We are never satisfied with the present situation and expand and update the CCAR-P exam practice guide by all means. We focus on the innovation and organize our expert team to compile new knowledge points and update the test bank. We treat our clients as our god and treat their supports to our CCAR-P Study Materials as our driving forces to march forward. So the clients can enjoy the results of the latest innovation on CCAR-P exam questions and achieve more learning resources. The credits belong to our diligent and dedicated professional innovation team and our experts.
| Section | Weight | Objectives |
|---|---|---|
| Developer Productivity & Operational Enablement | 7% | - Configure Claude tools and environments for teams - Support debugging, monitoring, and operational resolution - Improve developer workflows with AI-assisted tooling |
| Governance, Safety & Risk Management | 14% | - Address ethical AI considerations and bias mitigation - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Implement guardrails and safety controls - Manage data privacy and security compliance |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs - Mitigate prompt injection, leaks, and jailbreak risks |
| Solution Design & Architecture | 17% | - Design end-to-end architectures and feedback loops - Translate business problems into Claude-based AI solutions - Align solutions to business value pillars - Design multi-agent systems and orchestration strategies - Select architectural patterns: workflow, agentic, augmented LLM |
| Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment - Conduct structured discovery and requirement gathering |
| Evaluation, Testing & Optimization | 16% | - Define evaluation metrics and success criteria - Implement iterative improvement pipelines - Optimize performance, prompting, and model selection - Test accuracy, reliability, latency, and cost |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations |
>> Valid CCAR-P Exam Testking <<
When you are studying for the CCAR-P exam, maybe you are busy to go to work, for your family and so on. Time is precious for everyone to do the efficient job. If you want to get good CCAR-P prep guide, it must be spending less time to pass it. We are choosing the key point and the latest information to finish our CCAR-P Guide Torrent. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the CCAR-P exam torrent. Then, you will have enough confidence to pass the CCAR-P exam.
NEW QUESTION # 55
A Claude-based research assistant begins producing responses that confidently contradict its retrieved source documents despite no change to the retrieval pipeline.
Which two diagnostic actions most directly identify the root cause of this behavior? (Select two.)
Answer: C,D
Explanation:
The retrieval pipeline is stated to be unchanged, so the first investigation should isolate changes in generation behavior and grounding instructions. Replaying the failing cases on the previous model version determines whether the regression follows the model upgrade or current model-prompt combination. Inspecting the system prompt establishes whether source-use rules, uncertainty behavior, citation requirements, or prohibitions against unsupported claims were removed or weakened. Increasing context or replacing the embedding model changes a component for which no failure evidence exists and may introduce additional noise. Lowering temperature may reduce variation but does not explain systematic contradiction of retrieved evidence. The investigation should compare identical requests, retrieved passages, prompts, and model versions before applying a fix. Define success criteria and evaluations
NEW QUESTION # 56
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.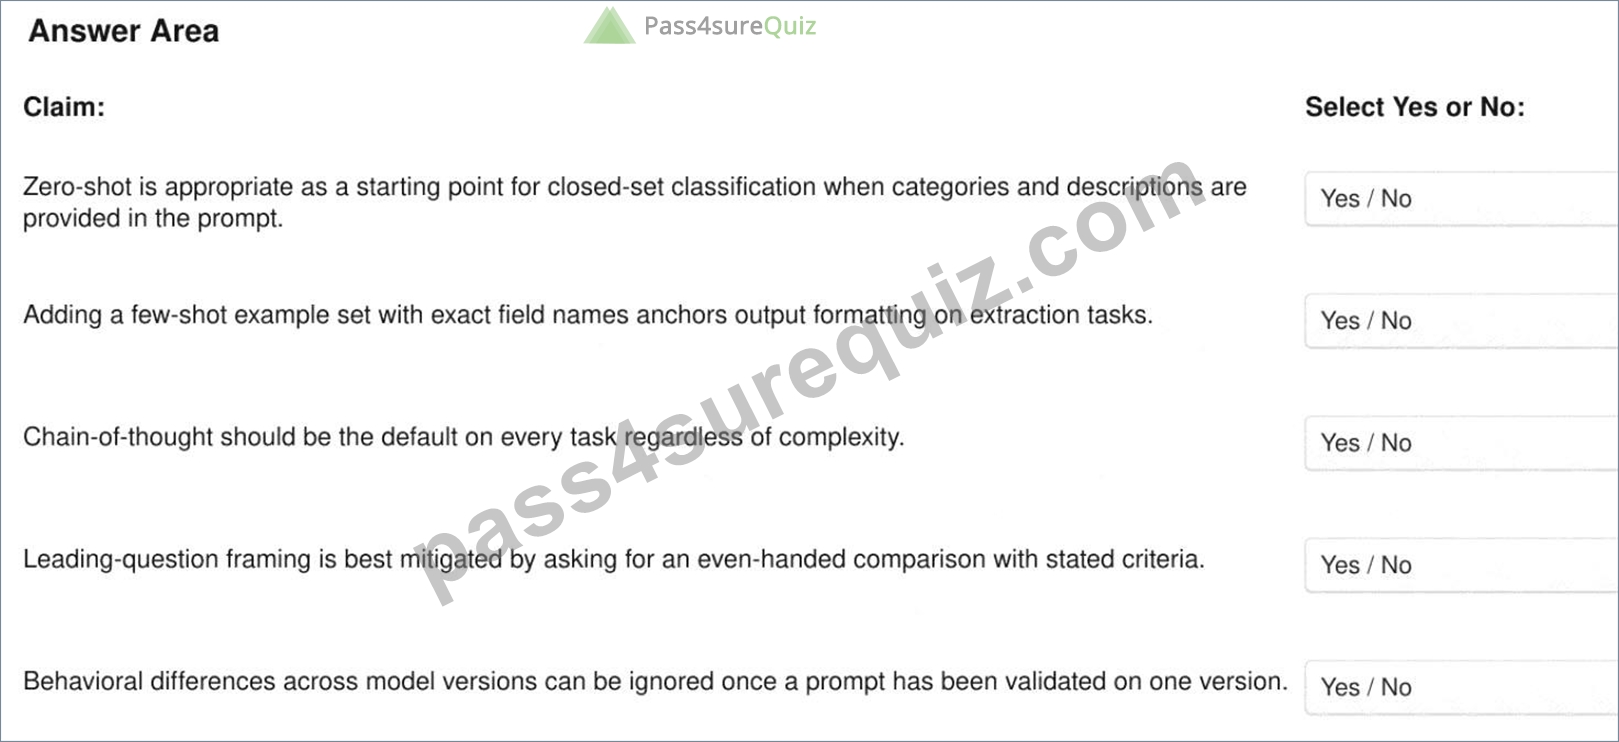
Answer:
Explanation: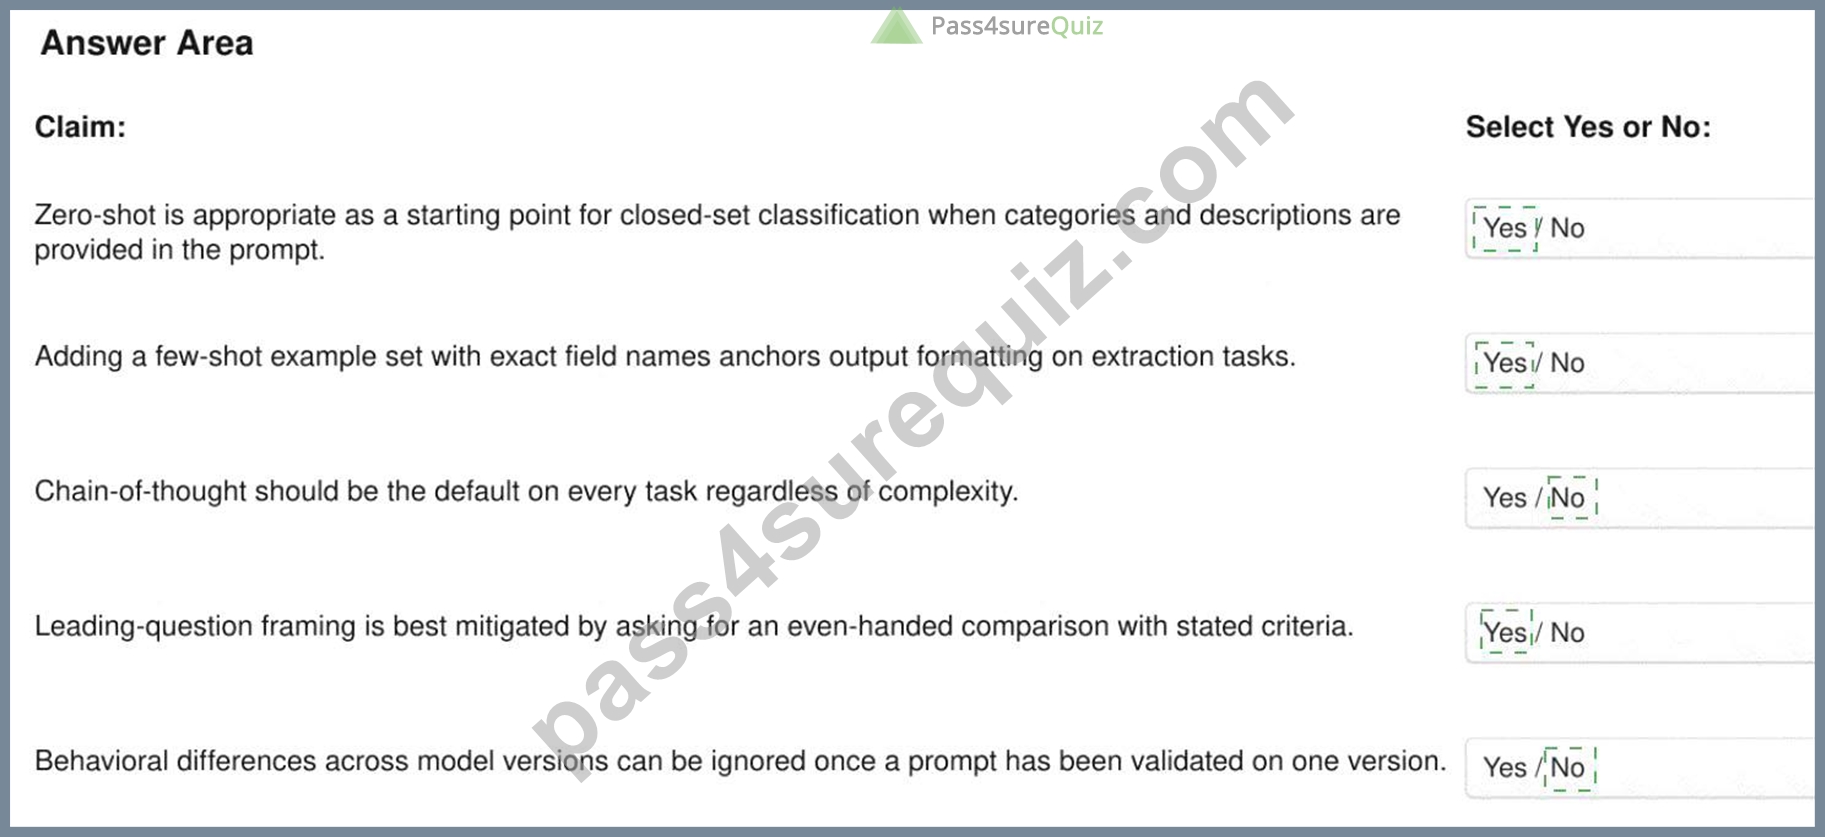
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 57
A Claude architect needs to ensure that a security-hardening flag cannot be disabled by any individual engineer after it is set.
Which configuration scope correctly enforces this requirement?
Answer: A
Explanation:
Managed configuration is designed for organization-wide security and compliance controls that individual users and repositories must not override. Applying the hardening flag centrally establishes an administrative policy boundary and prevents engineers from disabling the control through user, project, or local settings.
Anthropic identifies managed scope as the appropriate location for security policies, non-overridable compliance requirements, and standardized configurations deployed by IT or DevOps. Managed values ordinarily take precedence over command-line arguments and every user-controlled settings scope. Claude Code Settings Option A depends on every engineer maintaining the setting and allows the user to edit or delete it. Option B affects only pipeline execution and does not protect local, interactive, IDE, or other execution paths. Option D standardizes the setting within the repository but does not make it tamper-resistant; contributors with repository write access could alter the file, use higher-precedence local settings where permitted, or operate outside the repository configuration.
The implementation should also verify active policy delivery, monitor configuration-change events, and test that startup or execution fails safely if the managed setting is absent or invalid. Central definition without enforcement and verification would not fully satisfy the requirement.
Study Guide references/topics: Managed settings; non-overridable controls; enterprise hardening; policy enforcement; configuration governance; defense against local override.
NEW QUESTION # 58
Engineering leadership wants to roll out Claude Skills to 280 developers across 14 teams. Skills will encode internal coding standards, code-review checklists, and incident-postmortem templates. Leadership has asked how to govern Skill authorship so that Skills remain trustworthy without bottlenecking on a single central team.
Which governance model should you recommend?
Answer: B
Explanation:
Federated authorship allows each domain team to maintain the procedural knowledge it understands while preserving organization-wide trust through a central publication gate. Team authors can update coding standards, review practices, and postmortem procedures without waiting for a single platform group to write every change. Central reviewers can validate ownership, security, tool permissions, duplication, versioning, testing evidence, and compliance before publication. Per-developer or fully decentralized publication creates inconsistent and potentially unsafe Skills. Fully centralized authorship becomes a scalability bottleneck and separates content maintenance from domain expertise. Anthropic describes Skills as packages of instructions, scripts, and resources and warns that repository Skills may grant broad tool access, making formal review essential. Claude Code Skills
NEW QUESTION # 59
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.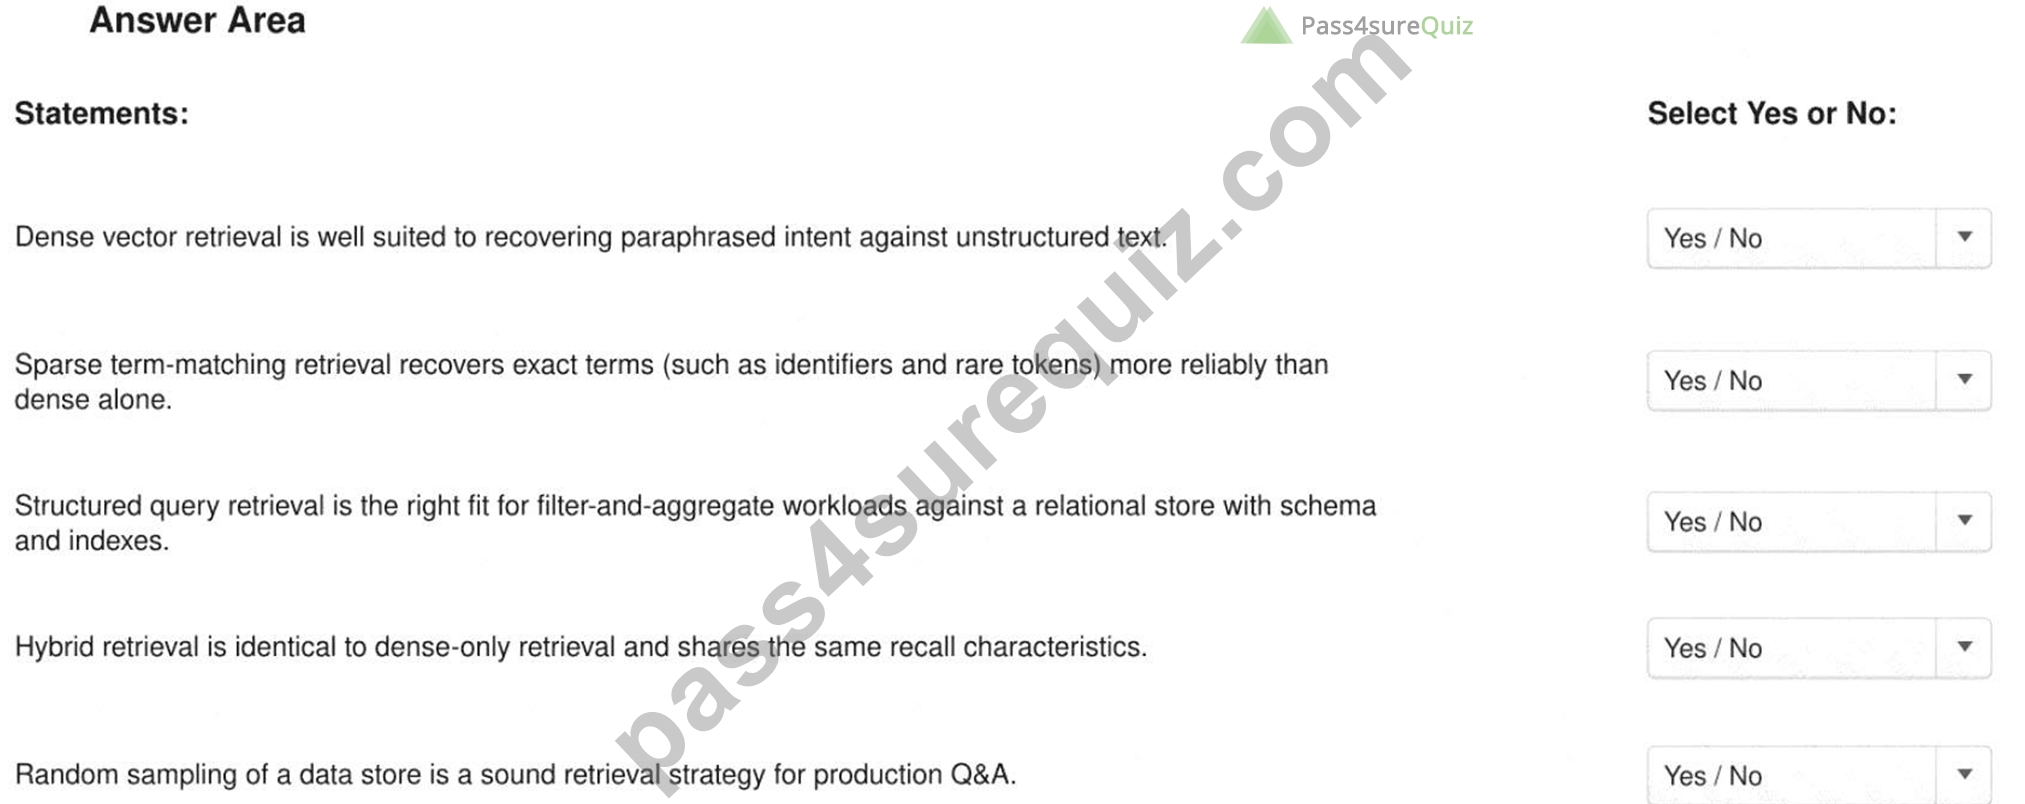
Answer:
Explanation: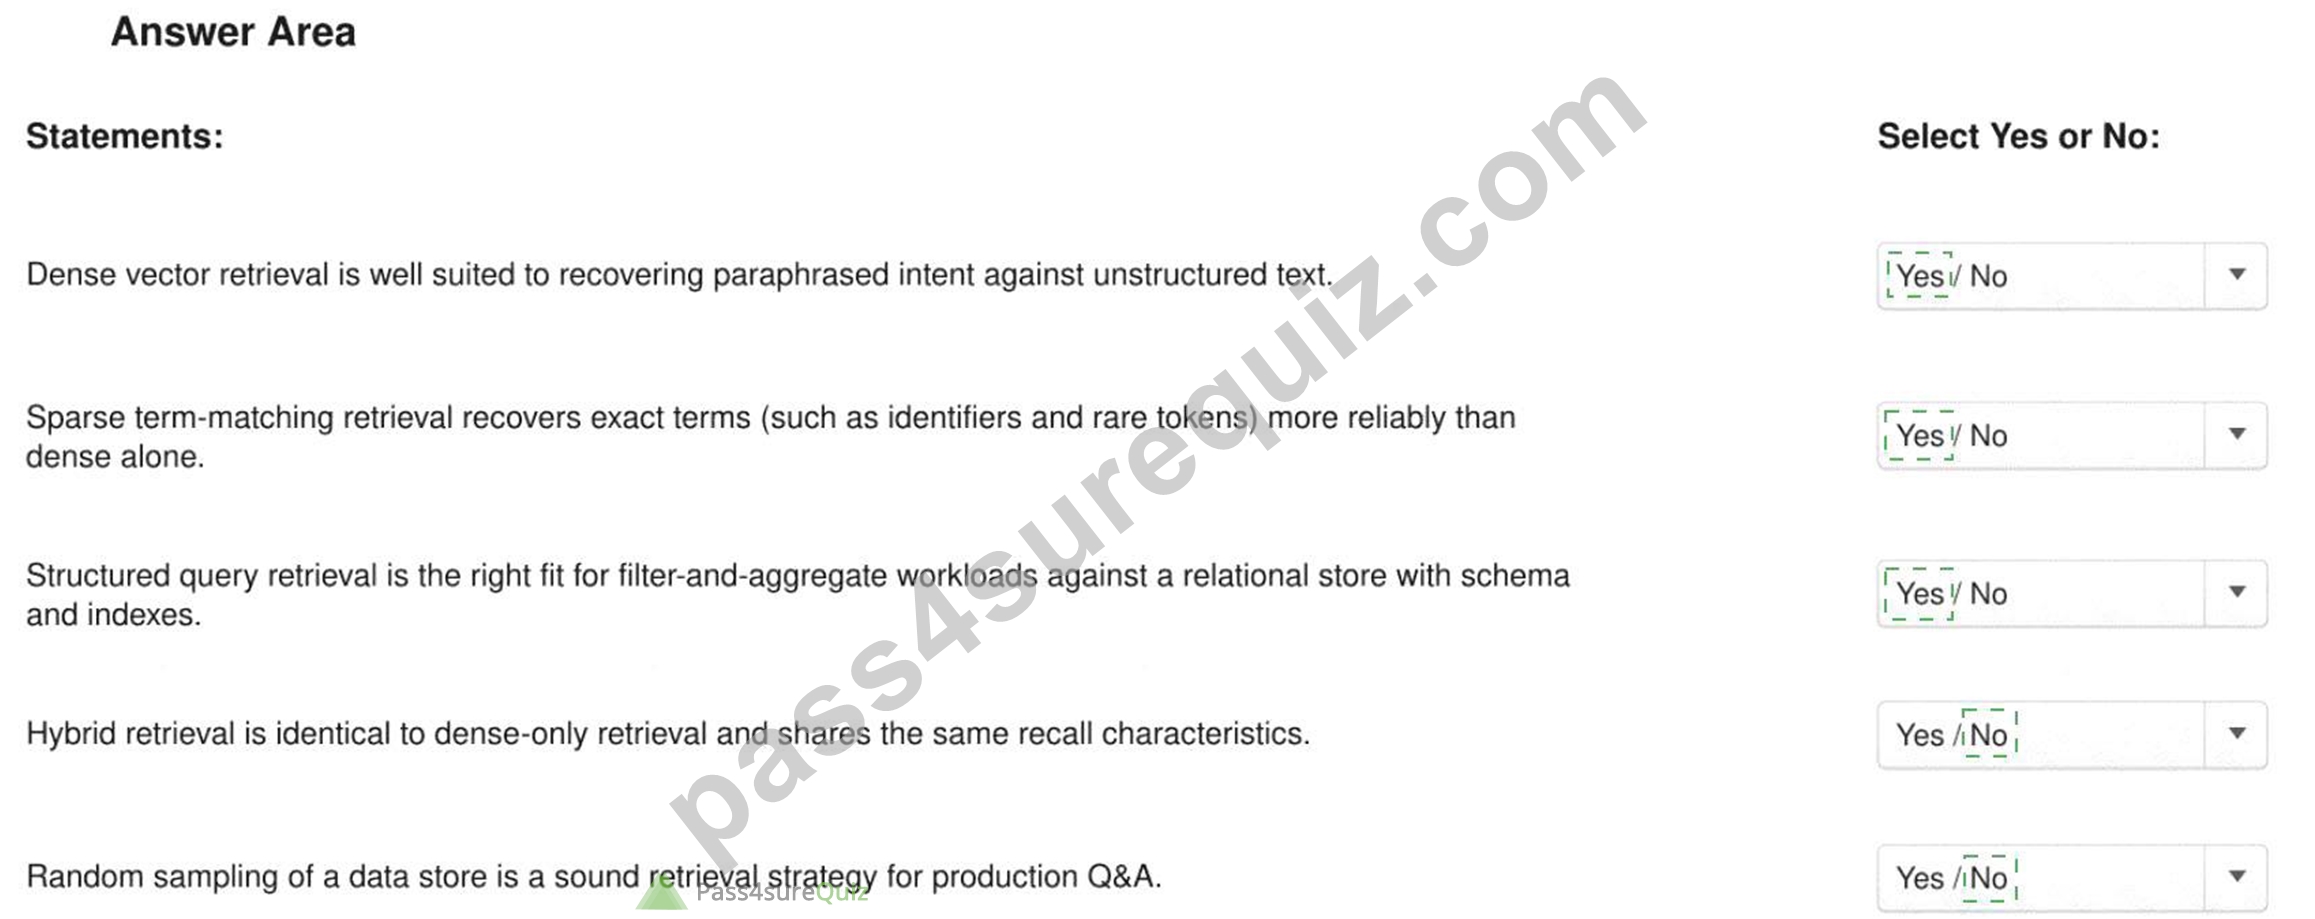
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 60
......
We guarantee you that our top-rated Anthropic CCAR-P practice exam will enable you to pass the Anthropic CCAR-P certification exam on the very first go. The authority of Claude Certified Architect - Professional CCAR-P Exam Questions rests on its being high-quality and prepared according to the latest pattern.
Study CCAR-P Reference: https://www.pass4surequiz.com/CCAR-P-exam-quiz.html