P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by VCETorrent: https://drive.google.com/open?id=1UYmI_rMF6T4cbGYZfPaqIu-rRHiIHYkc
One of the most effective strategies to prepare for the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam successfully is to prepare with actual Databricks Databricks-Certified-Data-Engineer-Associate exam questions. It would be difficult for the candidates to pass the Databricks exam on the first try if the Databricks-Certified-Data-Engineer-Associate study materials they use are not updated. Studying with invalid Databricks-Certified-Data-Engineer-Associate practice material results in a waste of time and money. Therefore, updated Databricks Databricks-Certified-Data-Engineer-Associate practice questions are essential for the preparation of the Databricks-Certified-Data-Engineer-Associate exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Pipeline Architecture | 15-20% | - Understand ELT vs ETL patterns - Monitor and optimize pipeline performance - Implement incremental data processing - Design data pipelines for batch and streaming |
| Python for Data Engineering | 10-15% | - Implement user-defined functions (UDFs) - Work with Spark APIs in Python - Use PySpark for data processing |
| Lakehouse Platform Concepts | 10-15% | - Describe key Databricks Lakehouse platform components - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts |
| Spark SQL and DataFrames | 15-20% | - Write and execute Spark SQL queries - Handle null values and data quality - Join and union DataFrames - Aggregate and group data |
| Apache Spark Data Processing Fundamentals | 20-25% | - Apply transformations and actions on DataFrames - Work with structured data types (arrays, maps, structs) - Use Spark SQL for data processing - Create and use Spark DataFrames |
| Delta Lake Fundamentals | 20-25% | - Explain Delta Lake features and benefits - Understand ACID transactions and time travel - Create and manage Delta tables - Write to and read from Delta tables |
>> Exam Databricks-Certified-Data-Engineer-Associate Tips <<
Maybe you are a hard-work person who has spent much time on preparing for Databricks-Certified-Data-Engineer-Associate exam test. While the examination fee is very expensive, you must want to pass at your first try. So, standing at your perspective, our Databricks-Certified-Data-Engineer-Associate practice torrent will help you pass your Databricks exam with less time and money investment. Our Databricks-Certified-Data-Engineer-Associate Valid Exam Dumps simulate the actual test and are compiled by the professional experts who have worked in IT industry for decades. The authority and reliability are without doubt. Besides, the price is affordable, it is really worthy being chosen.
NEW QUESTION # 258
A data engineer needs to determine whether to use the built-in Databricks Notebooks versioning or version their project using Databricks Repos.
Which of the following is an advantage of using Databricks Repos over the Databricks Notebooks versioning?
Answer: E
Explanation:
Databricks Repos is a visual Git client and API in Databricks that supports common Git operations such as cloning, committing, pushing, pulling, and branch management. Databricks Notebooks versioning is a legacy feature that allows users to link notebooks to GitHub repositories and perform basic Git operations. However, Databricks Notebooks versioning does not support the use of multiple branches for development work, which is an advantage of using Databricks Repos. With Databricks Repos, users can create and manage branches for different features, experiments, or bug fixes, and merge, rebase, or resolve conflicts between them. Databricks recommends using a separate branch for each notebook and following data science and engineering code development best practices using Git for version control, collaboration, and CI/CD. References: Git integration with Databricks Repos - Azure Databricks | Microsoft Learn, Git version control for notebooks (legacy) | Databricks on AWS, Databricks Repos Is Now Generally Available - New 'Files' Feature in
..., Databricks Repos - What it is and how we can use it | Adatis.
NEW QUESTION # 259
A data engineer has developed a Python notebook in a Databricks workspace and has configured it to run as a scheduled Job to process daily sales data. How are the storage and execution of this notebook managed within the Databricks architecture?
Answer: C
Explanation:
Databricks workspace notebooks and their metadata are securely stored and encrypted in the control plane. When the scheduled job runs, the notebook code is executed on Databricks compute in the compute plane, where data processing occurs.
NEW QUESTION # 260
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below: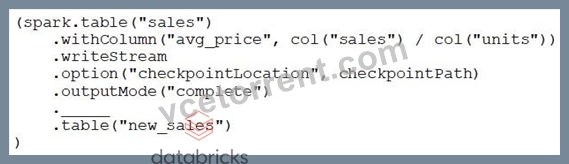
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
Answer: B
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). Reference: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 261
A data engineer needs to create a table in Databricks using data from a CSV file at location /path/to/csv.
They run the following command: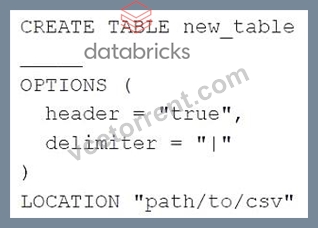
Which of the following lines of code fills in the above blank to successfully complete the task?
Answer: A
Explanation:
A data lakehouse is a new paradigm that can be used to simplify and unify siloed data architectures that are specialized for specific use cases. A data lakehouse combines the best of both data lakes and data warehouses, providing a single platform that supports diverse data types, open standards, low-cost storage, high-performance queries, ACID transactions, schema enforcement, and governance. A data lakehouse enables data engineers to build reliable and scalable data pipelines that can serve various downstream applications and users, such as data science, machine learning, analytics, and reporting. A data lakehouse leverages the power of Delta Lake, a storage layer that brings reliability and performance to data lakes. Reference: What is a data lakehouse?, Delta Lake, Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics
NEW QUESTION # 262
A data engineer needs to parse only png files in a directory that contains files with different suffixes. Which code should the data engineer use to achieve this task?
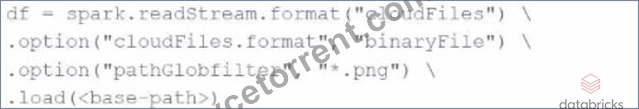



Answer: C
NEW QUESTION # 263
......
Most of the candidates remain confused about the format of the actual Databricks-Certified-Data-Engineer-Associate exam and the nature of questions therein. So our Databricks-Certified-Data-Engineer-Associate exam questions can perfectly provide them with the newest information about the exam not only on the content but also on the format. And to help them adjust to the real exam, we also developed the Software verson of the Databricks-Certified-Data-Engineer-Associate learning prep which can simulate the real exam.
Databricks-Certified-Data-Engineer-Associate Free Download Pdf: https://www.vcetorrent.com/Databricks-Certified-Data-Engineer-Associate-valid-vce-torrent.html
What's more, part of that VCETorrent Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1UYmI_rMF6T4cbGYZfPaqIu-rRHiIHYkc