P.S. Free & New DP-800 dumps are available on Google Drive shared by Exam4Tests: https://drive.google.com/open?id=1LPU2Qqw8UNt90j1U-XtSpiSc9Wz0g88D
If you are also facing the same problem then you are at the trusted spot. Exam4Tests offers updated and real Microsoft DP-800 Exam Dumps for Developing AI-Enabled Database Solutions (DP-800) test takers who want to prepare quickly for the Developing AI-Enabled Database Solutions (DP-800) examination. These actual DP-800 exam questions have been compiled by a team of professionals after a thorough analysis of past papers and current content of the DP-800 test. If students prepare with these valid Developing AI-Enabled Database Solutions (DP-800) questions, they will surely become capable of clearing the Developing AI-Enabled Database Solutions (DP-800) examination within a few days.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, optimize, and deploy database solutions | 35-40% | - Secure database solutions
|
| Topic 2: Implement AI capabilities in database solutions | 25-30% | - Use AI-assisted development tools
|
| Topic 3: Design and develop database solutions | 35-40% | - Develop database solutions
|
We strongly recommend using our DP-800 exam dumps to prepare for the Developing AI-Enabled Database Solutions. It is the best way to ensure success. With our DP-800 practice questions, you can get the most out of your studying and maximize your chances of passing your DP-800 Exam. Exam4Tests Developing AI-Enabled Database Solutions is the answer if you want to score higher in the DP-800 exam and achieve your academic goals.
NEW QUESTION # 44
Drag and Drop Question
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 45
You need to create a table in the database to store the telemetry data. You have the following Transact-SQL code.

Answer:
Explanation:
Explanation:
The first statement is No . The requirement says telemetry data must be stored in a partitioned table to provide predictable performance for ingestion and retention operations. However, the shown CREATE TABLE statement does not define a partition function or partition scheme, and the table is created with a regular clustered primary key on TelemetryId. Microsoft's partitioning guidance states that creating a partitioned table requires a partition function , a partition scheme , and creating the table or index on that partition scheme using a partitioning column. None of that appears in the code, so the table is not partitioned.
The second statement is Yes . The code creates a JSON index named JI_VehicleTelemetry_Location on LocationJson for these specific JSON paths: $.location.latitude, $.location.longitude, and $.location.accuracy.
That matches the requirement that those JSON properties must be filterable by using an index seek .
Microsoft documents that JSON indexing is used to optimize filtering and sorting on JSON properties, and the index only helps for the properties included in the index definition.
The third statement is No . The JSON index is defined only for latitude, longitude, and accuracy. A query filtering on $.location.heading references a different path that is not included in the index definition, so that query would not use JI_VehicleTelemetry_Location for that predicate. JSON indexes are path-specific; they do not automatically cover unrelated properties in the same JSON document.
NEW QUESTION # 46
You have an Azure SQL database that contains the following SQL graph tables:
- A NODE table named dbo.Person
- An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
- PersonID (int)
- DisplayName (nvarchar(100))
You need to use a MATCH operator and exactly two directed Knows relationships to return the PersonID and DisplayName of people that are reachable from the person identified by an input parameter named @StartPersonId.
Which Transact-SQL query should you use?


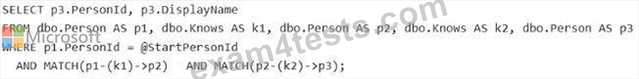
Answer: C
Explanation:
To achieve this using SQL Graph in Azure SQL, you use the MATCH clause to define the path.
Since you need exactly two directed relationships (A → B → C), you must chain the edge table twice in the same direction.
Transact-SQL Statement
SELECT
Person3.ID,
Person3.NameColumn -- Replace with your actual nvarchar(100) column name FROM PersonNodeTable AS Person1, KnowsEdgeTable AS Knows1, PersonNodeTable AS Person2, KnowsEdgeTable AS Knows2, PersonNodeTable AS Person3 WHERE MATCH(Person1-(Knows1)->Person2-(Knows2)->Person3) AND Person1.ID = @InputID; Use code with caution.
Key Components
MATCH Clause: Defines the traversal pattern. The syntax (Node)-(Edge)->(Node) ensures the relationship is directed.
Chaining: To get "exactly two" steps, you define three node aliases and two edge aliases.
Aliases: Each instance of the table must have a unique alias (e.g., Person1, Person2, Person3) so the engine can distinguish between the different points in the path.
Filtering: The WHERE clause uses your input parameter (@InputID) to set the starting point of the graph traversal Incorrect:
[Not A]
Need three persons, not two.
[Not B]
Do not use JOIN.
[Not C]
Incorrect MATCH statement.
Reference:
https://learn.microsoft.com/en-us/sql/relational-databases/graphs/sql-graph-sample
NEW QUESTION # 47
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.
Answer:
Explanation:
Explanation:
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
NEW QUESTION # 48
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Drag and Drop Question
You need to meet the database performance requirements for maintenance data.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 49
......
Our DP-800 desktop practice test software works after installation on Windows computers. The Developing AI-Enabled Database Solutions DP-800 web-based practice exam has all the features of the desktop software, but it requires an active internet connection. If you are busy in your daily routine and cant manage a proper time to sit and prepare for the DP-800 Certification test, our DP-800 PDF questions file is ideal for you. You can open and use the DP-800 Questions from any location at any time on your smartphones, tablets, and laptops. Questions in the Developing AI-Enabled Database Solutions DP-800 PDF document are updated, and real.
Reliable DP-800 Test Notes: https://www.exam4tests.com/DP-800-valid-braindumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Exam4Tests: https://drive.google.com/open?id=1LPU2Qqw8UNt90j1U-XtSpiSc9Wz0g88D