What's more, part of that TestkingPass Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1pcYuQVvd9fO_MG1nzx51TZSR0N01jpSs
We are one of the largest and the most confessional dealer of Databricks-Generative-AI-Engineer-Associate practice materials for we have been professional in this career for over ten years. And we have enough strenght on this filed. That is why our Databricks-Generative-AI-Engineer-Associate actual exam outreaches others greatly among substantial suppliers of the exam. Getting place great orders with competitive prices and unquestionable quality for your information, the excellency of our Databricks-Generative-AI-Engineer-Associate Exam Questions is obvious. Just come and buy them!
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Real Exam Qty: | 45 |
| Available Languages: | English, Portuguese (Brazil), Japanese, Korean |
| Passing Score: | Scaled Score (approx. 70%) |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Format: | Multiple Select, Multiple Choice |
| Exam Price: | $200 USD |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Questions <<
Do you upset about the difficulty of Databricks practice questions? Do you disappointed at losing exam after long-time preparation? We can help you from these troubles with our Latest Databricks-Generative-AI-Engineer-Associate Learning Materials and test answers. You will find valid Databricks-Generative-AI-Engineer-Associate real questions and detailed explanations in TestkingPass, which ensure you clear exam easily.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 47
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
Answer: D
Explanation:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is tocreate an agentthat has access to specific tools (option D).
* Agent with SQL and Web Search Capabilities:By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
* Why This Approach Works:
* SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
* Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
* Why Other Options Are Less Suitable:
* A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
* B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
* C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
NEW QUESTION # 48
A Generative AI Engineer is building a multi-turn chat app with LangGraph on Databricks. The app must persist chat history-messages, roles, timestamps, and session IDs-for many concurrent users, support SQL queries, and stay governed in Unity Catalog. The engineer also wants ACID guarantees, low-latency reads and writes, and an easy way to sync chat data into Delta tables for analytics and model training.
Which approach fits these requirements?
Answer: C
Explanation:
Lakebase provides a Postgres database suited to transactional application state, including concurrent chat- history reads and writes. A Postgres-backed LangGraph checkpoint or memory component can persist conversation state across requests and application restarts. SQL support and transactional guarantees address the application's operational requirements. Databricks also documents registering Lakebase databases in Unity Catalog and feeding Lakebase changes into Delta tables for downstream analytics. These integrations require appropriate configuration and permissions; they are not automatic simply because a table exists.
MLflow runs are intended for experiment and application tracking rather than serving as a low-latency conversation database. Per-turn Spark writes introduce unnecessary processing overhead, while driver- memory storage with periodic snapshots risks losing recent conversation state. Databricks documentation
NEW QUESTION # 49
A Generative AI Engineer at an automotive company would like to build a question-answering chatbot to help customers answer specific questions about their vehicles. They have:
A catalog with hundreds of thousands of cars manufactured since the 1960s Historical searches with user queries and successful matches Descriptions of their own cars in multiple languages They have already selected an open-source LLM and created a test set of user queries. They need to discard techniques that will not help them build the chatbot. Which do they discard?
Answer: A
Explanation:
According to Generative AI engineering standards for Retrieval-Augmented Generation (RAG), chunking strategy is a critical optimization variable. Setting the chunk size to match the model's maximum context window (e.g., 4k or 8k tokens) is a poor practice and should be discarded. Large chunks introduce significant "noise" into the LLM's context, as only a small portion of a massive chunk usually contains the answer to a specific query. This leads to the "lost in the middle" phenomenon where LLMs struggle to extract relevant information from bloated contexts. Furthermore, large chunks reduce the precision of the vector search. Standard best practices involve using smaller, semantically meaningful chunks (typically 256-512 tokens) with overlap to maintain context. In contrast, metadata filtering (B) is essential for narrowing searches to specific car years, fine-tuning embeddings (C) improves retrieval accuracy for domain-specific technical terms, and few-shot examples (D) guide the LLM's output format and tone.
NEW QUESTION # 50
A Generative Al Engineer is building a RAG application that answers questions about internal documents for the company SnoPen AI.
The source documents may contain a significant amount of irrelevant content, such as advertisements, sports news, or entertainment news, or content about other companies.
Which approach is advisable when building a RAG application to achieve this goal of filtering irrelevant information?
Answer: C
Explanation:
In a Retrieval-Augmented Generation (RAG) application built to answer questions about internal documents, especially when the dataset contains irrelevant content, it's crucial to guide the system to focus on the right information. The best way to achieve this is by including a clear instruction in the system prompt (option C).
System Prompt as Guidance:
The system prompt is an effective way to instruct the LLM to limit its focus to SnoPen AI-related content. By clearly specifying that the model should avoid answering questions unrelated to SnoPen AI, you add an additional layer of control that helps the model stay on-topic, even if irrelevant content is present in the dataset.
Why This Approach Works:
The prompt acts as a guiding principle for the model, narrowing its focus to specific domains. This prevents the model from generating answers based on irrelevant content, such as advertisements or news unrelated to SnoPen AI.
Why Other Options Are Less Suitable:
A (Keep All Articles): Retaining all content, including irrelevant materials, without any filtering makes the system prone to generating answers based on unwanted data.
B (Include in the System Prompt about SnoPen AI): This option doesn't address irrelevant content directly, and without filtering, the model might still retrieve and use irrelevant data.
D (Consolidating Documents into a Single Chunk): Grouping documents into a single chunk makes the retrieval process less efficient and won't help filter out irrelevant content effectively.
Therefore, instructing the system in the prompt not to answer questions unrelated to SnoPen AI (option C) is the best approach to ensure the system filters out irrelevant information.
NEW QUESTION # 51
A company has a typical RAG-enabled, customer-facing chatbot on its website.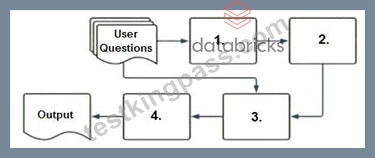
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: B
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 52
......
Databricks-Generative-AI-Engineer-Associate Training Online: https://www.testkingpass.com/Databricks-Generative-AI-Engineer-Associate-testking-dumps.html
2026 Latest TestkingPass Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1pcYuQVvd9fO_MG1nzx51TZSR0N01jpSs