P.S. Free & New SPS-C01 dumps are available on Google Drive shared by DumpsMaterials: https://drive.google.com/open?id=1F7_oCpaTU18s-FbPtXYaEIM8UC2ZcCjR
Snowflake SPS-C01 questions are available in PDF format. Our Snowflake SPS-C01 PDF is embedded with questions relevant to the actual exam content only. Snowflake SPS-C01 PDF is printable and portable, so you can learn with ease and share it on multiple devices. You can use this Snowflake SPS-C01 PDF on your mobile and tablet anywhere, anytime, without the internet and installation process.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API for Python | 30% | - Working with Semi-structured data - Reading and writing data - DataFrame creation and manipulation - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Window functions - Using built-in functions - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines - Persisting transformed data |
| Topic 3: Snowpark Concepts | 15% | - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Stored procedures and conditional logic |
| Topic 4: Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Minimizing data transfer - Warehouse sizing for Snowpark - Debugging and explain plans - Query pushdown and optimization - Caching strategies |
>> SPS-C01 Reliable Study Questions <<
Through continuous development and growth of the IT industry in the past few years, SPS-C01 exam has become a milestone in the Snowflake exam, it can help you to become a IT professional. There are hundreds of online resources to provide the Snowflake SPS-C01 questions. Why do most people to choose DumpsMaterials? Because DumpsMaterials has a huge IT elite team, In order to ensure you accessibility through the Snowflake SPS-C01 Certification Exam, they focus on the study of Snowflake SPS-C01 exam. DumpsMaterials ensure that the first time you try to obtain certification of Snowflake SPS-C01 exam. DumpsMaterials will stand with you, with you through thick and thin.
NEW QUESTION # 129
You are tasked with optimizing a Snowpark Python application that performs complex geospatial calculations on a large dataset. The application experiences significant performance bottlenecks due to the computational intensity of the geospatial functions. Which of the following strategies would be MOST effective in improving performance?
Answer: E
Explanation:
Vectorized UDFs written in Java or Scala offer significant performance gains compared to Python UDFs due to their lower overhead and ability to leverage JVM optimizations. Increasing the warehouse size (A) might help, but it's not the most targeted solution for computationally intensive tasks. Partitioning (C) can help with data distribution, but the bottleneck remains the calculation itself. Native Python libraries (D) might not be as performant as optimized JVM-based UDFs. Disabling query optimization (E) is generally not recommended and can negatively impact performance.
NEW QUESTION # 130
You are working with a Snowpark DataFrame containing product review data'. The DataFrame has a 'review_text' column containing unstructured text reviews. Your task is to perform sentiment analysis on these reviews using Snowpark for Python. However, you are restricted to using only Snowpark built-in functions and UDFs; you cannot use external libraries like NLTK or TextBlob directly within your Snowpark code. Given this contraint, what is a valid approach to enrich your dataframe?
Answer: B,C,D,E
Explanation:
Options A, B, D and E are valid approaches given the constraints, since the task says enrich your dataframe, so we need some final column containing a score. Option A: The microservice approach, using 'call_udf and external function is a robust and scalable solution. It enables to leverage complex sentiment analysis models without directly integrating them into Snowflake. Option B: The Java UDF allows leveraging existing Java-based NLP libraries, extending the capabilities of Snowpark for sentiment analysis while adhering to the constraint of not using external Python libraries directly. Option D: Snowflake's External Functions are designed for calling external services. Passing 'review_text as an argument to pre-trained sentiment analysis model, and receive a result. Option E: This solution utilizes regular expression and UDFs. To search for sentiment indicative keywords and phrases and assigning the score using 'when' statements. Option C: This approach is the least efficient because it requires maintaining an internal vocabulary, which can be less accurate and harder to update compared to using pre-trained models or external services and it also does not generate a final new column to enrich the dataframe.
NEW QUESTION # 131
You have a Snowpark DataFrame named 'products_df' with columns 'product_id' (INT), 'product_name' (VARCHAR), and 'price' (FLOAT). You want to create a new DataFrame called 'discounted_products df that includes all columns from 'products_df' plus a new column named 'discounted_price', which is calculated as the original price minus a discount percentage specified by the variable 'discount_rate' (e.g., 0.1 for 10%). The 'discount_rate' is stored in the database table named 'discount_table'. You want to load the rate to variable. Choose the correct ways to achieve this. (Select all that apply)





Answer: A,B,C
Explanation:
Options A, B and D provide valid ways to fetch 'discount_rate' as a single numerical value. And fetch the data and gets the first value from the first row. Similarly, gets the data and return the first row. However, Option C does not have LIMIT 1 and will not work. Option E fetches one row as one array, thus requires rate[0] to compute discounted_price.
NEW QUESTION # 132
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
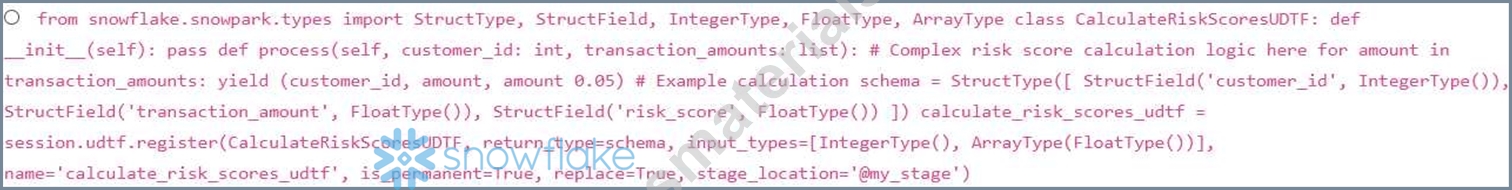
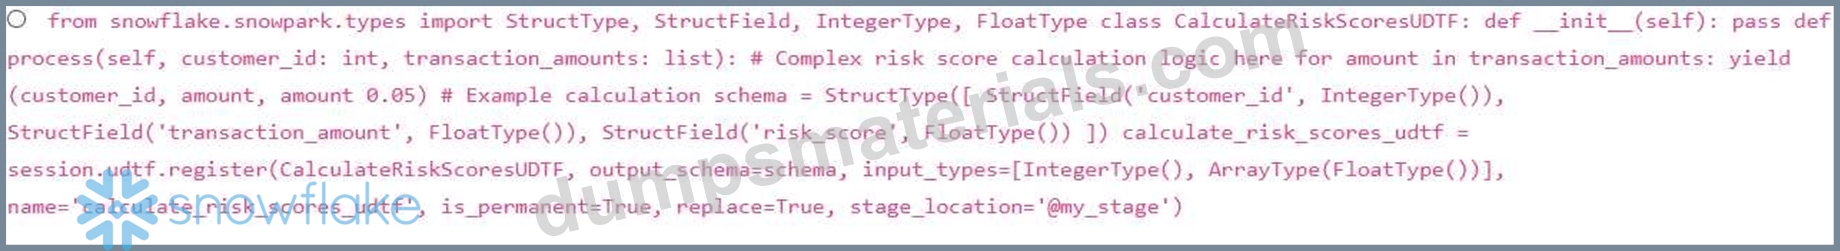
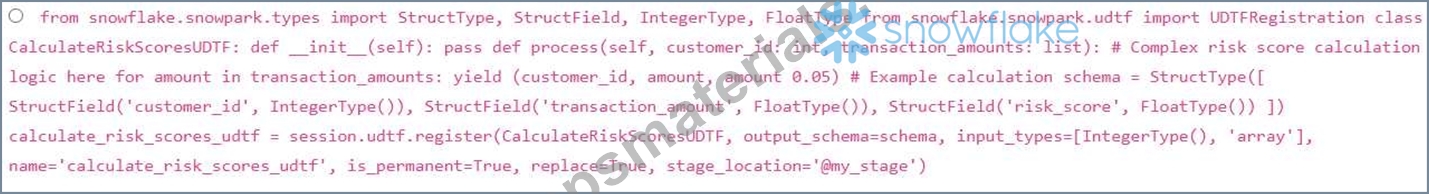
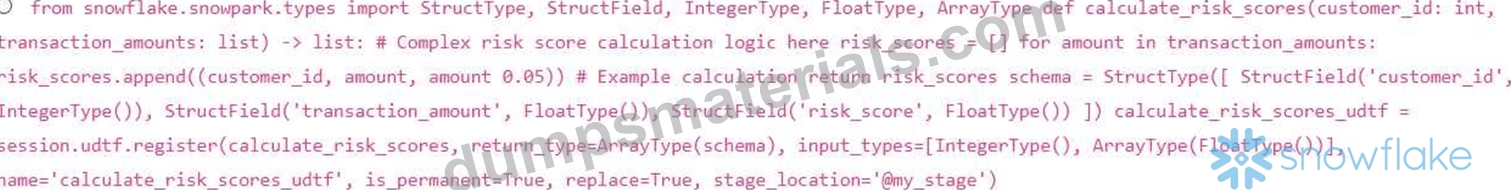
Answer: D
Explanation:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
NEW QUESTION # 133
Consider a JSON structure representing product information, where prices are stored as strings due to inconsistent data quality. You need to calculate the average price of products. However, some price strings contain non-numeric characters (e.g., '$', commas). Which of the following approaches, using Snowpark DataFrame operations, is the MOST robust and efficient way to clean and cast the price data to a numeric type for accurate average calculation?





Answer: C
Explanation:
Option D is the most robust. It uses 'regexp_replace' to remove '$' and commas from the price string and then uses which handles cases where the cleaned string still cannot be converted to a number gracefully (returning NULL instead of throwing an error). Then computes the average on this column. Option A would fail in some cases as it cast the string to float directly, so some string format won't work, it's better using Option B would throw error while casting when the number is not in float format. Option C would throw error while casting as to_number need to be called with a format to work. Option E would raise conversion error because return variant and not numeric type to be cast to float.
NEW QUESTION # 134
......
There are a lot of experts and professors in or company in the field. In order to meet the demands of all people, these excellent experts and professors from our company have been working day and night. They tried their best to design the best SPS-C01 certification training dumps from our company for all people. By our study materials, all people can prepare for their SPS-C01 exam in the more efficient method. We can guarantee that our study materials will be suitable for all people and meet the demands of all people, including students, workers and housewives and so on. If you decide to buy and use the SPS-C01 Training Materials from our company with dedication on and enthusiasm step and step, it will be very easy for you to pass the exam without doubt. We sincerely hope that you can achieve your dream in the near future by the SPS-C01 latest questions of our company.
Test SPS-C01 Topics Pdf: https://www.dumpsmaterials.com/SPS-C01-real-torrent.html
BTW, DOWNLOAD part of DumpsMaterials SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1F7_oCpaTU18s-FbPtXYaEIM8UC2ZcCjR