BTW, DOWNLOAD part of TorrentValid Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1SmZho5EMiQYDzifUAFVgQCMcT24kAiB0
The best practice indicates that people who have passed the Professional-Machine-Learning-Engineer exam would not pass the exam without the help of the Professional-Machine-Learning-Engineer reference guide. So the study materials will be very important for all people. If you also want to pass the Professional-Machine-Learning-Engineer exam and get the related certification in a short, our Professional-Machine-Learning-Engineer Study Materials are the best choice for you. After studing with our Professional-Machine-Learning-Engineer exam questions, you will be able to pass the Professional-Machine-Learning-Engineer exam with confidence. We sincerely hope that our Professional-Machine-Learning-Engineer study materials will help you achieve your dream.
| Section | Objectives |
|---|---|
| Topic 1: Scaling prototypes into ML models | - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Hyperparameter tuning - Training at scale (Distributed training, TPUs) |
| Topic 2: Architecting low-code ML solutions | - Implementing BigQuery ML for basic models - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - AutoML capabilities and implementation |
| Topic 3: Serving and scaling models | - Online prediction (Vertex AI Prediction) - Model optimization (Quantization, Distillation) - Batch prediction - Hardware accelerators (GPU/TPU) in serving |
| Topic 4: Monitoring ML solutions | - Performance monitoring and drift detection - Logging and alerting (Cloud Monitoring) - Model retraining strategies |
| Topic 5: Collaborating within and across teams to manage data and models | - Data management and governance - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Version control and reproducibility (e.g., DVC, MLOps) |
| Topic 6: Automating and orchestrating ML pipelines | - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems |
>> Downloadable Professional-Machine-Learning-Engineer PDF <<
You only need 20-30 hours to learn our Professional-Machine-Learning-Engineer test torrents and prepare for the exam. Anybody, whether he or she is an in-service staff or a student, must spend much time on their jobs, family lives and the learning. After buying our Professional-Machine-Learning-Engineer exam questions you only need to spare several hours to learn our Professional-Machine-Learning-Engineer test torrent s and commit yourselves mainly to the jobs, the family lives and the learning. Our answers and questions of Professional-Machine-Learning-Engineer Exam Questions are chosen elaborately and seize the focus of the exam so you can save much time to learn and prepare the exam. Because the passing rate is high you can reassure yourselves to buy our Professional-Machine-Learning-Engineer guide torrent.
NEW QUESTION # 61
You recently trained a XGBoost model that you plan to deploy to production for online inference Before sending a predict request to your model's binary you need to perform a simple data preprocessing step This step exposes a REST API that accepts requests in your internal VPC Service Controls and returns predictions You want to configure this preprocessing step while minimizing cost and effort What should you do?
Answer: A
NEW QUESTION # 62
You work for a small company that has deployed an ML model with autoscaling on Vertex AI to serve online predictions in a production environment. The current model receives about 20 prediction requests per hour with an average response time of one second. You have retrained the same model on a new batch of data, and now you are canary testing it, sending ~10% of production traffic to the new model. During this canary test, you notice that prediction requests for your new model are taking between 30 and 180 seconds to complete. What should you do?
Answer: B
NEW QUESTION # 63
You trained a text classification model. You have the following SignatureDefs: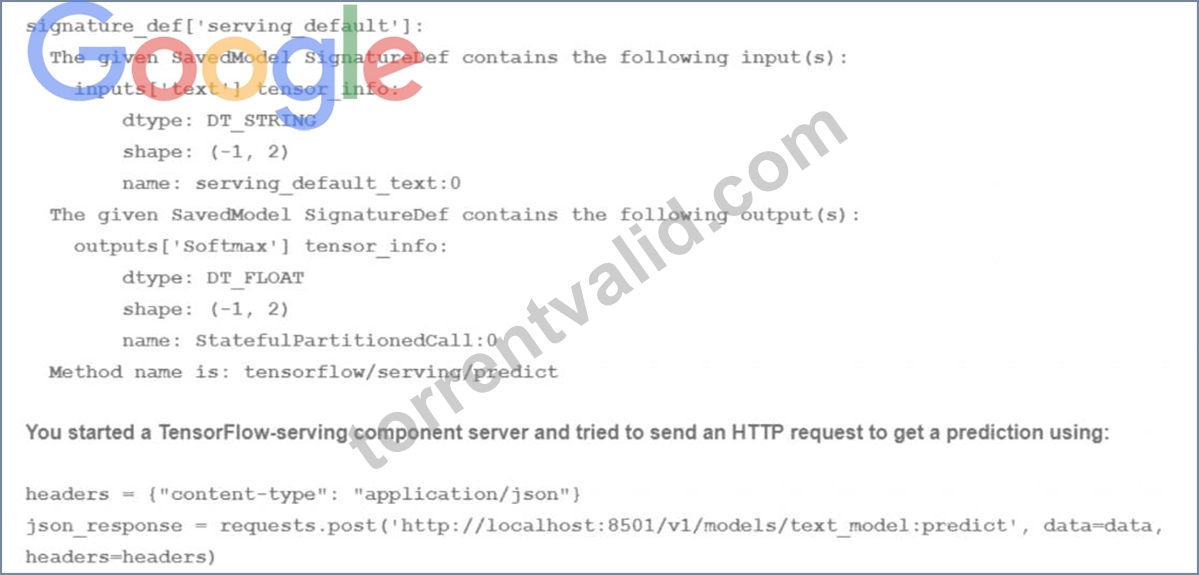
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model. A signature is a way to specify the expected format, type, and shape of the data that the model can accept
* and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
NEW QUESTION # 64
Your work for a textile manufacturing company. Your company has hundreds of machines and each machine has many sensors. Your team used the sensory data to build hundreds of ML models that detect machine anomalies Models are retrained daily and you need to deploy these models in a cost-effective way. The models must operate 24/7 without downtime and make sub millisecond predictions. What should you do?
Answer: B
Explanation:
A Dataflow streaming pipeline is a cost-effective way to process large volumes of real-time data from sensors. The RunInference API is a Dataflow transform that allows you to run online predictions on your streaming data using your ML models. By using the RunInference API, you can avoid the latency and cost of using a separate prediction service. The automatic model refresh feature enables you to update your models in the pipeline without redeploying the pipeline. This way, you can ensure that your models are always up-to- date and accurate. By deploying a Dataflow streaming pipeline with the RunInference API and using automatic model refresh, you can achieve sub-millisecond predictions, 24/7 availability, and low operational overhead for your ML models. References:
* Dataflow documentation
* RunInference API documentation
* Automatic model refresh documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 65
You developed a Vertex Al pipeline that trains a classification model on data stored in a large BigQuery table.
The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names: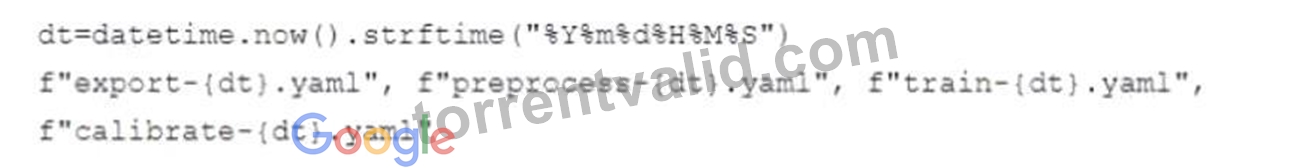
You launch your Vertex Al pipeline as the following:
You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?




Answer: A
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "automate and orchestrate ML pipelines using Cloud Composer". Vertex AI Pipelines2 is a service that allows you to orchestrate your ML workflows using Kubeflow Pipelines SDK v2 or TensorFlow Extended. Vertex AI Pipelines supports execution caching, which means that if you run a pipeline and it reaches a component that has already been run with the same inputs and parameters, the component does not run again. Instead, the component uses the output from the previous run. This can save you time and resources when you are iterating on your pipeline.
Therefore, option A is the best way to reduce model development costs, as it enables execution caching for the data export and preprocessing steps, which are likely to be the same for each model iteration. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* Vertex AI Pipelines
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 66
......
Candidates who crack the Professional-Machine-Learning-Engineer examination of the Google Professional-Machine-Learning-Engineer certification validate their worth in the sector of information technology. The Google Professional-Machine-Learning-Engineer credential is evidence of their talent. Reputed firms hire these talented people for high-paying jobs. To get the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) certification, it is essential to clear the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) test. For this task, you need to update Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) preparation material to get success.
Professional-Machine-Learning-Engineer Latest Torrent: https://www.torrentvalid.com/Professional-Machine-Learning-Engineer-valid-braindumps-torrent.html
BTW, DOWNLOAD part of TorrentValid Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1SmZho5EMiQYDzifUAFVgQCMcT24kAiB0