Our DP-800 study materials are excellent examination review products composed by senior industry experts that focuses on researching the mock examination products which simulate the real DP-800 test environment. Experts fully considered the differences in learning methods and examination models between different majors and eventually formed a complete review system. It will help you to Pass DP-800 Exam successfully after a series of exercises, correction of errors, and self-improvement.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest DP-800 Exam Preparation <<
As is known to all, DP-800 practice guide simulation plays an important part in the success of exams. By simulation, you can get the hang of the situation of the real exam with the help of our free demo. Simulation of our DP-800 training materials make it possible to have a clear understanding of what your strong points and weak points are and at the same time, you can learn comprehensively about the DP-800 Exam. By combining the two aspects, you are more likely to achieve high grades.
NEW QUESTION # 74
Hotspot Question
You have an Azure SQL managed instance that supports a gaming leaderboard API and contains a table named dbo.Leaderboard.
You plan to reduce write latency during peak events of dbo.Leaderboard.
You need to ensure that dbo.Leaderboard supports point lookups. The leaderboard information does NOT need to persist after a restart.
Which type of table and index should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.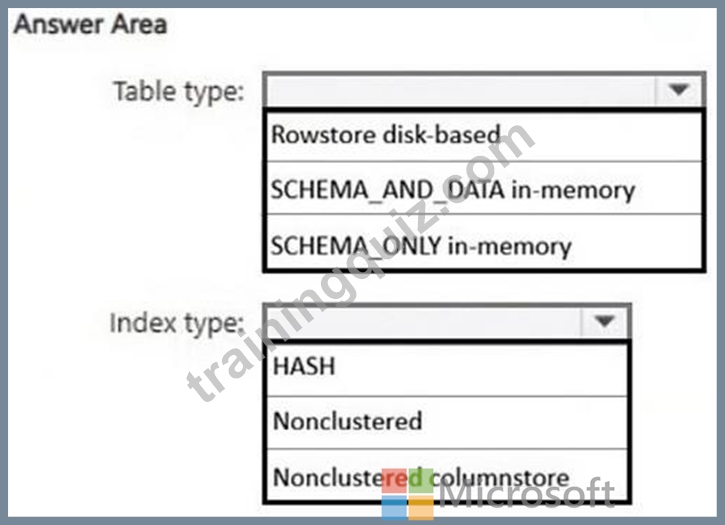
Answer:
Explanation: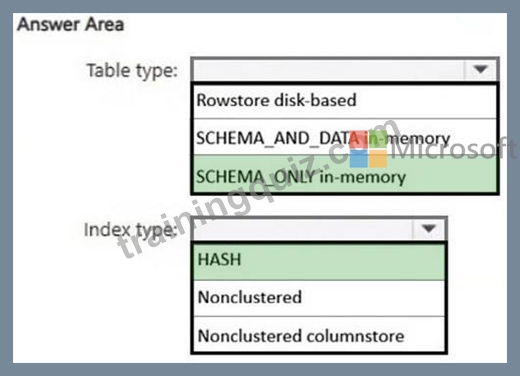
NEW QUESTION # 75
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.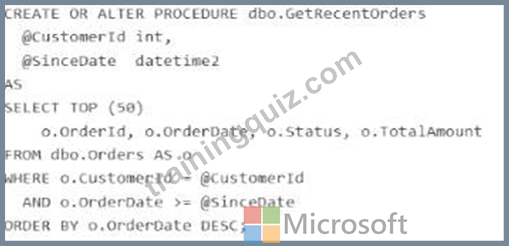
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.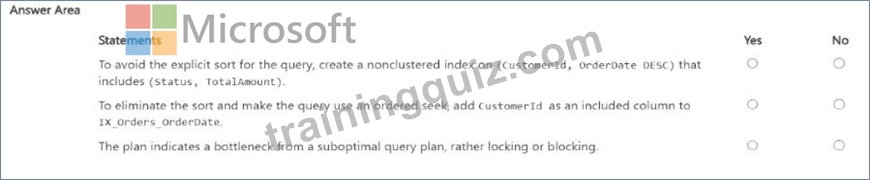
Answer:
Explanation: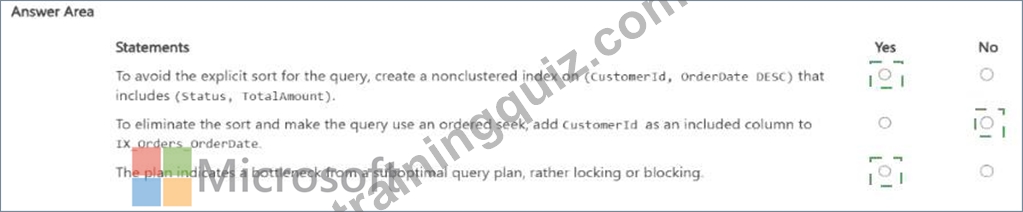
Explanation: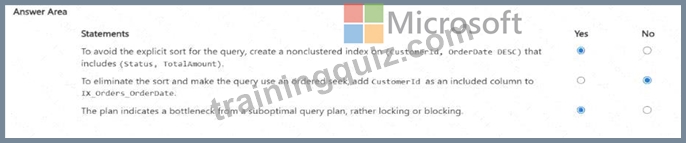
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
NEW QUESTION # 76
You have an Azure SQL database that contains the following SQL graph tables:
- A NODE table named dbo.Person
- An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
- PersonID (int)
- DisplayName (nvarchar(100))
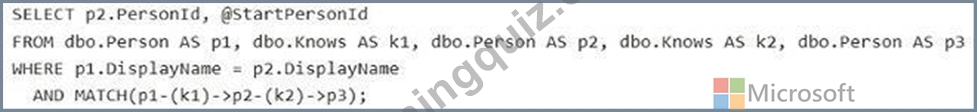
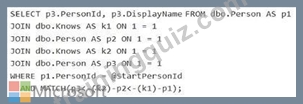
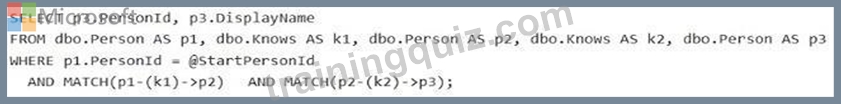
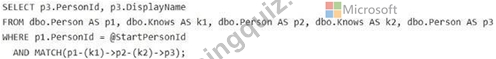
You need to use a MATCH operator and exactly two directed Knows relationships to return the PersonID and DisplayName of people that are reachable from the person identified by an input parameter named @StartPersonId.
Which Transact-SQL query should you use?
Answer: D
Explanation:
To achieve this using SQL Graph in Azure SQL, you use the MATCH clause to define the path.
Since you need exactly two directed relationships (A → B → C), you must chain the edge table twice in the same direction.
Transact-SQL Statement
SELECT
Person3.ID,
Person3.NameColumn -- Replace with your actual nvarchar(100) column name FROM PersonNodeTable AS Person1, KnowsEdgeTable AS Knows1, PersonNodeTable AS Person2, KnowsEdgeTable AS Knows2, PersonNodeTable AS Person3 WHERE MATCH(Person1-(Knows1)->Person2-(Knows2)->Person3) AND Person1.ID = @InputID; Use code with caution.
Key Components
MATCH Clause: Defines the traversal pattern. The syntax (Node)-(Edge)->(Node) ensures the relationship is directed.
Chaining: To get "exactly two" steps, you define three node aliases and two edge aliases.
Aliases: Each instance of the table must have a unique alias (e.g., Person1, Person2, Person3) so the engine can distinguish between the different points in the path.
Filtering: The WHERE clause uses your input parameter (@InputID) to set the starting point of the graph traversal Incorrect:
[Not A]
Need three persons, not two.
[Not B]
Do not use JOIN.
[Not C]
Incorrect MATCH statement.
Reference:
https://learn.microsoft.com/en-us/sql/relational-databases/graphs/sql-graph-sample
NEW QUESTION # 77
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1 DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1 .
A company policy prohibits sharing customer Personally Identifiable Information (Pll), secrets, and query result sets with any Al service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to sales .Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
Answer: A
Explanation:
The correct answer is D because the policy explicitly prohibits sharing customer PII, secrets, and query result sets with any AI service. The safe way to use GitHub Copilot Chat here is to provide only schema- level information such as table names, column names, relationships, and the required procedure behavior, without sharing actual table contents or result sets. That lets Copilot help generate and review the Transact- SQL while avoiding disclosure of customer data. This is consistent with Microsoft and GitHub guidance that content provided in prompts is what the AI can use, so avoiding real data in the prompt is the appropriate control.
The other options violate the requirement:
* A pastes real rows containing email addresses, which is direct PII disclosure.
* B shares actual query result sets, which the policy forbids.
* C provides the connection string so Copilot can validate against the database, which is inappropriate because it exposes connection details and could enable access beyond schema-only assistance.
So the correct approach is to ask Copilot to generate the stored procedure using only the schema and requirements, not real customer data.
NEW QUESTION # 78
You need to design a generative Al solution that uses a Microsoft SOL Server 2025 database named DB1 as a data source. The solution must generate responses that meet the following requirements:
* Ait ' grounded In the latest transactional and reference data stored in D61
* Do NOT require retraining or fine-tuning the language model when the data changes
* Can include citations or references to the source data used in the response Which scenario is the best use case for implementing a Retrieval Augmented Generation (RAG) pattern?
More than one answer choice may achieve the goal. Select the BEST answer
Answer: A
Explanation:
The best use case for RAG is answering user questions based on company-specific knowledge . Microsoft defines RAG as a pattern that augments a language model with a retrieval system that provides grounding data at inference time, which is exactly what you need when responses must be based on the latest transactional and reference data , must avoid retraining/fine-tuning , and should be able to include citations or references to source data.
The other options do not fit as well:
* summarizing free-form user input does not inherently require retrieval from DB1,
* training a custom model contradicts the requirement to avoid retraining/fine-tuning,
* generating marketing slogans is a creative generation task, not a grounding-and-citation scenario. RAG is specifically strong when answers must come from your organization's own changing knowledge.
NEW QUESTION # 79
......
Looking at the experiences of our loyal customers, you will find with the help of our excellent DP-800 exam questions, to achieve the desired certification is no long a unreached dream. And i believe that you will definitely be more determined to pass the DP-800 Exam. At the same time, you will also believe that our DP-800 learning questions can really help you. We can claim that as long as you study with our DP-800 praparation engine for 20 to 30 hours, you will pass the exam easily.
DP-800 Valid Test Pdf: https://www.trainingquiz.com/DP-800-practice-quiz.html